Once you have practiced and experienced the quality of our Databricks-Certified-Data-Engineer-Professional exam preparation, you will remember the serviceability and usefulness of them. It explains why our Databricks-Certified-Data-Engineer-Professional practice materials helped over 98 percent of exam candidates get the certificate you dream of successfully. Believe me you can get it too and you will be benefited by our Databricks-Certified-Data-Engineer-Professional Study Guide as well. Just have a try on our Databricks-Certified-Data-Engineer-Professional learning prep, and you will fall in love with it.
| Section | Objectives |
|---|---|
| Data Ingestion and Processing | - Batch and streaming ingestion with Auto Loader - ETL pipeline design patterns - Structured Streaming fundamentals |
| Production Pipelines and Orchestration | - Databricks Workflows - Error handling and recovery strategies - Job scheduling and monitoring |
| Delta Lake and Data Management | - Time travel and versioning - Delta Lake transactions and ACID properties - Schema evolution and enforcement |
| Data Modeling and Transformation | - Performance optimization techniques - Dimensional modeling concepts - Spark SQL transformations |
| Databricks Lakehouse Platform Architecture | - Data governance concepts (Unity Catalog basics) - Workspace and cluster architecture - Medallion architecture (Bronze, Silver, Gold) |
>> Test Databricks-Certified-Data-Engineer-Professional Discount Voucher <<
In this social-cultural environment, the Databricks-Certified-Data-Engineer-Professional certificates mean a lot especially for exam candidates like you. To some extent, these Databricks-Certified-Data-Engineer-Professional certificates may determine your future. With respect to your worries about the practice exam, we recommend our Databricks-Certified-Data-Engineer-Professional Preparation materials which have a strong bearing on the outcomes dramatically. For a better understanding of their features, please follow our website and try on them.
NEW QUESTION # 24
The business intelligence team has a dashboard configured to track various summary metrics for retail stories. This includes total sales for the previous day alongside totals and averages for a variety of time periods. The fields required to populate this dashboard have the following schema:
For Demand forecasting, the Lakehouse contains a validated table of all itemized sales updated incrementally in near real-time. This table named products_per_order, includes the following fields:
Because reporting on long-term sales trends is less volatile, analysts using the new dashboard only require data to be refreshed once daily. Because the dashboard will be queried interactively by many users throughout a normal business day, it should return results quickly and reduce total compute associated with each materialization.
Which solution meets the expectations of the end users while controlling and limiting possible costs?
Answer: C
NEW QUESTION # 25
An upstream system is emitting change data capture (CDC) logs that are being written to a cloud object storage directory. Each record in the log indicates the change type (insert, update, or delete) and the values for each field after the change. The source table has a primary key identified by the field pk_id.
For analytical purposes, only the most recent value for each record needs to be recorded in the target Delta Lake table in the Lakehouse. The Databricks job to ingest these records occurs once per hour, but each individual record may have changed multiple times over the course of an hour.
Which solution meets these requirements?
Answer: C
NEW QUESTION # 26
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer s suggestion is correct?
Answer: B
Explanation:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data.
NEW QUESTION # 27
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table: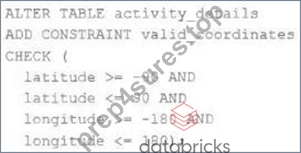
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
Answer: B
Explanation:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and
180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation.
NEW QUESTION # 28
Spill occurs as a result of executing various wide transformations. However, diagnosing spill requires one to proactively look for key indicators.
Where in the Spark UI are two of the primary indicators that a partition is spilling to disk?
Answer: B
Explanation:
In the Spark UI, the Stage's detail screen provides key metrics about each stage of a job, including the amount of data that has been spilled to disk. If you see a high number in the "Spill (Memory)" or "Spill (Disk)" columns, it's an indication that a partition is spilling to disk.
The Executor's log files can also provide valuable information about spill. If a task is spilling a lot of data, you'll see messages in the logs like "Spilling UnsafeExternalSorter to disk" or "Task memory spill". These messages indicate that the task ran out of memory and had to spill data to disk.
NEW QUESTION # 29
......
To improve our products’ quality we employ first-tier experts and professional staff and to ensure that all the clients can pass the test we devote a lot of efforts to compile the Databricks-Certified-Data-Engineer-Professional learning guide. Even if you unfortunately fail in the test we won’t let you suffer the loss of the money and energy and we will return your money back at the first moment. After you pass the Databricks-Certified-Data-Engineer-Professional test you will enjoy the benefits the certificate brings to you such as you will be promoted by your boss in a short time and your wage will surpass your colleagues. In short, buying the Databricks-Certified-Data-Engineer-Professional exam guide deserves your money and energy spent on them.
Databricks-Certified-Data-Engineer-Professional Reliable Dumps: https://www.prep4sures.top/Databricks-Certified-Data-Engineer-Professional-exam-dumps-torrent.html