For candidates who will buy Databricks-Certified-Data-Engineer-Professional learning materials online, they may care more about the quality of the exam dumps. We have a professional team to collect the latest information of the Databricks-Certified-Data-Engineer-Professional exam dumps, therefore the quality can be guaranteed. Moreover, we have online and offline chat service stuff, who have professional knowledge for Databricks-Certified-Data-Engineer-Professional Learning Materials. If you have any questions, you can consult us. We will give you reply as soon as possible. Free demo for Databricks-Certified-Data-Engineer-Professional exam dumps will also be offered, and you can have a try before purchasing.
| Section | Objectives |
|---|---|
| Topic 1: Production Pipelines and Orchestration | - Databricks Workflows - Job scheduling and monitoring - Error handling and recovery strategies |
| Topic 2: Databricks Lakehouse Platform Architecture | - Medallion architecture (Bronze, Silver, Gold) - Workspace and cluster architecture - Data governance concepts (Unity Catalog basics) |
| Topic 3: Data Modeling and Transformation | - Performance optimization techniques - Spark SQL transformations - Dimensional modeling concepts |
| Topic 4: Data Ingestion and Processing | - Batch and streaming ingestion with Auto Loader - Structured Streaming fundamentals - ETL pipeline design patterns |
| Topic 5: Delta Lake and Data Management | - Delta Lake transactions and ACID properties - Schema evolution and enforcement - Time travel and versioning |
>> Databricks-Certified-Data-Engineer-Professional Test Engine Version <<
With the Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional exam, you will have the chance to update your knowledge while obtaining dependable evidence of your proficiency. You can benefit from a number of additional benefits after completing the Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional Certification Exam. But keep in mind that the Databricks-Certified-Data-Engineer-Professional certification test is a worthwhile and challenging certificate.
NEW QUESTION # 126
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from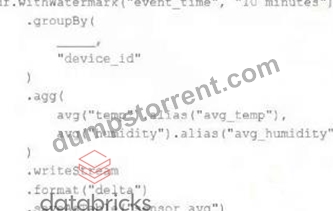
Choose the response that correctly fills in the blank within the code block to complete this task.
Answer: D
Explanation:
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five- minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as "time".
NEW QUESTION # 127
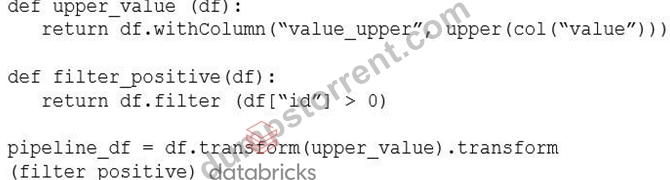
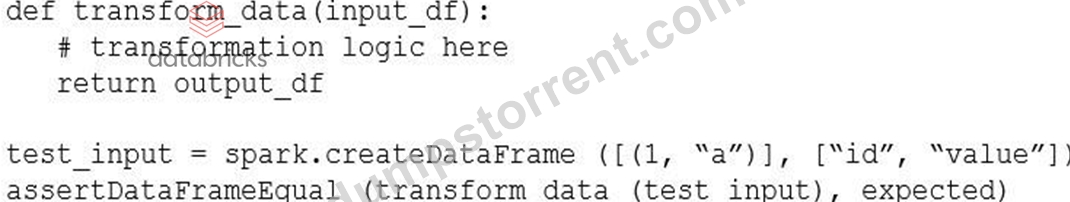
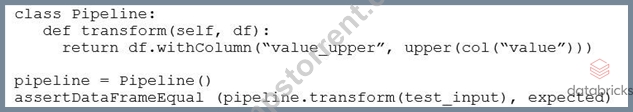
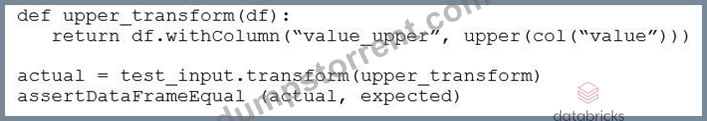
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
Answer: D
Explanation:
Using DataFrame.transform with a pure transformation function promotes modular, reusable, and easily testable ETL logic. Each transformation is encapsulated as a standalone function, can be independently unit tested, and composed cleanly in a pipeline without coupling to orchestration or class state.
NEW QUESTION # 128
A new data engineer notices that a critical field was omitted from an application that writes its Kafka source to Delta Lake. This happened even though the critical field was in the Kafka source.
That field was further missing from data written to dependent, long-term storage. The retention threshold on the Kafka service is seven days. The pipeline has been in production for three months.
Which describes how Delta Lake can help to avoid data loss of this nature in the future?
Answer: E
Explanation:
This is the correct answer because it describes how Delta Lake can help to avoid data loss of this nature in the future. By ingesting all raw data and metadata from Kafka to a bronze Delta table, Delta Lake creates a permanent, replayable history of the data state that can be used for recovery or reprocessing in case of errors or omissions in downstream applications or pipelines.
Delta Lake also supports schema evolution, which allows adding new columns to existing tables without affecting existing queries or pipelines. Therefore, if a critical field was omitted from an application that writes its Kafka source to Delta Lake, it can be easily added later and the data can be reprocessed from the bronze table without losing any information.
NEW QUESTION # 129
Which statement describes the correct use of pyspark.sql.functions.broadcast?
Answer: D
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
NEW QUESTION # 130
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer s suggestion is correct?
Answer: E
Explanation:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data.
NEW QUESTION # 131
......
Do you want to get more respects from other people? Do you long to become a powerful people? Our Databricks-Certified-Data-Engineer-Professional exam torrent is compiled by professional experts that keep pace with contemporary talent development and makes every learner fit in the needs of the society. If you choose our Databricks-Certified-Data-Engineer-Professional Study Materials, you will pass Databricks-Certified-Data-Engineer-Professional exam successful in a short time. There is no doubt that our Databricks-Certified-Data-Engineer-Professional exam question can be your first choice for your relevant knowledge accumulation and ability enhancement.
New APP Databricks-Certified-Data-Engineer-Professional Simulations: https://www.dumpstorrent.com/Databricks-Certified-Data-Engineer-Professional-exam-dumps-torrent.html