Updated Certified-Data-Engineer-Professional Test Cram, Certified-Data-Engineer-Professional Valid Exam Experience

Candidates may have different ways to practice the Certified-Data-Engineer-Professional study materials, some may like to practice in paper, and some may like to practice it in the computer. We have three versions for you to meet your different needs. If you like to practice in the paper, Certified-Data-Engineer-Professional PDF version will be your choice, which can be printed into the hard one. If you like to practice on your computer, Certified-Data-Engineer-Professional Soft test engine will be your best, choice, besides it also stimulates the exam environment, you can experience the exam environment through this.
| Section | Objectives |
|---|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 5. Apply Change Data Feed to address streaming table limitations and improve latency
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create pipeline components using control flow operators such as if/else and foreach
- 2. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 3. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 4. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 5. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 6. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
|
>> Updated Certified-Data-Engineer-Professional Test Cram <<
Certified-Data-Engineer-Professional Valid Exam Experience | Certified-Data-Engineer-Professional Dumps Guide
According to personal propensity and various understanding level of exam candidates, we have three versions of Certified-Data-Engineer-Professional study guide for your reference. They are the versions of the PDF, Software and APP online. If you visit our website on our Certified-Data-Engineer-Professional Exam Braindumps, then you may find that there are the respective features and detailed disparities of our Certified-Data-Engineer-Professional simulating questions. And you can free donwload the demos to have a look.
Databricks Certified Data Engineer Professional Sample Questions (Q160-Q165):
NEW QUESTION # 160
A company stores account transactions in a Delta Lake table. The company needs to apply frequent account-level correlations (e.g., UPDATE statements) but wants to avoid rewriting entire Parquet files for each change to reduce file churn and improve write performance. Which Delta Lake feature should they enable?
- A. Enable automatic file compaction on writes
- B. Enable change data feed on the Delta table
- C. Partition the Delta table by account_id
- D. Enable deletion vectors on the Delta table
Answer: D
Explanation:
Deletion vectors allow Delta Lake to track row-level deletes and updates without rewriting entire Parquet files. By recording changes separately from the base files, this feature significantly reduces file churn and improves write performance for workloads with frequent row-level modifications such as account-level updates.
NEW QUESTION # 161
A data architect is implementing Delta Sharing as part of their data governance strategy to enable secure data collaboration with external partners and internal business units. The architect must establish a permission framework that allows designated data stewards to create shares for their respective domains while maintaining security boundaries and audit compliance. Which specific permissions and roles must be assigned to enable users to create, configure, and manage Delta Shares while maintaining proper security governance and access controls?
- A. Users need the MANAGE SHARES permission on the workspace
- B. Only workspace admins can create and manage shares
- C. Users need to be metastore admins or have CREATE SHARE privilege for the metastore
- D. Any user with USE_CATALOG privilege can create shares
Answer: C
Explanation:
Creating and managing Delta Shares requires elevated governance privileges at the metastore level. Assigning users as metastore admins or granting them the CREATE SHARE privilege allows designated data stewards to create and configure shares within defined security boundaries, while preserving centralized auditability and access control.
NEW QUESTION # 162
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats. After converting a subset of data to Delta Lake, they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join, whereas queries on legacy formats used Sort Merge Joins. The queries reading Delta Lake data also scanned less data. Which reason could be attributed to the difference in query performance?
- A. The queries against the ORC tables leveraged the dynamic data skipping optimization but not the dynamic file pruning optimization.
- B. Delta Lake enables data skipping and file pruning using a vectorized Parquet reader.
- C. The queries against the Delta Lake tables were able to leverage the dynamic file pruning optimization.
- D. Shuffle Hash Joins are always more efficient than Sort Merge Joins.
Answer: B
Explanation:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage, data skipping, and file pruning. According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters, a process called data skipping and file pruning. Additionally, Delta uses a vectorized Parquet reader, which reduces I/O and CPU overhead. Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
NEW QUESTION # 163
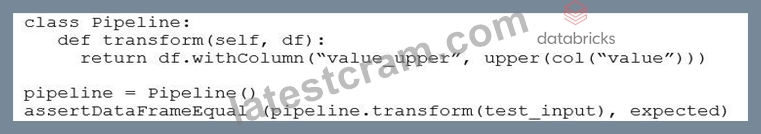
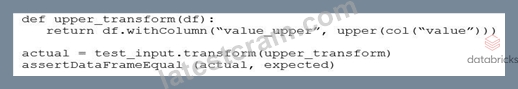
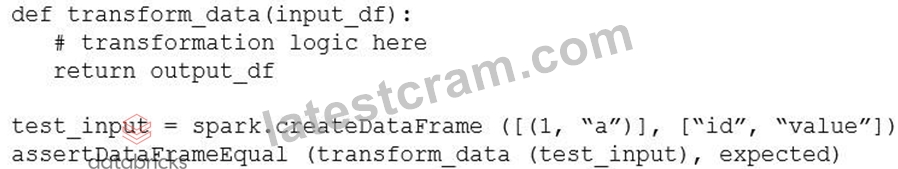
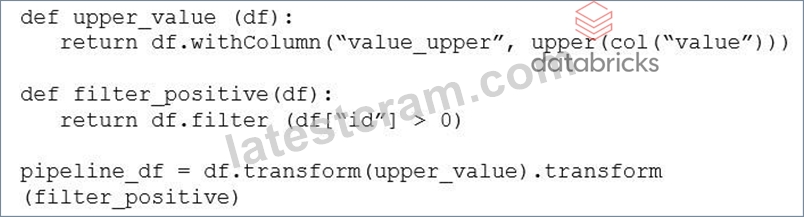
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
Answer: B
Explanation:
Using DataFrame.transform with a pure transformation function promotes modular, reusable, and easily testable ETL logic. Each transformation is encapsulated as a standalone function, can be independently unit tested, and composed cleanly in a pipeline without coupling to orchestration or class state.
NEW QUESTION # 164
A data engineering team has a time-consuming data ingestion job with three data sources. Each notebook takes about one hour to load new data. One day, the job fails because a notebook update introduced a new required configuration parameter. The team must quickly fix the issue and load the latest data from the failing source. Which action should the team take?
- A. Update the task by adding the missing task parameter, and manually run the job.
- B. Repair the run with the new parameter.
- C. Share the analysis with the failing notebook owner so that they can fix it quickly.
- D. Repair the run with the new parameter, and update the task by adding the missing task parameter.
Answer: D
Explanation:
The repair run capability in Databricks Jobs allows re-execution of failed tasks without re-running successful ones. When a parameterized job fails due to missing or incorrect task configuration, engineers can perform a repair run to fix inputs or parameters and resume from the failed state.
This approach saves time, reduces cost, and ensures workflow continuity by avoiding unnecessary recomputation. Additionally, updating the task definition with the missing parameter prevents future runs from failing.
Running the job manually (B) loses run context; (C) alone does not prevent recurrence; (D) delays resolution. Thus, A follows the correct operational and recovery practice.
NEW QUESTION # 165
......
Certified-Data-Engineer-Professional study guide can bring you more than you wanted. After you have used our products, you will certainly have your own experience. Now let's take a look at why a worthy product of your choice is our Certified-Data-Engineer-Professional actual exam. Firstly, with a high pass rate of 98% to 100%, you will get the pass guarantee form our Certified-Data-Engineer-Professional Practice Engine. Secondly, the price of our Certified-Data-Engineer-Professional learning guide is quite favourable than the other websites'.
Certified-Data-Engineer-Professional Valid Exam Experience: https://www.latestcram.com/Certified-Data-Engineer-Professional-exam-cram-questions.html
- Pass Guaranteed Quiz 2026 Databricks Certified-Data-Engineer-Professional Updated Updated Test Cram ⏭ Search for ▛ Certified-Data-Engineer-Professional ▟ and download exam materials for free through ▶ www.troytecdumps.com ◀ 🎢Certified-Data-Engineer-Professional Actual Questions
- Certified-Data-Engineer-Professional PDF Questions - Perfect Prospect To Go With Certified-Data-Engineer-Professional Practice Exam 📧 Open website { www.pdfvce.com } and search for ▛ Certified-Data-Engineer-Professional ▟ for free download 🏨Certified-Data-Engineer-Professional Training Solutions
- Certified-Data-Engineer-Professional PDF Questions - Perfect Prospect To Go With Certified-Data-Engineer-Professional Practice Exam 🦟 Go to website ⏩ www.examdiscuss.com ⏪ open and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download for free 👯Certified-Data-Engineer-Professional Original Questions
- Pass-Sure Updated Certified-Data-Engineer-Professional Test Cram – Find Shortcut to Pass Certified-Data-Engineer-Professional Exam ✌ Easily obtain ▛ Certified-Data-Engineer-Professional ▟ for free download through ☀ www.pdfvce.com ️☀️ 🍅Valid Certified-Data-Engineer-Professional Exam Notes
- Free Certified-Data-Engineer-Professional Braindumps 📊 Valid Certified-Data-Engineer-Professional Exam Pdf 🌀 New Certified-Data-Engineer-Professional Dumps Book 😂 { www.pass4test.com } is best website to obtain ⮆ Certified-Data-Engineer-Professional ⮄ for free download 🥎Pass Leader Certified-Data-Engineer-Professional Dumps
- Valid Certified-Data-Engineer-Professional Exam Pdf 🖐 Certified-Data-Engineer-Professional Original Questions 😈 Valid Certified-Data-Engineer-Professional Exam Format 🕞 Copy URL ➽ www.pdfvce.com 🢪 open and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 💂Certified-Data-Engineer-Professional Dumps Discount
- Real Certified-Data-Engineer-Professional Dumps 🚇 Valid Certified-Data-Engineer-Professional Exam Notes 🧩 Real Certified-Data-Engineer-Professional Dumps 📹 Search for ✔ Certified-Data-Engineer-Professional ️✔️ and easily obtain a free download on ▶ www.examcollectionpass.com ◀ 🧰Valid Certified-Data-Engineer-Professional Exam Pdf
- Best Preparation Material For The Databricks Certified-Data-Engineer-Professional Dumps PDF from Pdfvce 🔎 Open ▛ www.pdfvce.com ▟ and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download exam materials for free 🌒Certified-Data-Engineer-Professional Quiz
- Pass Guaranteed Quiz 2026 Databricks Certified-Data-Engineer-Professional Updated Updated Test Cram 🤨 Search for ✔ Certified-Data-Engineer-Professional ️✔️ on ⮆ www.troytecdumps.com ⮄ immediately to obtain a free download 🌛Certified-Data-Engineer-Professional Dumps Discount
- Valid Certified-Data-Engineer-Professional Exam Pdf ✋ Exam Certified-Data-Engineer-Professional Duration 📰 Clear Certified-Data-Engineer-Professional Exam 🗼 Open ➤ www.pdfvce.com ⮘ enter ⏩ Certified-Data-Engineer-Professional ⏪ and obtain a free download 💭Clear Certified-Data-Engineer-Professional Exam
- Certified-Data-Engineer-Professional PDF Questions - Perfect Prospect To Go With Certified-Data-Engineer-Professional Practice Exam 🥑 Search for 《 Certified-Data-Engineer-Professional 》 and download it for free immediately on ⮆ www.testkingpass.com ⮄ 🎡Valid Certified-Data-Engineer-Professional Exam Format
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, scalar.usc.edu, qiita.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes