CertShikenにあるソフトウェアバージョンは、DP-750実際の試験の3つのバージョンの1つであり、当社の専門家によって設計されています。 ソフトウェアバージョンの機能は非常に特殊です。 たとえば、ソフトウェアバージョンは実際の試験環境をシミュレートできます。 DP-750試験問題を購入すると、同様の実際の試験環境を楽しむことができます。 また、教材のソフトウェアバージョンは、コンピューターの数に限定されません。 DP-750準備試験をためらわずに購入してください。多くのメリットが得られ、DP-750試験に確実に合格します。
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
社会の発展と相対的な法律と規制の完成により、私たちのキャリア分野でのDP-750証明書は私たちの国にとって必要になります。 DP-750に合格して証明書を取得することが、あなたの立場を変えて目標を達成するための最も迅速で直接的な方法かもしれません。そして、私たちはあなたを助けるためにちょうどここにいます。このキャリアで最も本物のブランドと見なされているプロの専門家は、お客様に最新の有効なDP-750試験シミュレーションを提供するために絶え間ない努力を行っています。
質問 # 47
You have an Azure Databricks workspace named Workspace1. You create a compute cluster named Cluser1 that will be used to ingest data.
You need to install the required libraries on Cluster 1. The solution must use Unity Catalog for access control.
What should you do?
正解:C
解説:
The correct answer is B. The %pip install command (or pip3 in a terminal context) creates an isolated, per- session library environment in notebooks, which is the Unity Catalog-compatible approach. Unity Catalog workspaces require cluster access mode set to 'Shared' or 'Single User,' and %pip installs work seamlessly within those modes without requiring cluster restarts.
Option A (custom dependency script) introduces extra maintenance work for every environment change - exactly what the question says to avoid. Option C installs libraries at the cluster level and requires a manual restart, which disrupts other users sharing the cluster and bypasses the per-notebook isolation model that Unity Catalog recommends. Option D uploads libraries to the Workspace file system (legacy DBFS approach), which is being deprecated in favour of Unity Catalog Volumes for library storage.
Reference: https://learn.microsoft.com/en-us/azure/databricks/libraries/notebooks-python-libraries
質問 # 48
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.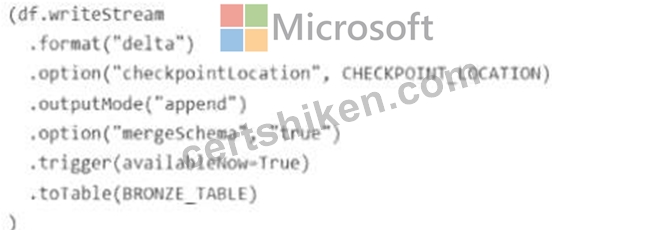
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.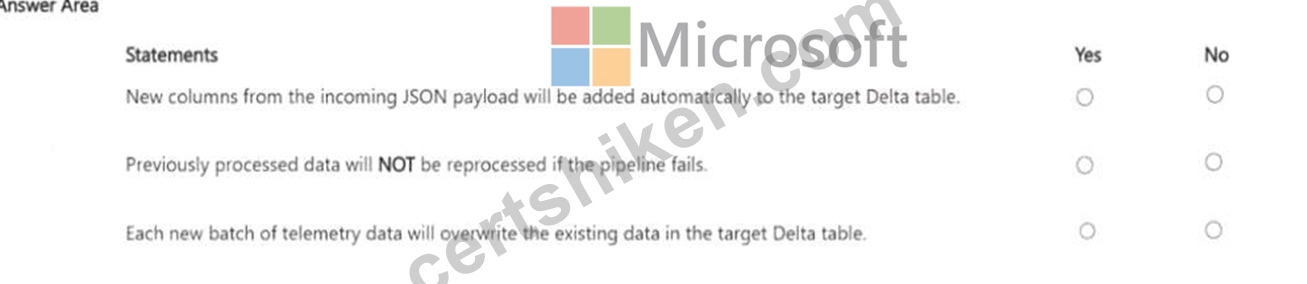
正解:
解説: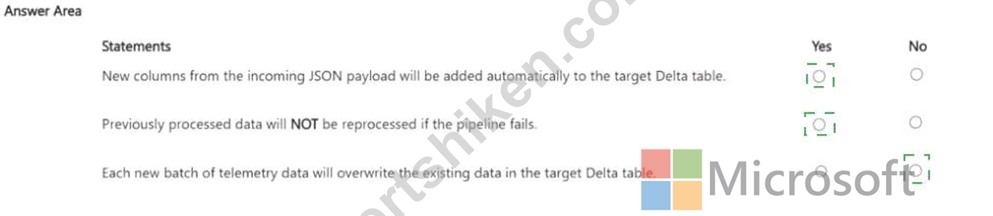
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: ' overwrite ' replaces existing data; ' append ' adds to it.
Always check whether the code uses the correct Delta format (.format( ' delta ' )), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
質問 # 49
You have an Azure Databricks workspace.
You have a streaming table named sales_order that is populated by using a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
You need to create a new streaming table named sales_order_by_city that summarizes sales by city and calculates the total sales per city.
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.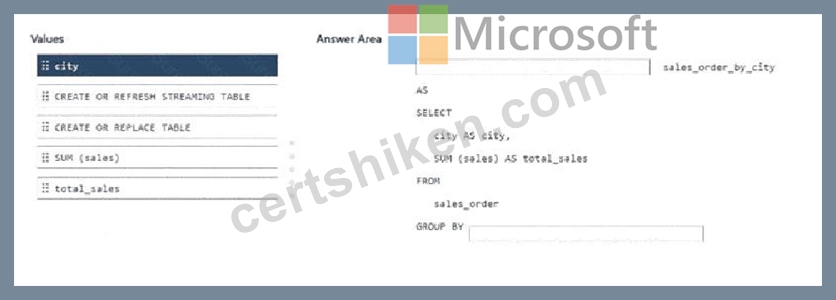
正解:
解説: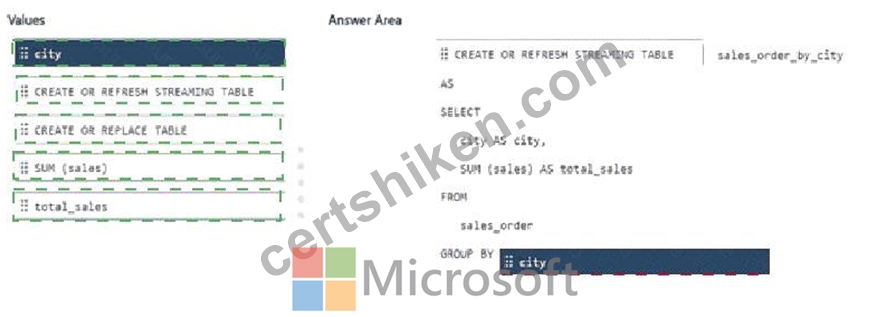
Explanation:
CREATE OR REFRESH STREAMING TABLE
city
CREATE OR REFRESH STREAMING TABLE defines a streaming table managed by Lakeflow Spark Declarative Pipelines. When the pipeline refreshes, Databricks incrementally processes newly available source data and maintains the resulting table. CREATE OR REPLACE TABLE would create a conventional table and does not provide the required streaming-table semantics. The query selects city AS city and calculates SUM(sales) AS total_sales. Because the aggregation must produce one result for each city, the GROUP BY expression must be city. Neither SUM(sales) nor total_sales belongs in the grouping clause: the former is the aggregate calculation, while the latter is only the alias assigned to its result. This produces continuously maintained city-level sales totals from the sales_order source table.
質問 # 50
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a complex job named Job1 that contains eight tasks. Job1 takes multiple hours to complete.
During the last job run, the final task fails due to a transient issue.
You need to retry the last task without rerunning tasks that have already completed.
What should you do?
正解:D
解説:
Repairing the current job run allows Lakeflow Jobs to rerun the failed task while preserving the successful status of tasks that already completed. This prevents several hours of successful processing from being repeated and reduces both recovery time and compute consumption. If downstream tasks had been skipped because of the failure, they can also be included in the repair operation as appropriate. Updating job parameters changes configuration but does not retry the failed task in the existing run. Restarting Job1 creates a new run and ordinarily executes the workflow again from its beginning. Disabling and reenabling the schedule only changes whether future scheduled runs can start; it does not repair the failed execution. Repair Run is specifically designed for recovering selected failed or skipped tasks in a multi-task workflow.
質問 # 51
You have an Apache Spark DataFrame named salesDF that contains the following columns:
* Product
* Region
* Sales
* Date
You need to create a pivot table that shows the total sales by product for each region.
How should you complete the PySpark code segment? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.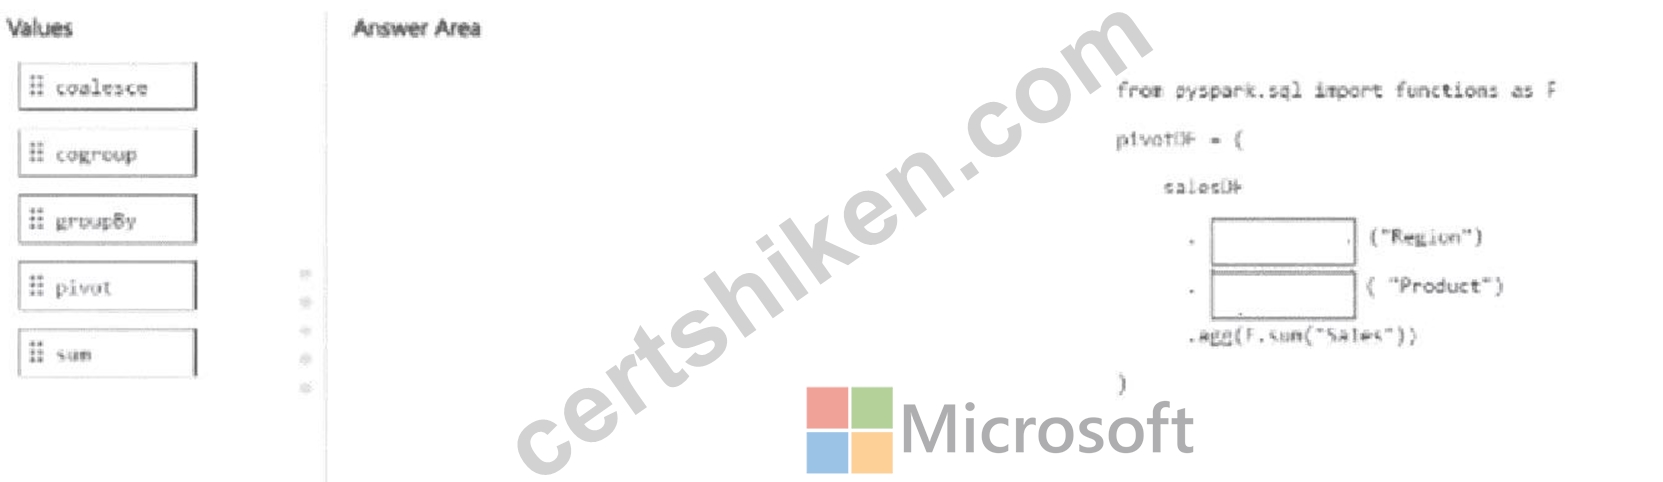
正解:
解説: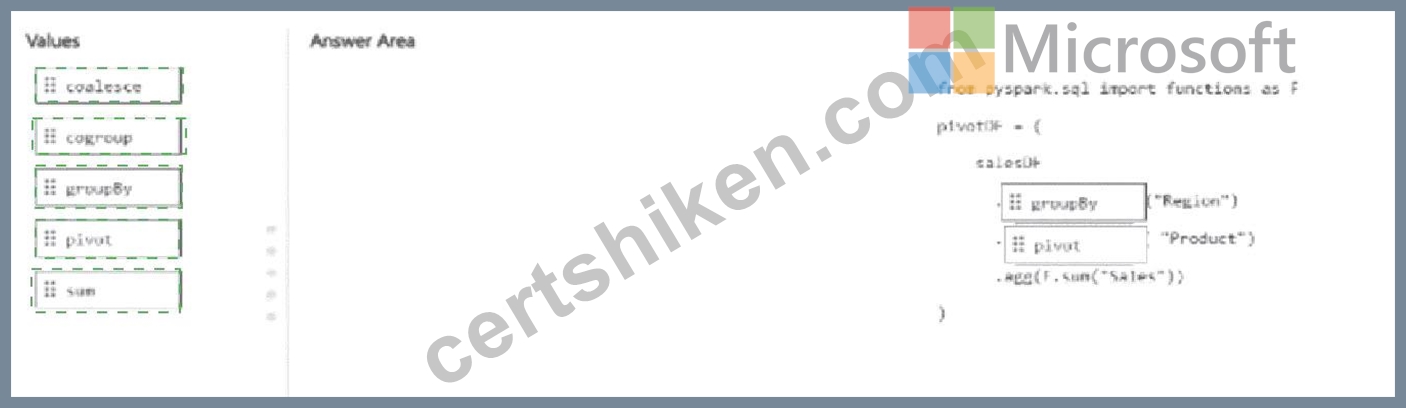
Explanation:
* groupBy
* pivot
The groupBy( " Region " ) operation establishes one aggregation group for each geographical region in the DataFrame. The subsequent pivot( " Product " ) operation converts every distinct Product value into a separate output column. Finally, agg(F.sum( " Sales " )) calculates the total sales for every product within each region. The resulting DataFrame contains one row per region and one column for each product, with the corresponding aggregated sales value. cogroup combines grouped datasets and is not used for creating a conventional pivot table. coalesce controls the number of DataFrame partitions or replaces null values, depending on its context. The sum function is already provided inside the aggregation expression and therefore is not required in either blank.
質問 # 52
......
誰もが良い仕事とまともな収入を望んでいます。しかし、彼らが優れた能力と優れた主要な知識を持っていない場合、彼らはまともな仕事を見つけるのは難しいです。テストDP-750認定に合格すると、夢を実現し、満足のいく仕事を見つけることができます。 DP-750学習教材は、DP-750試験に簡単に合格するのに役立つ優れたツールです。時間をかけて学習する必要はありません。 DP-750試験ガイドは高品質であり、当社の製品を使用する場合、DP-750試験に合格する可能性は99%〜100%と非常に高くなっています。
DP-750テスト内容: https://www.certshiken.com/DP-750-shiken.html