BONUS!!! Download part of PracticeVCE MLA-C01 dumps for free: https://drive.google.com/open?id=10mxKPGfx7W2SjLg8v9brEuSkhEkyjlzw
As our AWS Certified Machine Learning Engineer - Associate study questions can bring more professional quality service for the user. Our MLA-C01 study materials can give the user confidence and strongly rely on feeling, lets the user in the reference appendix not alone on the road, because we are to accompany the examinee on MLA-C01 Exam, candidates need to not only learning content of teaching, but also share his arduous difficult helper, so believe us, we are so professional company. Now, you can free download the demo of our MLA-C01 test guide to understand in more details.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
It is very convenient for all people to use the MLA-C01 study materials from our company. Our study materials will help a lot of people to solve many problems if they buy our products. The online version of MLA-C01 study materials from our company is not limited to any equipment, which means you can apply our study materials to all electronic equipment, including the telephone, computer and so on. So the online version of the MLA-C01 Study Materials from our company will be very useful for you to prepare for your exam. We believe that our study materials will be a good choice for you.
NEW QUESTION # 164
A company is building an enterprise AI platform. The company must catalog models for production, manage model versions, and associate metadata such as training metrics with models. The company needs to eliminate the burden of managing different versions of models.
Which solution will meet these requirements?
Answer: A
Explanation:
The correct answer is B. Use the Amazon SageMaker Model Registry to catalog the models. Create model groups for each model to manage the model versions and to maintain associated metadata.
The Amazon SageMaker Model Registry is a managed repository within SageMaker designed specifically for production-grade ML model lifecycle management. It allows organizations to catalog models, track multiple versions of a model, associate rich metadata, and manage deployment workflows in a scalable, controlled manner. Each model can belong to a model group, which acts as a container for all versions of that particular model. Versions can store training metrics, hyperparameters, model artifacts, and other key metadata, enabling reproducibility, auditing, and automated promotion between stages (e.g., Staging # Production).
Option A, while using the Model Registry, relies on manually tagging versions and creating key-value pairs to store metadata. This approach is error-prone, lacks structured versioning, and does not integrate with SageMaker's deployment pipelines.
Options C and D suggest using Amazon ECR repositories. While ECR can store containerized model artifacts, it is not designed for ML-specific metadata, versioning, or automated model stage transitions. Using ECR alone would require custom-built solutions for metadata management, auditing, and version tracking, adding unnecessary operational overhead.
By leveraging the Model Registry with model groups, organizations can automate promotions, apply approval workflows, and track lineage efficiently, fully aligning with AWS best practices for ML model development and production readiness. This ensures compliance, reproducibility, and reduces operational complexity in enterprise AI platforms.
Using the Model Registry and model groups is the standard AWS-recommended approach for enterprise-scale model cataloging and version control, enabling teams to focus on model improvement rather than infrastructure management.
NEW QUESTION # 165
A company needs to give its ML engineers appropriate access to training data. The ML engineers must access training data from only their own business group. The ML engineers must not be allowed to access training data from other business groups.
The company uses a single AWS account and stores all the training data in Amazon S3 buckets.
All ML model training occurs in Amazon SageMaker.
Which solution will provide the ML engineers with the appropriate access?
Answer: D
NEW QUESTION # 166
An ML engineer is building an ML model in Amazon SageMaker AI. The ML engineer needs to load historical data directly from Amazon S3, Amazon Athena, and Snowflake into SageMaker AI.
Which solution will meet this requirement?
Answer: D
Explanation:
AWS provides Amazon SageMaker Data Wrangler as a native tool for importing, transforming, and analyzing data from multiple sources directly into SageMaker Studio. Data Wrangler supports Amazon S3, Amazon Athena, and Snowflake as built-in data sources through managed connectors.
Using Data Wrangler, ML engineers can query data from Athena using SQL, load structured files from S3, and securely connect to Snowflake without writing custom ingestion code. This approach significantly reduces development effort and aligns with AWS best practices for rapid ML experimentation.
Option A is incorrect because AWS Glue DataBrew is designed for data preparation but does not natively integrate with SageMaker training workflows. Option B introduces unnecessary complexity and is not intended for direct ML data loading. Option C focuses on feature storage, not raw historical data ingestion.
Therefore, SageMaker Data Wrangler is the correct solution.
NEW QUESTION # 167
A company wants to host an ML model on Amazon SageMaker. An ML engineer is configuring a continuous integration and continuous delivery (Cl/CD) pipeline in AWS CodePipeline to deploy the model. The pipeline must run automatically when new training data for the model is uploaded to an Amazon S3 bucket.
Select and order the pipeline's correct steps from the following list. Each step should be selected one time or not at all. (Select and order three.)
* An S3 event notification invokes the pipeline when new data is uploaded.
* S3 Lifecycle rule invokes the pipeline when new data is uploaded.
* SageMaker retrains the model by using the data in the S3 bucket.
* The pipeline deploys the model to a SageMaker endpoint.
* The pipeline deploys the model to SageMaker Model Registry.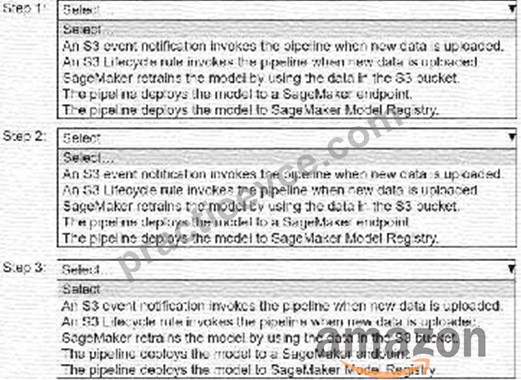
Answer:
Explanation: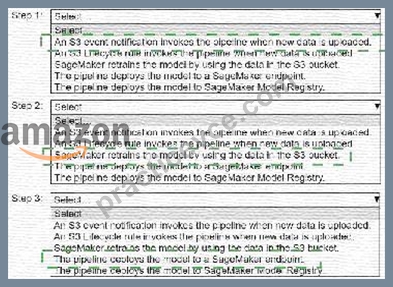
Explanation:
Step 1: An S3 event notification invokes the pipeline when new data is uploaded.
Step 2: SageMaker retrains the model by using the data in the S3 bucket.
Step 3: The pipeline deploys the model to a SageMaker endpoint.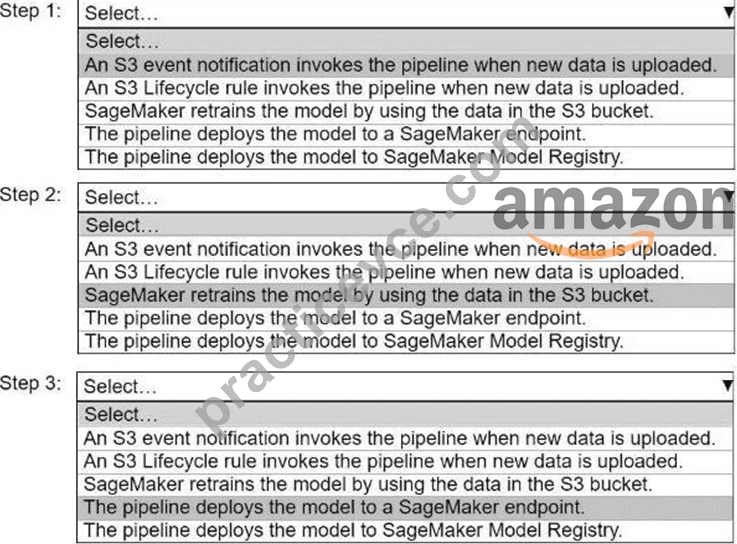
* Step 1: An S3 Event Notification Invokes the Pipeline When New Data is Uploaded
* Why? The CI/CD pipeline should be triggered automatically whenever new training data is uploaded to Amazon S3. S3 event notifications can be configured to send events to AWS services like Lambda, which can then invoke AWS CodePipeline.
* How? Configure the S3 bucket to send event notifications (e.g., s3:ObjectCreated:*) to AWS Lambda, which in turn triggers the CodePipeline.
* Step 2: SageMaker Retrains the Model by Using the Data in the S3 Bucket
* Why? The uploaded data is used to retrain the ML model to incorporate new information and maintain performance. This step is critical to updating the model with fresh data.
* How? Define a SageMaker training step in the CI/CD pipeline, which reads the training data from the S3 bucket and retrains the model.
* Step 3: The Pipeline Deploys the Model to a SageMaker Endpoint
* Why? Once retrained, the updated model must be deployed to a SageMaker endpoint to make it available for real-time inference.
* How? Add a deployment step in the CI/CD pipeline, which automates the creation or update of the SageMaker endpoint with the retrained model.
Order Summary:
* An S3 event notification invokes the pipeline when new data is uploaded.
* SageMaker retrains the model by using the data in the S3 bucket.
* The pipeline deploys the model to a SageMaker endpoint.
This configuration ensures an automated, efficient, and scalable CI/CD pipeline for continuous retraining and deployment of the ML model in Amazon SageMaker.
NEW QUESTION # 168
An ML engineer must choose the appropriate Amazon SageMaker algorithm to solve specific AI problems.
Select the correct SageMaker built-in algorithm from the following list for each use case. Each algorithm should be selected one time.
* Random Cut Forest (RCF) algorithm
* Semantic segmentation algorithm
* Sequence-to-Sequence (seq2seq) algorithm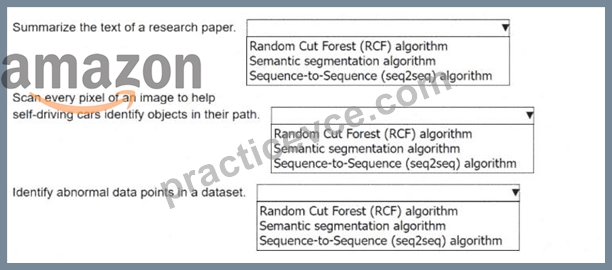
Answer:
Explanation: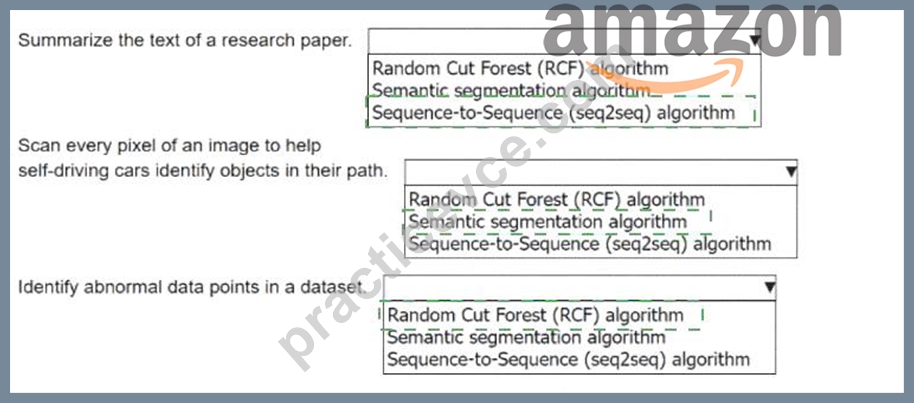
Explanation:
Use case 1:
Summarize the text of a research paper
## Sequence-to-Sequence (seq2seq) algorithm
Why:
Seq2seq models are designed for natural language generation tasks such as text summarization, translation, and paraphrasing. AWS documentation explicitly lists text summarization as a primary use case for the SageMaker seq2seq algorithm.
Use case 2:
Scan every pixel of an image to help self-driving cars identify objects in their path
## Semantic segmentation algorithm
Why:
Semantic segmentation performs pixel-level classification, assigning a class label to every pixel in an image.
This is exactly what is required for applications such as autonomous driving, road scene understanding, and object boundary detection.
Use case 3:
Identify abnormal data points in a dataset
## Random Cut Forest (RCF) algorithm
Why:
Random Cut Forest is an unsupervised anomaly detection algorithm. AWS SageMaker RCF is purpose-built to identify outliers, unusual patterns, and anomalies in numerical datasets, making it ideal for fraud detection, monitoring, and abnormal data point detection.
NEW QUESTION # 169
......
In PracticeVCE's website you can free download study guide, some exercises and answers about Amazon Certification MLA-C01 Exam as an attempt.
Reliable MLA-C01 Dumps Free: https://www.practicevce.com/Amazon/MLA-C01-practice-exam-dumps.html
BONUS!!! Download part of PracticeVCE MLA-C01 dumps for free: https://drive.google.com/open?id=10mxKPGfx7W2SjLg8v9brEuSkhEkyjlzw