Test DP-300 Sample Online, DP-300 Exam Preparation

BTW, DOWNLOAD part of ITPassLeader DP-300 dumps from Cloud Storage: https://drive.google.com/open?id=11txNivj7J1qU-z7R07wZOZe-4ABuppiL

Many candidates do not have actual combat experience, for the qualification examination is the first time to attend, so about how to get the test Microsoft certification didn't own a set of methods, and cost a lot of time to do something that has no value. With our DP-300 exam Practice, you will feel much relax for the advantages of high-efficiency and accurate positioning on the content and formats according to the candidates' interests and hobbies. Numerous grateful feedbacks form our loyal customers proved that we are the most popular vendor in this field to offer our DP-300 Preparation questions.

Microsoft DP-300 Exam Syllabus Topics:

SectionWeightObjectives
Implement a secure environment20–25%- Configure authentication and authorization
  • 1. Apply least privilege principle
    • 2. Implement Microsoft Entra ID authentication
      • 3. Manage database users, roles, and permissions
        - Secure data at rest and in transit
        • 1. Configure encryption for connections and data transfer
          • 2. Manage keys and certificates
            • 3. Implement Transparent Data Encryption
              - Implement compliance and security controls
              • 1. Assess and remediate vulnerabilities
                • 2. Implement data masking and classification
                  • 3. Configure auditing and logging
                    Monitor and optimize operational resources15–20%- Automate maintenance and operations
                    • 1. Schedule and perform updates and patches
                      • 2. Automate tasks using jobs, scripts, or Logic Apps
                        • 3. Manage database lifecycle operations
                          - Monitor database performance and health
                          • 1. Use Azure Monitor, SQL Insights, and metrics
                            • 2. Set up alerts and notifications
                              • 3. Identify and diagnose performance issues
                                - Optimize resource consumption
                                • 1. Adjust compute, storage, and tier settings
                                  • 2. Implement auto-scaling and elasticity
                                    • 3. Manage costs and licensing
                                      Optimize query performance15–20%- Analyze query execution plans
                                      • 1. Identify bottlenecks and inefficiencies
                                        • 2. Evaluate index usage and design
                                          • 3. Interpret execution plans and statistics
                                            - Improve query performance
                                            • 1. Optimize T-SQL code and constructs
                                              • 2. Use query store and performance tuning tools
                                                • 3. Create and modify indexes
                                                  - Manage workload performance
                                                  • 1. Troubleshoot slow-running queries
                                                    • 2. Implement partitioning and compression
                                                      • 3. Control resource usage and concurrency
                                                        Plan and implement data platform resources15–20%- Deploy database resources
                                                        • 1. Deploy Azure SQL Database, Managed Instance, and SQL Server on Azure VMs
                                                          • 2. Automate deployment using templates, PowerShell, or CLI
                                                            • 3. Configure resources for scale and performance
                                                              - Implement migration strategies
                                                              • 1. Perform offline and online migrations
                                                                • 2. Migrate between Azure services or from on-premises
                                                                  • 3. Evaluate migration requirements and strategies
                                                                    - Plan deployment of database offerings
                                                                    • 1. Plan for scalability and performance requirements
                                                                      • 2. Identify use cases for hybrid and multi-cloud solutions
                                                                        • 3. Evaluate deployment options for Azure SQL services
                                                                          Plan and configure high availability and disaster recovery20–25%- Implement backup and restore
                                                                          • 1. Perform point-in-time and long-term retention restores
                                                                            • 2. Configure automated backups and retention
                                                                              • 3. Manage backup storage and costs
                                                                                - Configure high availability solutions
                                                                                • 1. Configure Always On availability groups
                                                                                  • 2. Test and monitor HA/DR operations
                                                                                    • 3. Implement failover groups and auto-failover
                                                                                      - Design HA/DR strategy
                                                                                      • 1. Choose between built-in and custom solutions
                                                                                        • 2. Define RPO and RTO requirements
                                                                                          • 3. Evaluate hybrid and cross-region options

                                                                                            >> Test DP-300 Sample Online <<

                                                                                            Free PDF 2026 Microsoft DP-300: High Pass-Rate Test Administering Relational Databases on Microsoft Azure Sample Online

                                                                                            Every working person knows that DP-300 is a dominant figure in the field and also helpful for their career. If DP-300 reliable exam bootcamp helps you pass exams and get a qualification certificate you will obtain a better career even a better life. Our study DP-300 Guide materials cover most of latest real DP-300 test questions and answers. If you are certainly determined to make something different in the field, a useful certification will be a stepping-stone for your career, so why not try our product?

                                                                                            Microsoft Administering Relational Databases on Microsoft Azure Sample Questions (Q43-Q48):

                                                                                            NEW QUESTION # 43
                                                                                            You have an Azure Databricks workspace named workspace1 in the Standard pricing tier. Workspace1 contains an all-purpose cluster named cluster1.
                                                                                            You need to reduce the time it takes for cluster1 to start and scale up. The solution must minimize costs.
                                                                                            What should you do first?

                                                                                            Answer: A

                                                                                            Explanation:
                                                                                            You can use Databricks Pools to Speed up your Data Pipelines and Scale Clusters Quickly.
                                                                                            Databricks Pools, a managed cache of virtual machine instances that enables clusters to start and scale 4 times faster.
                                                                                            Reference:
                                                                                            https://databricks.com/blog/2019/11/11/databricks-pools-speed-up-data-pipelines.html Basic Concept: This question tests plan and configure a high availability and disaster recovery (ha/dr) environment in the DP-300 exam context. The correct choice is determined by the exact service boundary and operational requirement stated in the scenario.
                                                                                            Why C is Correct: Create a pool in workspace1. is part of the availability or recovery design space, but the correct choice must satisfy the specified failover, restore, quorum, RPO, or RTO requirement. The scenario asks for: You need to reduce the time it takes for cluster1 to start and scale up. That makes Create a pool in workspace1. the option that satisfies the required Azure SQL layer and operational outcome.
                                                                                            Why A is Wrong: Upgrade workspace1 to the Premium pricing tier. is part of the availability or recovery design space, but the correct choice must satisfy the specified failover, restore, quorum, RPO, or RTO requirement. It does not meet the failover, restore, quorum, or cross-region continuity target stated in the question, even if it is valid in a different availability design.
                                                                                            Why B is Wrong: Configure a global init script for workspace1. is part of the availability or recovery design space, but the correct choice must satisfy the specified failover, restore, quorum, RPO, or RTO requirement. It handles a different resilience pattern and would not deliver the failover or recovery behavior required here.
                                                                                            Why D is Wrong: Create a cluster policy in workspace1. is part of the availability or recovery design space, but the correct choice must satisfy the specified failover, restore, quorum, RPO, or RTO requirement. It does not meet the failover, restore, quorum, or cross-region continuity target stated in the question, even if it is valid in a different availability design.


                                                                                            NEW QUESTION # 44
                                                                                            You are designing an enterprise data warehouse in Azure Synapse Analytics that will store website traffic analytics in a star schema.
                                                                                            You plan to have a fact table for website visits. The table will be approximately 5 GB.
                                                                                            You need to recommend which distribution type and index type to use for the table. The solution must provide the fastest query performance.
                                                                                            What should you recommend? To answer, select the appropriate options in the answer area.
                                                                                            NOTE: Each correct selection is worth one point.
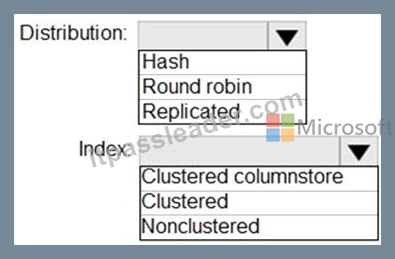
                                                                                            Answer:

                                                                                            Explanation:
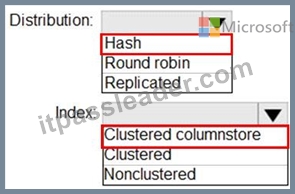
                                                                                            Reference:
                                                                                            https://docs.microsoft.com/en-us/azure/synapse-analytics/sql-data-warehouse/sql-data-warehouse-tables-distribute
                                                                                            https://docs.microsoft.com/en-us/azure/synapse-analytics/sql-data-warehouse/sql-data-warehouse-tables-index


                                                                                            NEW QUESTION # 45
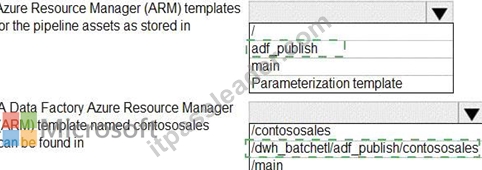
                                                                                            You configure version control for an Azure Data Factory instance as shown in the following exhibit.
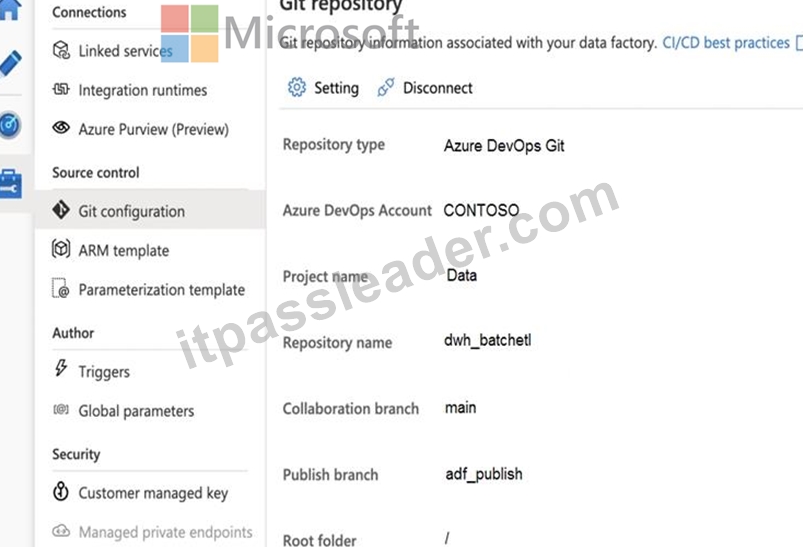
                                                                                            Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic.
                                                                                            NOTE:Each correct selection is worth one point.
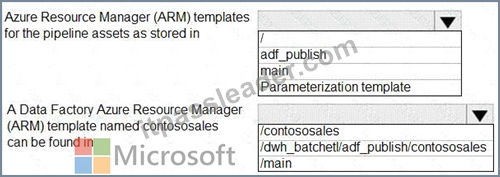
                                                                                            Answer:

                                                                                            Explanation:
                                                                                            Explanation
                                                                                            Graphical user interface, text, application Description automatically generated
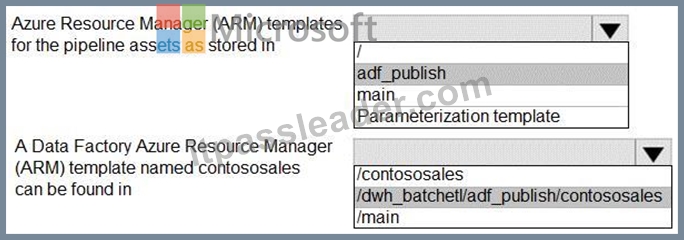
                                                                                            Box 1: adf_publish
                                                                                            By default, data factory generates the Resource Manager templates of the published factory and saves them into a branch called adf_publish. To configure a custom publish branch, add a publish_config.json file to the root folder in the collaboration branch. When publishing, ADF reads this file, looks for the field publishBranch, and saves all Resource Manager templates to the specified location. If the branch doesn't exist, data factory will automatically create it. And example of what this file looks like is below:
                                                                                            {
                                                                                            "publishBranch": "factory/adf_publish"
                                                                                            }
                                                                                            Box 2: /dwh_barchlet/ adf_publish/contososales
                                                                                            RepositoryName: Your Azure Repos code repository name. Azure Repos projects contain Git repositories to manage your source code as your project grows. You can create a new repository or use an existing repository that's already in your project.
                                                                                            Reference:
                                                                                            https://docs.microsoft.com/en-us/azure/data-factory/source-control


                                                                                            NEW QUESTION # 46
                                                                                            You have SQL Server 2019 on an Azure virtual machine that runs Windows Server 2019. The virtual machine has 4 vCPUs and 28 GB of memory.
                                                                                            You scale up the virtual machine to 16 vCPUSs and 64 GB of memory.
                                                                                            You need to provide the lowest latency for tempdb.
                                                                                            What is the total number of data files that tempdb should contain?

                                                                                            Answer: C

                                                                                            Explanation:
                                                                                            The number of files depends on the number of (logical) processors on the machine. As a general rule, if the number of logical processors is less than or equal to eight, use the same number of data files as logical processors. If the number of logical processors is greater than eight, use eight data files and then if contention continues, increase the number of data files by multiples of 4 until the contention is reduced to acceptable levels or make changes to the workload/code.
                                                                                            Reference:
                                                                                            https://docs.microsoft.com/en-us/sql/relational-databases/databases/tempdb-database


                                                                                            NEW QUESTION # 47
                                                                                            You plan to perform batch processing in Azure Databricks once daily.
                                                                                            Which type of Databricks cluster should you use?

                                                                                            Answer: A

                                                                                            Explanation:
                                                                                            Azure Databricks makes a distinction between all-purpose clusters and job clusters. You use all-purpose clusters to analyze data collaboratively using interactive notebooks. You use job clusters to run fast and robust automated jobs.
                                                                                            The Azure Databricks job scheduler creates a job cluster when you run a job on a new job cluster and
                                                                                            terminates the cluster when the job is complete.
                                                                                            Reference:
                                                                                            https://docs.microsoft.com/en-us/azure/databricks/clusters


                                                                                            NEW QUESTION # 48
                                                                                            ......

                                                                                            The Microsoft DP-300 exam questions are designed and verified by experienced and qualified Microsoft DP-300 exam trainers. They work together and share their expertise to maintain the top standard of Microsoft DP-300 Exam Practice test. So you can get trust on Microsoft DP-300 exam questions and start preparing today.

                                                                                            DP-300 Exam Preparation: https://www.itpassleader.com/Microsoft/DP-300-dumps-pass-exam.html

                                                                                            DOWNLOAD the newest ITPassLeader DP-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=11txNivj7J1qU-z7R07wZOZe-4ABuppiL