If you want to have a general review of what you have learned, you can choose us. DP-750 Online test engine has testing history and performance review, and it can help you have a general review of what you have learnt last time. Besides DP-750 Online test engine support all web browsers, and it is convenient and easy to learn, and you can have offline practice if you like. DP-750 Training Materials are high quality and you can pass the exam just one time if you choose us. We offer you free update for one year, and the update version for DP-750 exam dumps will be sent to your email automatically.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
If you choose to sign up to participate in Microsoft certification DP-750 exams, you should choose a good learning material or training course to prepare for the examination right now. Because Microsoft Certification DP-750 Exam is difficult to pass. If you want to pass the exam, you must have a good preparation for the exam.
NEW QUESTION # 66
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales.
Sales stores transaction data and contains the following columns:
- transaction_id (string)
- transaction_date (date)
- amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
- amount must be greater than 0.
- transaction_id must never be null.
- Invalid records must be rejected when data is written to the Sales
table.
What should you do?
Answer: C
Explanation:
To enforce these table-level data quality rules and automatically reject any invalid write operations in Azure Databricks, you must configure NOT NULL and CHECK constraints on the Delta table using standard SQL commands.
In Delta Lake, these constraints are enforced instantly on write. If an incoming record violates any of them, the entire transaction fails, and the invalid records are rejected.
1. Enforce transaction_id Cannot Be Null
Add a NOT NULL constraint to the transaction_id column. This blocks any write attempt containing a null identifier.
ALTER TABLE sales_data ALTER COLUMN transaction_id SET NOT NULL;
2. Enforce amount Must Be Greater Than 0
Add a CHECK constraint to the table to validate that the amount values strictly exceed zero.
ALTER TABLE sales_data ADD CONSTRAINT check_amount_positive CHECK (amount > 0); Reference:
https://docs.databricks.com/aws/en/tables/constraints
NEW QUESTION # 67
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.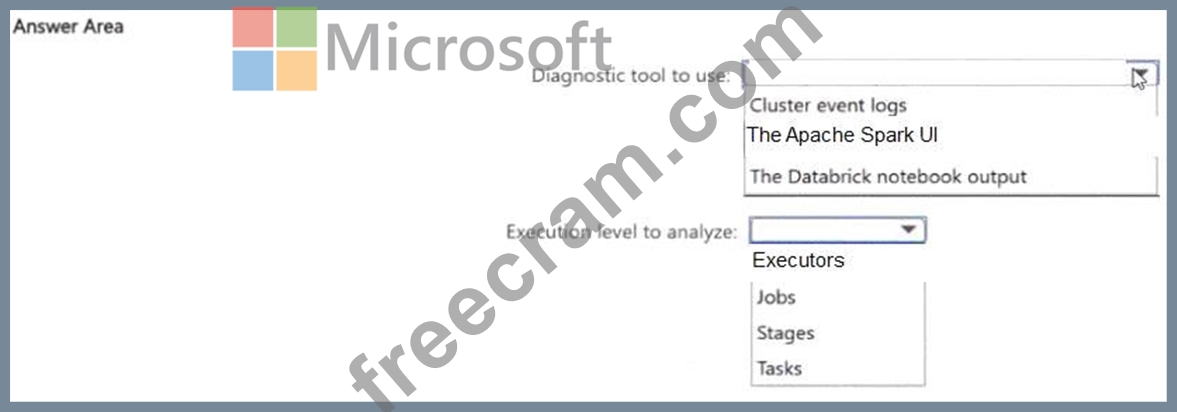
Answer:
Explanation: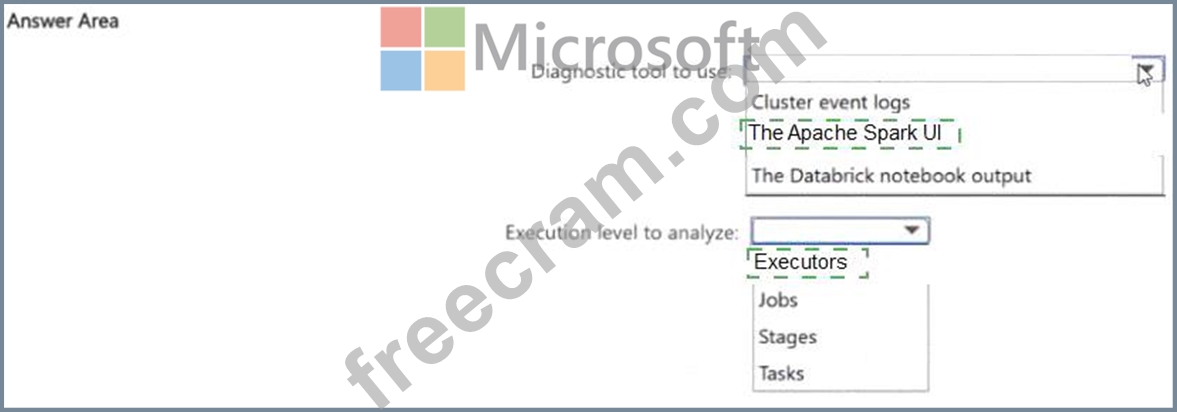
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it ' s accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it ' s processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that
' s data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
NEW QUESTION # 68
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named Catalog1. Catalog1 contains a schema named Schema1 and a table named Table1.
You need to ensure that access to the data in Table1 is controlled by using attribute-based access control (ABAC).
What should you apply to Table1, and how should you control access for users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.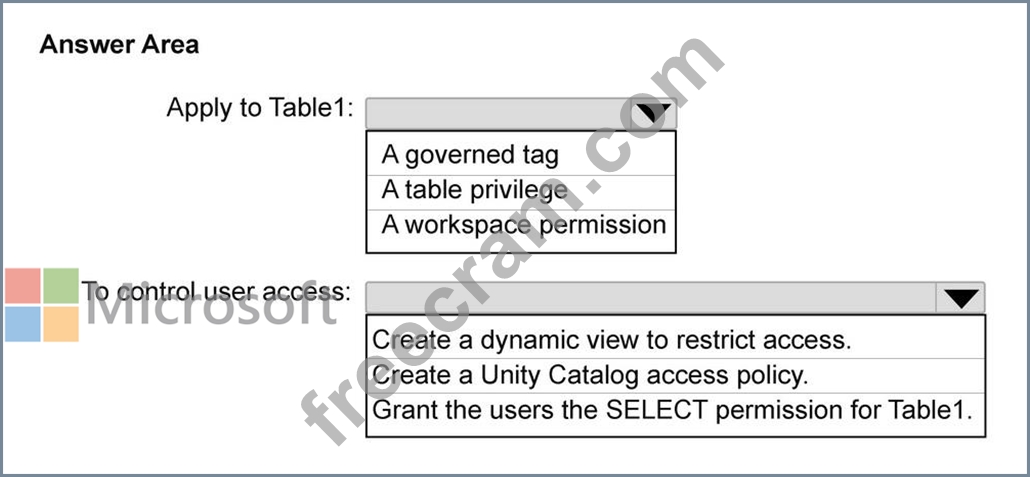
Answer:
Explanation: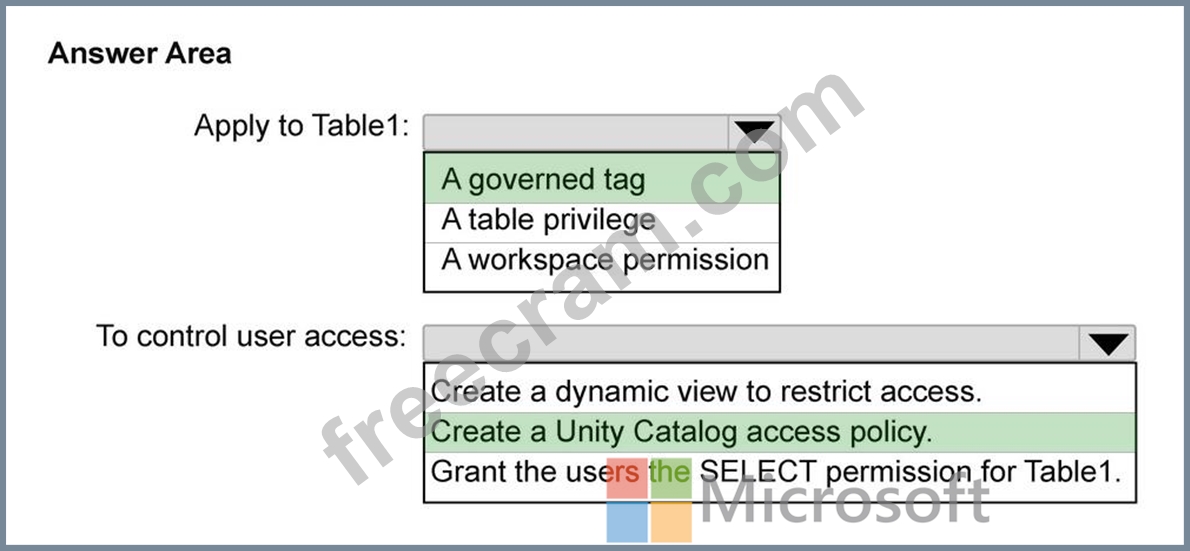
NEW QUESTION # 69
You have an Azure Databricks workspace named Workspace1.
You create a compute cluster named Cluster1 that will be used to ingest data.
You need to install the required libraries on Cluster1. The solution must use Unity Catalog for access control.
What should you do?
Answer: D
Explanation:
The best action is uploading the libraries to the workspace and installing the libraries on the cluster (or ideally uploading them to Unity Catalog volumes).
Unity Catalog Compatibility: When using Unity Catalog for access control, compute clusters are typically configured with Standard (Shared) access mode. In this mode, traditional cluster init scripts [Not B.] face strict execution restrictions or are completely blocked to maintain secure user isolation.
Governance: Uploading your packages as Workspace Files or to Unity Catalog volumes allows administrators to manage access permissions directly and add them to an allowlist if needed.
Cluster-Wide Availability: Installing the libraries via the cluster's Libraries tab ensures that the required ingestion packages are automatically pre-installed and available across all nodes and notebooks running on that cluster.
Incorrect:
[Not A]
Running pip3 install manually on a cluster terminal or inside a notebook only applies to the specific notebook session (notebook-scoped). It does not natively persist across cluster restarts or handle cross-node execution effectively for data ingestion pipelines.
[Not B]
Running a custom script or a legacy init script to modify system-level paths introduces security risks and is generally incompatible with Unity Catalog's strict execution isolation policies for shared compute.
Reference:
https://docs.databricks.com/aws/en/libraries/
NEW QUESTION # 70
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
Answer: D
Explanation:
The correct answer is A. Photon is Azure Databricks ' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso ' s requirement for ' fast and consistent performance for BI workloads ' and ' production ingestion workloads that can scale automatically during telemetry spikes. ' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what ' s needed
- telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
NEW QUESTION # 71
......
As we all know, through the judicial examination, you need to become a lawyer, when the teacher is need through the teachers' qualification examinations. If you want to be an excellent elites in this line, you need to get the Implementing Data Engineering Solutions Using Azure Databricks certification, thus it can be seen through the importance of qualification examination. Only through qualification examination, has obtained the corresponding qualification certificate, we will be able to engage in related work, so the DP-750 Test Torrent is to help people in a relatively short period of time a great important tool to pass the qualification test.
DP-750 Study Plan: https://www.freecram.com/Microsoft-certification/DP-750-exam-dumps.html