Databricks-Machine-Learning-Professional Exam Revision Plan - Dump Databricks-Machine-Learning-Professional Collection

DOWNLOAD the newest PracticeVCE Databricks-Machine-Learning-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1TnzzP4eQDrbJEv8kbxvlPdldWd_fxIhR
To get better condition of life, we all need impeccable credentials of different exams to prove individual’s capacity. However, weak Databricks-Machine-Learning-Professional practice materials may descend and impair your ability and flunk you in the real exam unfortunately. And the worst condition is all that work you have paid may go down the drain for those Databricks-Machine-Learning-Professional question torrent lack commitments and resolves to help customers. The practice materials of the exam with low quality may complicate matters of the real practice exam. So, you must know about our Databricks-Machine-Learning-Professional question torrent.
| Section | Weight | Objectives |
|---|
| Topic 1: Model Deployment | 12% | - Model rollout and version management
- Custom model serving
- Deployment strategies
|
| Topic 2: ML Ops | 44% | - Automated retraining workflows
- Environment management with Databricks Asset Bundles
- Model monitoring and drift detection with Lakehouse Monitoring
- Testing and validation strategies
|
| Topic 3: Model Development | 44% | - Distributed training and hyperparameter tuning
- Advanced MLflow usage
- Scalable ML pipelines with SparkML
- Feature Store and automated feature pipelines
|
>> Databricks-Machine-Learning-Professional Exam Revision Plan <<
Dump Databricks-Machine-Learning-Professional Collection & Study Databricks-Machine-Learning-Professional Center
The browser-based version has all features of the desktop Databricks-Machine-Learning-Professional practice exam. You don't need special plugins or software installations to operate the web-based Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) practice exam. This Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) practice test is compatible with every browser such as MS Edge, Chrome, Internet Explorer, Firefox, Opera, and Safari. PracticeVCE's web-based Databricks-Machine-Learning-Professional practice exam promotes self-assessment and self-study.
Databricks Certified Machine Learning Professional Sample Questions (Q91-Q96):
NEW QUESTION # 91
A machine learning engineer has implemented a numeric drift monitoring solution by examining trends in the summary statistics of input variables. However, the engineer's stakeholders would like a more robust monitoring solution. Which of the following can provide a more robust drift monitoring solution for numeric feature variables?
- A. Statistical tests
- B. Oversampling
- C. Correlations
- D. None of these can provide more robust drift monitoring than summary statistics
Answer: A
Explanation:
Statistical tests (such as the Kolmogorov-Smirnov test or Wasserstein distance) provide a more robust and quantitative method for detecting numeric feature drift compared to simple summary statistics. These tests compare the full distributions of features between datasets, making them more sensitive to subtle changes in data behavior over time.
NEW QUESTION # 92
A machine learning engineer is converting a Hyperopt-based hyperparameter tuning process from manual MLflow logging to MLflow Autologging. They are trying to determine how to manage nested Hyperopt runs with MLflow Autologging.
Which of the following approaches will create a single parent run for the process and a child run for each unique combination of hyperparameter values when using Hyperopt and MLflow Autologging?
- A. MLflow Autoloqqinq will automatically accomplish this task with Hyperopt
- B. Startinq a manual parent run before calling fmin
- C. There is no way to accomplish nested runs with MLflow Autoloqqinq and Hyperopt
- D. Starting a manual child run within the objective function
- E. Ensuring that a built-in model flavor is used for the model logging
Answer: B
NEW QUESTION # 93
A data scientist is utilizing MLflow to track their machine learning experiments. After completing a run with run ID run_id for the experiment with experiment ID exp_id, the data scientist wants to programmatically return the logged metrics for run_id. They have an active MLflow Client client and an active Spark session spark. Which lines of code can be used to return the logged metrics for run_id?
- A. client.qet_run(exp_id.run_id).data.metrics
- B. client.get_run(run_id).data.metrics
- C. spark.read.format("mlflow-run").load(run_id)
- D.
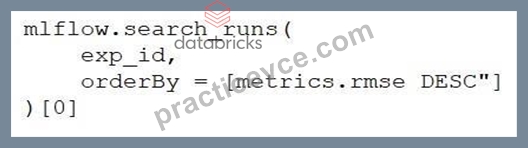
Answer: B
Explanation:
The correct way to retrieve logged metrics for a specific run using the MLflow Client is client.get_run(run_id).data.metrics. This returns a dictionary of all metrics logged for that run. The method in the image (mlflow.search_runs(...)) is for querying across multiple runs, not for accessing a specific run's metrics.
NEW QUESTION # 94
A Machine Learning Engineer has deployed a fraud detection model that processes 10,000 transactions per hour. The model was trained on data from Q1 2024, but it's now Q4 2024. The ML team notices three concerning trends: (1) the model's precision has dropped from 92% to
78% over the past month, (2) the average transaction amount in recent data has increased from
$150 to $220 and (3) the relationship between transaction frequency and fraud likelihood has weakened significantly due to new payment methods being introduced. The engineer needs to implement a monitoring solution that can detect the root cause of the performance degradation, identify why the precision dropped, and be able to do this at the scale needed. Which monitoring pipeline component will do this?
- A. Model Health Monitoring Pipeline because it ensures the infrastructure can handle the 10,000 transactions per hour load.
- B. Model Performance Monitoring Pipeline because it directly tracks precision metrics and can alert when thresholds are breached.
- C. Drift Detection Pipeline because it can identify both the data drift (transaction amount changes) and concept drift (weakened relationship between features and target).
- D. Logging and Monitoring Pipeline because it captures all prediction requests and can identify patterns in the fraud predictions.
Answer: C
Explanation:
A drift detection pipeline is designed to diagnose the root causes of model performance degradation at scale. It can detect data drift, such as changes in the distribution of transaction amounts, and concept drift, where the relationship between input features and the fraud label changes due to new payment methods. This directly explains why precision dropped and provides actionable insight beyond simply observing metric degradation.
NEW QUESTION # 95
A Machine Learning Engineer is building an application that requires low latency data lookups in response to a user's question following a RAG based search. They want to ensure their users can receive as recent data as possible for urgent requests, so data should not be more than a few minutes late. The underlying data is a large table that may contain hundreds of gigabytes of data. Which data serving approach will suit their use case?
- A. Online tables with snapshot sync mode
- B. A fast database hosted in MLflow model serving
- C. Online tables with triggered mode and a time series key
- D. Online tables with continuous sync mode
Answer: D
Explanation:
Online tables with continuous sync mode are designed for low-latency serving while keeping data fresh within minutes. Continuous sync incrementally propagates updates from the large underlying table to the online store, ensuring near-real-time availability for RAG-based lookups without requiring full refreshes, which is ideal for urgent, freshness-sensitive queries on large datasets.
NEW QUESTION # 96
......
IT elite team of our PracticeVCE make a great effort to provide large numbers of examinees with the latest version of Databricks's Databricks-Machine-Learning-Professional exam training materials, and to improve the accuracy of Databricks-Machine-Learning-Professional exam dumps. Choosing PracticeVCE, you can make only half efforts of others to pass the same Databricks-Machine-Learning-Professional Certification Exam. What's more, after you purchase Databricks-Machine-Learning-Professional exam training materials, we will provide free renewal service as long as one year.
Dump Databricks-Machine-Learning-Professional Collection: https://www.practicevce.com/Databricks/Databricks-Machine-Learning-Professional-practice-exam-dumps.html
- Hot Databricks-Machine-Learning-Professional Exam Revision Plan | Efficient Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional 100% Pass ⛅ Search for [ Databricks-Machine-Learning-Professional ] and obtain a free download on ( www.testkingpass.com ) 🅾Databricks-Machine-Learning-Professional Practice Exam
- Exam Databricks-Machine-Learning-Professional Consultant 🍗 Valid Databricks-Machine-Learning-Professional Exam Forum 🕎 Databricks-Machine-Learning-Professional Updated Demo 💥 Search on ▷ www.pdfvce.com ◁ for { Databricks-Machine-Learning-Professional } to obtain exam materials for free download 🚬Real Databricks-Machine-Learning-Professional Exam Dumps
- Databricks-Machine-Learning-Professional Updated Dumps 🧉 Databricks-Machine-Learning-Professional Exam Registration 🤥 Real Databricks-Machine-Learning-Professional Exam Dumps ✉ Search for ➽ Databricks-Machine-Learning-Professional 🢪 and obtain a free download on ✔ www.practicevce.com ️✔️ 🚚Real Databricks-Machine-Learning-Professional Testing Environment
- ML Data Scientist Databricks-Machine-Learning-Professional certkingdom exam torrent - Databricks-Machine-Learning-Professional practice dumps 🎫 Search for ( Databricks-Machine-Learning-Professional ) on 【 www.pdfvce.com 】 immediately to obtain a free download 🔵Databricks-Machine-Learning-Professional Latest Test Vce
- Complete Databricks-Machine-Learning-Professional Exam Revision Plan - Guaranteed Databricks Databricks-Machine-Learning-Professional Exam Success with High-quality Dump Databricks-Machine-Learning-Professional Collection 📙 Open 「 www.prep4away.com 」 and search for “ Databricks-Machine-Learning-Professional ” to download exam materials for free 🦏Databricks-Machine-Learning-Professional Practice Exam
- Exam Databricks-Machine-Learning-Professional Consultant 🏢 Databricks-Machine-Learning-Professional Practice Exam 📽 Latest Databricks-Machine-Learning-Professional Exam Discount 🆒 Open { www.pdfvce.com } enter { Databricks-Machine-Learning-Professional } and obtain a free download 😪Databricks-Machine-Learning-Professional Updated Demo
- Ace Your Exam Preparation with www.validtorrent.com Databricks Databricks-Machine-Learning-Professional Exam Questions 🥛 Copy URL ➡ www.validtorrent.com ️⬅️ open and search for ▶ Databricks-Machine-Learning-Professional ◀ to download for free 💜Databricks-Machine-Learning-Professional Valid Test Review
- ML Data Scientist Databricks-Machine-Learning-Professional certkingdom exam torrent - Databricks-Machine-Learning-Professional practice dumps 😌 Go to website ⏩ www.pdfvce.com ⏪ open and search for 《 Databricks-Machine-Learning-Professional 》 to download for free 😜Databricks-Machine-Learning-Professional Latest Test Vce
- Exam Databricks-Machine-Learning-Professional Labs 🦕 Exam Databricks-Machine-Learning-Professional Labs 🏓 Databricks-Machine-Learning-Professional Valid Test Review 🥑 Download “ Databricks-Machine-Learning-Professional ” for free by simply searching on ⏩ www.examcollectionpass.com ⏪ 😅Real Databricks-Machine-Learning-Professional Exam Dumps
- Latest Databricks-Machine-Learning-Professional Exam Discount 🕛 Databricks-Machine-Learning-Professional Practice Exam 🏛 Databricks-Machine-Learning-Professional Exam Registration 💛 Simply search for ➥ Databricks-Machine-Learning-Professional 🡄 for free download on “ www.pdfvce.com ” 🌳Databricks-Machine-Learning-Professional Practice Exam
- Databricks-Machine-Learning-Professional Practice Exam ✔ Databricks-Machine-Learning-Professional Pdf Files 🚙 Valid Exam Databricks-Machine-Learning-Professional Preparation 🟡 Go to website [ www.vce4dumps.com ] open and search for ▷ Databricks-Machine-Learning-Professional ◁ to download for free ♻Valid Exam Databricks-Machine-Learning-Professional Preparation
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.toprecepty.cz, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free 2026 Databricks Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by PracticeVCE: https://drive.google.com/open?id=1TnzzP4eQDrbJEv8kbxvlPdldWd_fxIhR