Keeping in mind all these benefits, we ensure you can pass the Implementing Data Engineering Solutions Using Azure Databricks DP-750 exam on your maiden attempt with the help of our exceptional Microsoft DP-750 dumps material. Our dedicated and committed team takes feedback from over 90,000 experts worldwide in the Microsoft DP-750 Dumps field to update our product.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Data quality and validation
|
| Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
>> Pass4sure DP-750 Pass Guide <<
Dreaming to be a certified professional in this line? Our DP-750 study materials are befitting choices. We made real test materials in three accessible formats for your inclinations. (PDF, APP, software). Our website is an excellent platform, which provides the questions of these versions of our DP-750 Exam Questions compiled by experts. By browsing this website, all there versions of our DP-750 pratice engine can be chosen according to your taste or preference.
NEW QUESTION # 87
You have an Azure Databricks workspace that is attached to a Unity Catalog metastore named metastore1.
Metastore1 contains a catalog named catalog 1.
You need to create a new schema named schema2 that meets the following requirements:
* Is contained in catalog1
* Uses abfss://containergstorageaccount.dfs.core.windows.net/data as the Managed location Which SQL statement should you execute?
Answer: A
Explanation:
The correct answer is A. The Unity Catalog DDL for creating a schema inside a specific catalog and setting a custom managed storage path uses the three-part name (catalog.schema) and the MANAGED LOCATION clause:
CREATE SCHEMA catalog1.schema2 MANAGED LOCATION ' abfss://... ' ;
The three-part name explicitly places the schema inside catalog1. MANAGED LOCATION tells Unity Catalog where to store managed tables and volumes created under this schema - any managed table without its own explicit location will inherit this path.
Option B uses CREATE CATALOG, which creates an entirely new catalog rather than a schema. Option C uses the LOCATION keyword without MANAGED - that syntax is for external locations, not for overriding the managed storage path of a schema. Option D uses WITH DBPROPERTIES, which stores arbitrary key- value metadata but has no effect on where Unity Catalog physically stores data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-ddl-create- schema
NEW QUESTION # 88
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job! that processes data continuously and fails periodically due to transient errors You need to ensure that Job! meets the following requirements
* Resumes processing from the point that Job1 failed
* Minimizes how long it takes to restart Job!
* Minimizes the costs to restart Job!
What should you do?
Answer: D
Explanation:
The correct answer is B - implement checkpointing.
A checkpoint is a durable record of the streaming job's progress written to ADLS Gen2 or DBFS after each successfully committed micro-batch. When the job restarts after a transient failure, it reads the checkpoint to find the last committed offset and resumes from that exact point - no data is reprocessed, no data is lost.
This satisfies all three requirements directly: checkpointing enables resumption from the failure point (not from the beginning), restart is fast because there's no replay overhead, and costs are minimised because no compute is wasted reprocessing records already handled.
Option A (decrease retry interval) makes the job retry sooner but doesn't control where it resumes from.
Option C (alert and manual restart) adds human latency and doesn't prevent reprocessing without a checkpoint. Option D (increase minimum nodes) reduces the likelihood of resource-related failures but increases cost and doesn't address the recovery behaviour itself.
Reference: https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/query-recovery
NEW QUESTION # 89
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two catalogs named Catalog1 and Catalog2.
An external application uses a service principal named SP1 to connect to a SQL warehouse.
You need to ensure that SP1 can query the data in Catalog1 and Catalog2. The solution must follow the principle of least privilege.
Which permissions should you grant to SP1 for the catalogs?
Answer: B
NEW QUESTION # 90
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.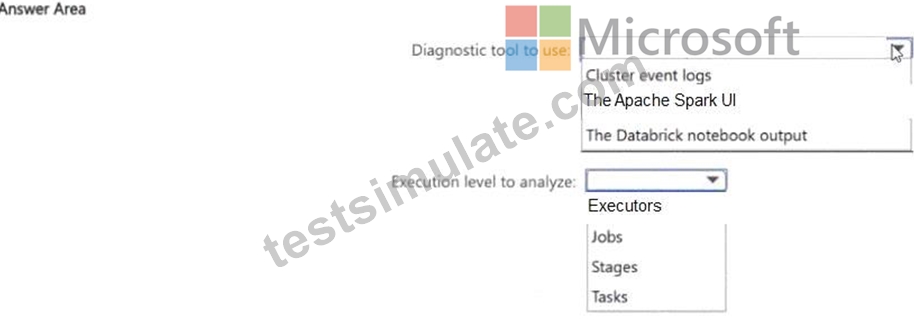
Answer:
Explanation: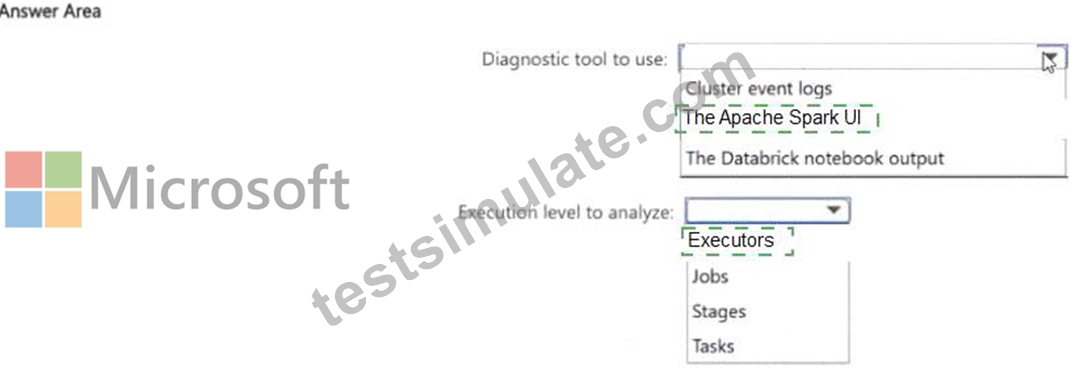
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it's accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it's processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that's data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
NEW QUESTION # 91
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named Catalog1. Catalog1 contains a schema named Schema1 and a table named Table1.
You need to ensure that access to the data in Table1 is controlled by using attribute-based access control (ABAC).
What should you apply to Table1, and how should you control access for users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.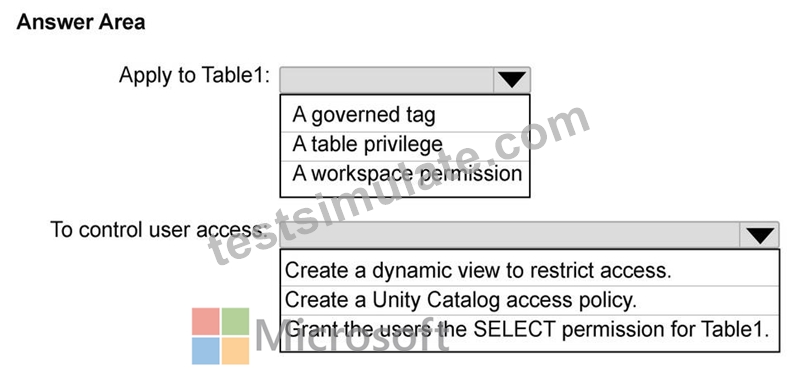
Answer:
Explanation: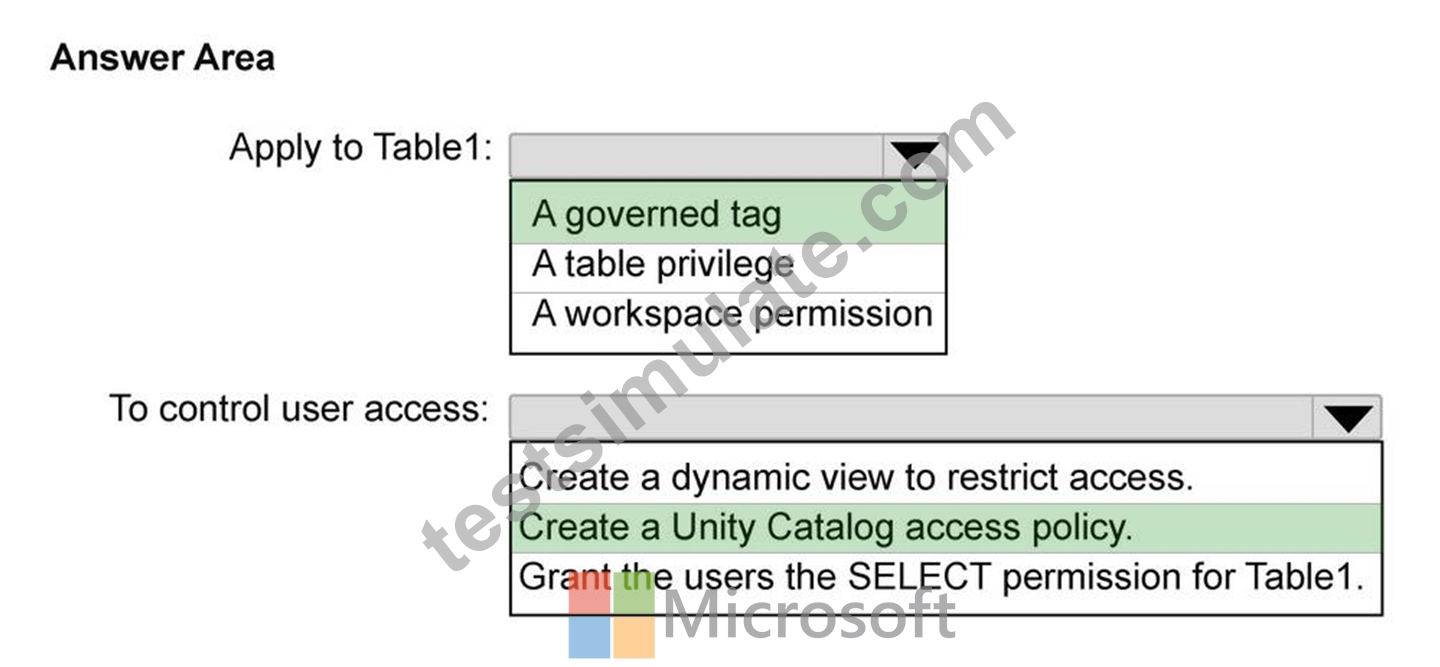
NEW QUESTION # 92
......
We know that time is very precious to everyone, especially the test takers to study our DP-750 exam questions. Saving time means increasing the likelihood of passing the DP-750 exam. In order not to delay your review time, our DP-750 Actual Exam can be downloaded instantly. Within about 5 - 10 minutes of your payment, you will receive our login link available for immediate use of our DP-750 study materials.
Reliable DP-750 Exam Materials: https://www.testsimulate.com/DP-750-study-materials.html