Außerdem sind jetzt einige Teile dieser ZertSoft DP-100 Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1hlWDd59VFIQ_Y3Cd3LqdDpNDxcoatG1e
Wollen Sie die Fragenkataloge zur Microsoft DP-100 Zertifizierungsprüfung haben, die Ihre Zeit und Energie sparen können? Dann wählen Sie ZertSoft. Unsere Fragenkataloge für Microsoft DP-100 Zertifizierungsprüfung werden Ihnen einjähriger Aktualisierung kostenlos bieten, damit Sie die neulich aktualisierten Informationen über Microsoft DP-100 Zertifizierungsprüfung erhalten können. Wir versprechen Ihnen, dass wir Ihnen alle Ihre bezahlten Summe zurückgeben werden, wenn Sie die Zertifizierungsprüfung nicht bestehen, nachdem Sie unsere Produkte gekauft haben.
Die Microsoft DP-100 Zertifizierungsprüfung ist für Datenwissenschaftler und Dateningenieure konzipiert, die ihre Fähigkeit demonstrieren möchten, Datenwissenschaftslösungen auf Azure zu entwerfen und umzusetzen. Diese Prüfung richtet sich an Personen, die Erfahrung mit Azure haben, um Machine-Learning-Modelle zu erstellen und bereitzustellen, sowie an diejenigen, die Erfahrung mit der Datenverwaltung und -verarbeitung auf Azure haben.
Die DP-100-Prüfung deckt eine Reihe von Themen ab, einschließlich Datenvorbereitung, Modellierung und Bereitstellung. Die Kandidaten müssen ihre Fähigkeit demonstrieren, mit verschiedenen Azure -Datendiensten wie Azure Machine Learning, Azure Databricks und Azure Hdinsight zusammenzuarbeiten. Sie müssen auch ihre Kenntnisse in Programmiersprachen wie Python und R. zeigen
Nun bieten viele Ausbildungsinstitute Ihnen die Schulungsunterlagen zur Microsoft DP-100 Zertifizierungsprüfung. Meistens bekommen die Kandidaten per diese Websites keine ausführlichen Materialien. Denn ihre Materialien zur Microsoft DP-100 Zertifizierungsprüfung sind breit gefächert und nicht zielgerichtet. So können sie keine Aufmerksamkeit der Kandidaten gewinnen.
Die Microsoft DP-100 Prüfung ist eine Zertifizierungsprüfung für Personen, die ihr Wissen und ihre Fähigkeiten im Bereich Design und Implementierung von Data Science-Lösungen auf der Microsoft Azure-Plattform demonstrieren möchten. Diese Prüfung richtet sich an Data Scientists, Data Engineers und andere IT-Profis, die für die Gestaltung und Umsetzung von Datenlösungen in ihrer Organisation verantwortlich sind. Diese Prüfung misst die Fähigkeit des Kandidaten, Machine-Learning-Modelle zu entwerfen und umzusetzen, Vorhersagemodelle zu erstellen sowie Azure-Dienste für Data Science bereitzustellen und zu verwalten.
490. Frage
You need to implement a feature engineering strategy for the crowd sentiment local models.
What should you do?
Antwort: B
Begründung:
The linear discriminant analysis method works only on continuous variables, not categorical or ordinal variables.
Linear discriminant analysis is similar to analysis of variance (ANOVA) in that it works by comparing the means of the variables.
Scenario:
Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
Experiments for local crowd sentiment models must combine local penalty detection data.
All shared features for local models are continuous variables.
Incorrect Answers:
B: The Pearson correlation coefficient, sometimes called Pearson's R test, is a statistical value that measures the linear relationship between two variables. By examining the coefficient values, you can infer something about the strength of the relationship between the two variables, and whether they are positively correlated or negatively correlated.
C: Spearman's correlation coefficient is designed for use with non-parametric and non-normally distributed data. Spearman's coefficient is a nonparametric measure of statistical dependence between two variables, and is sometimes denoted by the Greek letter rho. The Spearman's coefficient expresses the degree to which two variables are monotonically related. It is also called Spearman rank correlation, because it can be used with ordinal variables.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/fisher-linear-discriminant- analysis
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/compute-linear-correlation Perform Feature Engineering Testlet 2 Case study Overview You are a data scientist for Fabrikam Residences, a company specializing in quality private and commercial property in the United States. Fabrikam Residences is considering expanding into Europe and has asked you to investigate prices for private residences in major European cities. You use Azure Machine Learning Studio to measure the median value of properties. You produce a regression model to predict property prices by using the Linear Regression and Bayesian Linear Regression modules.
Datasets
There are two datasets in CSV format that contain property details for two cities, London and Paris, with the following columns: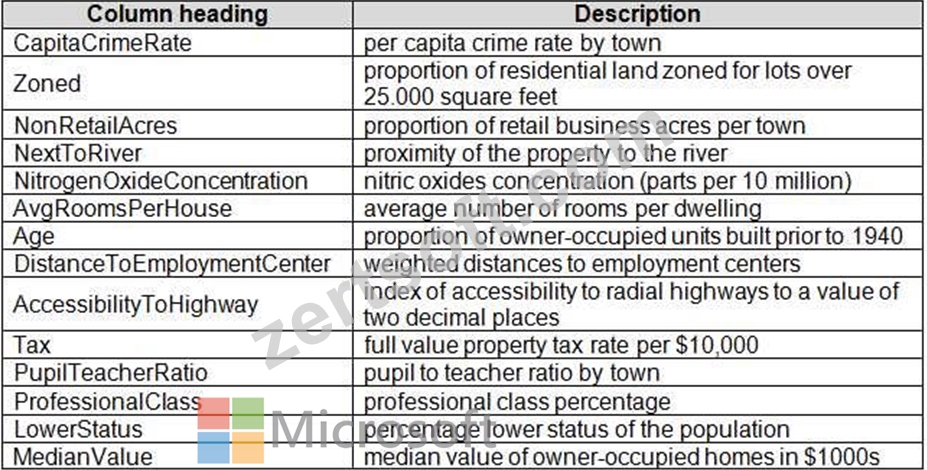
The two datasets have been added to Azure Machine Learning Studio as separate datasets and included as the starting point of the experiment.
Dataset issues
The AccessibilityToHighway column in both datasets contains missing values. The missing data must be replaced with new data so that it is modeled conditionally using the other variables in the data before filling in the missing values.
Columns in each dataset contain missing and null values. The dataset also contains many outliers. The Age column has a high proportion of outliers. You need to remove the rows that have outliers in the Age column.
The MedianValue and AvgRoomsinHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
Model fit
The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
Experiment requirements
You must set up the experiment to cross-validate the Linear Regression and Bayesian Linear Regression modules to evaluate performance.
In each case, the predictor of the dataset is the column named MedianValue. An initial investigation showed that the datasets are identical in structure apart from the MedianValue column. The smaller Paris dataset contains the MedianValue in text format, whereas the larger London dataset contains the MedianValue in numerical format. You must ensure that the datatype of the MedianValue column of the Paris dataset matches the structure of the London dataset.
You must prioritize the columns of data for predicting the outcome. You must use non-parameters statistics to measure the relationships.
You must use a feature selection algorithm to analyze the relationship between the MedianValue and AvgRoomsinHouse columns.
Model training
Given a trained model and a test dataset, you need to compute the permutation feature importance scores of feature variables. You need to set up the Permutation Feature Importance module to select the correct metric to investigate the model's accuracy and replicate the findings.
You want to configure hyperparameters in the model learning process to speed the learning phase by using hyperparameters. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
You are concerned that the model might not efficiently use compute resources in hyperparameter tuning. You also are concerned that the model might prevent an increase in the overall tuning time. Therefore, you need to implement an early stopping criterion on models that provides savings without terminating promising jobs.
Testing
You must produce multiple partitions of a dataset based on sampling using the Partition and Sample module in Azure Machine Learning Studio. You must create three equal partitions for cross-validation. You must also configure the cross-validation process so that the rows in the test and training datasets are divided evenly by properties that are near each city's main river. The data that identifies that a property is near a river is held in the column named NextToRiver. You want to complete this task before the data goes through the sampling process.
When you train a Linear Regression module using a property dataset that shows data for property prices for a large city, you need to determine the best features to use in a model. You can choose standard metrics provided to measure performance before and after the feature importance process completes. You must ensure that the distribution of the features across multiple training models is consistent.
Data visualization
You need to provide the test results to the Fabrikam Residences team. You create data visualizations to aid in presenting the results.
You must produce a Receiver Operating Characteristic (ROC) curve to conduct a diagnostic test evaluation of the model. You need to select appropriate methods for producing the ROC curve in Azure Machine Learning Studio to compare the Two-Class Decision Forest and the Two-Class Decision Jungle modules with one another.
491. Frage
You must use in Azure Data Science Virtual Machine (DSVM) as a compute target.
You need to attach an existing DSVM to the workspace by using the Azure Machine Learning SDK for Python.
How should you complete the following code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.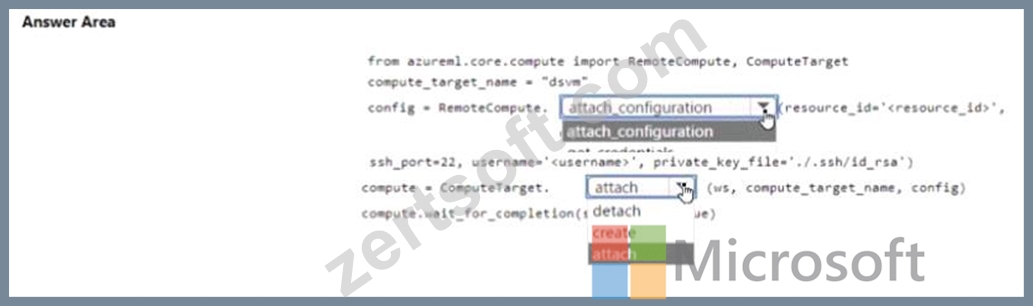
Antwort:
Begründung: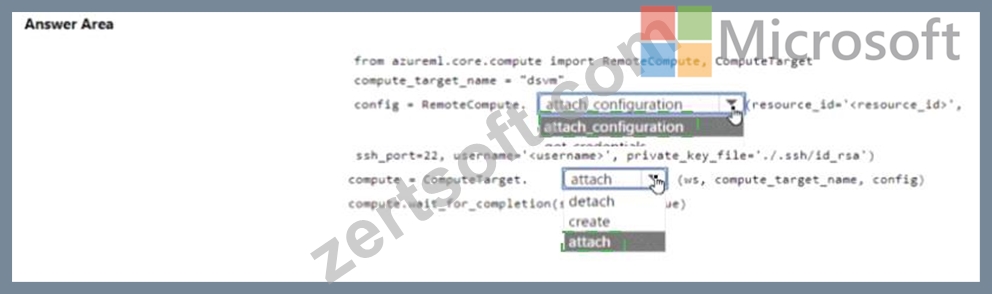
Explanation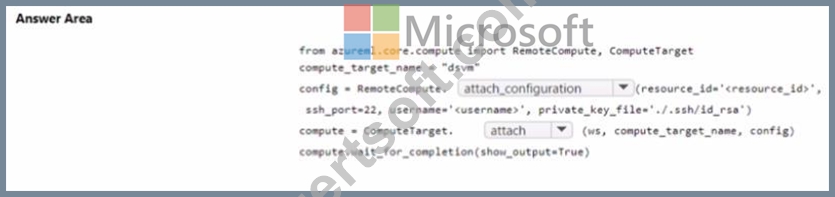
492. Frage
You are designing an Azure Machine Leaning solution by using the Python SDK v2.
You must train and deploy the solution by using a compute target. The compute target must meet the following requirements:
* Enable the use of on-premises compute resources.
* Support autoscalling.
You need to configure a compute target for training and inference.
Which compute target t should you configure?
To answer select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.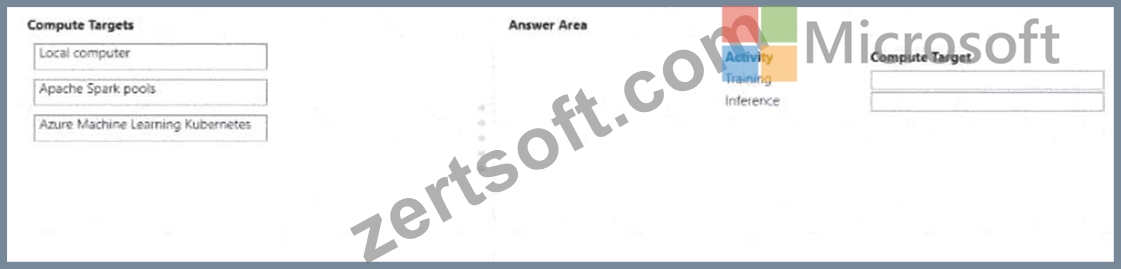
Antwort:
Begründung: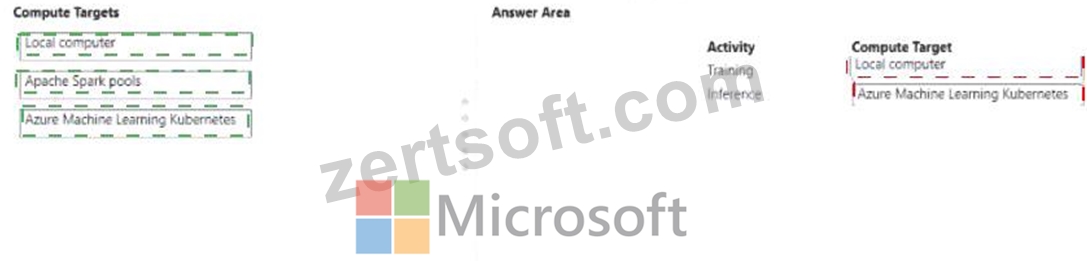
Explanation: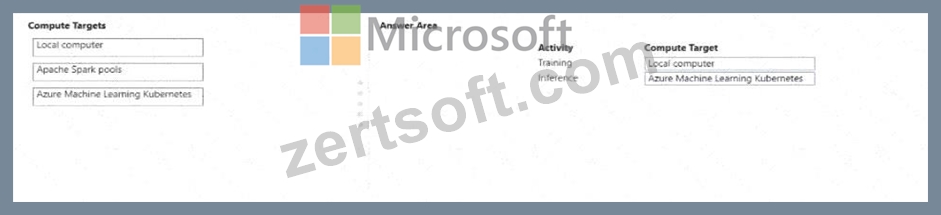
493. Frage
You create an Azure Machine Learning compute resource to train models. The compute resource is configured as follows:
- Minimum nodes: 2
- Maximum nodes: 4
You must decrease the minimum number of nodes and increase the maximum number of nodes to the following values:
- Minimum nodes: 0
- Maximum nodes: 8
You need to reconfigure the compute resource.
What are three possible ways to achieve this goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
Antwort: A,C,D
Begründung:
A: You can manage assets and resources in the Azure Machine Learning studio.
B: The update(min_nodes=None, max_nodes=None, idle_seconds_before_scaledown=None) of the AmlCompute class updates the ScaleSettings for this AmlCompute target.
C: To change the nodes in the cluster, use the UI for your cluster in the Azure portal.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-
core/azureml.core.compute.amlcompute(class)
494. Frage
You plan to use Hyperdrive to optimize the hyperparameters selected when training a model. You create the following code to define options for the hyperparameter experiment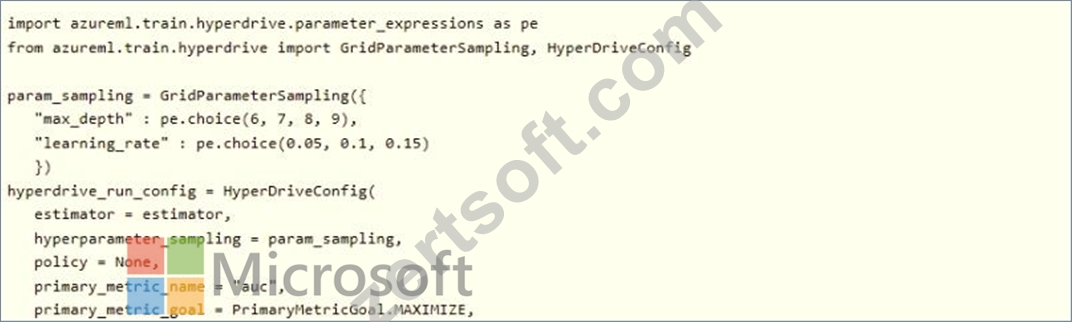
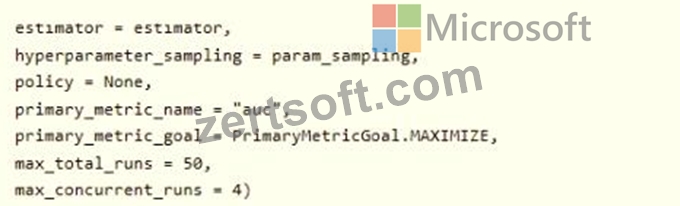
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.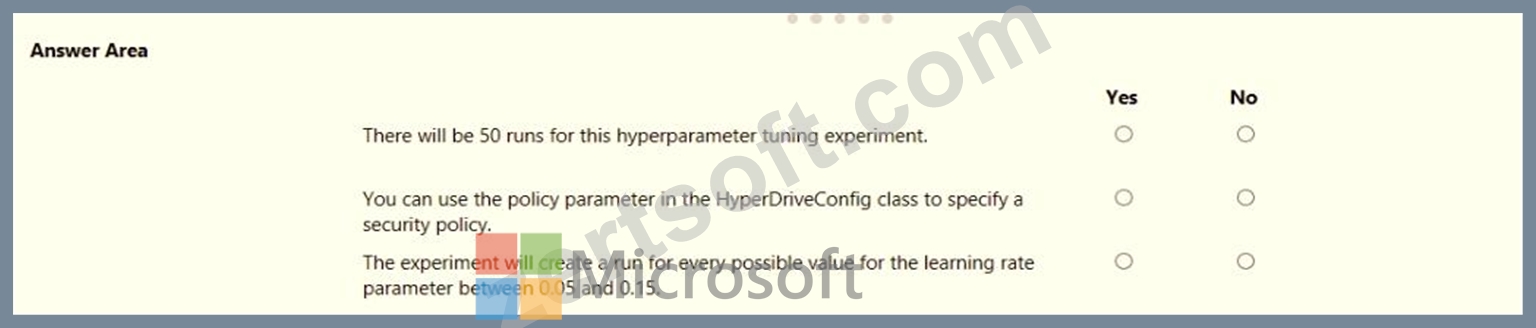
Antwort:
Begründung: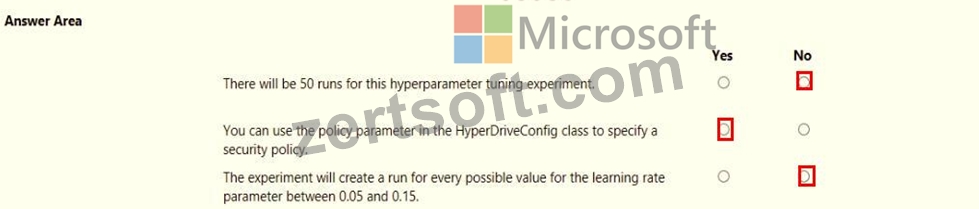
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-train-core/azureml.train.hyperdrive.hyperdriveconfig
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-tune-hyperparameters
495. Frage
......
DP-100 Prüfungsübungen: https://www.zertsoft.com/DP-100-pruefungsfragen.html
Laden Sie die neuesten ZertSoft DP-100 PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1hlWDd59VFIQ_Y3Cd3LqdDpNDxcoatG1e