Jpexamは、精巧にまとめられた非常に効率的な最高の有効なAI-300試験問題を提供するWebサイトです。AI-300学習ガイドで学習すると、時間と労力を節約できます。物事以外のいくつか。 AI-300トレーニング資料の合格率とヒット率も非常に高く、数千人の候補者が当社のWebサイトを信頼し、AI-300試験に合格しています。候補者には非常に多くの保証を提供しており、AI-300学習教材を心配なく購入できます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Topic 2: Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Topic 3: Implement machine learning model lifecycle and operations | 25–30% | - Monitor and maintain models in production
|
| Topic 4: Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Topic 5: Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
私たちのAI-300試験材料とサービスはあなたのAI-300試験に合格することに役に立ちます。私たちはあなたの時間と精力を節約してタイムスケジュールを設定します。 私たちのAI-300試験資料は確かに有効かつ全面的であるので、AI-300試験の合格率が高いです。私たちのAI-300試験資料のような書籍が少ないので、早く買いましょう!
質問 # 116
-
You have an Azure Machine Learning workspace and a collection of image files stored in two Azure Blob Storage accounts.
You need to configure data asset properties.
Which values should you use in your configuration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.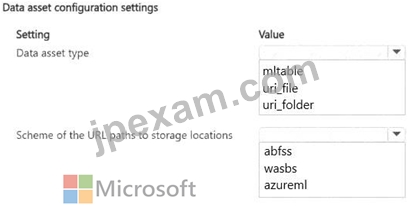
正解:
解説: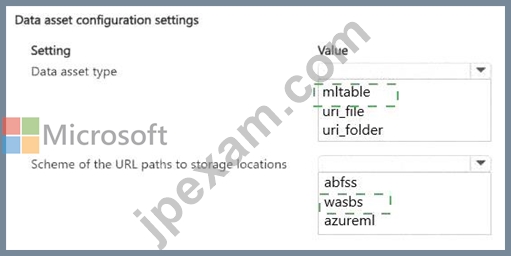
Explanation:
Data asset type: mltable
Scheme of the URL paths to storage locations: wasbs
The correct data asset type is mltable because the image collection is distributed across multiple storage locations . Microsoft identifies MLTable as the appropriate Azure Machine Learning data asset type when unstructured data such as images, text, or audio is spread across multiple storage locations. An MLTable definition can contain multiple file, folder, or pattern entries, allowing one logical data asset to reference image data residing in different storage accounts.
A uri_folder data asset is appropriate when the required unstructured files reside within a single folder path .
It represents one folder location and therefore does not provide the same multi-path abstraction required by this scenario. uri_file represents only an individual file and is clearly unsuitable for a collection of images.
For the path scheme, Azure Machine Learning uses wasbs:// for Azure Blob Storage. Microsoft documents the canonical format as:
wasbs:// < container > @ < account > .blob.core.windows.net/ < path >
By comparison, abfss:// is used for Azure Data Lake Storage Gen2, while azureml:// identifies Azure Machine Learning datastore paths rather than direct Azure Blob Storage URLs.
Therefore, an MLTable containing multiple wasbs:// paths correctly represents image files distributed across the two Azure Blob Storage accounts.
Study Guide Reference: Design and implement an MLOps infrastructure - Azure Machine Learning data assets, MLTable, multi-location datasets, storage URI schemes, and Blob Storage integration.
質問 # 117
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals.
You have an Azure Machine Learning workspace. You connect to a terminal session from the Notebooks page in Azure Machine Learning studio.
You plan to add a new Jupyter kernel that will be accessible from the same terminal session.
You need to perform the task that must be completed before you can add the new kernel.
Solution: Create an environment.
Does the solution meet the goal?
正解:A
解説:
Yes. Before registering a new Jupyter kernel on an Azure Machine Learning compute instance, you create a separate environment that will contain the Python runtime and packages associated with that kernel.
Microsoft's current Azure Machine Learning terminal guidance explicitly starts the new-kernel procedure by creating a Conda environment, for example:
conda create --name newenv
The environment is then activated by using conda activate newenv. After activation, pip and ipykernel are installed into that environment, and the environment is finally registered as a Jupyter kernel by using python - m ipykernel install.
This separation is important because each Jupyter kernel should execute against a defined Python environment containing its own dependencies. It prevents package changes for one notebook workload from unexpectedly affecting another kernel or the Azure Machine Learning system environment.
Therefore, creating an environment is a valid prerequisite in the process of adding a new Jupyter kernel from the Azure Machine Learning terminal. The environment provides the runtime context that is subsequently exposed to Jupyter through its kernel specification.
Study Guide Reference: Design and implement an MLOps infrastructure - Azure Machine Learning compute instances, Jupyter kernels, Conda environments, dependency isolation, and interactive development.
質問 # 118
You have an Azure Machine Learning (ML) model deployed to an online endpoint.
You need to review container logs from the endpoint by using Azure Ml Python SDK v2. The logs must include the console log from the inference server with print/log statements from the models scoring script.
What should you do first?
正解:D
質問 # 119
You manage an Azure Machine learning workspace.
You build a custom model you must log with Mlftow. The custom model includes the following:
* The model is not natively supported by Mlflow.
* The model cannot be serialized in Pickle format.
* The model source code is complex.
* The Python library tor the model must be packaged with the model.
You need to create a custom model flavor to enable logging with ML. flow.
What should you use?
正解:A
質問 # 120
A pipeline step fails intermittently due to transient compute issues. You need to improve reliability without modifying core logic or increasing cost significantly. What is the BEST approach?
正解:D
解説:
Retry policies allow pipeline steps to automatically recover from transient failures, such as temporary compute or network issues. This improves reliability without modifying core logic or increasing infrastructure costs. Increasing compute resources does not address transient failure scenarios effectively.
質問 # 121
......
JpexamのAI-300試験トレントの合格率は、効果的で有用を証明する唯一の基準であるというのは常識です。 AI-300試験問題の利点についての一般的な考えは既にお持ちのことと思いますが、AI-300ガイドトレントの最大の強みである最高の合格率をお見せしたいと思います。 Microsoft統計によると、AI-300ガイドトレントのガイダンスに従って試験を準備したお客様の合格率は、98〜100%に達し、AI-300試験トレントを20〜30時間しか練習していません。
AI-300日本語練習問題: https://www.jpexam.com/AI-300_exam.html