AI-500 Exam Questions of ExamsTorrent are ideal for the students who are willing to prepare for the exam in a short time. The Designing and Implementing Multi-Agent AI Solutions (AI-500) professionals have worked hard on making this product one of the most successful and user-friendly. This Designing and Implementing Multi-Agent AI Solutions (AI-500) exam prep material came into existence after talking to many Microsoft professionals and getting their positive feedback. The ExamsTorrent guarantees the customers that if they fail to pass the Designing and Implementing Multi-Agent AI Solutions (AI-500) exam despite all their efforts they can claim a refund according to some terms and conditions.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop multi-agent solutions in Azure | 30–35% | - Manage state and memory
|
| Topic 2: Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Implement observability
|
| Topic 3: Architect multi-agent solutions | 15–20% | - Design logical architecture for multi-agent systems
|
| Topic 4: Secure, govern, and deploy multi-agent solutions | 20–25% | - Deploy and maintain solutions
|
We provide three versions of AI-500 study materials to the client and they include PDF version, PC version and APP online version. Different version boosts own advantages and using methods. The content of AI-500 exam torrent is the same but different version is suitable for different client. For example, the PC version of AI-500 Study Materials supports the computer with Windows system and its advantages includes that it simulates real operation AI-500 exam environment and it can simulates the exam and you can attend time-limited exam on it. Most candidates liked and passed with this version.
NEW QUESTION # 10
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.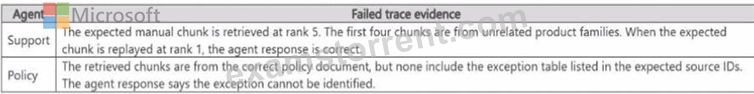
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.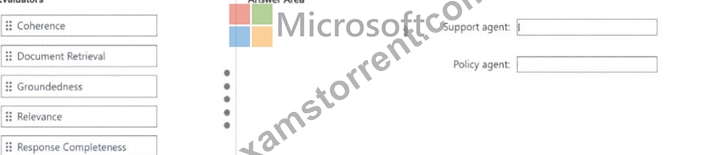
Answer:
Explanation: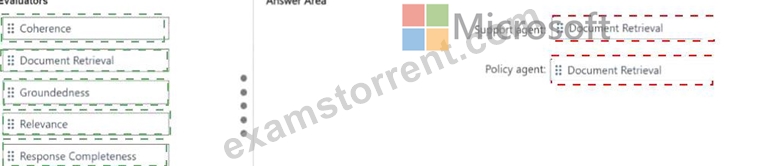
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 11
You have a Microsoft Foundry multi-agent solution for loan applications. Each agent scores a full application independently and does NOT require output from other agents.
You need to recommend an orchestration pattern that meets the following requirements:
Produces one aggregated recommendation
Preserves independent scoring -
Minimizes end-to-end latency -
Minimize development effort -
What should you recommend?
Answer: A
Explanation:
The scoring agents do not depend on each other ' s output, so their work should be fanned out in parallel and aggregated afterward. Microsoft Agent Framework concurrent orchestration is intended for independent participants that can process the same input simultaneously. That minimizes end-to-end latency because completion time approaches the slowest individual scorer instead of the sum of all scorers. The concurrent workflow also provides a fan-in stage that can aggregate the separate scores into one recommendation without requiring a complex custom conversation protocol. Sequential orchestration wastes time by serializing independent work. Group chat and Magentic-style collaboration introduce unnecessary coordination and planning overhead when the agents simply need independent scoring. Therefore D, concurrent, is the simplest and fastest orchestration pattern. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Concurrent orchestration
NEW QUESTION # 12
You have a Microsoft Foundry multi-agent solution. The agents contain the CI/CD evaluation gates shown in the following table.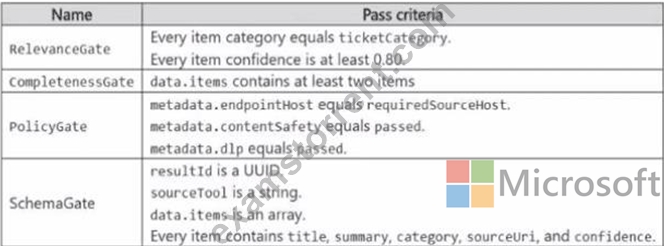
You call one of the agents by using the request context in the evaluation process as shown in the following table.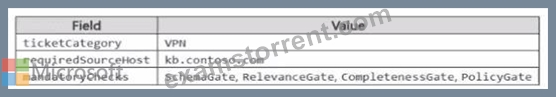
The agent receives the following results for the tool.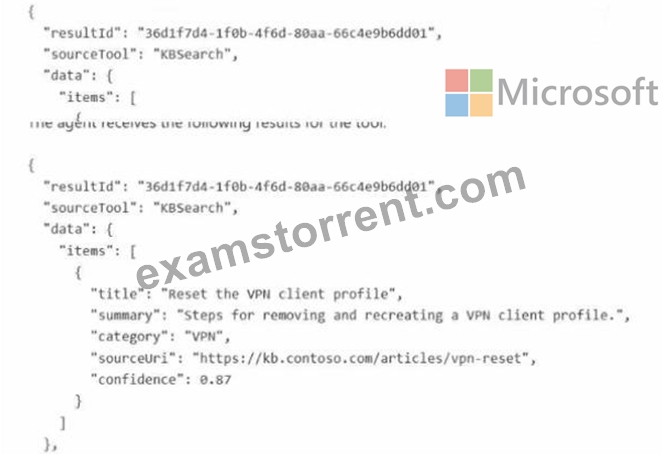
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.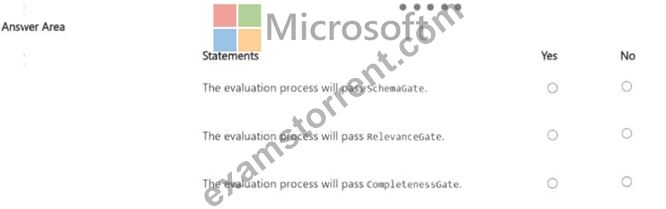
Answer:
Explanation: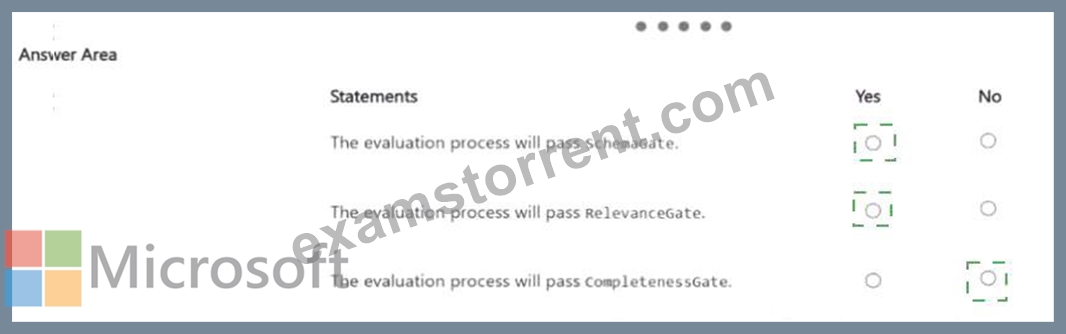
Explanation:
SchemaGate: Yes; RelevanceGate: Yes; CompletenessGate: No.
The supplied tool result satisfies the structural requirements of SchemaGate: it includes a valid-looking UUID result identifier, a string sourceTool value, an items array, and the required fields on the item. RelevanceGate also passes because the request category is VPN, the returned item category is VPN, and its confidence value of 0.87 is above the required 0.80 threshold. CompletenessGate fails because the rule requires at least two items while the response contains only one. This is a deterministic gate evaluation rather than an LLM-judge interpretation, so the values should be checked directly against the declared criteria. Microsoft Foundry evaluation datasets and CI/CD quality gates are designed to make exactly these regression checks repeatable before release. Therefore the correct sequence is Yes, Yes, No. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - evaluation datasets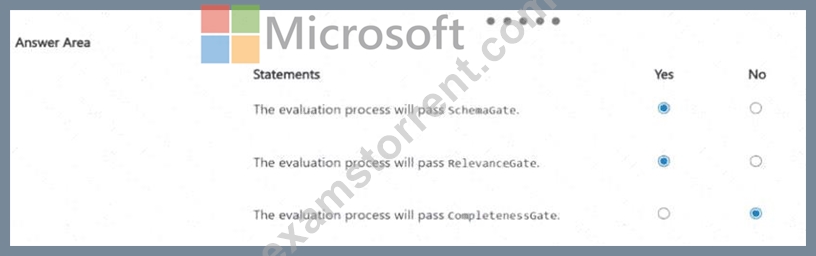
NEW QUESTION # 13
You have a LangGraph multi-agent workflow that uses Azure Cosmos DB as a checkpointer.
You plan to change the pruning rules for the running message list before the next release You need to implement evaluations tor memory. The solution must meet the following requirements:
* Verify that claim-related state values remain correct at transition points.
* Verify that conversation context is preserved after an interruption.
* Identify the source of any loss of continuity during a run
Which three actions should you perform Each correct answer presents part of the solution NOTE: Each correct selection is worth one point.
Answer: D,E,F
Explanation:
Memory evaluation must verify persistence across interruption, correctness of checkpointed state, and enough telemetry to locate where continuity was lost. Running a scripted multi-turn case with one stable `thread_id` before and after a restart directly tests whether the Cosmos-backed LangGraph checkpointer restores the same conversation/workflow. Comparing persisted checkpoint documents with expected state values at each handoff verifies that claim-related state has not been corrupted by the new pruning rules. Correlating the evaluation run with trace spans then provides the diagnostic path to identify which agent transition or state- management operation caused a failure. Changing the thread ID each turn would intentionally create separate state scopes, and removing durable artifacts would defeat the persistence test. Tool-call arguments alone do not prove workflow-memory continuity. Therefore D, E, and F are the complementary actions required. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Azure Cosmos DB integrations for LangGraph and agent state
NEW QUESTION # 14
You have a Microsoft Foundry ticket-triage solution that uses connected agents. Each subagent prompt includes instructions for allowed tools and a JSON handoff.
You need to add automated prompt evaluations. The solution must identify changes that cause the subagents to do the following:
* Skip mandated evidence gathering.
* Return payloads that downstream agents cannot process.
* Handle work outside their assigned responsibilities.
How should you configure the evaluation suite? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.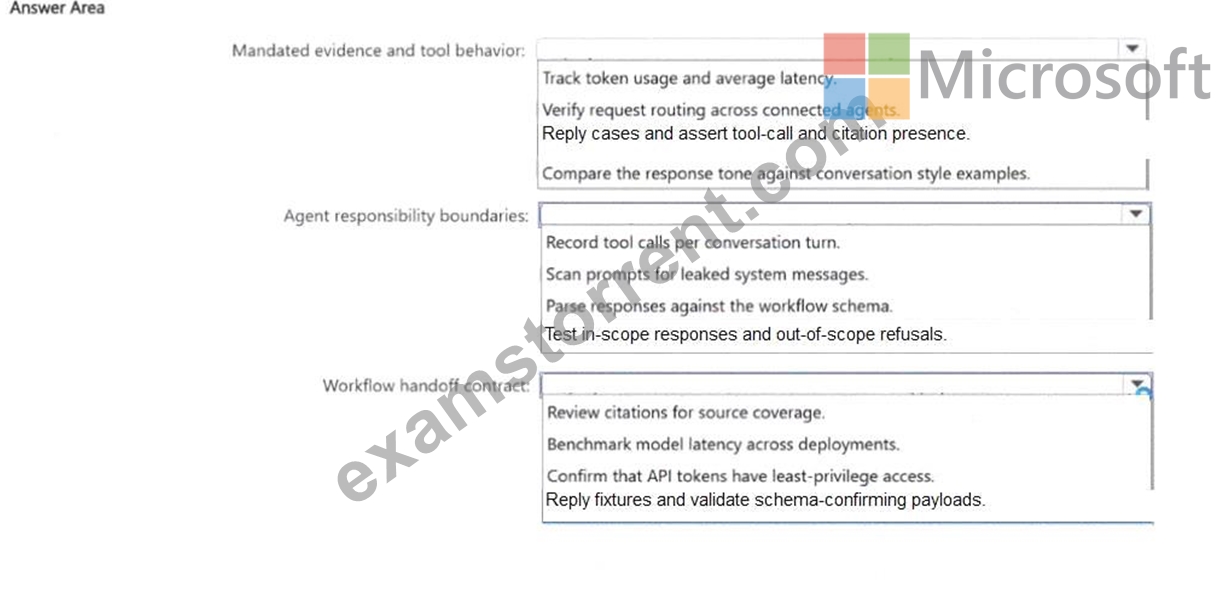
Answer:
Explanation: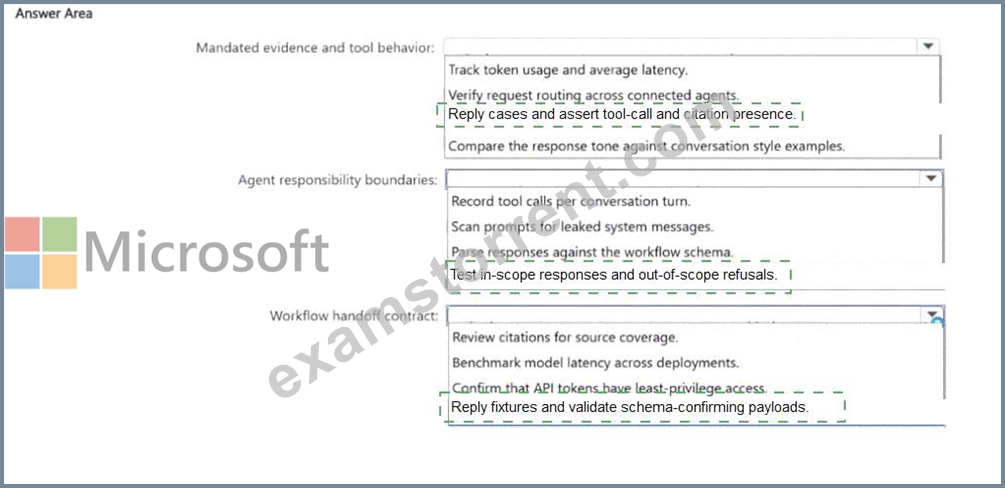
Explanation:
Mandated evidence/tool behavior: Replay cases and assert tool-call and citation presence; Agent responsibility boundaries: Test in-scope responses and out-of-scope refusals; Workflow handoff contract: Replay fixtures and validate schema-conforming payloads.
The three regressions target different interfaces and should be evaluated with tests that directly observe those interfaces. Required evidence gathering is a process behavior, so replayed cases should assert that mandated tool calls and citations occur. Responsibility boundaries are best tested with both positive and negative prompts: in-scope cases must be handled, while out-of-scope work should be refused or redirected. The JSON handoff is an interface contract, so replay fixtures should be validated against the expected schema to catch missing fields, renamed properties, and type changes before downstream agents fail. Microsoft Foundry ' s agent evaluators and evaluation datasets support process-level tool checks, task-adherence checks, and structured regression testing. The supplied mappings therefore correctly align each evaluation technique with the failure it is intended to detect. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - built-in evaluators and evaluation datasets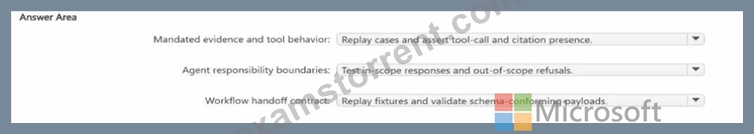
NEW QUESTION # 15
......
Tech firms award high-paying job contracts to Designing and Implementing Multi-Agent AI Solutions (AI-500) certification holders. Every year many aspirants appear in the AI-500 test of the certification, but few of them cannot crack it because of not finding reliable Designing and Implementing Multi-Agent AI Solutions prep materials. So, you must prepare with real exam questions to pass the certification exam. If you don't rely on actual exam questions, you will fail and loss time and money.
AI-500 Latest Test Fee: https://www.examstorrent.com/AI-500-exam-dumps-torrent.html