BONUS!!! Download part of ITExamDownload Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=1hCPh56zsXrUOrgf8rLaIC6X27S6X8ZcR
Having Databricks-Generative-AI-Engineer-Associate training materials of ITExamDownload is equal to have success. If you buy our Databricks-Generative-AI-Engineer-Associate exam dumps, we will offer one year-update service. The passing rate of Databricks-Generative-AI-Engineer-Associate test of ITExamDownload is 100%, if the Databricks-Generative-AI-Engineer-Associate VCE Dumps and training materials have any problems or you fail the Databricks-Generative-AI-Engineer-Associate exam with our Databricks-Generative-AI-Engineer-Associate braindumps, we will refund fully.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Certification Databricks-Generative-AI-Engineer-Associate Exam Cost <<
This is a gainful opportunity to choose Databricks-Generative-AI-Engineer-Associate actual exam from our company. They are saleable offerings from our responsible company who dedicated in this line over ten years which helps customers with desirable outcomes with the help of our Databricks-Generative-AI-Engineer-Associate Study Guide. Up to now, there are three versions of Databricks-Generative-AI-Engineer-Associate exam materials for your reference. They are PDF, software and app versions. And we have free demos for you to download before you decide to purchase.
NEW QUESTION # 45
A generative AI engineer is deploying an AI agent authored with MLflow's ChatAgent interface for a retail company ' s customer support system on Databricks. The agent must handle thousands of inquiries daily, and the engineer needs to track its performance and quality in real-time to ensure it meets service-level agreements. Which metrics are automatically captured by default and made available for monitoring when the agent is deployed using the Mosaic AI Agent Framework?
Answer: A
Explanation:
When deploying an agent via the Mosaic AI Agent Framework (which leverages Databricks Model Serving), operational metrics are captured automatically by default. These include system-level telemetry such as the number of requests per second (volume), the time taken for the model to respond (latency), and the rate of 4xx
/5xx HTTP errors. These are essential for monitoring Service Level Agreements (SLAs). However, Quality metrics (B), such as correctness, groundedness, or adherence to custom guidelines, cannot be determined " automatically " by the serving infrastructure because they require either human feedback or an LLM-as-a- judge evaluation (using Databricks Agent Evaluation). While Databricks makes it easy to generate quality metrics using the mlflow.evaluate API or the inference table, they are not " default operational metrics " that appear without additional evaluation configuration.
NEW QUESTION # 46
When developing an LLM application, it's crucial to ensure that the data used for training the model complies with licensing requirements to avoid legal risks.
Which action is NOT appropriate to avoid legal risks?
Answer: C
Explanation:
* Problem Context : When using data to train a model, it's essential to ensure compliance with licensing to avoid legal risks. Legal issues can arise from using data without permission, especially when it comes from third-party sources.
* Explanation of Options :
* Option A : Reaching out to data curators before using the data is an appropriate action. This allows you to ensure you have permission or understand the licensing terms before starting to use the data in your model.
* Option B : Using original data that you personally created is always a safe option. Since you have full ownership over the data, there are no legal risks, as you control the licensing.
* Option C : Using data that is explicitly labeled with an open license and adhering to the license terms is a correct and recommended approach. This ensures compliance with legal requirements.
* Option D : Reaching out to the data curators after you have already started using the trained model is not appropriate . If you've already used the data without understanding its licensing terms, you may have already violated the terms of use, which could lead to legal complications.
It's essential to clarify the licensing terms before using the data, not after.
Thus, Option D is not appropriate because it could expose you to legal risks by using the data without first obtaining the proper licensing permissions.
NEW QUESTION # 47
A Generative Al Engineer is building a system which will answer questions on latest stock news articles.
Which will NOT help with ensuring the outputs are relevant to financial news?
Answer: A
Explanation:
In the context of ensuring that outputs are relevant to financial news, increasing compute power (option B) does not directly improve the relevance of the LLM-generated outputs. Here's why:
Compute Power and Relevancy:
Increasing compute power can help the model process inputs faster, but it does not inherently improve the relevance of the answers. Relevancy depends on the data sources, the retrieval method, and the filtering mechanisms in place, not on how quickly the model processes the query.
What Actually Helps with Relevance:
Other methods, like content filtering, guardrails, or manual review, can directly impact the relevance of the model's responses by ensuring the model focuses on pertinent financial content. These methods help tailor the LLM's responses to the financial domain and avoid irrelevant or harmful outputs.
Why Other Options Are More Relevant:
A (Comprehensive Guardrail Framework): This will ensure that the model avoids generating content that is irrelevant or inappropriate in the finance sector.
C (Profanity Filter): While not directly related to financial relevancy, ensuring the output is clean and professional is still important in maintaining the quality of responses.
D (Manual Review): Incorporating human oversight to catch and correct issues with the LLM's output ensures the final answers are aligned with financial content expectations.
Thus, increasing compute power does not help with ensuring the outputs are more relevant to financial news, making option B the correct answer.
NEW QUESTION # 48
A company has a typical RAG-enabled, customer-facing chatbot on its website.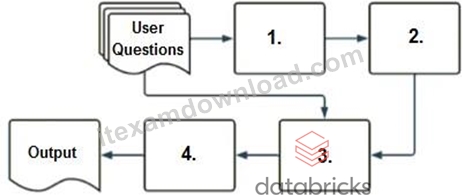
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: A
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
Embedding Model (1):
The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
Vector Search (2):
The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
Context-Augmented Prompt (3):
The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
Response-Generating LLM (4):
Finally, the context-augmented prompt is fed into a response-generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence is embedding model, vector search, context-augmented prompt, response-generating LLM, which is option A.
NEW QUESTION # 49
A Generative AI Engineer is deploying an agent using Mosaic AI Model Serving. The agent needs to access various Databricks resources, including Vector Search, Databricks SQL, and Functions. They need to find the easiest and best-practice way to authenticate the deployed agent to access these resources.
What approach should they choose?
Answer: C
Explanation:
For agents deployed through Model Serving, Databricks supports automatic authentication passthrough for declared resources. The engineer records the agent's dependencies through the resources parameter when logging the model. During deployment, Databricks checks the deployer's access, creates a service principal for the agent model version, grants the required resource access, and supplies short-lived credentials.
Credential rotation is handled automatically. Supported dependencies include Vector Search indexes, SQL warehouses, and Unity Catalog functions. This approach avoids embedding secrets in source code or recording authentication tokens as model artifacts. Permissions on the serving endpoint govern access to that endpoint; they do not independently establish all downstream resource permissions. All required dependencies, including relevant underlying resources, must be declared correctly. Databricks documentation
NEW QUESTION # 50
......
The authoritative, efficient, and thoughtful service of Databricks-Generative-AI-Engineer-Associate learning question will give you the best user experience, and you can also get what you want with our study materials. I hope our study materials can accompany you to pursue your dreams. If you can choose Databricks-Generative-AI-Engineer-Associate test guide, we will be very happy. We look forward to meeting you. You can choose your favorite our study materials version according to your feelings. When you use Databricks-Generative-AI-Engineer-Associate Test Guide, you can also get our services at any time. We will try our best to solve your problems for you. I believe that you will be more inclined to choose a good service product, such as Databricks-Generative-AI-Engineer-Associate learning question. After all, everyone wants to be treated warmly and kindly, and hope to learn in a more pleasant mood.
Databricks-Generative-AI-Engineer-Associate Test Questions Fee: https://www.itexamdownload.com/Databricks-Generative-AI-Engineer-Associate-valid-questions.html
What's more, part of that ITExamDownload Databricks-Generative-AI-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1hCPh56zsXrUOrgf8rLaIC6X27S6X8ZcR