さらに、PassTest AB-100ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1MaeZdmUYIhxagRskE9Spg5EZh1mM6tcz
ユーザーのプライバシー保護は、インターネット時代の永遠の問題です。多くの違法ウェブサイトはユーザーのプライバシーを第三者に販売するため、多くの購入者は奇妙なウェブサイトを信じることを嫌います。ただし、AB-100学習エンジンAB-100を購入する際に心配する必要はまったくありません。弊社の評判を損なうため、ユーザーの情報を決して販売しないことを保証します。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design AI-powered business solutions | 25–30% | - Design AI and agents
|
| Topic 2: Plan AI-powered business solutions | 25–30% | - Design overall AI strategy
|
| Topic 3: Deploy AI-powered business solutions | 40–45% | - Manage testing and validation
|
AB-100トレーニング資料のPDFバージョンは読みやすく、覚えやすく、印刷リクエストをサポートしているため、紙で印刷して練習することができます。練習資料のソフトウェアバージョンは、シミュレーションテストシステムをサポートし、セットアップの時間を与えることには制限がありません。
質問 # 63
A company has multiple AI models that support generation of sales transactions.
Each release of the models must be reviewed by a security and compliance team before being deployed to the production environment. The security and compliance team must have access to prior versions to properly determine potential exposures introduced.
You need to recommend a solution to evaluate the impact of each deployment to production. The solution must enhance business continuity.
What should you recommend?
正解:C
解説:
Comprehensive and Detailed Explanation From Agentic AI Business Solutions Topics:
The correct answer is C. Implement version control for all the AI system components .
This question is not only about model approval. It is about creating a deployment process that allows the organization to:
* review every release before production
* compare current and prior versions
* evaluate the impact of changes
* improve business continuity if a deployment introduces risk
That makes version control for all AI system components the strongest answer.
Why C is correct
The requirement says the security and compliance team must have access to prior versions to determine exposures introduced by each release. That means the organization must be able to track, compare, and potentially roll back not just the model itself, but the broader AI solution over time.
In real enterprise AI deployments, "AI system components" usually include:
* models
* prompts
* orchestration logic
* configuration files
* policies
* connectors
* inference code
* evaluation assets
* deployment definitions
If only the model is versioned, the team may miss exposure introduced by surrounding components. For example:
* a prompt change could create unsafe outputs
* a policy/configuration change could expose sensitive data
* an orchestration update could alter transaction behavior
* a connector change could affect compliance boundaries
That is why full AI system version control is the best answer. It gives security and compliance teams complete visibility into what changed across releases.
It also enhances business continuity because version control supports:
* rollback to known-good versions
* change auditing
* release comparison
* traceability
* controlled recovery from faulty deployments
From an agentic AI business solutions perspective, this is the most robust governance pattern because AI outcomes are rarely determined by the model alone. They are determined by the entire solution stack.
Why the other options are less appropriate
A). Create a central model registry that uses version history
A model registry is useful, and version history helps, but this option is too narrow. The question asks about evaluating the impact of each deployment and enhancing business continuity. In enterprise AI systems, impact is often caused by more than just the model artifact. A model registry does not necessarily capture all surrounding components that affect production behavior.
B). Establish a promotion process by using a quality gate
A quality gate is valuable for approval workflows, but it does not by itself satisfy the need for deep access to prior versions across the system. It controls promotion, but it does not fully provide historical traceability and rollback coverage for all AI system components.
D). Track model retirement schedules to prevent service disruptions
This may support lifecycle planning, but it does not address the core requirement of comparing releases, reviewing prior versions, and evaluating exposure introduced by each deployment.
Expert reasoning
This question combines three ideas:
* security/compliance review
* access to prior versions
* business continuity
When those appear together, the strongest answer is typically the one that provides end-to-end traceability and rollback across the whole solution , not just a single artifact.
That is why version control for all AI system components is the best recommendation.
質問 # 64
A startup wants to build a customizable, agent-based workflow that can integrate with their internal APIs, retrieve contextual data from various sources, and run complex business logic autonomously. The team has moderate engineering skills but explicitly wants to avoid the overhead of managing underlying infrastructure. Which Microsoft AI service model best fits this requirement for building and deploying their agent-based solution?
正解:D
質問 # 65
You need to recommend a Microsoft Power Platform business solution that consolidates data from multiple internal and external data sources. The solution must meet the following requirements:
Provide the data as a centralized source for multiple AI systems, including Microsoft Copilot Studio agents, Dynamics 365 applications, and external AI models.
Support built-in data classification and protection policies.
Provide data for grounding and analytics.
What should you include in the recommendation?
正解:C
質問 # 66
A company deploys a Microsoft Copilot Studio agent that integrates with a Microsoft Power Automate desktop flow.
You need to recommend a testing solution that meets the following requirements:
Test cases must validate the most recent changes to the agent before the agent is released.
The flow must be validated as part of the agent ' s orchestration.
What should you recommend for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.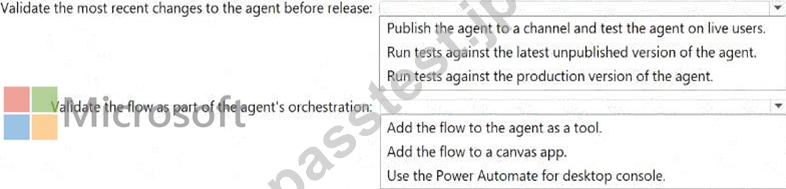
正解:
解説: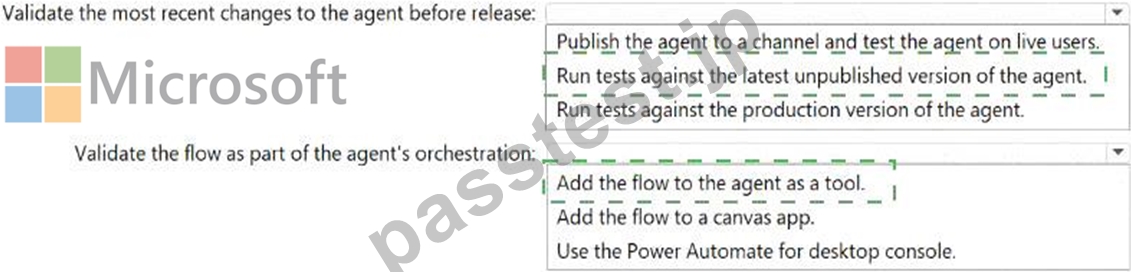
Explanation:
Validate most recent changes # Run tests against the latest unpublished version of the agent; Validate the flow as part of orchestration # Add the flow to the agent as a tool Why the first selection is correct The requirement says the company must validate the most recent changes to the agent before the agent is released. That means testing must happen on the newest working version that has not yet been published to production.
So the correct recommendation is:
Run tests against the latest unpublished version of the agent
This is the safest and most appropriate pre-release testing pattern because it allows the team to:
verify recent changes before users see them
catch regressions early
validate orchestration logic in a controlled state
reduce production risk
From an AI business solutions perspective, pre-release testing is critical for Copilot agents because even small changes in prompts, tools, orchestration, or data connections can affect:
response quality
workflow behavior
escalation paths
compliance behavior
user trust
Testing unpublished changes ensures that governance and quality assurance happen before release, not after deployment.
Why the second selection is correct
The question also requires that the Power Automate desktop flow be validated as part of the agent ' s orchestration.
That means the flow must participate directly in the agent's runtime action path. The correct way to do that is:
Add the flow to the agent as a tool
When a flow is added as a tool, the agent can invoke it during its orchestration. This allows test cases to validate not only the conversational layer, but also the actual execution of the flow inside the end-to-end agent behavior.
From an agentic AI design perspective, tools are how agents connect reasoning with action. If the flow is meant to be part of orchestration, it must be exposed to the agent in a way that allows the agent to call it during task execution.
That is the correct enterprise pattern for validating integrated behavior.
質問 # 67
A company has a Microsoft Copilot Studio prompt-and-response agent.
You need to ensure that the agent meets the following requirements:
Provides effective and relevant responses
Provides conversational outcomes
Which metric should you use for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.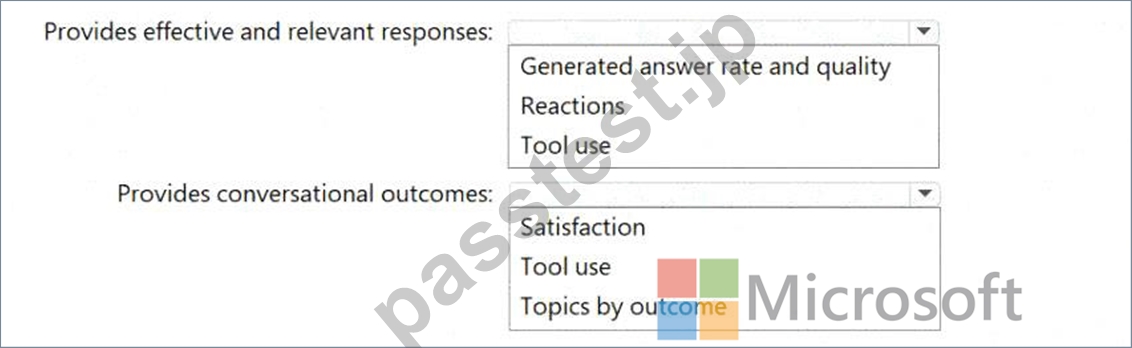
正解:
解説: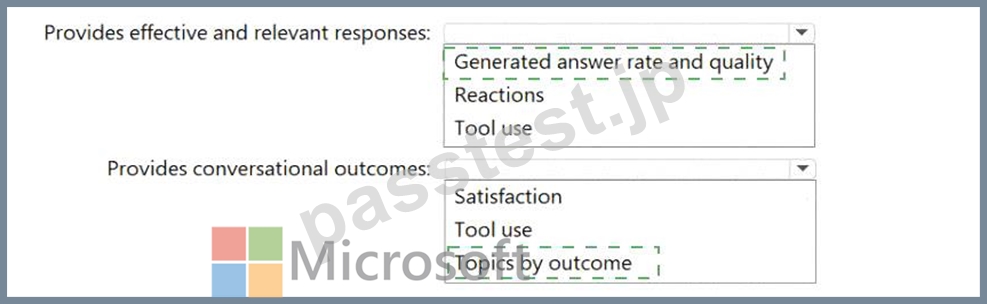
Explanation:
Provides effective and relevant responses # Generated answer rate and quality Provides conversational outcomes # Topics by outcome Why "Generated answer rate and quality" is correct The requirement says the agent must provide effective and relevant responses. In Microsoft Copilot Studio, the metric that most directly evaluates whether the agent is successfully generating useful answers is Generated answer rate and quality.
This metric helps assess whether the prompt-and-response agent is:
returning answers consistently
producing responses that are useful
generating content of acceptable quality
handling user requests with enough relevance
From an AI business solutions perspective, response effectiveness is not just about whether the agent says something. It is about whether the generated output is meaningful, accurate enough for the scenario, and valuable to the user. That is exactly what generated answer rate and quality is designed to measure.
This metric is especially important in prompt-and-response solutions because these agents depend heavily on the quality of generated outputs rather than only predefined topic flows.
Why "Topics by outcome" is correct
The second requirement says the agent must provide conversational outcomes. The best metric for understanding whether conversations are reaching meaningful end states is Topics by outcome.
This metric helps evaluate what happens to conversations, such as whether they:
are resolved successfully
escalate
fail
abandon
complete a desired path
In enterprise AI and conversational business solutions, outcomes matter because stakeholders want to know whether the agent is actually driving the intended business result, not just generating text. A conversation can sound good but still fail operationally. Topics by outcome reveals whether the conversation reached a useful business conclusion.
For example, in a support or business-process scenario, leadership often wants to know:
how many conversations were resolved
how many required escalation
which flows underperform
where users get stuck
That is outcome measurement, and this metric aligns directly with that requirement.
Why the other metrics are not the best fit
Reactions
Reactions can provide feedback signals such as likes or dislikes, but they are not the strongest primary metric for determining whether responses are effective and relevant at a system level.
Satisfaction
Satisfaction is useful as a user sentiment metric, but it does not directly measure conversational outcomes. A user may be satisfied with tone but still not complete the intended business process.
Tool use
Tool use measures whether tools or actions are invoked, but it does not directly tell you whether responses are effective or whether conversations ended in successful outcomes.
質問 # 68
......
PassTestはMicrosoftのAB-100認定試験に受かりたい各受験生に明確かつ顕著なソリューションを提供しました。当社はMicrosoftのAB-100認定試験の詳しい問題と解答を提供します。当社のIT専門家が最も経験と資格があるプロな人々で、我々が提供したテストの問題と解答は実際の認定試験と殆ど同じです。これは本当に素晴らしいことです。それにもっと大切なのは、PassTestのサイトは世界的でAB-100試験トレーニングによっての試験合格率が一番高いです。
AB-100模擬資料: https://www.passtest.jp/Microsoft/AB-100-shiken.html
さらに、PassTest AB-100ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1MaeZdmUYIhxagRskE9Spg5EZh1mM6tcz