クライアントは、支払いが完了するとすぐに、当社の製品をダウンロードし、DP-800学習教材を使用できます。私たちのシステムは、支払いが成功してから5〜10分後にDP-800学習準備をメール形式でクライアントに送信します。メールはリンクを提供します。クライアントのみがリンクをクリックすると、すぐにソフトウェアにログインしてDP-800ガイド資料を学習できます。クライアントがDP-800トレーニングクイズを購入する限り、すぐにFast2test製品を使用して時間を節約できます。
| Section | Objectives |
|---|---|
| Topic 1: Design and implement data solutions | - Design database solutions using Azure data services - Implement data storage and data processing solutions |
| Topic 2: Integrate AI capabilities with database systems | - Implement AI-assisted data processing - Use Azure AI services with database workloads |
| Topic 3: Monitor, troubleshoot, and maintain solutions | - Troubleshooting data pipeline issues - Monitoring database health and performance |
| Topic 4: Develop and manage database solutions | - Optimize performance and scalability - Ensure security and compliance of data solutions |
我々社はMicrosoft DP-800問題集をリリースされる以来、たくさんの好評を博しました。試験に合格したお客様は「DP-800問題集のオンライン版を利用して、模擬試験を繰り返して受けました。無事試験に合格しました。Fast2testから大変助かりました。」と感謝します。あなたの支持こそ我々は最も高品質のMicrosoft DP-800問題集を開発して努力します。
質問 # 37
Drag and Drop Question
You have an Azure SQL database named SalesDB that has Query Store enabled. SalesDB supports an AI-driven product search API.
Users report that the latency of the API increased immediately after the API was deployed and remains high.
You need to identify whether the latency increase was caused by an execution plan regression and, if so, decide which corrective action will restore a previous plan. The solution must prevent any changes to the API code.
What should you use? To answer, drag the appropriate tools to the correct step. Each tool may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.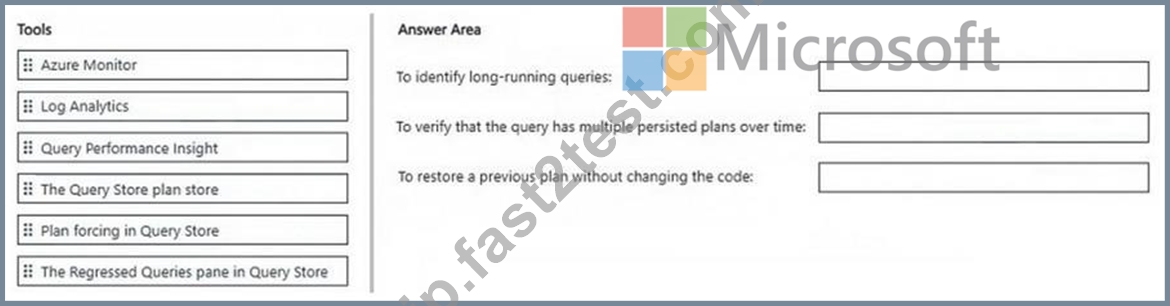
正解:
解説: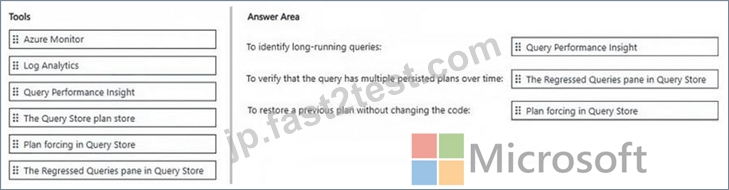
質問 # 38
Vou have an Azure SQL database named SalesDB that contains a table named dbo. Articles, dbo.Articles contains two million articles with embeddmgs. The articles are updated frequently throughout the day.
You query the embeddings by using VECTOR_SEARQi
Users report that semantic search results do NOT reflect the updates until the following day.
Vou need to ensure that the embeddings are updated whenever the articles change. The solution must minimize CPU usage on SalesDB Which embedding maintenance method should you implement?
正解:C
解説:
The correct answer is B because the problem is not the vector search operator itself. The problem is that embeddings are becoming stale when article content changes . Microsoft documents that change data capture (CDC) tracks insert, update, and delete operations on source tables, which makes it the right mechanism to identify only the rows that changed.
This also best satisfies the requirement to minimize CPU usage on SalesDB . With CDC, the database only records the row changes, and the embedding regeneration work can be moved to an external process such as an Azure Functions app. That avoids running embedding generation inline inside the database for every update and avoids repeatedly recalculating embeddings for unchanged rows. In contrast, an hourly full-table regeneration would be extremely wasteful on a table with two million frequently updated articles, and a trigger that calls embedding generation per row would push expensive AI work into the transactional path of the database.
Option A is incorrect because changing from VECTOR_SEARCH to VECTOR_DISTANCE does not regenerate embeddings; it only changes the retrieval method. Microsoft states that VECTOR_SEARCH is the ANN search function, while VECTOR_DISTANCE performs exact distance calculation, so neither option addresses stale embedding data.
So the right design is:
* use CDC to detect only changed articles,
* process those changes outside the database,
* regenerate embeddings only for changed rows,
* write back the refreshed embeddings for current semantic search results.
質問 # 39
Hotspot Question
You have an Azure SQL database that contains a table named stores. stores contains a column named description and a vector column named embedding.
You need to implement a hybrid search query that meets the following requirements:
- Uses full-text search on description for the keyword portion
- Returns the top 20 results based on a combined score that uses a
weighted formula of 60% vector distance and 40% full-text rank
How should you configure the query components? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.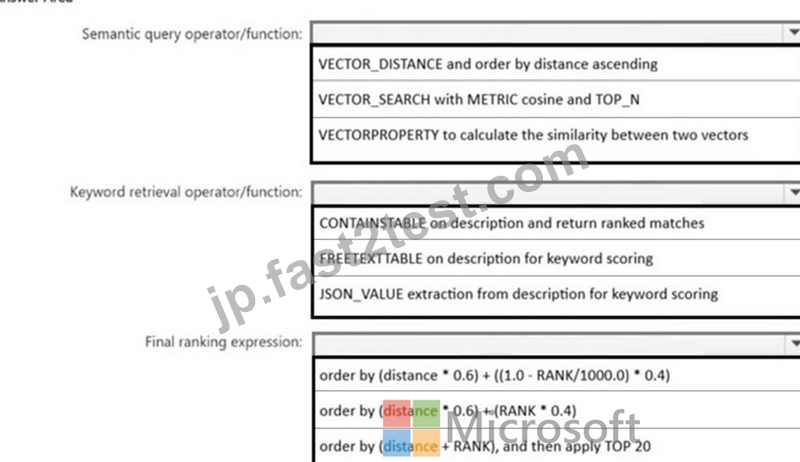
正解:
解説: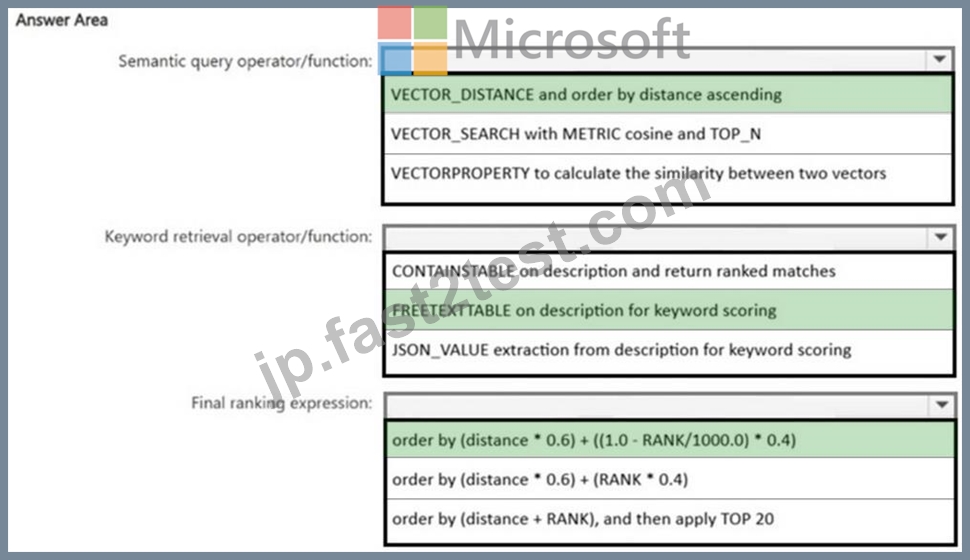
質問 # 40
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders. dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.Orders.
Solution: Identify the partition scheme for the oldest month, and then run the following Transact-SQL statement:
SQL
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME {partition_scheme_name};
Does this meet the goal?
正解:A
質問 # 41
You are creating a table that will store customer profiles.
You have the following Transact-SQL code.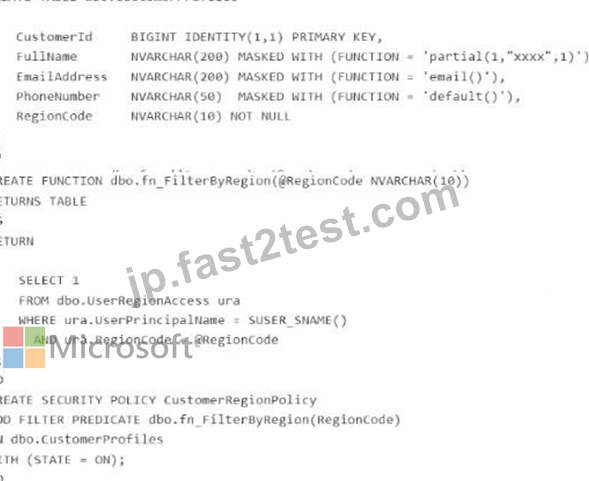
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection Is worth one point.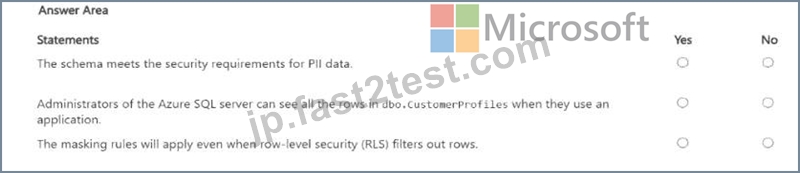
正解:
解説: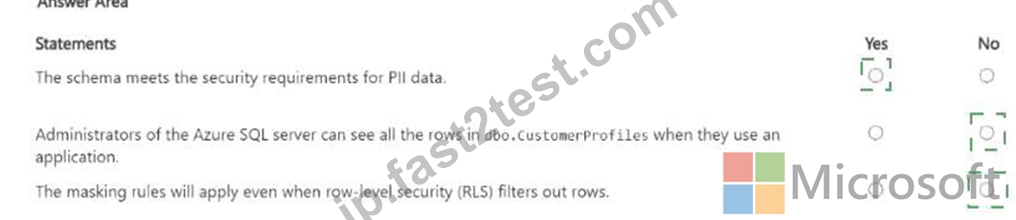
Explanation:
* The schema meets the security requirements for PII data. # Yes
* Administrators of the Azure SQL server can see all the rows in dbo.CustomerProfiles when they use an application. # No
* The masking rules will apply even when row-level security (RLS) filters out rows. # No The first statement is Yes because the design combines two relevant SQL security controls for personally identifiable information: Dynamic Data Masking (DDM) on sensitive columns such as FullName, EmailAddress, and PhoneNumber, and Row-Level Security (RLS) to restrict which rows a user can access based on RegionCode. Microsoft documents that DDM limits sensitive data exposure for nonprivileged users
, while RLS restricts row access according to the user executing the query. Together, these are valid and appropriate controls for protecting PII in Azure SQL Database.
The second statement is No . Administrative users can view unmasked data because administrative roles effectively have CONTROL, which includes UNMASK. However, that does not mean they automatically see all rows through the application query path defined by the RLS policy. The security policy filters rows based on SUSER_SNAME() and matching RegionCode, so row visibility is governed by the predicate unless the policy is altered or bypassed administratively. DDM and RLS solve different problems: DDM affects how returned values are shown, while RLS affects which rows are returned at all.
The third statement is No because masking only applies to data that is actually returned in the query result set.
Microsoft describes DDM as hiding sensitive data in the result set of a query . If RLS filters a row out, that row is not returned, so there is nothing left for masking to act on. In other words, RLS eliminates inaccessible rows first from the user's perspective, and DDM masks sensitive column values only on rows the user is allowed to see.
質問 # 42
......
信頼できるプロフェッショナルな試験DP-800学習ガイド教材を購入する場合は、正しいWebサイトにアクセスしてください。 Fast2testは、専門的な実際のテスト問題の最新バージョンのみを提供します。お客様に安心してお買い物をお楽しみいただけます。私たちのDP-800試験問題の高い合格率はこの分野で有名です。そのため、何年も早く成長し、多くの古い顧客を抱えることができます。 DP-800試験の質問を選択すると、DP-800試験の準備に時間を費やす必要がなくなり、考えすぎになりません。
DP-800関連問題資料: https://jp.fast2test.com/DP-800-premium-file.html