DOWNLOAD the newest DumpsTests AI-103 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1K8iJfd33_t7c96GaiIwikWFd2jaNu7MF
As we know, everyone has opportunities to achieve their own value and life dream. And our AI-103 can help them achieve all of these more easily and leisurely. Our AI-103 exam materials are pleased to serve you as such an exam tool. With over a decade’s endeavor, our AI-103 Practice Guide successfully become the most reliable products in the industry. There is a great deal of advantages of our AI-103 exam questions you can spare some time to get to know.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
| Topic 2: Implement agentic solutions | 20-25% | - Build AI agents
|
| Topic 3: Plan and manage Azure AI solutions | 25-30% | - Manage AI solution lifecycle
|
| Topic 4: Implement generative AI solutions | 25-30% | - Optimize and evaluate models
|
| Topic 5: Implement computer vision solutions | 10-15% | - Analyze visual content
|
>> New Microsoft AI-103 Exam Format <<
If you are preparing for the Developing AI Apps and Agents on Azure (AI-103) exam dumps our AI-103 Questions help you to get high scores in your Microsoft AI-103 exam. Test your knowledge of the Developing AI Apps and Agents on Azure exam dumps with DumpsTests Microsoft AI-103 Practice Questions. The software is designed to help with AI-103 exam dumps preparation.
NEW QUESTION # 76
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have a multimodal AI generative model that accepts image uploads and uses extracted image text to generate responses.
You discover that users can upload unsafe images and embed hidden instructions into images to manipulate the model.
You need to implement controls to mitigate the risk.
Solution: You configure a prompt shield for user prompts.
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You configure a prompt shield for documents.
Prompt Shield for Documents: Highly Effective (Critical Defense)
How it helps: This shield specifically scans untrusted, third-party data inputs (like external documents or text extracted from uploaded images).
Mechanism: It evaluates the extracted image text before it is sent to the LLM to identify hidden jail
* You configure a prompt shield for user prompts.
Prompt Shield for User Prompts: Partially Effective (Defense in Depth)
How it helps: This shield targets direct jailbreak attempts written manually by the user in the text prompt field accompanying the upload.
Mechanism: It prevents the user from typing supporting instructions that prime the model to execute the hidden instructions found within the image.
* You configure image moderation to block unsafe content before processing the images.
Implementing rigorous image moderation is one of the most effective ways to secure multimodal AI systems against these threats. Moderation acts as a necessary gatekeeper, preventing malicious inputs from ever reaching the generative model.
Incorrect:
* You configure protected material detection.
Protected Material Detection: Ineffective for this Threat
Why it does not help: This feature is designed to scan model outputs to prevent the generation of copyrighted text, proprietary source code, or licensed imagery.
Limitation: It does not scan inputs for adversarial instructions and will not prevent a user from manipulating the model's logic.
Reference:
https://www.upgrad.com/blog/what-is-multimodal-ai/
https://learn.microsoft.com/en-us/azure/ai-services/content-safety/concepts/jailbreak-detection
NEW QUESTION # 77
You have a Microsoft Foundry project that contains an agent. The agent uses Azure AI Search for Retrieval Augmented Generation (RAG). You plan to ingest and index PDF product manuals. You need to build a solution that supports semantic similarity matching. The solution must ensure that the agent retrieves relevant data when user questions use different wording than the product manuals.
Answer: C
Explanation:
Use vector search because it performs similarity matching based on semantic meaning rather than requiring literal keyword overlap. During ingestion, the product manuals should be divided into appropriately sized chunks. An embedding model converts each chunk into a numerical vector, which Azure AI Search stores in a vector field. At query time, the user's question is also converted into an embedding, and the service retrieves chunks whose vectors are closest to the query vector. Consequently, wording such as "reset the device to factory settings" can match manual content such as "restore the unit's original configuration," despite minimal lexical overlap. Azure AI Search explicitly defines vector fields as enabling similarity searches over mathematically represented content and supports this retrieval pattern for RAG applications.
Semantic ranking improves the ordering of an existing result set but is not the indexing mechanism that stores embeddings and performs nearest-neighbor similarity matching. Suggesters provide search-as-you-type functionality, while analyzers control tokenization and lexical processing for text fields.
This aligns with the AI-103 Study Guide objectives for implementing RAG, configuring Azure AI Search grounding, generating embeddings, and selecting vector retrieval techniques for agentic solutions.
NEW QUESTION # 78
A legal team must extract clauses and inferred fields from unstructured contracts. One required field is the contract end date, which is not stated explicitly and must be derived from the start date plus the term. The team has no labelled training data. Which tool best fits?
Answer: B
NEW QUESTION # 79
Hotspot Question
You have a Python application that redacts sensitive information before sending prompt text to a language model. The application has the following code: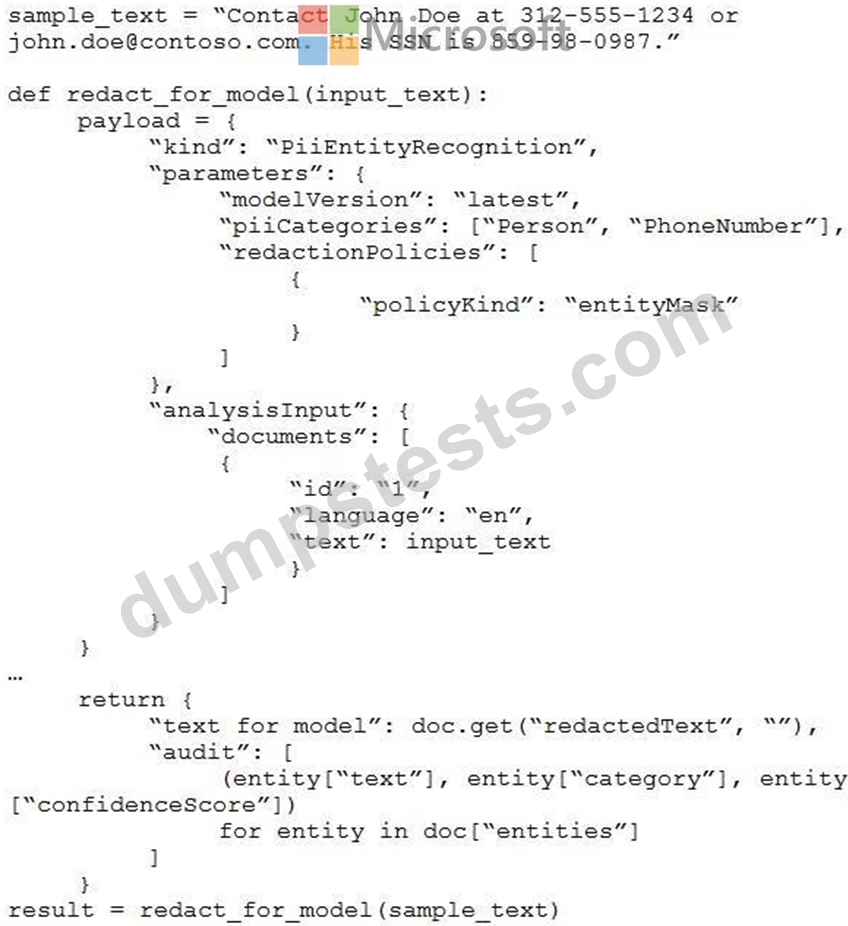
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.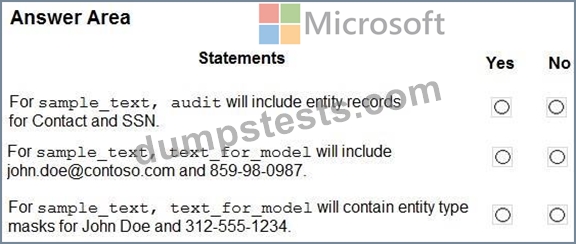
Answer:
Explanation: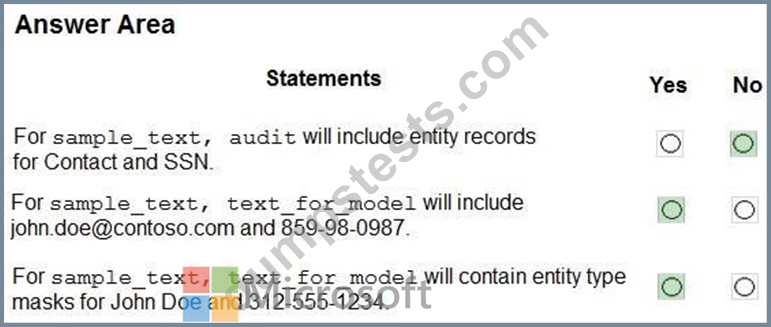
Explanation:
Box 1: No
The audit list will not include entity records for "Contact" and "SSN" because neither word is a target PII entity type defined in the configuration.
The code limits scanning to Person and PhoneNumber via the piiCategories list.
"Contact" Definition: This is a regular English verb/noun, not a person's name or a telephone number.
"SSN" Definition: While "SSN" is a text label that points to sensitive data, it is a descriptor rather than an actual Social Security Number.
Box 2: Yes
For the given sample_text, text_for_model will include both or john.doe@contoso.com and 859-
98-0987 completely unredacted.
The payload explicitly restricts the Personally Identifiable Information (PII) recognition to only two specific categories by setting piiCategories: ["Person", "PhoneNumber"].
Email Address Excluded: Because the Email category is omitted from the configuration list, the service bypasses the email address (john.doe@contoso.com) and leaves it fully intact.
SSN Excluded: Similarly, because the USSSN (or equivalent Social Security Number) category is not specified in the piiCategories array, the SSN (859-98-0987) is completely ignored by the redaction policy and remains visible.
Box 3: Yes
text_for_model will contain entity type masks for "John Doe" and "312-555-1234", but only for those two specific items.
The piiCategories array explicitly requests Person and PhoneNumber.
Applied Redaction: The Azure AI Language service will replace "John Doe" and "312-555-1234" with masks like * or entity labels (depending on exact policy settings).
Skipped Data: The email (john.doe@contoso.com) and the SSN (859-98-0987) will not be redacted because their categories (Email and USSSN) were omitted from your piiCategories list.
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/language-service/personally-identifiable-information/concepts/conversations-entity-categories
NEW QUESTION # 80
You need to recommend a plan to create a customer support agent by using the Microsoft Foundry Agent Service. The agent must meet the following requirements:
* Retain user preferences across multiple conversations.
* Enable users to provide contextual grounding by directly uploading documents during a chat.
Which Foundry capability should you recommend for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.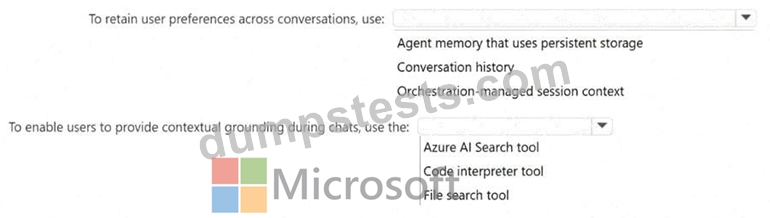
Answer:
Explanation: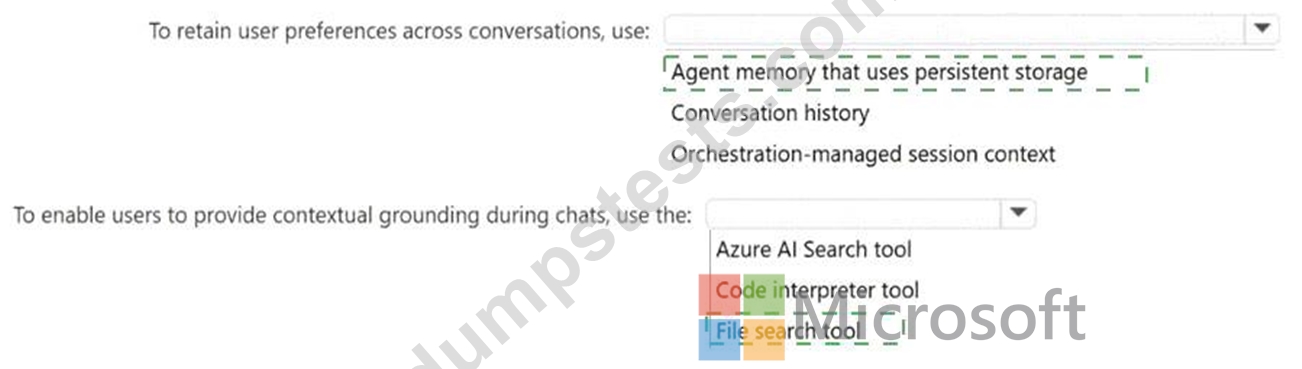
Explanation:
To retain user preferences across conversations, use: Agent memory that uses persistent storage To enable users to provide contextual grounding during chats, use the: file search tool The correct capability for retaining user preferences is agent memory that uses persistent storage .
Microsoft Foundry Agent Service memory is a managed long-term memory capability that enables continuity across sessions, devices, and workflows. It is specifically intended to let agents retain user preferences, maintain relevant historical context, and personalize responses across separate conversations. Memory stores provide the persistent storage layer, and scope can be used to segment memories for secure user-specific experiences.
The correct capability for contextual grounding from user-uploaded documents is the file search tool .
Microsoft describes file search as the tool that enables Foundry agents to search through documents and retrieve relevant information from outside the base model, including proprietary product information and user- provided documents. The file search workflow supports uploading files, creating a vector store, enabling the tool on the agent, and querying those documents through the agent.
Conversation history alone supports continuity within a conversation, but it is not durable preference memory across multiple conversations. An Azure AI Search tool is better for preconfigured enterprise indexes, while file search is the direct document-upload grounding capability. Reference topics: Foundry Agent Service memory, memory stores, File Search tool, vector stores, and grounded agent responses.
NEW QUESTION # 81
......
Developing AI Apps and Agents on Azure exam tests are a high-quality product recognized by hundreds of industry experts. Over the years, AI-103 exam questions have helped tens of thousands of candidates successfully pass professional qualification exams, and help them reach the peak of their career. It can be said that AI-103 test guide is the key to help you open your dream door. We have enough confidence in our products, so we can give a 100% refund guarantee to our customers. AI-103 Exam Questions promise that if you fail to pass the exam successfully after purchasing our product, we are willing to provide you with a 100% full refund.
Reliable AI-103 Exam Topics: https://www.dumpstests.com/AI-103-latest-test-dumps.html
BONUS!!! Download part of DumpsTests AI-103 dumps for free: https://drive.google.com/open?id=1K8iJfd33_t7c96GaiIwikWFd2jaNu7MF