All kinds of exams are changing with dynamic society because the requirements are changing all the time. To keep up with the newest regulations of the Implementing Data Engineering Solutions Using Azure Databricks exam, our experts keep their eyes focusing on it. Expert team not only provides the high quality for the DP-750 Quiz guide consulting, also help users solve problems at the same time, leak fill a vacancy, and finally to deepen the user's impression, to solve the problem of Implementing Data Engineering Solutions Using Azure Databricks test material and no longer make the same mistake.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Topic 2: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 3: Prepare and process data | 30-35% | - Data quality and validation
|
| Topic 4: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
If you buy our DP-750 exam questions, we will offer you high quality products and perfect after service just as in the past. We believe our consummate after-sale service system will make our customers feel the most satisfactory. Our company has designed the perfect after sale service system for these people who buy our DP-750 practice materials. We can always give the most professinal suggestion on our DP-750 learning guide to our customers at the first time for our service are working 24/7 online.
NEW QUESTION # 23
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two catalogs named Catalog1 and Catalog2.
An external application uses a service principal named SP1 to connect to a SQL warehouse.
You need to ensure that SP1 can query the data in Catalog1 and Catalog2. The solution must follow the principle of least privilege.
Which permissions should you grant to SP1 for the catalogs?
Answer: A
Explanation:
To ensure a service principal can query data in two specific catalogs while maintaining the principle of least privilege, you must assign the following permissions for each catalog:
Unified Catalog Permissions
USE CATALOG on the specific catalog: This is a prerequisite that allows the principal to see the catalog and its child objects.
USE SCHEMA on the schemas containing the data: This allows the principal to interact with the schemas within that catalog.
SELECT on the specific tables or views: This provides the actual read access required to query the data.
Reference:
https://learn.microsoft.com/en-us/purview/data-governance-roles-permissions
NEW QUESTION # 24
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1. Table1 stores customer data.
You need to implement a data retention solution that meets the following requirements:
Deleted data must be retained for 30 days to support audits.
Deleted data that is older than 30 days must be removed permanently.
The solution must minimize administrative effort.
Which two properties should you configure? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
The correct answers are B and D. Delta Lake's data retention behaviour is controlled by two distinct properties that work together:
delta.deletedFileRetentionDuration governs how long physically deleted data files are kept before VACUUM can remove them. Setting this to 30 days ensures deleted records remain on storage for the full audit window.
delta.logRetentionDuration controls how long the transaction log is retained. Time-travel queries (SELECT ...
VERSION AS OF or TIMESTAMP AS OF) rely on the log to reconstruct historical table states - without 30 days of log, you can't query 30-day-old snapshots even if the data files are still there.
Both properties need to be set to 30 days to fully honour the requirement. Option A (delta.timeUntilArchived) doesn't exist in Delta Lake. Option C (autoCompact) manages file sizing, not retention. Option E (enableDeletionVectors) speeds up deletes but has no bearing on how long data is kept.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/history#configure-data-retention
NEW QUESTION # 25
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: A
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don ' t prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely. Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 26
You have an Azure Databricks workspace that contains a Delta table named Customer.
A job named Job1 performs frequent upserts into Customer.
You discover that Job1 has created many small Parquet files in Customer, and the small files are degrading query performance.
You need to improve query performance for the current data already stored in Customer. The solution must not affect the travel for the Customer table.
What should you do?
Answer: C
Explanation:
The OPTIMIZE command performs bin-packing compaction, combining the Customer table's existing small Parquet files into fewer, larger files. This reduces file-open overhead and improves data-skipping efficiency without changing the logical table contents. Enabling optimized writes affects future write operations but does not compact the small files already stored. VACUUM removes unreferenced data files that are older than the configured retention threshold; it does not reorganize active small files and can restrict time-travel availability. Reducing delta.deletedFileRetentionDuration changes how long obsolete files remain available and can directly reduce the time-travel window, contrary to the requirement. OPTIMIZE is therefore the correct operation for improving the physical layout of current data while preserving Delta table semantics and history. Microsoft Learn
NEW QUESTION # 27
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.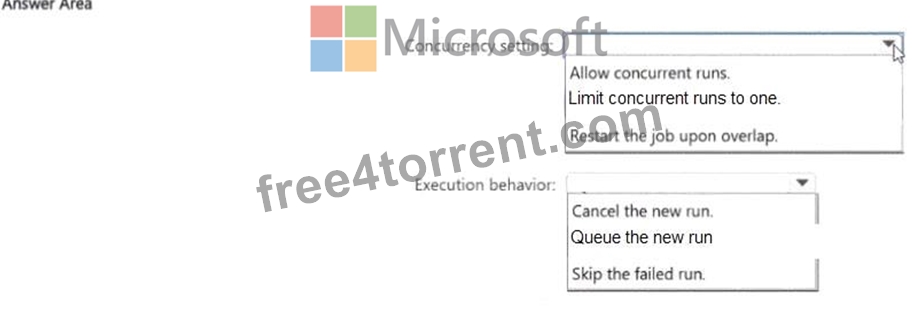
Answer:
Explanation: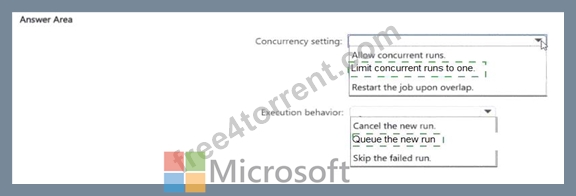
Explanation:
Two settings address the overlapping-run problem:
Concurrent Runs policy set to 'Skip' (or 'Allow only one concurrent run'). When a new scheduled trigger fires while the previous run is still in progress, the new run is skipped rather than starting alongside the ongoing one. This prevents two runs from writing to the same tables at the same time - which is the data corruption risk the question highlights.
Cron-based schedule for the hourly trigger. A cron expression defines the regular execution cadence.
Combined with the concurrency setting, the job runs hourly but never overlaps.
An alternative to 'Skip' is 'Wait' (queue the new run), which ensures every scheduled run eventually executes
- but for this scenario where overlapping is the primary concern, skipping the missed run is typically preferable to building up a queue of back-to-back executions.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#concurrent-runs
NEW QUESTION # 28
......
With this software, you can evaluate your Microsoft DP-750 exam preparation.The beforehand awareness of your weaknesses will help you take the Microsoft certification exam successfully. Environment you encounter during the practice test is similar to the real Microsoft DP-750 Exam. This feature of software will help you kill Microsoft DP-750 Exam anxiety.
Authorized DP-750 Test Dumps: https://www.free4torrent.com/DP-750-braindumps-torrent.html