PassTIP에서 제공해드리는 Microsoft인증 DP-750덤프는 가장 출중한Microsoft인증 DP-750시험전 공부자료입니다. 덤프품질은 수많은 IT인사들로부터 검증받았습니다. Microsoft인증 DP-750덤프뿐만아니라 PassTIP에서는 모든 IT인증시험에 대비한 덤프를 제공해드립니다. IT인증자격증을 취득하려는 분들은PassTIP에 관심을 가져보세요. 구매의향이 있으시면 할인도 가능합니다. 고득점으로 패스하시면 지인분들께 추천도 해주실거죠?
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
PassTIP의 Microsoft인증 DP-750덤프를 선택하여Microsoft인증 DP-750시험공부를 하는건 제일 현명한 선택입니다. 시험에서 떨어지면 덤프비용 전액을 환불처리해드리고Microsoft인증 DP-750시험이 바뀌면 덤프도 업데이트하여 고객님께 최신버전을 발송해드립니다. Microsoft인증 DP-750덤프뿐만아니라 IT인증시험에 관한 모든 덤프를 제공해드립니다.
질문 # 29
You need to complete the PySpark code for the Spark Structured Streaming pipelines. The solution must meet the data ingestion and processing requirements.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.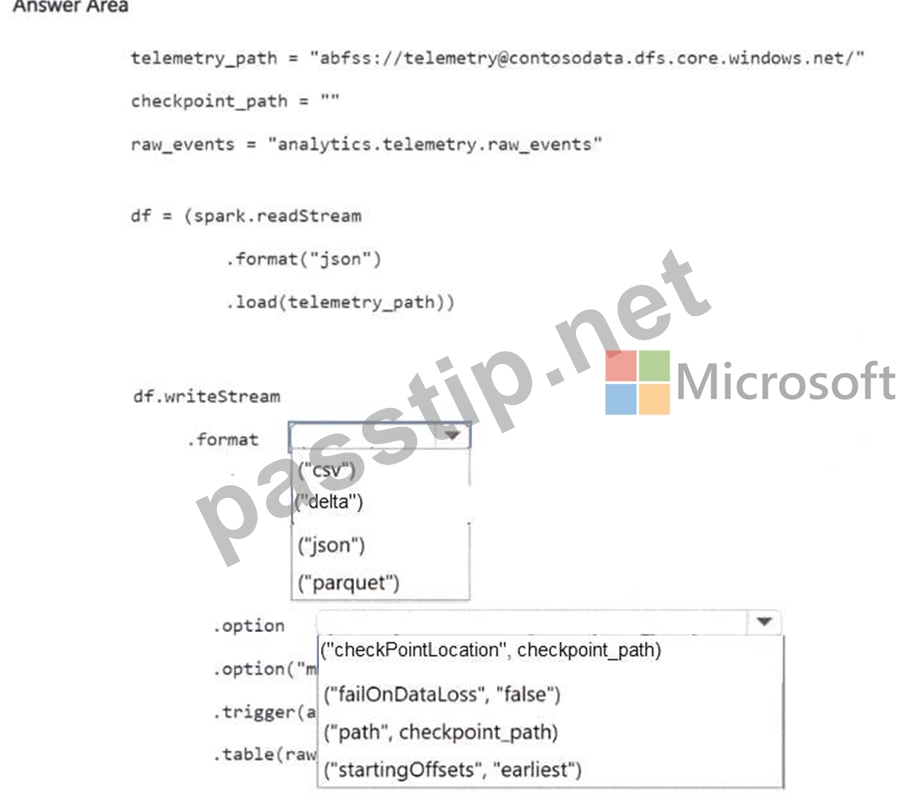
정답:
설명: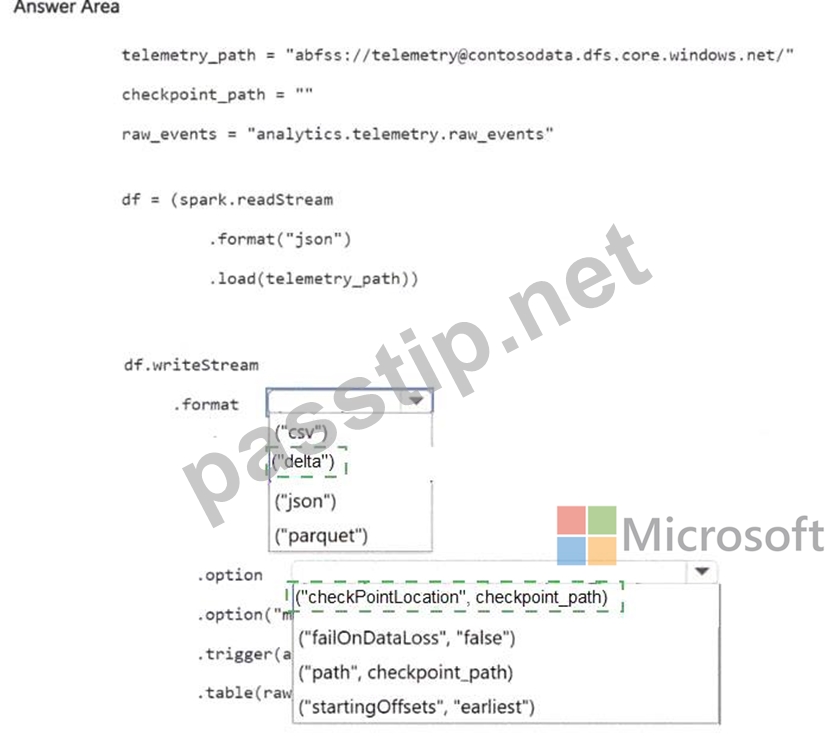
Explanation:
The solution requires spark.readStream with format('cloudFiles') for Auto Loader, paired with .writeStream using mergeSchema=true and a checkpointLocation.
Auto Loader's cloudFiles source incrementally processes new JSON files without rescanning the entire directory. The mergeSchema option handles schema drift - when sensors add new fields, the target Delta table schema expands automatically instead of throwing a parse error. This directly addresses Contoso's requirement to 'support schema drift.' The checkpointLocation is what gives the pipeline its resilience. Databricks writes the stream's committed offset and schema state to that path. If the cluster restarts, the engine reads the checkpoint and picks up exactly where it left off - no events are reprocessed, satisfying 'exactly-once semantics' and 'resume processing after failures without reprocessing the data.' Without a checkpoint, the stream would restart from the beginning on every cluster bounce, which is precisely the problem Contoso is trying to eliminate.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/schema
질문 # 30
Hotspot Question
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming. The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.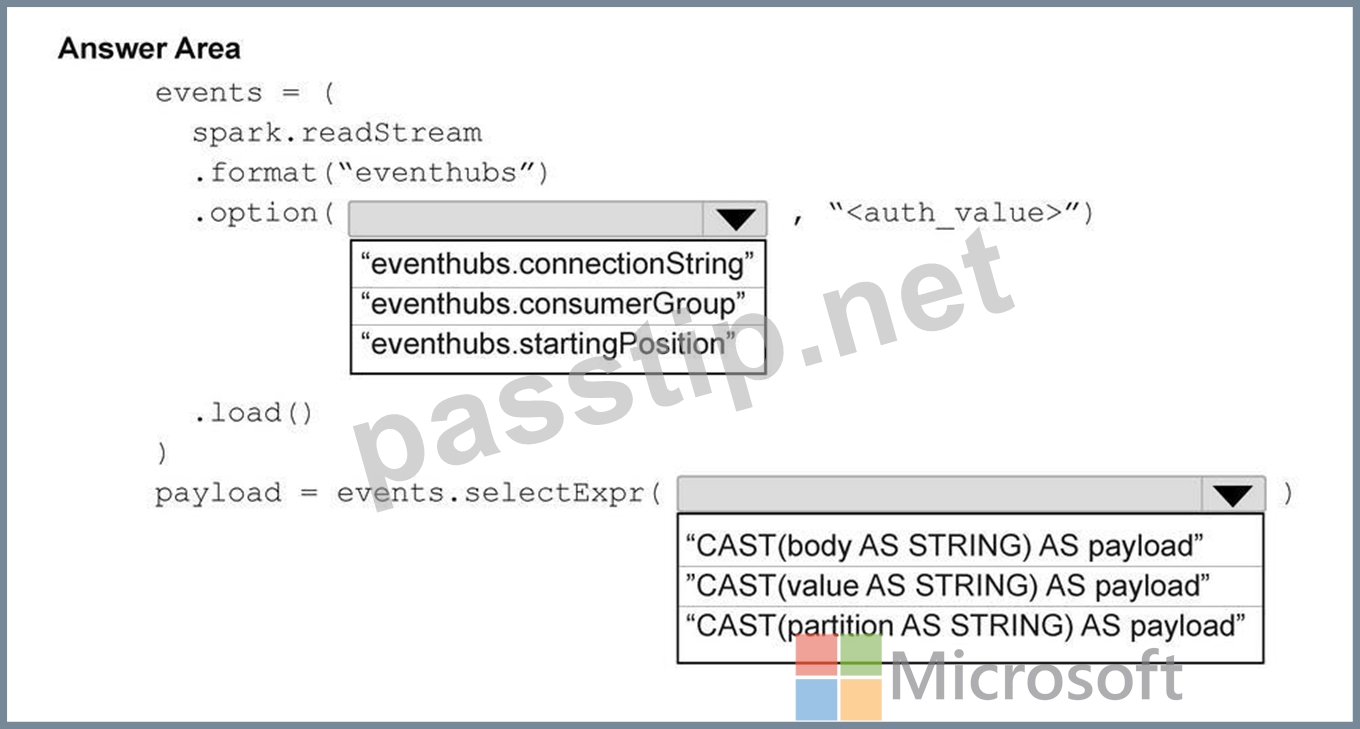
정답:
설명: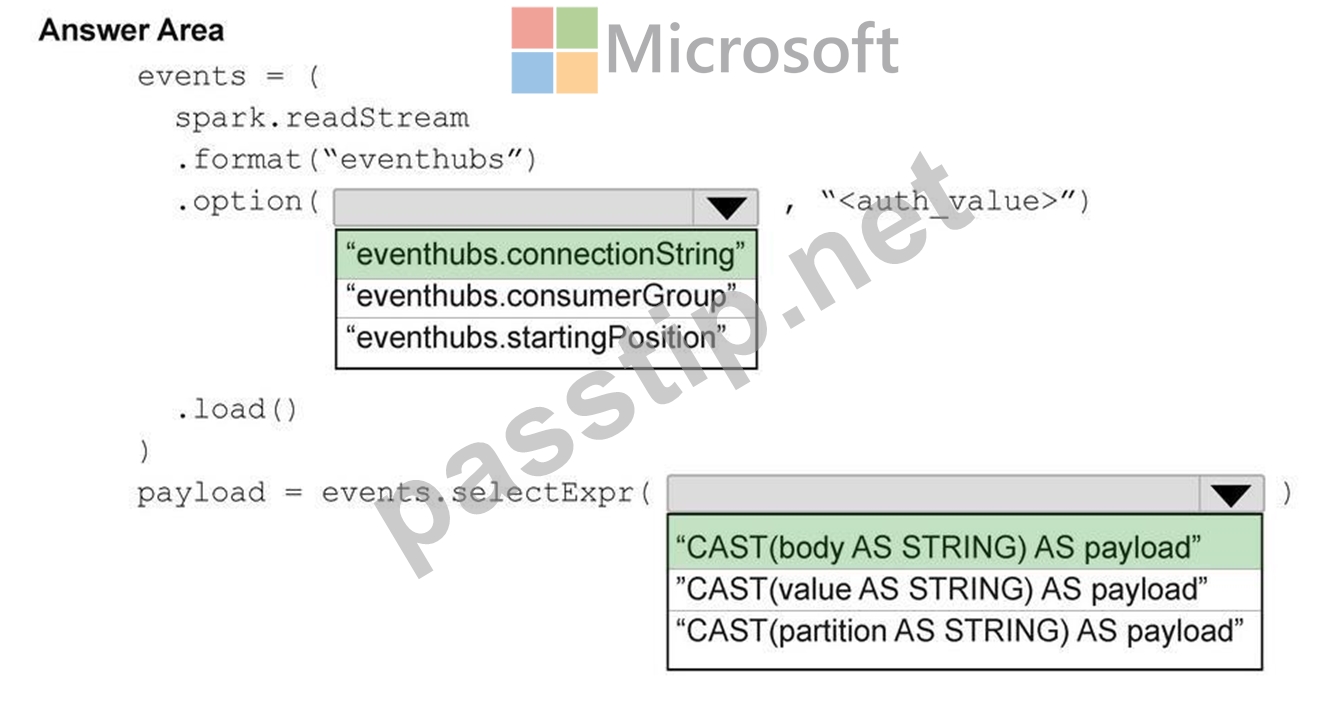
질문 # 31
You have an Azure Databricks workspace named Workspace1. You create a compute cluster named Cluser1 that will be used to ingest data.
You need to install the required libraries on Cluster 1. The solution must use Unity Catalog for access control.
What should you do?
정답:D
설명:
The correct answer is B. The %pip install command (or pip3 in a terminal context) creates an isolated, per- session library environment in notebooks, which is the Unity Catalog-compatible approach. Unity Catalog workspaces require cluster access mode set to 'Shared' or 'Single User,' and %pip installs work seamlessly within those modes without requiring cluster restarts.
Option A (custom dependency script) introduces extra maintenance work for every environment change - exactly what the question says to avoid. Option C installs libraries at the cluster level and requires a manual restart, which disrupts other users sharing the cluster and bypasses the per-notebook isolation model that Unity Catalog recommends. Option D uploads libraries to the Workspace file system (legacy DBFS approach), which is being deprecated in favour of Unity Catalog Volumes for library storage.
Reference: https://learn.microsoft.com/en-us/azure/databricks/libraries/notebooks-python-libraries
질문 # 32
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
db1.sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the db1.sales_orders table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.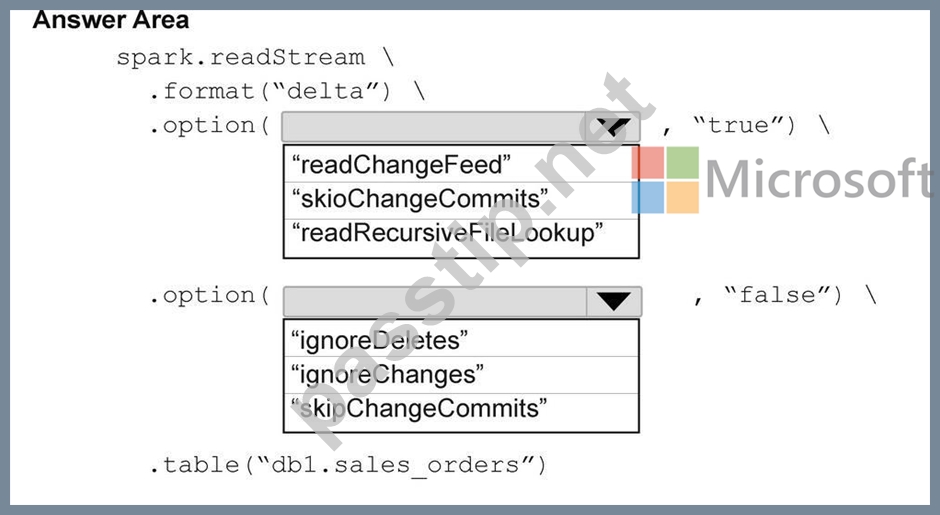
정답:
설명: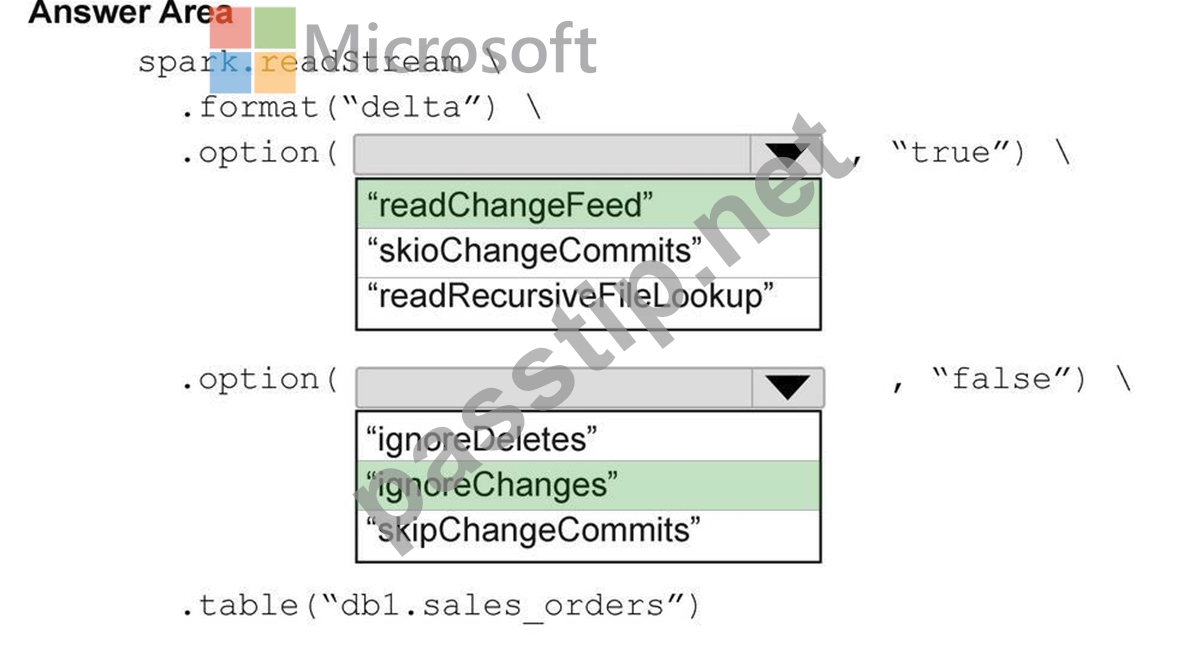
질문 # 33
Which Azure service is best integrated with Databricks Unity Catalog for centralized data governance?
정답:B
설명:
Microsoft Purview integrates with Unity Catalog to provide centralized data governance, classification, and lineage tracking. It helps organizations manage data compliance and discovery. Key Vault handles secrets, not governance. DevTest Labs is for testing environments.
Azure Automation is for workflow automation.
질문 # 34
......
PassTIP는 유일하게 여러분이 원하는Microsoft인증DP-750시험관련자료를 해결해드릴 수 잇는 사이트입니다. 여러분이 다른 사이트에서도 관련덤프자료를 보셨을경우 페이지 아래를 보면 자료출처는 당연히 PassTIP 일 것입니다. PassTIP의 자료만의 제일 전면적이고 또 최신 업데이트일 것입니다.
DP-750 Vce: https://www.passtip.net/DP-750-pass-exam.html