AI-300トレーニング資料は、ユーザーが学習した内容を統合し、多くのトレーニングの瞬間に追加するのに役立つように設計されています。ユーザーは、学習コンテンツの一部を終えた後、学習効果を時間内にテストできます。 AI-300ガイドトレントのトピックを使用して、ユーザーがこの機能の知識の弱点を見つけ、一定の練習を繰り返して、最終的に高い成功率を達成できるようにします。その結果、当社のAI-300試験問題は、ユーザーがAI-300試験に合格するための知識を習得できるように、実践内容の完全なセットを形成するように設計されています。
| Section | Objectives |
|---|---|
| Topic 1: Design and implement generative AI solutions | - Large language model integration
|
| Topic 2: Implement secure and scalable AI systems | - Scalability and performance optimization
|
| Topic 3: Plan and design AI solutions using Azure AI services | - Requirements gathering and solution architecture
|
| Topic 4: Operationalizing machine learning solutions | - ML lifecycle management
|
あなたが学生であるか、すでに仕事に参加した専門家であるかどうか、あなたは今競争の圧力を感じなければなりません。しかし、どんなに激しい競争であっても、あなたが力を持っている限り、あなたは確かに目立つことができます。良くなるのは簡単ではありません。 AI-300試験の質問はあなたに助けを与えることができます。 AI-300学習教材を使用した後、AI-300試験にすばやく合格し、自分の強さを証明することもできます。もちろん、AI-300学習教材はそれ以上のものをもたらします。 AI-300試験問題の助けを借りて、より明るい未来を手に入れてください。
質問 # 168
A team maintains Infrastructure as Code (IaC) templates to provision Azure Machine Learning resources.
Provisioning must be triggered by changes in the templates and executed without manual intervention.
You need to automate resource provisioning.
Which action should you take for each requirement? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content. NOTE: Each correct selection is worth one point.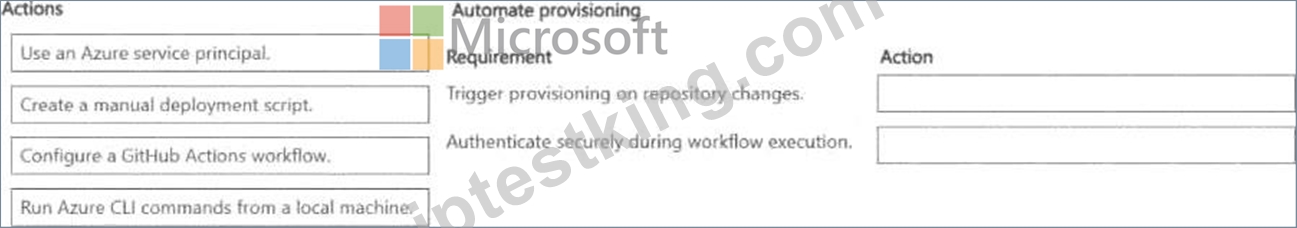
正解:
解説: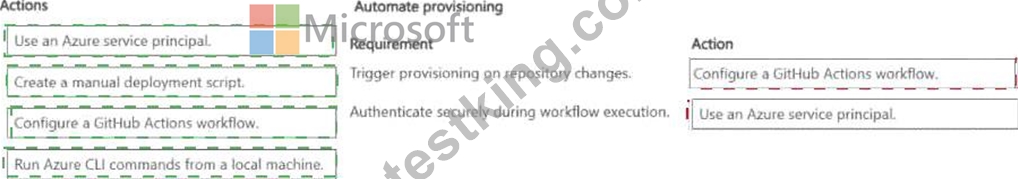
Explanation:
Azure Machine Learning infrastructure can be described as Infrastructure as Code using ARM templates, Bicep, or Terraform. To make provisioning fully automated, two separate concerns must be addressed. First, the trigger: a CI/CD system like GitHub Actions or Azure DevOps Pipelines must detect changes to IaC template files in the repository, configured through a branch-push or pull-request trigger. Second, the execution: the CI/CD pipeline runs the provisioning commands such as az ml workspace create or bicep deploy non-interactively using a service principal or managed identity, eliminating the need for a human to run scripts manually. Together, these two mechanisms deliver the GitOps-style automation that modern MLOps practices require, ensuring every template change automatically results in a consistent, auditable infrastructure update.
Microsoft Learn Reference Topic: Automate Azure Machine Learning with GitHub Actions - CI/CD for ML infrastructure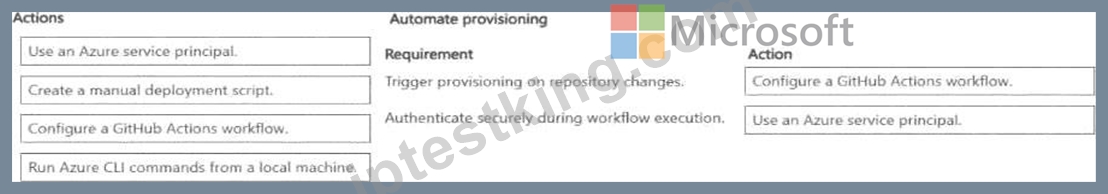
質問 # 169
A product team is building a customer support assistant that must respond consistently across multiple channels.
Early testing shows that small wording changes in prompts cause large differences in tone and factual accuracy.
The team needs prompts that are reliable, reusable, and adaptable across multiple use cases without retraining the underlying model.
You need to design prompts that improve response quality while remaining flexible for future changes.
Which two actions should you perform? Each correct answer presents part of the solution.
(Choose two.)
NOTE: Each correct selection is worth one point.
正解:D、E
解説:
To achieve reliable, reusable, and adaptable prompts without retraining the model, you should implement Prompt Flow, use System Messages for tone/role definition, and enforce Output Parsing. These techniques standardize how the model behaves across all channels.
Here is the most effective approach to stabilize your customer support assistant:
[B]
1. Implement Prompt Flow
Instead of hardcoding raw prompts in your code, use Azure Machine Learning Prompt Flow.
Visual Workflows: Create executable flows that link LLMs, prompts, and Python tools.
Versioning: Easily track, iterate, and roll back prompt versions without touching application code.
Evaluation: Test prompt variants systematically against a set of baseline queries to objectively measure factual accuracy and tone before pushing to production.
[C]
2. Standardize System Messages
A well-defined system message serves as the "guardrails" for your assistant. It should dictate the persona, scope of knowledge, and safety rules.
Define the Persona: Instruct the model exactly how to behave (e.g., "You are a helpful, empathetic, and strictly technical support assistant for [Company Name].").Strict Guidelines:
Provide instructions on how to handle out-of-scope queries (e.g., "If you do not know the answer, do not guess. Apologize and route the user to [Support Email].").
Reference:
https://whitebeardstrategies.com/blog/5-best-practices-for-efficient-language-model-prompting/
質問 # 170
You train and register an Azure Machine Learning model
You plan to deploy the model to an online endpoint
You need to ensure that applications will be able to use the authentication method with a non-expiring artifact to access the model.
Solution:
Create a managed online endpoint with the default authentication settings. Deploy the model to the online endpoint.
Does the solution meet the goal?
正解:A
質問 # 171
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You work in Microsoft Foundry with a prompt flow.
You must manually evaluate prompts and compare results across prompt variants.
You need to capture the inputs, outputs, token usage, and latencies for each flow run for the evaluation.
Solution: In Microsoft Foundry, turn on Tracing for the prompt flow of the project and execute test runs to produce trace data.
Does the solution meet the goal?
正解:A
解説:
Navigate to the Microsoft Foundry project in the Azure portal or Foundry portal and open the prompt flow for which you want to capture telemetry. Locate the Tracing toggle in the project or flow settings and enable it - this single action instructs the Foundry runtime to instrument every LLM call within the flow. Execute test runs of the prompt flow through the portal ' s test interface or via the CLI. Open the Traces view in Microsoft Foundry: each run appears as a trace with a tree of spans, where each span corresponds to one LLM call or tool invocation. Every span captures the exact input sent to the model, the model ' s output, token counts including prompt tokens and completion tokens, and wall-clock latency. Compare runs across prompt variants by examining individual traces side-by-side. This solution directly satisfies all four capture requirements.
Microsoft Learn Reference Topic: Enable and use tracing in Microsoft Foundry - Capturing LLM call telemetry for evaluation
質問 # 172
Hotspot Question
A team trains an MLflow model that scores customer churn risk. The model will be consumed by different downstream systems.
One system requests predictions synchronously during customer interactions.
Another system submits files containing millions of records for scheduled scoring.
You need to deploy the model by using managed inference options that match each usage pattern.
Which option should you use for each usage pattern? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.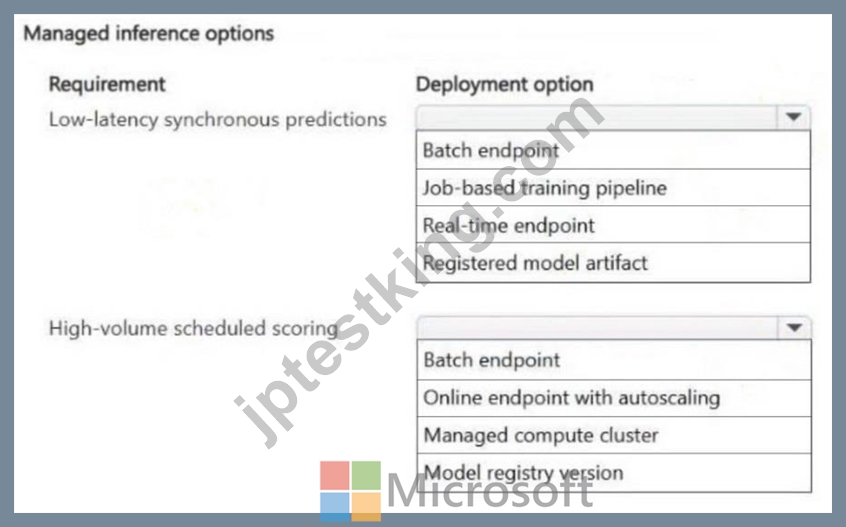
正解:
解説: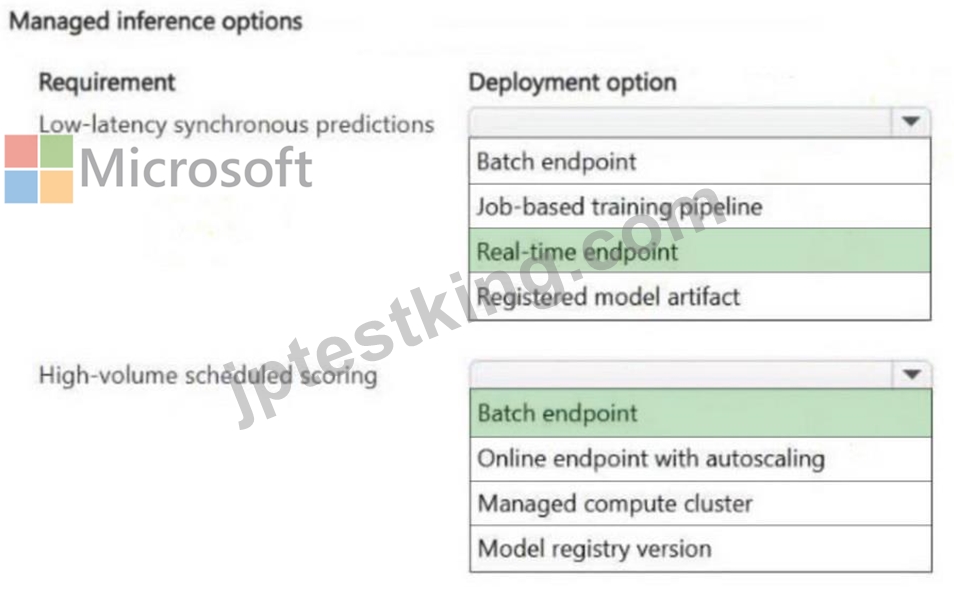
質問 # 173
......
当社JPTestKingの製品は、主要な質問と回答で精巧に構成されています。 AI-300ガイドの質問を完了するために、過去の資料からキーを選択しています。 練習するのに20時間から30時間しかかかりません。 効果的な練習の後、MicrosoftのAI-300テスト問題から試験ポイントをマスターできます。 そうすれば、合格するのに十分な自信があります。
AI-300試験情報: https://www.jptestking.com/AI-300-exam.html