Reliable New Certified-Data-Engineer-Professional Test Materials & Leading Offer in Qualification Exams & Fast Download Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional

First and foremost, we have high class operation system so we can assure you that you can start to prepare for the Certified-Data-Engineer-Professional exam with our study materials only 5 to 10 minutes after payment. Second, once we have compiled a new version of the Certified-Data-Engineer-Professional test question, we will send the latest version of our Certified-Data-Engineer-Professional Training Materials to our customers for free during the whole year after purchasing. Last but not least, our worldwide after sale staffs will provide the most considerate after sale service for you in twenty four hours a day, seven days a week.
| Section | Objectives |
|---|
| Topic 1: Ensuring Data Security and Compliance | - Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
- Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Use row filters and column masks for sensitive data
- 3. Apply anonymization and pseudonymization techniques
|
| Topic 2: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
| Topic 3: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Manage and troubleshoot third-party library installations and dependencies
- Building and Testing ETL Pipelines
- 1. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 2. Develop unit and integration tests for data processing code
- 3. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 4. Use APPLY CHANGES APIs for change data capture
- 5. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 6. Configure environments, dependencies, memory, and retry behavior
- 7. Use control flow operators in pipeline components
- 8. Compare streaming tables and materialized views
|
| Topic 4: Data Modelling | - Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Optimize data layout using Liquid Clustering
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Topic 5: Data Sharing and Federation | - Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure sharing with external platforms using the open sharing protocol
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Topic 6: Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use Query Profiler and Spark UI to monitor workloads
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Topic 7: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Topic 8: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
| Topic 9: Cost & Performance Optimisation | - Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Understand deletion vectors and liquid clustering
- 3. Apply data skipping and file pruning techniques
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Topic 10: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
>> New Certified-Data-Engineer-Professional Test Materials <<
Databricks Certified-Data-Engineer-Professional Updated Test Cram - Actual Certified-Data-Engineer-Professional Test Pdf
Exam-Killer is one of the only few platforms offering updated Databricks exam preparatory products for the Certified-Data-Engineer-Professional at an affordable rate. Our Databricks Certified-Data-Engineer-Professional exam questions preparation products help you know your weaknesses before the actual Databricks Certified Data Engineer Professional exam. Databricks Certified-Data-Engineer-Professional Exam Questions preparation materials are affordable for everyone. Moreover, we give you free updates for 365 days. Exam-Killer offers reliable, updated Databricks Exam Questions at an affordable price and also gives a 30% discount on all Databricks exam questions.
Databricks Certified Data Engineer Professional Sample Questions (Q114-Q119):
NEW QUESTION # 114
The data science team has created and logged a production model using MLflow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.
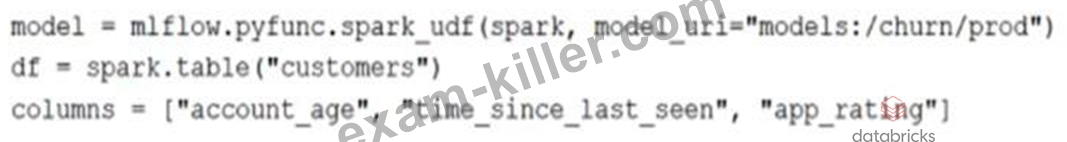
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
- A. df.select("customer_id", model(*columns).alias("predictions"))
- B. df.apply(model, columns).select("customer_id, predictions")
- C. df.select("customer_id", pandas_udf(model, columns).alias("predictions"))
- D. df.map(lambda x:model(x[columns])).select("customer_id, predictions")
- E. model.predict(df, columns)
Answer: A
Explanation:
This code block applies the Spark UDF created from the MLflow model to the DataFrame df by selecting the existing customer_id column and the new column produced by the model, which is aliased to predictions. The model(*columns) part is where the UDF is applied to the columns specified in the columns list, and alias("predictions") is used to name the output column of the model's predictions. This will result in a DataFrame with the desired schema: "customer_id LONG, predictions DOUBLE".
NEW QUESTION # 115
A data architect is designing a Databricks solution to efficiently process data for different business requirements. In which scenario should a data engineer use a materialized view compared to a streaming table?
- A. Ingesting data from Apache Kafka topics with sub-second processing requirements for immediate alerting.
- B. Processing high-volume, continuous clickstream data from a website to monitor user behavior in real-time.
- C. Precomputing complex aggregations and joins from multiple large tables to accelerate BI dashboard performance.
- D. Implementing a CDC (Change Data Capture) pipeline that needs to detect and respond to database changes within seconds.
Answer: C
Explanation:
Materialized views in Databricks are optimized for precomputing and caching results of complex SQL queries, joins, and aggregations. They store query outputs physically and automatically refresh on a schedule or incremental change basis, drastically improving BI dashboard performance and reducing compute costs.
Conversely, streaming tables are designed for real-time data ingestion and processing, enabling event-driven analytics and low-latency use cases.
Databricks documentation explicitly recommends materialized views for analytical workloads with periodic updates and streaming tables for continuously updating sources. Therefore, the correct choice is C, where complex aggregations from large tables benefit most from materialized precomputation for fast reporting.
NEW QUESTION # 116
A data engineer is using Lakeflow Declarative Pipelines Expectations feature to track the data quality of their incoming sensor data. Periodically, sensors send bad readings that are out of range, and they are currently flagging those rows with a warning and writing them to the silver table along with the good data. They've been given a new requirement ?the bad rows need to be quarantined in a separate quarantine table and no longer included in the silver table.
This is the existing code for their silver table:
@dlt.table
@dlt.expect("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
What code will satisfy the requirements?
- A. @dlt.table
@dlt.expect("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - B. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect_or_drop("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - C. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - D. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading < 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
Answer: A
Explanation:
Lakeflow Declarative Pipelines (DLT) supports data quality enforcement using @dlt.expect,
@dlt.expect_or_drop, and @dlt.expect_all.
@dlt.expect applies a rule and records whether rows pass or fail the condition but does not drop failing rows. Instead, failing rows can be written to a quarantine table.
@dlt.expect_or_drop enforces that only rows passing the condition flow downstream, dropping bad records automatically.
In this case, the requirement is:
Good rows (reading < 120) go to the silver table.
Bad rows (reading >= 120) go to a quarantine table.
Bad rows should not be included in silver.
The correct implementation is Option A, where:
The silver table uses @dlt.expect to validate reading < 120. These rows flow normally.
The quarantine table applies an expectation for reading >= 120, ensuring bad records are captured separately.
Other options are incorrect:
Option B/D: These either use expect_or_drop incorrectly or apply wrong conditions, leading to dropped rows without quarantining properly.
Option C: Uses expect_or_drop for both tables, which would discard bad rows instead of persisting them into a quarantine table.
Thus, Option A meets the business requirement to split good and bad data streams while ensuring both are captured for auditing and processing.
NEW QUESTION # 117
A data engineer wants to ingest a large collection of image files (JPEG and PNG) from cloud object storage into a Unity Catalog-managed table for analysis and visualization. Which two configurations and practices are recommended to incrementally ingest these images into the table? (Choose two.)
- A. Use Auto Loader and set cloudFiles.format to "TEXT".
- B. Use Auto Loader and set cloudFiles.format to "IMAGE".
- C. Move files to a volume and read with SQL editor.
- D. Use the pathGlobFilter option to select only image files (e.g., "*.jpg,*.png").
- E. Use Auto Loader and set cloudFiles.format to "BINARYFILE".
Answer: D,E
Explanation:
Databricks Auto Loader supports ingestion of binary file formats using the cloudFiles.format option. For ingesting JPEG or PNG image files, the correct setting is "BINARYFILE", which loads the raw binary content and file metadata into a DataFrame. Additionally, when processing files from object storage, it is best practice to apply pathGlobFilter to limit ingestion to specific file types and reduce unnecessary scanning of non-image files. Options like "IMAGE" or "TEXT" are invalid, and using volumes with SQL editors does not provide incremental ingestion. Therefore, combining Auto Loader with cloudFiles.format="BINARYFILE" and pathGlobFilter ensures scalable, incremental ingestion of image data into Unity Catalog tables.
NEW QUESTION # 118
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on Task A.
If task A fails during a scheduled run, which statement describes the results of this run?
- A. Tasks B and C will attempt to run as configured; any changes made in task A will be rolled back due to task failure.
- B. Tasks B and C will be skipped; task A will not commit any changes because of stage failure.
- C. Unless all tasks complete successfully, no changes will be committed to the Lakehouse; because task A failed, all commits will be rolled back automatically.
- D. Tasks B and C will be skipped; some logic expressed in task A may have been committed before task failure.
- E. Because all tasks are managed as a dependency graph, no changes will be committed to the Lakehouse until all tasks have successfully been completed.
Answer: D
Explanation:
When a Databricks job runs multiple tasks with dependencies, the tasks are executed in a dependency graph. If a task fails, the downstream tasks that depend on it are skipped and marked as Upstream failed. However, the failed task may have already committed some changes to the Lakehouse before the failure occurred, and those changes are not rolled back automatically. Therefore, the job run may result in a partial update of the Lakehouse. To avoid this, you can use the transactional writes feature of Delta Lake to ensure that the changes are only committed when the entire job run succeeds. Alternatively, you can use the Run if condition to configure tasks to run even when some or all of their dependencies have failed, allowing your job to recover from failures and continue running.
NEW QUESTION # 119
......
Perhaps you still have doubts about our Certified-Data-Engineer-Professional study tool. You can contact other buyers to confirm. Our company always regards quality as the most important things. The pursuit of quantity is meaningless. Our company positively accepts annual official quality inspection. All of our Certified-Data-Engineer-Professional real exam dumps have passed the official inspection every year. Our study materials are completely reliable and responsible for all customers. The development process of our study materials is strict. We will never carry out the Certified-Data-Engineer-Professional real exam dumps that are under researching. All Certified-Data-Engineer-Professional Study Tool that can be sold to customers are mature products. We are not chasing for enormous economic benefits. As for a company, we are willing to assume more social responsibility. So our Certified-Data-Engineer-Professional real exam dumps are manufactured carefully, which could endure the test of practice. Stable and healthy development is our long lasting pursuit. In order to avoid fake products, we strongly advise you to purchase our Certified-Data-Engineer-Professional exam question on our official website.
Certified-Data-Engineer-Professional Updated Test Cram: https://www.exam-killer.com/Certified-Data-Engineer-Professional-valid-questions.html
- Valid Certified-Data-Engineer-Professional Exam Cram ❕ Certified-Data-Engineer-Professional Vce Free 🚲 Certified-Data-Engineer-Professional Exam Vce Free 📊 Download ☀ Certified-Data-Engineer-Professional ️☀️ for free by simply searching on ▷ www.pass4test.com ◁ 🧟Certified-Data-Engineer-Professional Real Torrent
- Certified-Data-Engineer-Professional Mock Exams 🦢 Certified-Data-Engineer-Professional Sample Questions Pdf 🕖 Valid Certified-Data-Engineer-Professional Exam Cram 🚊 Open ▛ www.pdfvce.com ▟ and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download exam materials for free 🦯Valid Certified-Data-Engineer-Professional Exam Testking
- Test Certified-Data-Engineer-Professional Simulator Fee 🦟 Certified-Data-Engineer-Professional Latest Test Preparation 🧷 Test Certified-Data-Engineer-Professional Objectives Pdf 👬 Enter ☀ www.troytecdumps.com ️☀️ and search for ➽ Certified-Data-Engineer-Professional 🢪 to download for free 🔦Certified-Data-Engineer-Professional Exam Vce Free
- Quiz 2026 Unparalleled New Certified-Data-Engineer-Professional Test Materials - Databricks Certified Data Engineer Professional Updated Test Cram 🌯 The page for free download of ➤ Certified-Data-Engineer-Professional ⮘ on “ www.pdfvce.com ” will open immediately 🥀Dumps Certified-Data-Engineer-Professional Questions
- Free PDF Quiz Databricks - High Hit-Rate Certified-Data-Engineer-Professional - New Databricks Certified Data Engineer Professional Test Materials 😍 Open ▶ www.vceengine.com ◀ and search for “ Certified-Data-Engineer-Professional ” to download exam materials for free 🦔Certified-Data-Engineer-Professional Exam Vce Free
- Test Certified-Data-Engineer-Professional Simulator Fee ✉ Certified-Data-Engineer-Professional Best Preparation Materials 🧀 Certified-Data-Engineer-Professional Sample Questions Pdf 💘 The page for free download of ⮆ Certified-Data-Engineer-Professional ⮄ on 「 www.pdfvce.com 」 will open immediately 🏎Certified-Data-Engineer-Professional Valid Test Camp
- Certified-Data-Engineer-Professional Latest Test Preparation 🍨 Certified-Data-Engineer-Professional Latest Exam Vce 🚓 Dumps Certified-Data-Engineer-Professional Questions 😙 Search for ▛ Certified-Data-Engineer-Professional ▟ and obtain a free download on ✔ www.exam4labs.com ️✔️ 💋Certified-Data-Engineer-Professional Mock Exams
- Test Certified-Data-Engineer-Professional Objectives Pdf 🆚 Valid Certified-Data-Engineer-Professional Exam Testking 🥶 Latest Certified-Data-Engineer-Professional Exam Practice 🌉 Open “ www.pdfvce.com ” enter ▛ Certified-Data-Engineer-Professional ▟ and obtain a free download 🔖Certified-Data-Engineer-Professional Updated CBT
- Certified-Data-Engineer-Professional Updated CBT 🅾 Certified-Data-Engineer-Professional Best Preparation Materials 🏁 Reliable Certified-Data-Engineer-Professional Dumps Free 🔚 Search for { Certified-Data-Engineer-Professional } and easily obtain a free download on ( www.examcollectionpass.com ) ↖Certified-Data-Engineer-Professional Valid Test Camp
- Certified-Data-Engineer-Professional Mock Exams 🌎 Test Certified-Data-Engineer-Professional Simulator Fee 🔡 Certified-Data-Engineer-Professional Exam Vce Free 🕸 Search for ✔ Certified-Data-Engineer-Professional ️✔️ and download exam materials for free through ⇛ www.pdfvce.com ⇚ 🐆Certified-Data-Engineer-Professional Latest Examprep
- Valid Exam Certified-Data-Engineer-Professional Preparation 🚈 Certified-Data-Engineer-Professional Best Preparation Materials 😿 Certified-Data-Engineer-Professional Updated CBT 🌎 Immediately open ⮆ www.examcollectionpass.com ⮄ and search for 「 Certified-Data-Engineer-Professional 」 to obtain a free download 🌋Valid Certified-Data-Engineer-Professional Exam Testking
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, learn.csisafety.com.au, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes