無料でクラウドストレージから最新のCertShiken Workday-Pro-Integrations PDFダンプをダウンロードする:https://drive.google.com/open?id=1daY0Twmor7M1uNYE1FASSMeGhcexe1ic
最近の数年間で、IT領域の継続的な発展と成長に従って、Workday-Pro-Integrations認証試験はもうWorkday試験のマイルストーンになりました。WorkdayのWorkday-Pro-Integrations「Workday Pro Integrations Certification Exam」の認証試験はあなたがIT分野のプロフェッショナルになることにヘルプを差し上げます。WorkdayのWorkday-Pro-Integrationsの試験問題を提供するウェブが何百ありますが、なぜ受験生は殆どCertShikenを選んだのですか。それはCertShikenにはIT領域のエリートたちが組み立てられた団体があります。その団体はWorkdayのWorkday-Pro-Integrationsの認証試験の最新の資料に専攻して、あなたが気楽にWorkdayのWorkday-Pro-Integrationsの認証試験に合格するためにがんばっています。CertShikenは初めにWorkdayのWorkday-Pro-Integrationsの認証試験を受けるあなたが一回で成功することを保証します。CertShikenはいつまでもあなたのそばにいて、あなたと一緒に苦楽を共にするのです。
| Section | Objectives |
|---|---|
| Reporting | - Building, modifying, and managing Workday reports for integrations
|
| Calculated Fields | - Creation, configuration, and management of calculated fields
|
| Integrations | - Building scalable, maintainable, and secure integrations
|
| Cloud Connect | - Using Workday Cloud Connect solutions for third-party integration
|
| XSLT | - Transforming XML data structures
|
>> Workday-Pro-Integrations入門知識 <<
あまりにも多くのIT認定試験と試験に関連する参考書を見ると、頭が痛いと感じていますか。一体どうしたらでしょうか。どのように選択すべきなのかを知らないなら、私は教えてあげます。最近非常に人気があるWorkdayのWorkday-Pro-Integrations認定試験を選択できます。この認定試験の資格を取得すれば、あなたは大きなメリットを得ることができます。それに、より効率的に試験の準備をするために、CertShikenのWorkday-Pro-Integrations試験問題集を選択したほうがいいです。それはあなたが試験に合格する最善の方法です。
質問 # 93
How does an XSLT processor identify the specific nodes in an XML document to which a particular transformation rule should be applied?
正解:B
解説:
In XSLT, the processor applies transformation rules by matching nodes using XPath expressions inside <xsl:
template match=""> statements.
"Templates define the rule, and XPath expressions determine which nodes they apply to." This is the foundational mechanism by which XSLT processes XML data.
Why the others are incorrect:
* B. The <xsl:stylesheet> element defines scope, not node matching.
* C. <xsl:call-template> invokes a named template but does not itself match nodes.
* D. Namespace prefixes are used within XPath, but node matching is based on XPath.
Reference:W3C XSLT 1.0 Specification - xsl:template and XPath MatchingWorkday Integration Training -
"How XSLT Applies Rules to XML Output"
質問 # 94
This is the XML file generated from a Core Connector; Positions integration.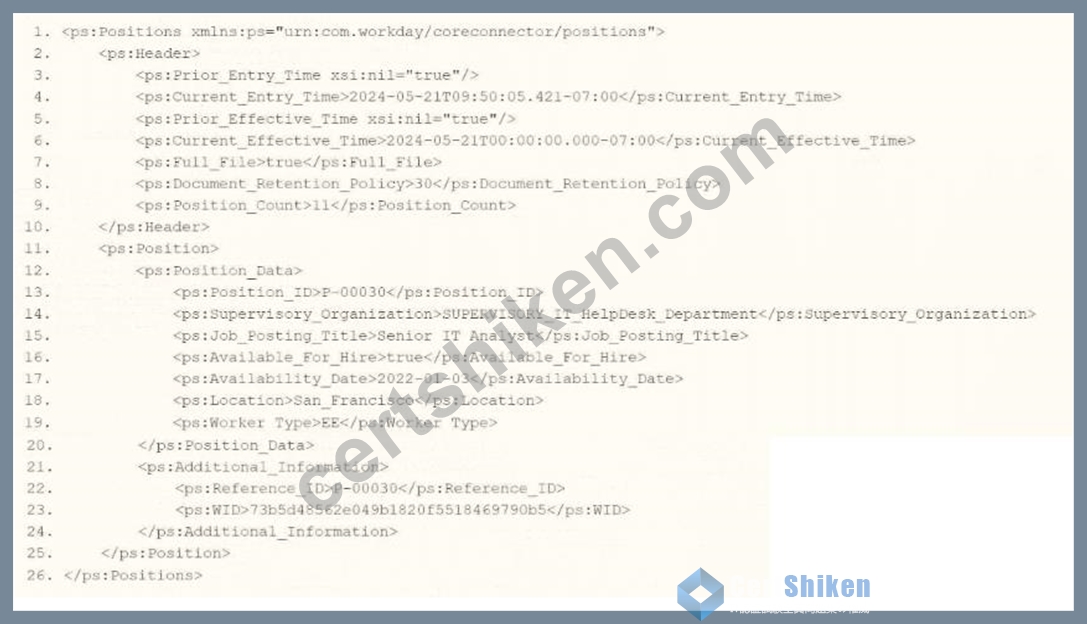
When performing an XSLT Transformation on the Core Connector: Positions XML output file, you want to show a hyperlink of positions that are not available for hiring as an entry in the Message tab.
What are all the needed ETV items to meet the above requirements?
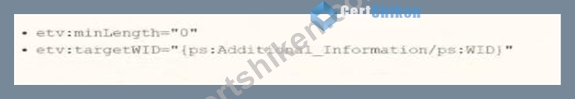
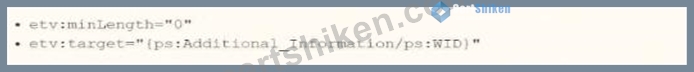
正解:B
解説:
In Workday integrations, the Extension for Transformation and Validation (ETV) framework is used within XSLT transformations to apply validation and formatting rules to XML data, such as the output from a Core Connector (e.g., Positions integration). In this scenario, you need to perform an XSLT transformation on the Core Connector: Positions XML output file to display a hyperlink for positions that are not available for hiring as an entry in the Message tab. This requires configuring ETV attributes to ensure the data is present and correctly targeted for the hyperlink.
Here's why option B is correct:
Requirement Analysis: The requirement specifies showing a hyperlink for positions "not available for hiring." In the provided XML, the ps:Available_For_Hire field under ps:Position_Data indicates whether a position is available for hire (e.g., <ps:Available_For_Hire>true</ps:Available_For_Hire>). For positions where this is false, you need to create a message (hyperlink) in the Message tab, which typically requires linking to a Workday ID (WID) or other identifier.
ETV Attributes:
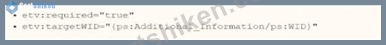
etv:required="true": This ensures that the ps:WID value under ps:Additional_Information is mandatory for the transformation. If the WID is missing, the transformation will fail or generate an error, ensuring that the hyperlink can be created only for valid positions with an associated WID.
etv:target="[ps:Additional_Information/ps:WID]": This specifies that the target of the transformation (e.g., the hyperlink) should be the WID value found at ps:Additional_Information/ps:WID in the XML. This WID can be used to construct a hyperlink to the position in Workday, meeting the requirement to show a hyperlink for positions not available for hiring.
Context in XML: The XML shows ps:Additional_Information containing ps:WID (e.g., <ps:WID>73bd4d8562e04b1820f55818467905b</ps:WID>), which is a unique identifier for the position. By targeting this WID with etv:target, you ensure the hyperlink points to the correct position record in Workday when ps:Available_For_Hire is false.
Why not the other options?
A .
etv:minLength="0"
etv:targetWID="[ps:Additional_Information/ps:WID]"
etv:minLength="0" allows the WID to be empty or have zero length, which contradicts the need for a valid WID to create a hyperlink. It does not ensure the data is present, making it unsuitable. Additionally, etv:targetWID is not a standard ETV attribute; the correct attribute is etv:target, making this option incorrect.
C .
etv:minLength="0"
etv:target="[ps:Additional_Information/ps:WID]"
Similar to option A, etv:minLength="0" allows the WID to be empty, which does not meet the requirement for a mandatory WID to create a hyperlink. This makes it incorrect, as the hyperlink would fail if the WID is missing.
D .
etv:required="true"
etv:targetWID="[ps:Additional_Information/ps:WID]"
While etv:required="true" ensures the WID is present, etv:targetWID is not a standard ETV attribute. The correct attribute is etv:target, making this option syntactically incorrect and unsuitable for the transformation.
To implement this in XSLT for a Workday integration:
Use the ETV attributes from option B (etv:required="true" and etv:target="[ps:Additional_Information/ps:WID]") within your XSLT template to validate and target the ps:WID for positions where ps:Available_For_Hire is false. This ensures the transformation generates a valid hyperlink in the Message tab, linking to the position's WID in Workday.
:
Workday Pro Integrations Study Guide: Section on "ETV in XSLT Transformations" - Details the use of ETV attributes like required and target for validating and targeting data in Workday XML, including handling identifiers like WID for hyperlinks.
Workday Core Connector and EIB Guide: Chapter on "XML Transformations" - Explains how to use ETV attributes in XSLT to process position data, including creating messages or hyperlinks based on conditions like Available_For_Hire.
Workday Integration System Fundamentals: Section on "ETV for Message Generation" - Covers applying ETV attributes to generate hyperlinks in the Message tab, ensuring data integrity and correct targeting of Workday identifiers like WID.
質問 # 95
You need to create a report that includes data from multiple business objects. For a supervisory organization specified at run time, the report must output one row per worker, their active benefit plans, and the names and ages of all related dependents. The Worker business object contains the Employee, Benefit Plans, and Dependents fields. The Dependent business object contains the employee's dependent's Name and Age fields.
How would you select the primary business object (PBO) and related business objects (RBO) for the report?
正解:C
解説:
In Workday reporting, selecting the appropriate Primary Business Object (PBO) and Related Business Objects (RBOs) is critical to ensure that the report retrieves and organizes data correctly based on the requirements.
The requirement here is to create a report that outputs one row per worker for a specified supervisory organization, including their active benefit plans and the names and ages of all related dependents. The Worker business object contains fields like Employee, Benefit Plans, and Dependents, while the Dependent business object provides the Name and Age fields for dependents.
* Why Worker as the PBO?The report needs to output "one row per worker," making the Worker business object the natural choice for the PBO. In Workday, the PBO defines the primary dataset and determines the granularity of the report (i.e., one row per instance of the PBO). Since the report revolves around workers and their associated data (benefit plans and dependents), Worker is the starting point. Additionally, the requirement specifies a supervisory organization at runtime, which is a filter applied to the Worker business object to limit the population.
* Why Dependent as an RBO?The Worker business object includes a "Dependents" field, which is a multi-instance field linking to the Dependent business object. To access detailed dependent data (Name and Age), the Dependent business object must be added as an RBO. This allows the report to pull in the related dependent information for each worker. Without the Dependent RBO, the report could only reference the existence of dependents, not their specific attributes like Name and Age.
* Analysis of Benefit Plans:The Worker business object already contains the "Benefit Plans" field, which provides access to active benefit plan data. Since this is a field directly available on the PBO (Worker), no additional RBO is needed to retrieve benefit plan information.
* Option Analysis:
* A. PBO: Dependent, RBO: Worker: Incorrect. If Dependent were the PBO, the report would output one row per dependent, not one row per worker, which contradicts the requirement.
Additionally, Worker as an RBO would unnecessarily complicate accessing worker-level data.
* B. PBO: Worker, RBO: Dependent: Correct. This aligns with the requirement: Worker as the PBO ensures one row per worker, and Dependent as the RBO provides access to dependent details (Name and Age). Benefit Plans are already accessible via the Worker PBO.
* C. PBO: Dependent, no RBOs: Incorrect. This would result in one row per dependent and would not allow easy access to worker or benefit plan data, failing to meet the "one row per worker" requirement.
* D. PBO: Worker, no RBOs: Incorrect. While Worker as the PBO is appropriate, omitting the Dependent RBO prevents the report from retrieving dependent Name and Age fields, which are stored in the Dependent business object, not directly on Worker.
* Implementation:
* Create a custom report with Worker as the PBO.
* Add a filter for the supervisory organization (specified at runtime) on the Worker PBO.
* Add Dependent as an RBO to access Name and Age fields.
* Include columns from Worker (e.g., Employee, Benefit Plans) and Dependent (e.g., Name, Age).
References from Workday Pro Integrations Study Guide:
* Workday Report Writer Fundamentals: Section on "Selecting Primary and Related Business Objects" explains how the PBO determines the report's row structure and RBOs extend data access to related objects.
* Integration System Fundamentals: Discusses how multi-instance fields (e.g., Dependents on Worker) require RBOs to retrieve detailed attributes.
質問 # 96
What items must a report have for you to use it as a data source for an integration?
正解:B
解説:
To use a custom report as an integration data source, especially through Report-as-a-Service or an EIB-style extract, the report must be configured so Workday can expose its output in a structured service format.
Enabling the report as a Web Service allows the report to be called externally or used by integration tools. The Namespace is required so the XML output has a defined structure and can be referenced properly. XML Aliases for fields, group column headings, and prompts are also required because they control the XML element names used in the integration output. Web service aliases and "linking fields" are not the correct required set. Without these report settings, the integration cannot reliably consume the report as a service- based data source.
質問 # 97
An external system needs a file containing data for total hours of overtime worked for each worker. They would like to receive a file at the end of each month. The file should show compensation changes since the last integration run.
What is the recurrence type of the integration schedule?
正解:A
解説:
The requirement is for the integration to run at the end of each month, so the schedule must be configured using a monthly recurrence pattern. "Day(s) of the Month: Last Day of the Month" directly matches the requirement because it automatically handles months with different lengths, including 28, 29, 30, and 31 days.
A dependent recurrence is used when one process depends on another scheduled process, which is not stated here. A custom recurrence is unnecessary because Workday provides a specific monthly scheduling option for the last day of the month. "Day of the Week: Last Sunday" would not reliably run at month-end. Since the file must include changes since the last run, a recurring monthly schedule is the correct design.
質問 # 98
......
この時代の変革とともに私たちは努力して積極的に進歩すべきです。WorkdayのWorkday-Pro-Integrations試験に参加するのを決めるとき、あなたは強い心を持っているのを証明します。我々CertShikenはあなたのような積極的な人に目標を達成させます。我々の提供した一番新しくて全面的なWorkdayのWorkday-Pro-Integrations資料はあなたのすべての需要を満たすことができます。
Workday-Pro-Integrations必殺問題集: https://www.certshiken.com/Workday-Pro-Integrations-shiken.html
BONUS!!! CertShiken Workday-Pro-Integrationsダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1daY0Twmor7M1uNYE1FASSMeGhcexe1ic