P.S. Free & New Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by BraindumpStudy: https://drive.google.com/open?id=13zghO1c17j8FecnG3FcZKbU81pLaz546
All kinds of exams are changing with dynamic society because the requirements are changing all the time. To keep up with the newest regulations of the Databricks Certified Data Analyst Associate Exam exam, our experts keep their eyes focusing on it. Expert team not only provides the high quality for the Databricks-Certified-Data-Analyst-Associate Quiz guide consulting, also help users solve problems at the same time, leak fill a vacancy, and finally to deepen the user's impression, to solve the problem of Databricks Certified Data Analyst Associate Exam test material and no longer make the same mistake.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Data Analyst Associate Exam |
| Exam Number: | Databricks-Certified-Data-Analyst-Associate |
| Related Certifications: | Databricks Certified Machine Learning Associate Databricks Certified Data Engineer Associate |
| Real Exam Qty: | 45 |
| Exam Price: | $200 USD |
| Certificate Validity Period: | 2 years |
| Available Languages: | English |
| Passing Score: | 70% |
| Exam Duration: | 90 minutes |
| Exam Format: | Multiple Choice |
| Sample Questions: | Databricks Databricks-Certified-Data-Analyst-Associate Sample Questions |
| Exam Way: | Online proctored or test center proctored |
| Pre Condition: | No formal prerequisites. Databricks recommends 6+ months of hands-on experience with data analysis and Databricks SQL. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-analyst-associate |
>> Databricks-Certified-Data-Analyst-Associate Latest Exam Test <<
BraindumpStudy also offers a demo version of the Databricks-Certified-Data-Analyst-Associate exam dumps for free. This way you can easily evaluate the validity of the Databricks-Certified-Data-Analyst-Associate prep material before buying it. Downloading a free demo will remove your doubts about purchasing the Databricks Databricks-Certified-Data-Analyst-Associate Questions. Most of the brands that offer Databricks Certified Data Analyst Associate Exam study material provide it at high rates.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 51
A data analyst filters rows where the tags array includes the value ' sql ' using this query:
SELECT *
FROM main.analytics.articles
WHERE tags = ' sql ' ;
This query returns no results.
How should the analyst query to filter for rows where the tags array contains ' sql ' ?
Answer: A
Explanation:
Option D is correct. The column tags is an array, so comparing the entire array to the scalar string ' sql ' is incorrect. The correct Databricks SQL function is array_contains(array, value), which returns true when the array contains the specified value. The uploaded document has a spelling error, array_conatins; the corrected Databricks function name is array_contains. Official Databricks documentation states that array_contains
"returns true if array contains value."
NEW QUESTION # 52
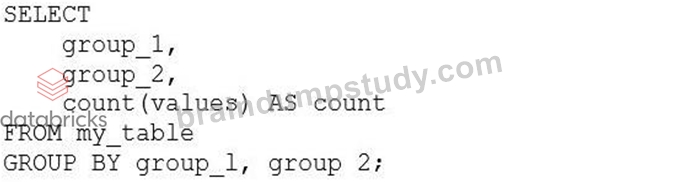
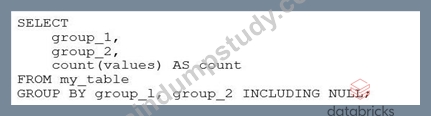
A data analyst is processing a complex aggregation on a table with zero null values and their query returns the following result: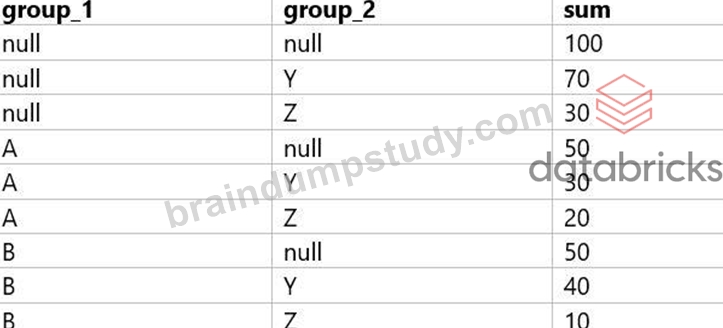
Which of the following queries did the analyst run to obtain the above result?
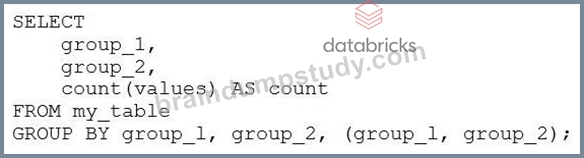
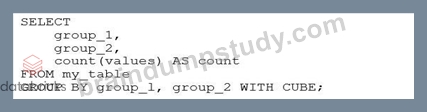
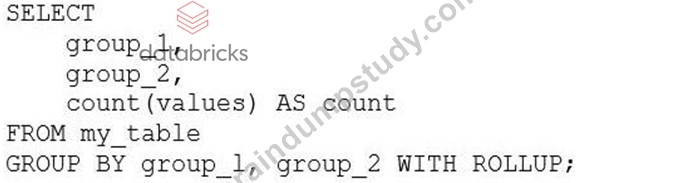
Answer: C
Explanation:
The result set provided shows a combination of grouping by two columns (group_1 and group_2) with subtotals for each level of grouping and a grand total. This pattern is typical of a GROUP BY ... WITH ROLLUP operation in SQL, which provides subtotal rows and a grand total row in the result set.
Considering the query options:
A) Option A: GROUP BY group_1, group_2 INCLUDING NULL - This is not a standard SQL clause and would not result in subtotals and a grand total.
B) Option B: GROUP BY group_1, group_2 WITH ROLLUP - This would create subtotals for each unique group_1, each combination of group_1 and group_2, and a grand total, which matches the result set provided.
C) Option C: GROUP BY group_1, group 2 - This is a simple GROUP BY and would not include subtotals or a grand total.
D) Option D: GROUP BY group_1, group_2, (group_1, group_2) - This syntax is not standard and would likely result in an error or be interpreted as a simple GROUP BY, not providing the subtotals and grand total.
E) Option E: GROUP BY group_1, group_2 WITH CUBE - The WITH CUBE operation produces subtotals for all combinations of the selected columns and a grand total, which is more than what is shown in the result set.
The correct answer is Option B, which uses WITH ROLLUP to generate the subtotals for each level of grouping as well as a grand total. This matches the result set where we have subtotals for each group_1, each combination of group_1 and group_2, and the grand total where both group_1 and group_2 are NULL.
NEW QUESTION # 53
A data engineering team has created a Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables. The microbatches are triggered every minute.
A data analyst has created a dashboard based on this gold-level data. The project stakeholders want to see the results in the dashboard updated within one minute or less of new data becoming available within the gold-level tables.
Which of the following cautions should the data analyst share prior to setting up the dashboard to complete this task?
Answer: C
Explanation:
A Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables every minute requires a high level of compute resources to handle the frequent data ingestion, processing, and writing. This could result in a significant cost for the organization, especially if the data volume and velocity are large. Therefore, the data analyst should share this caution with the project stakeholders before setting up the dashboard and evaluate the trade-offs between the desired refresh rate and the available budget. The other options are not valid cautions because:
B) The gold-level tables are assumed to be appropriately clean for business reporting, as they are the final output of the data engineering pipeline. If the data quality is not satisfactory, the issue should be addressed at the source or silver level, not at the gold level.
C) The streaming data is an appropriate data source for a dashboard, as it can provide near real-time insights and analytics for the business users. Structured Streaming supports various sources and sinks for streaming data, including Delta Lake, which can enable both batch and streaming queries on the same data.
D) The streaming cluster is fault tolerant, as Structured Streaming provides end-to-end exactly-once fault-tolerance guarantees through checkpointing and write-ahead logs. If a query fails, it can be restarted from the last checkpoint and resume processing.
E) The dashboard can be refreshed within one minute or less of new data becoming available in the gold-level tables, as Structured Streaming can trigger micro-batches as fast as possible (every few seconds) and update the results incrementally. However, this may not be necessary or optimal for the business use case, as it could cause frequent changes in the dashboard and consume more resources. Reference: Streaming on Databricks, Monitoring Structured Streaming queries on Databricks, A look at the new Structured Streaming UI in Apache Spark 3.0, Run your first Structured Streaming workload
NEW QUESTION # 54
A data analyst has been asked to count the number of customers in each region and has written the following query: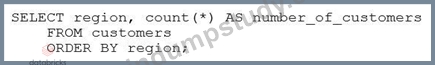
If there is a mistake in the query, which of the following describes the mistake?
Answer: E
Explanation:
In the provided SQL query, the data analyst is trying to count the number of customers in each region. However, they made a mistake by not including the "GROUP BY" clause to group the results by region. Without this clause, the query will not return counts for each distinct region but rather an error or incorrect result. Reference: The need for a GROUP BY clause in such queries can be understood from Databricks SQL documentation: Databricks SQL.
I also noticed that you uploaded an image with your question. The image shows a snippet of an SQL query written in plain text on a white background. The query is attempting to select regions and count customers from a "customers" table and order the results by region. There's no visible syntax highlighting or any other color - it's monochromatic. The query is the same as the one in your question. I'm not sure why you included the image, but maybe you wanted to show me the exact format of your query. If so, you can also use code blocks to display formatted content such as SQL queries. For example, you can write:
SELECT region, count(*) AS number_of_customers
FROM customers
ORDER BY region;
This way, you can avoid uploading images and make your questions more clear and concise. I hope this helps.
NEW QUESTION # 55
A data analyst has been asked to provide a list of options on how to share a dashboard with a client. It is a security requirement that the client does not gain access to any other information, resources, or artifacts in the database.
Which of the following approaches cannot be used to share the dashboard and meet the security requirement?
Answer: B
Explanation:
The approach that cannot be used to share the dashboard and meet the security requirement is D. Generating a Personal Access Token that is good for 1 day and sharing it with the client. This approach would give the client access to the Databricks workspace using the token owner's identity and permissions, which could expose other information, resources, or artifacts in the database1. The other approaches can be used to share the dashboard and meet the security requirement because:
A) Downloading the Dashboard as a PDF and sharing it with the client would only provide a static snapshot of the dashboard without any interactive features or access to the underlying data2.
B) Setting a refresh schedule for the dashboard and entering the client's email address in the "Subscribers" box would send the client an email with the latest dashboard results as an attachment or a link to a secure web page3. The client would not be able to access the Databricks workspace or the dashboard itself.
C) Taking a screenshot of the dashboard and sharing it with the client would also only provide a static snapshot of the dashboard without any interactive features or access to the underlying data4.
E) Downloading a PNG file of the visualizations in the dashboard and sharing them with the client would also only provide a static snapshot of the visualizations without any interactive features or access to the underlying data5. Reference:
1: Personal access tokens
2: Download as PDF
3: Automatically refresh a dashboard
4: Take a screenshot
5: Download a PNG file
NEW QUESTION # 56
......
Databricks-Certified-Data-Analyst-Associate Exam: https://www.braindumpstudy.com/Databricks-Certified-Data-Analyst-Associate_braindumps.html
BTW, DOWNLOAD part of BraindumpStudy Databricks-Certified-Data-Analyst-Associate dumps from Cloud Storage: https://drive.google.com/open?id=13zghO1c17j8FecnG3FcZKbU81pLaz546