完美的Professional-Data-Engineer考試資料|高通過率的考試材料|高通過率的Professional-Data-Engineer:Google Certified Professional Data Engineer Exam

BONUS!!! 免費下載PDFExamDumps Professional-Data-Engineer考試題庫的完整版:https://drive.google.com/open?id=1_bW9f5i4keyVh13T5rndZI9S_tbh7wC-
Google的Professional-Data-Engineer考試是IT行業之中既流行也非常重要的一個考試,我們準備了最優質的學習指南和最佳的線上服務,特意為IT專業人士提供捷徑,PDFExamDumps Google的Professional-Data-Engineer考題涵蓋了所有你需要知道的考試內容和答案,如果你通過我們PDFExamDumps的考題模擬,你就知道這才是你千方百計想得到的東西,並且認為這樣才真的是為考試做準備的
Google Professional-Data-Engineer Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Ensuring solution quality | 28% | - Reliability and performance
- 1. Fault tolerance and recovery strategies
- 2. Monitoring pipelines and workloads
- Security and governance
- 1. IAM and access control in GCP
- 2. Data governance and compliance
|
| Operationalizing machine learning models | 26% | - Model deployment and monitoring
- 1. Online vs batch prediction
- 2. Model monitoring and drift detection
- ML pipeline integration
- 1. Vertex AI pipeline deployment
- 2. Feature engineering and feature stores
|
| Designing data processing systems | 22% | - Batch and streaming data processing design
- 1. Event-driven vs batch architectures
- 2. Latency, throughput, and consistency trade-offs
- Data architecture and storage design
- 1. Choosing appropriate data storage solutions (relational, NoSQL, data warehouse)
- 2. Designing scalable and cost-effective data models
|
| Building and operationalizing data processing systems | 24% | - Data processing and transformation
- 1. Using Dataproc, Dataflow, and BigQuery SQL
- 2. ETL/ELT pipeline design
- Data ingestion and integration
- 1. Streaming ingestion (Pub/Sub, Dataflow)
- 2. Batch ingestion pipelines (BigQuery, Cloud Storage)
|
>> Professional-Data-Engineer考試資料 <<
高質量的Google Professional-Data-Engineer考試資料和授權的PDFExamDumps - 認證考試材料的領導者
我們PDFExamDumps配置提供給你最優質的Google的Professional-Data-Engineer考試考古題及答案,將你一步一步帶向成功,我們PDFExamDumps Google的Professional-Data-Engineer考試認證資料絕對提供給你一個真實的考前準備,我們針對性很強,就如同為你量身定做一般,你一定會成為一個有實力的IT專家,我們PDFExamDumps Google的Professional-Data-Engineer考試認證資料將是最適合你也是你最需要的培訓資料,趕緊註冊我們PDFExamDumps網站,相信你會有意外的收穫。
最新的 Google Cloud Certified Professional-Data-Engineer 免費考試真題 (Q71-Q76):
問題 #71
Your company operates in three domains: airlines, hotels, and ride-hailing services. Each domain has two teams: analytics and data science, which create data assets in BigQuery with the help of a central data platform team. However, as each domain is evolving rapidly, the central data platform team is becoming a bottleneck. This is causing delays in deriving insights from data, and resulting in stale data when pipelines are not kept up to date. You need to design a data mesh architecture by using Dataplex to eliminate the bottleneck. What should you do?
- A. 1. Create one lake for each team. Inside each lake, create one zone for each domain.
2. Attach each of the BigQuery datasets created by the individual teams as assets to the respective zone.
3. Have the central data platform team manage all zones' data assets. - B. 1 Create one lake for each domain. Inside each lake, create one zone for each team.
2. Attach each of the BigQuery datasets created by the individual teams as assets to the respective zone.
3. Have the central data platform team manage all lakes' data assets. - C. 1 Create one lake for each team. Inside each lake, create one zone for each domain.
2. Attach each to the BigQuory datasets created by the individual teams as assets to the respective zone.
3. Direct each domain to manage their own zone's data assets. - D. 1 Create one lake for each domain. Inside each lake, create one zone for each team.
2. Attach each of the BigQuery datasets created by the individual teams as assets to the respective zone.
3. Direct each domain to manage their own lake's data assets.
答案:C
解題說明:
To design a data mesh architecture using Dataplex to eliminate bottlenecks caused by a central data platform team, consider the following:
Data Mesh Architecture:
Data mesh promotes a decentralized approach where domain teams manage their own data pipelines and assets, increasing agility and reducing bottlenecks.
Dataplex Lakes and Zones:
Lakes in Dataplex are logical containers for managing data at scale, and zones are subdivisions within lakes for organizing data based on domains, teams, or other criteria.
Domain and Team Management:
By creating a lake for each team and zones for each domain, each team can independently manage their data assets without relying on the central data platform team.
This setup aligns with the principles of data mesh, promoting ownership and reducing delays in data processing and insights.
Implementation Steps:
Create Lakes and Zones:
Create separate lakes in Dataplex for each team (analytics and data science).
Within each lake, create zones for the different domains (airlines, hotels, ride-hailing).
Attach BigQuery Datasets:
Attach the BigQuery datasets created by the respective teams as assets to their corresponding zones.
Decentralized Management:
Allow each domain to manage their own zone's data assets, providing them with the autonomy to update and maintain their pipelines without depending on the central team.
Reference:
Dataplex Documentation
BigQuery Documentation
Data Mesh Principles
問題 #72
Your team is working on a binary classification problem. You have trained a support vector machine (SVM) classifier with default parameters, and received an area under the Curve (AUC) of 0.87 on the validation set.
You want to increase the AUC of the model. What should you do?
- A. Train a classifier with deep neural networks, because neural networks would always beat SVMs
- B. Perform hyperparameter tuning
- C. Deploy the model and measure the real-world AUC; it's always higher because of generalization
- D. Scale predictions you get out of the model (tune a scaling factor as a hyperparameter) in order to get the highest AUC
答案:D
解題說明:
Explanation/Reference:
問題 #73
Your company is using WHILECARD tables to query data across multiple tables with similar names. The SQL statement is currently failing with the following error:
# Syntax error : Expected end of statement but got "-" at [4:11]
SELECT age
FROM
bigquery-public-data.noaa_gsod.gsod
WHERE
age != 99
AND_TABLE_SUFFIX = '1929'
ORDER BY
age DESC
Which table name will make the SQL statement work correctly?
- A. 'bigquery-public-data.noaa_gsod.gsod'*
- B. bigquery-public-data.noaa_gsod.gsod*
- C. 'bigquery-public-data.noaa_gsod.gsod*`
- D. 'bigquery-public-data.noaa_gsod.gsod'
答案:B
問題 #74
You operate a database that stores stock trades and an application that retrieves average stock price for a given company over an adjustable window of time. The data is stored in Cloud Bigtable where the datetime of the stock trade is the beginning of the row key. Your application has thousands of concurrent users, and you notice that performance is starting to degrade as more stocks are added. What should you do to improve the performance of your application?
- A. Change the row key syntax in your Cloud Bigtable table to begin with a random number per second.
- B. Change the row key syntax in your Cloud Bigtable table to begin with the stock symbol.
- C. Change the data pipeline to use BigQuery for storing stock trades, and update your application.
- D. Use Cloud Dataflow to write summary of each day's stock trades to an Avro file on Cloud Storage.
Update your application to read from Cloud Storage and Cloud Bigtable to compute the responses.
答案:B
問題 #75
You are deploying a new storage system for your mobile application, which is a media streaming service. You decide the best fit is Google Cloud Datastore. You have entities with multiple properties, some of which can take on multiple values. For example, in the entity 'Movie' the property 'actors' and the property 'tags' have multiple values but the property 'date released' does not. A typical query would ask for all movies with actor=<actorname> ordered by date_released or all movies with tag=Comedy ordered by date_released. How should you avoid a combinatorial explosion in the number of indexes?
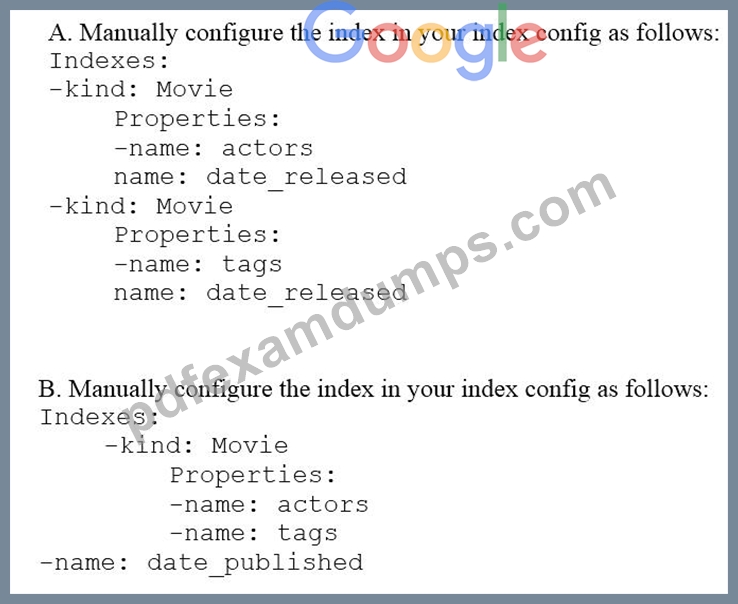
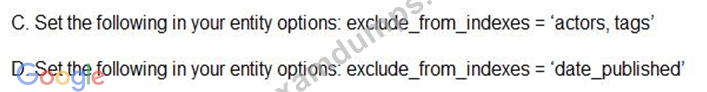
- A. Option A
- B. Option C
- C. Option D
- D. Option B.
答案:A
問題 #76
......
PDFExamDumps 考题大师始终致力与为客户提供 Professional-Data-Engineer 认证的全真考题及认证学习资料,該模擬試題可以在不同的電腦中使用,這對於考生來說沒有任何限制。我們的 Professional-Data-Engineer 權威考試題庫軟體是 Google 認證廠商的授權產品,全新的收錄了 Google 認證考試的所有試題,並根據認證的不斷變化而動態更新,參考資料的考試試題都是最新推出的。能够帮助你一次通过 Google Professional-Data-Engineer 认证考试。
Professional-Data-Engineer認證考試解析: https://www.pdfexamdumps.com/Professional-Data-Engineer_valid-braindumps.html
- Professional-Data-Engineer考試資料 |絕對通過|退款保證 ✅ 到「 www.pdfexamdumps.com 」搜尋{ Professional-Data-Engineer }以獲取免費下載考試資料Professional-Data-Engineer真題
- 最實用的Professional-Data-Engineer認證考試的題目與答案 🏐 ➥ www.newdumpspdf.com 🡄最新➠ Professional-Data-Engineer 🠰問題集合Professional-Data-Engineer PDF
- Professional-Data-Engineer題庫更新資訊 🎽 Professional-Data-Engineer真題 🎀 Professional-Data-Engineer考試大綱 🍈 ➡ www.pdfexamdumps.com ️⬅️上搜索➽ Professional-Data-Engineer 🢪輕鬆獲取免費下載Professional-Data-Engineer套裝
- 最有效的Professional-Data-Engineer考試資料,提前為Google Certified Professional Data Engineer Exam Professional-Data-Engineer考試做好準備 📄 ⇛ www.newdumpspdf.com ⇚是獲取[ Professional-Data-Engineer ]免費下載的最佳網站Professional-Data-Engineer認證資料
- Professional-Data-Engineer權威認證 ❗ Professional-Data-Engineer權威認證 🙂 Professional-Data-Engineer題庫下載 🤠 《 www.newdumpspdf.com 》是獲取( Professional-Data-Engineer )免費下載的最佳網站Professional-Data-Engineer題庫下載
- Professional-Data-Engineer考試資訊 🥌 Professional-Data-Engineer權威考題 📘 Professional-Data-Engineer真題 🌼 在⇛ www.newdumpspdf.com ⇚網站下載免費[ Professional-Data-Engineer ]題庫收集Professional-Data-Engineer題庫更新
- 最實用的Professional-Data-Engineer認證考試的題目與答案 ✡ 免費下載( Professional-Data-Engineer )只需在▶ www.vcesoft.com ◀上搜索Professional-Data-Engineer題庫更新資訊
- 準備充分的Professional-Data-Engineer考試資料和資格考試的領先材料提供商&準確的Professional-Data-Engineer認證考試解析 🛹 《 www.newdumpspdf.com 》上的免費下載▷ Professional-Data-Engineer ◁頁面立即打開Professional-Data-Engineer考試資訊
- 最實用的Professional-Data-Engineer認證考試的題目與答案 💌 ➠ www.vcesoft.com 🠰提供免費☀ Professional-Data-Engineer ️☀️問題收集Professional-Data-Engineer參考資料
- Professional-Data-Engineer權威認證 🚨 Professional-Data-Engineer最新考題 👒 Professional-Data-Engineer題庫更新 🤹 ▷ www.newdumpspdf.com ◁提供免費➽ Professional-Data-Engineer 🢪問題收集Professional-Data-Engineer真題
- Professional-Data-Engineer最新考題 🤸 Professional-Data-Engineer更新 🔑 Professional-Data-Engineer題庫更新資訊 🕉 ➥ www.testpdf.net 🡄上的免費下載( Professional-Data-Engineer )頁面立即打開Professional-Data-Engineer考題
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.competize.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, gettr.com, Disposable vapes
BONUS!!! 免費下載PDFExamDumps Professional-Data-Engineer考試題庫的完整版:https://drive.google.com/open?id=1_bW9f5i4keyVh13T5rndZI9S_tbh7wC-