Although the DP-750 certificate is good, people who can successfully obtain each year are rare, and the difficulty of the DP-750 exam and the pressure of study usually make the students feel discouraged. However, for us, these will no longer be a problem. In the past few years, our team has ushered in hundreds of industry experts, experienced numerous challenges day and night, and finally formed complete learning products--DP-750 Exam Torrent, which is tailor-made for students who want to obtain the DP-750 certificate.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
>> Valid Braindumps Microsoft DP-750 Ebook <<
Considering all customers'sincere requirements, DP-750 test question promise to our candidates with plenty of high-quality products, considerate after-sale services. Numerous advantages of DP-750training materials are well-recognized, such as 99% pass rate in the exam, free trial before purchasing, secure privacy protection and so forth. From the customers'perspective, We treasure every customer'reliance and feedback to the optimal DP-750 Practice Test and be the best choice.
NEW QUESTION # 72
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.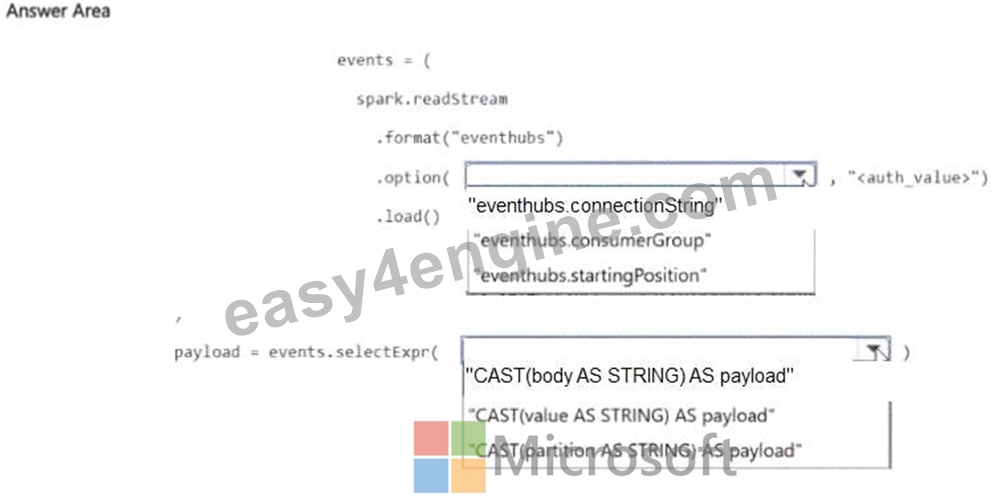
Answer:
Explanation: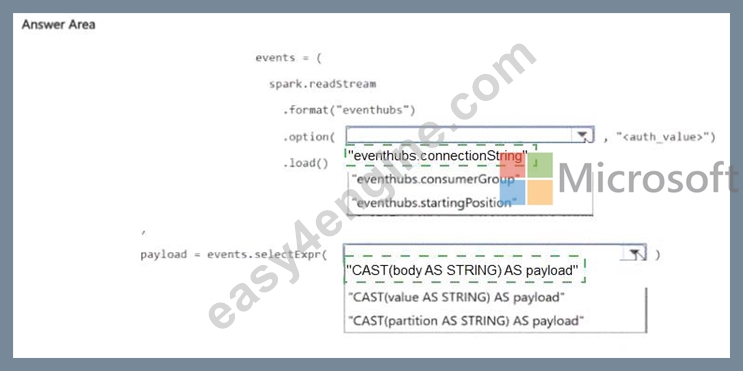
Explanation:
Reading from Azure Event Hubs in Spark Structured Streaming requires three things:
An EventHubsConf object built with the Event Hubs connection string (eventhubs.connectionString). This object is then converted to a map with .toMap before being passed to Spark.
spark.readStream.format('eventhubs').options(**ehConf).load() to create the streaming DataFrame. The
'eventhubs' format is provided by the azure-eventhubs-spark connector library.
A cast('string') on the body column to decode the binary payload. Event Hubs delivers messages with the raw event bytes in a column called body - without the cast, you get binary data rather than the readable JSON or text payload.
This is the standard, documented integration pattern for connecting Azure Databricks to Event Hubs with Structured Streaming, providing the checkpoint-based exactly-once semantics required by the Contoso telemetry pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/storage/events/eventhubs
NEW QUESTION # 73
You use Databricks Asset Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements:
- Deploy the app to both environments.
- Deploy only one job to development.
- Minimize administrative effort.
What should you use?
Answer: D
Explanation:
To meet your deployment needs with minimal administrative overhead, you should use Databricks Asset Bundle (DAB) targets combined with resource overrides or conditional lookups using Go template syntax in your databricks.yml file.
Instead of creating separate bundles or complex CI/CD logic, you can declare both jobs and the app inside the main resources block, and then filter or modify them per target environment.
Implementation Options
Depending on your preference for keeping configuration declarative or fully conditional, choose one of the two standard patterns:
*-> Option 1: Resource Overrides via targets (Recommended)
Define all components globally, but use the targets block to remove or empty out the configuration of the job you want to skip in development.yamlbundle:
name: my-unified-bundle
apps:
my_app:
# App configurations go here...
jobs:
job_shared:
# Configurations for the job deployed to BOTH dev and prod...
job_prod_only:
name: Only for Production
# Production configurations...
targets:
dev:
mode: development
workspace:
host: https://dev-workspace.cloud.databricks.com
# Keep administrative work low by overriding the prod job to null/empty resources:
jobs:
job_prod_only: !null
prod:
mode: production
workspace:
host: https://prod-workspace.cloud.databricks.com
Option 2: Go Template Conditional LogicIf you prefer not to use !null overrides, you can evaluate the target environment dynamically at deployment time using standard Go templates.
Reference:
https://docs.databricks.com/aws/en/dev-tools/bundles/workspace-deploy
NEW QUESTION # 74
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
* A catalog named Corpdb
* A schema named Finance in the Corpdb catalog
* A table named Sales in the Finance schema
You have a group named Analysts.
You assign the following permissions to Analysts:
* USE CATALOG on the Corpdb catalog
* USE SCHEMA on the Finance schema
* SELECT on the Sales table
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.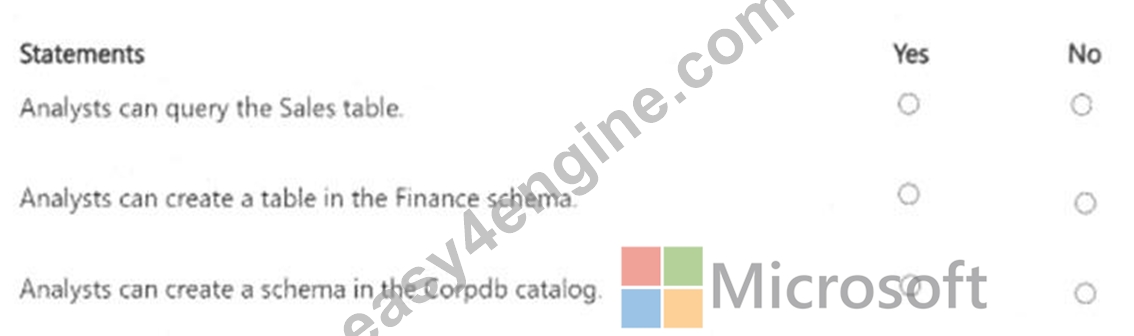
Answer:
Explanation: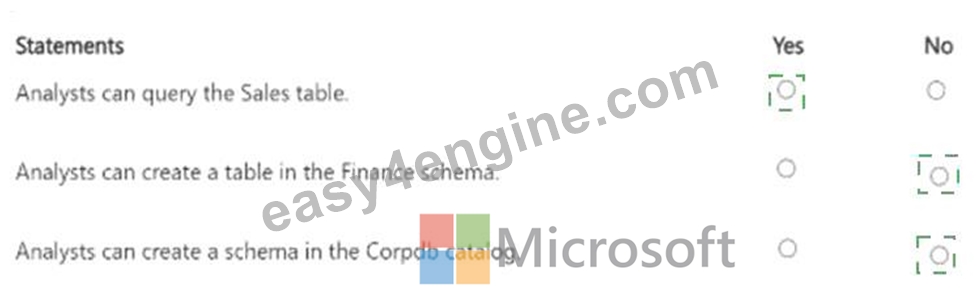
Explanation: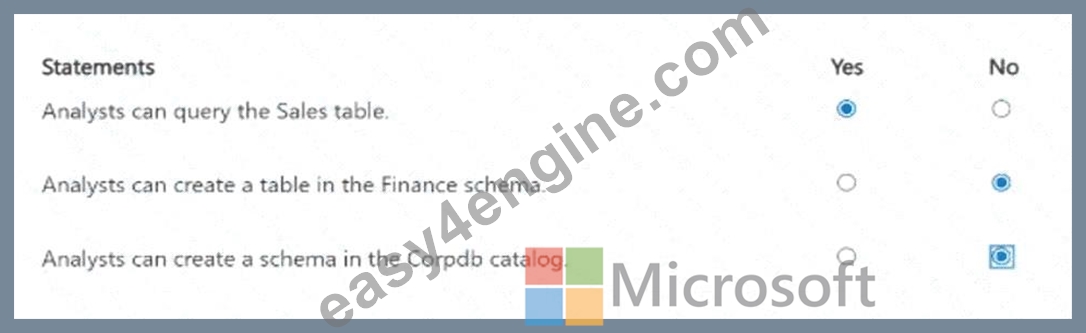
The Analysts group can query the Sales table because it has all three privileges required by the Unity Catalog hierarchy: USE CATALOG on Corpdb, USE SCHEMA on Finance, and SELECT on Sales. These permissions allow the group to navigate through the catalog and schema and read the table. However, USE SCHEMA does not grant permission to create tables. Creating a table in Finance would additionally require CREATE TABLE on that schema. Similarly, USE CATALOG only permits access to the catalog; it does not permit schema creation. Creating a schema in Corpdb would require the CREATE SCHEMA privilege on the catalog. Therefore, only the first statement is true.
NEW QUESTION # 75
You manage Declarative Automation Bundles by using the Databricks CLI.
You run the following command in a terminal window.
databricks bundle init
What occurs when you run the command?
Answer: B
Explanation:
The databricks bundle init command initializes a new bundle project from a selected default or custom project template. It prompts for relevant project values and creates the local project structure and starter configuration files. It does not deploy resources; deployment is performed with databricks bundle deploy. It does not merely validate an existing configuration, because validation uses databricks bundle validate. Running deployed bundle resources requires databricks bundle run followed by the resource key. The distinction matters in an automated bundle lifecycle: initialization scaffolds the project, validation checks configuration, deployment creates or updates workspace resources, and run starts a configured job or pipeline. Therefore, option A accurately describes the initialization command's function. Microsoft Learn
NEW QUESTION # 76
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 77
......
Success in the DP-750 certification exam is essential to advance your career. The Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification can set you apart from the competition and give you the edge you need to grow in your career. However, preparing for the DP-750 test can be challenging, mainly if you have limited time. Here's where Easy4Engine comes in with actual DP-750 Questions. We at Easy4Engine are well aware of the importance of the Microsoft DP-750 certification in order to stand out in today's competitive job environment.
Reliable DP-750 Test Notes: https://www.easy4engine.com/DP-750-test-engine.html