DOWNLOAD the newest Itcertking DP-700 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1b2h5-92VOu6HuWREJVKgSGE6p3H4w7Np
All these three Implementing Data Engineering Solutions Using Microsoft Fabric (DP-700) exam questions formats contain the actual, updated, and error-free Implementing Data Engineering Solutions Using Microsoft Fabric (DP-700) exam practice test questions that assist you in Implementing Data Engineering Solutions Using Microsoft Fabric (DP-700) exam preparation. Finally, With the Microsoft DP-700 Exam Questions you will be ready to get success in the final Microsoft DP-700 certification exam. Please choose the best Implementing Data Engineering Solutions Using Microsoft Fabric (DP-700) exam questions format and download it quickly and start this journey today.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> DP-700 Reliable Practice Materials <<
It is well known that even the best people fail sometimes, not to mention the ordinary people. In face of the DP-700 exam, everyone stands on the same starting line, and those who are not excellent enough must do more. Every year there are a large number of people who can't pass the DP-700 Exam smoothly. But we are professional in this career for over ten years. And our DP-700 study materials will help you pass the exam easily.
NEW QUESTION # 27
Your company has a team of developers. The team creates Python libraries of reusable code that is used to transform data.
You create a Fabric workspace name Workspace1 that will be used to develop extract, transform, and load (ETL) solutions by using notebooks.
You need to ensure that the libraries are available by default to new notebooks in Workspace1.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.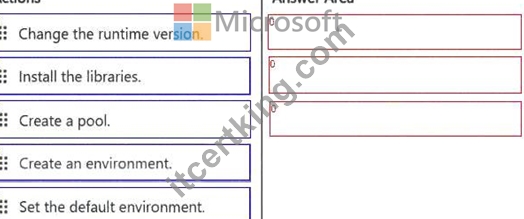
Answer:
Explanation: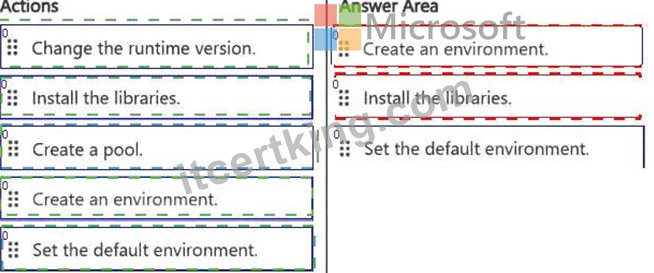
Explanation: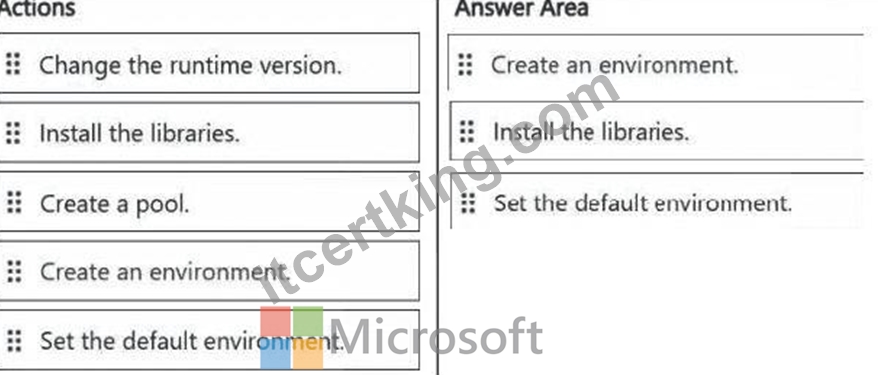
Topic 1, Litware, IncCase Study
This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview
Litware, Inc. is a publishing company that has an online bookstore and several retail bookstores worldwide.
Litware also manages an online advertising business for the authors it represents.
Existing Environment. Fabric Environment
Litware has a Fabric workspace named Workspace1. High concurrency is enabled for Workspace1.
The company has a data engineering team that uses Python for data processing.
Existing Environment. Data Processing
The retail bookstores send sales data at the end of each business day, while the online bookstore constantly provides logs and sales data to a central enterprise resource planning (ERP) system.
Litware implements a medallion architecture by using the following three layers: bronze, silver, and gold. The sales data is ingested from the ERP system as Parquet files that land in the Files folder in a lakehouse.
Notebooks are used to transform the files in a Delta table for the bronze and silver layers. The gold layer is in a warehouse that has V-Order disabled.
Litware has i mag e files of book covers in Azure Blob Storage. The files are loaded into the Files folder.
Existing Environment. Sales Data
Month-end sales data is processed on the first calendar day of each month. Data that is older than one month never changes.
In the source system, the sales data refreshes every six hours starting at midnight each day.
The sales data is captured in a Dataflow Gen1 dataflow. When the dataflow runs, new and historical data is captured. The dataflow captures the following fields of the source:
Sales Date
Author
Price
Units
SKU
A table named AuthorSales stores the sales data that relates to each author. The table contains a column named AuthorEmail. Authors authenticate to a guest Fabric tenant by using their email address.
Existing Environment. Security Groups
Litware has the following security groups:
Sales
Fabric Admins
Streaming Admins
Existing Environment. Performance Issues
Business users perform ad-hoc queries against the warehouse. The business users indicate that reports against the warehouse sometimes run for two hours and fail to load as expected. Upon further investigation, the data engineering team receives the following error message when the reports fail to load: "The SQL query failed while running." The data engineering team wants to debug the issue and find queries that cause more than one failure.
When the authors have new book releases, there is often an increase in sales activity. This increase slows the data ingestion process.
The company's sales team reports that during the last month, the sales data has NOT been up-to-date when they arrive at work in the morning.
Requirements. Planned Changes
Litware recently signed a contract to receive book reviews. The provider of the reviews exposes the data in Amazon Simple Storage Service (Amazon S3) buckets.
Litware plans to manage Search Engine Optimization (SEO) for the authors. The SEO data will be streamed from a REST API.
Requirements. Version Control
Litware plans to implement a version control solution in Fabric that will use GitHub integration and follow the principle of least privilege.
Requirements. Governance Requirements
To control data platform costs, the data platform must use only Fabric services and items. Additional Azure resources must NOT be provisioned.
Requirements. Data Requirements
Litware identifies the following data requirements:
Process the SEO data in near-real-time (NRT).
Make the book reviews available in the lakehouse without making a copy of the data.
When a new book cover image arrives in the Files folder, process the image as soon as possible.
NEW QUESTION # 28
DRAG DROP
You have a Fabric eventhouse that contains a KQL database. The database contains a table named TaxiData.
The following is a sample of the data in TaxiData.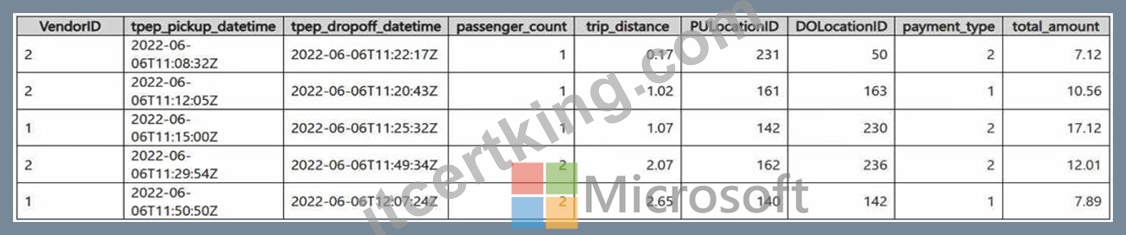
You need to build two KQL queries. The solution must meet the following requirements:
One of the queries must partition RunningTotalAmount by VendorID.
The other query must create a column named FirstPickupDateTime that shows the first value of each hour from tpep_pickup_datetime partitioned by payment_type.
How should you complete each query? To answer, drag the appropriate values the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.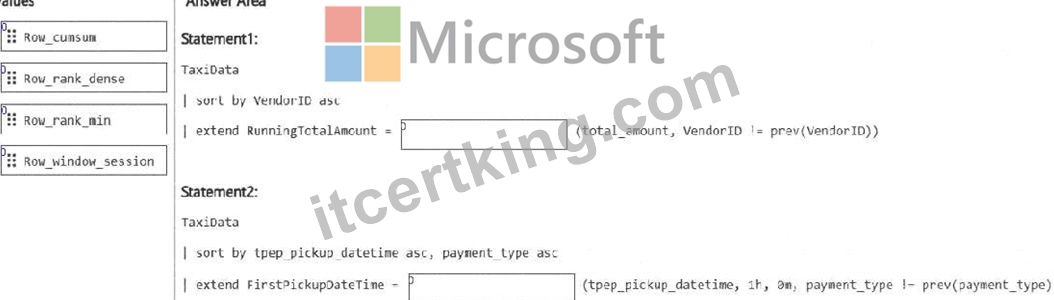
Answer:
Explanation: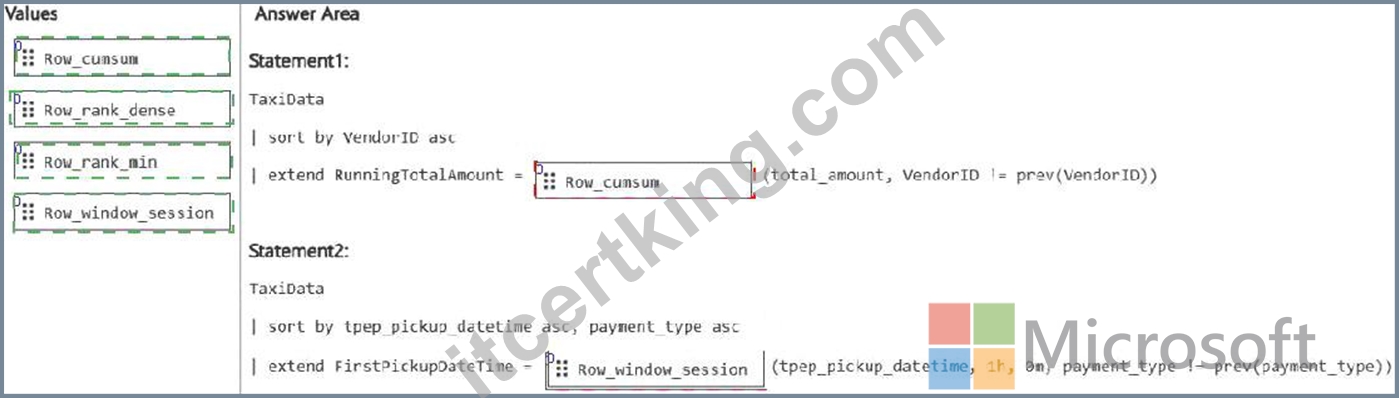
Explanation: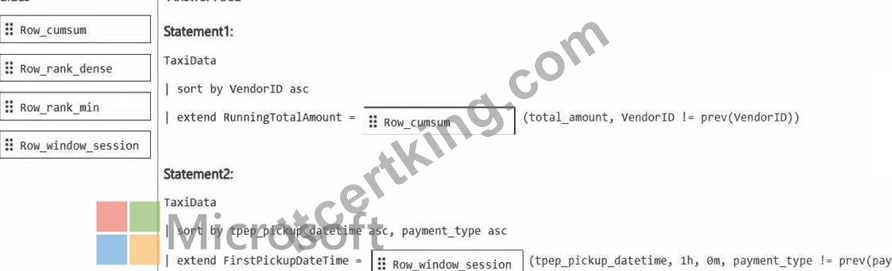
Partition the RunningTotalAmount by VendorID. - Row_cumsum
The Row_cumsum function computes the cumulative sum of a column while optionally restarting the accumulation based on a condition. In this case, it calculates the cumulative sum of total_amount for each VendorID, restarting when the VendorID changes (VendorID != prev(VendorID)).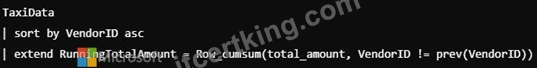
Create a column FirstPickupDateTime that shows the first value of each hour from tpep_pickup_datetime, partitioned by payment_type - Row_window_session
NEW QUESTION # 29
You have a Fabric workspace that contains a warehouse named DW1. DW1 is loaded by using a notebook named Notebook1.
You need to identify which version of Delta was used when Notebook1 was executed.
What should you use?
Answer: E
Explanation:
To identify the version of Delta used when Notebook1 was executed, you should use the Admin monitoring workspace. The Admin monitoring workspace allows you to track and monitor detailed information about the execution of notebooks and jobs, including the underlying versions of Delta or other technologies used. It provides insights into execution details, including versions and configurations used during job runs, making it the most appropriate choice for identifying the Delta version used during the execution of Notebook1.
NEW QUESTION # 30
You have a Fabric workspace that contains a lakehouse named Lakehousel. Lakehousel contains a table named Status_Target that has the following columns:
* Key
* Status
* LastModified
The data source contains a table named Status.Source that has the same columns as Status_Target. Status.Source is used to populate Status_Target. In a notebook name Notebook!, you load Status_Source to a DataFrame named sourceDF and Status_Target to a DataFrame named targetDF. You need to implement an incremental loading pattern by using Notebook-!. The solution must meet the following requirements:
* For all the matching records that have the same value of key, update the value of LastModified in Status_Target to the value of LastModified in Status_Source.
* Insert all the records that exist in Status_Source that do NOT exist in Status_Target.
* Set the value of Status in Status_Target to inactive for all the records that were last modified more than seven days ago and that do NOT exist in Status.Source.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.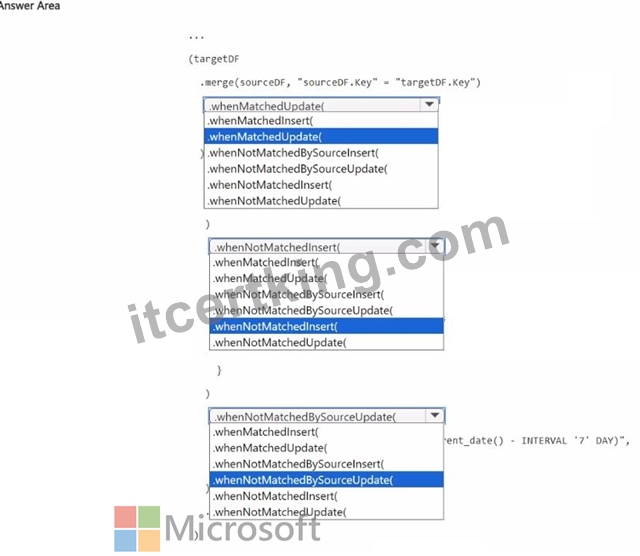
Answer:
Explanation: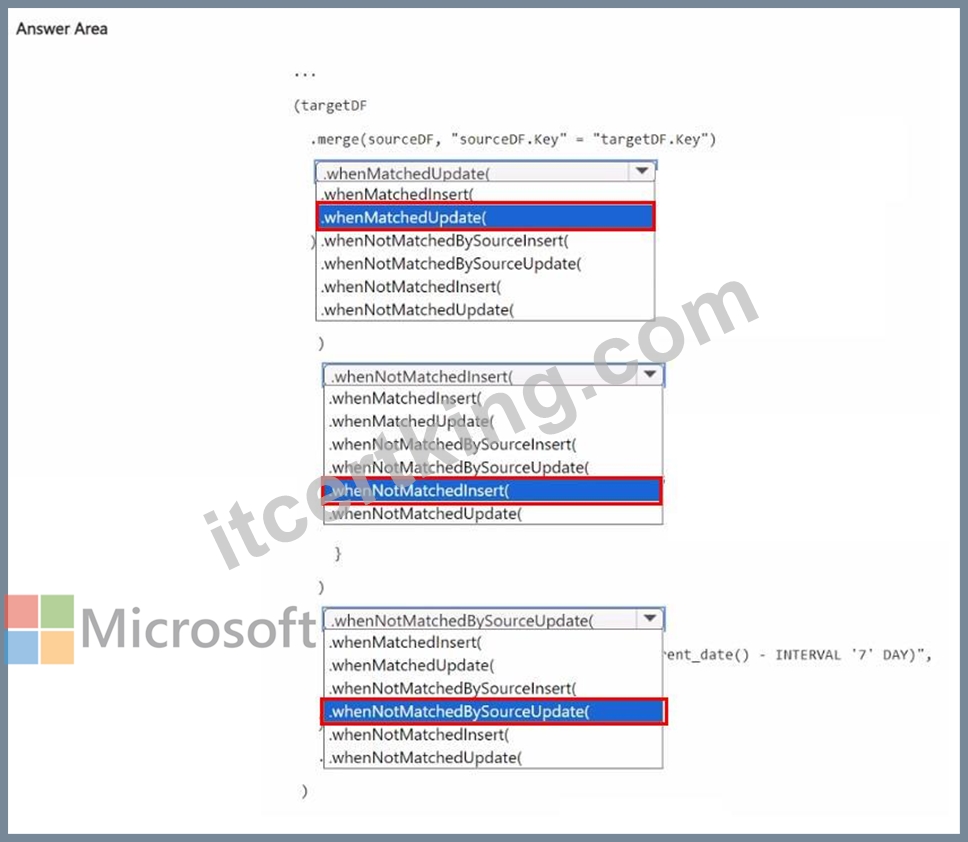
NEW QUESTION # 31
You have a Fabric workspace that contains an eventstream named Eventstream1. Eventstream1 processes data from a thermal sensor by using event stream processing, and then stores the data in a lakehouse.
You need to modify Eventstream1 to include the standard deviation of the temperature.
Which transform operator should you include in the Eventstream1 logic?
Answer: C
Explanation:
To compute the standard deviation of the temperature from the thermal sensor data, you would use the Aggregate transform operator in Eventstream1. The Aggregate operator allows you to apply functions like sum, average, count, and statistical functions like standard deviation across a group of rows or events. This operator is ideal for operations that require summarizing or computing statistics over a dataset, such as calculating the standard deviation.
NEW QUESTION # 32
......
If you do not quickly begin to improve your own strength, the next one facing the unemployment crisis is you. The time is very tight, and choosing DP-700 study questions can save you a lot of time. Without our DP-700 exam braindumps, you may have to find information from the books and online, and it is too broad for you to collect all of them. And at the same time, you have to worry about the validity. But with our DP-700 Practice Engine, your concerns are all solved. Our DP-700 learning guide can offer you the latest and valid exam materials.
DP-700 Reliable Real Exam: https://www.itcertking.com/DP-700_exam.html
What's more, part of that Itcertking DP-700 dumps now are free: https://drive.google.com/open?id=1b2h5-92VOu6HuWREJVKgSGE6p3H4w7Np