In the past ten years, our company has never stopped improving the quality of our Databricks-Generative-AI-Engineer-Associate study materials. For a long time, we have invested much money to perfect our Databricks-Generative-AI-Engineer-Associate exam questions. At the same time, we have introduced the most advanced technology and researchers to perfect our Databricks-Generative-AI-Engineer-Associate Test Torrent. At present, the overall strength of our company is much stronger than before. We are the leader in the market and master the most advanced technology. With our high quality of Databricks-Generative-AI-Engineer-Associate traning guide, you will pass the Databricks-Generative-AI-Engineer-Associate exam for sure.
| Section | Weight | Objectives |
|---|---|---|
| Evaluation and Monitoring | 12% | - Monitor application behavior and outputs - Iterate and improve solutions - Evaluate model and application performance |
| Data Preparation | 14% | - Prepare and process data for LLM use - Implement data pipelines and transformations - Manage data quality and format |
| Governance | 8% | - Manage access and permissions - Apply Unity Catalog for data governance - Ensure compliance and security |
| Assembling and Deploying Apps | 22% | - Package and deploy applications - Manage application lifecycle - Deploy models via Model Serving |
| Design Applications | 14% | - Decompose complex requirements into tasks - Design solution architecture - Select appropriate models, tools and approaches |
| Application Development | 30% | - Use Databricks Vector Search - Develop LLM chains and workflows - Integrate with MLflow - Build RAG applications |
>> New Databricks-Generative-AI-Engineer-Associate Exam Dumps <<
A whole new scope opens up to you and you are immediately hired by reputed firms. Even though the Databricks Databricks-Generative-AI-Engineer-Associate certification boosts your career options, you have to pass the Databricks-Generative-AI-Engineer-Associate Exam. This Databricks Databricks-Generative-AI-Engineer-Associate exam serves to filter out the capable from incapable candidates.
NEW QUESTION # 14
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: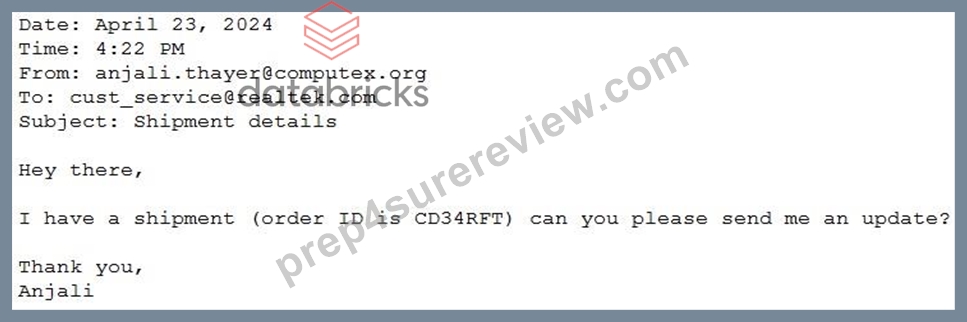
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: A
Explanation:
* Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM's responses.
* Explanation of Options:
Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore, Option B is optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 15
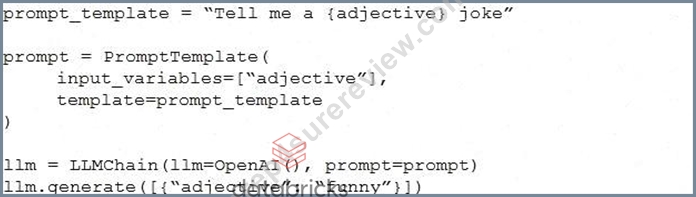
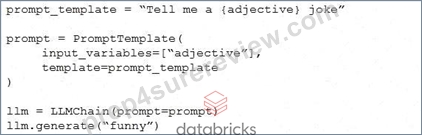
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.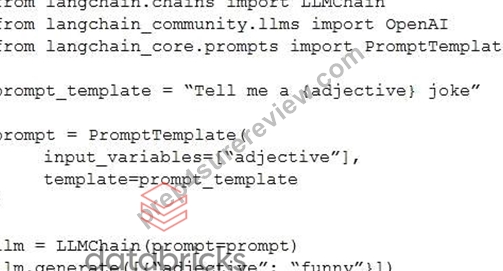
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
Answer: A
Explanation:
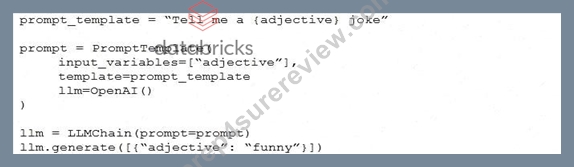
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here ' s a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization : In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods :
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A : Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
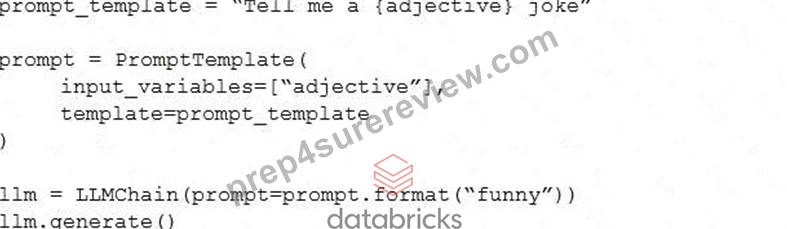
* Option B : Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D : Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain ' s architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 16
A Generative Al Engineer has successfully ingested unstructured documents and chunked them by document sections. They would like to store the chunks in a Vector Search index. The current format of the dataframe has two columns: (i) original document file name (ii) an array of text chunks for each document.
What is the most performant way to store this dataframe?
Answer: C
Explanation:
* Problem Context: The engineer needs an efficient way to store chunks of unstructured documents to facilitate easy retrieval and search. The current dataframe consists of document filenames and associated text chunks.
* Explanation of Options:
* Option A: Splitting into train and test sets is more relevant for model training scenarios and not directly applicable to storage for retrieval in a Vector Search index.
* Option B: Flattening the dataframe such that each row contains a single chunk with a unique identifier is the most performant for storage and retrieval. This structure aligns well with how data is indexed and queried in vector search applications, making it easier to retrieve specific chunks efficiently.
* Option C: Creating a unique identifier for each document only does not address the need to access individual chunks efficiently, which is critical in a Vector Search application.
* Option D: Storing each chunk as an independent JSON file creates unnecessary overhead and complexity in managing and querying large volumes of files.
OptionBis the most efficient and practical approach, allowing for streamlined indexing and retrieval processes in a Delta table environment, fitting the requirements of a Vector Search index.
NEW QUESTION # 17
A Generative Al Engineer is building a system which will answer questions on latest stock news articles.
Which will NOT help with ensuring the outputs are relevant to financial news?
Answer: A
Explanation:
In the context of ensuring that outputs are relevant to financial news, increasing compute power (option B) does not directly improve the relevance of the LLM-generated outputs. Here's why:
Compute Power and Relevancy:
Increasing compute power can help the model process inputs faster, but it does not inherently improve the relevance of the answers. Relevancy depends on the data sources, the retrieval method, and the filtering mechanisms in place, not on how quickly the model processes the query.
What Actually Helps with Relevance:
Other methods, like content filtering, guardrails, or manual review, can directly impact the relevance of the model's responses by ensuring the model focuses on pertinent financial content. These methods help tailor the LLM's responses to the financial domain and avoid irrelevant or harmful outputs.
Why Other Options Are More Relevant:
A (Comprehensive Guardrail Framework): This will ensure that the model avoids generating content that is irrelevant or inappropriate in the finance sector.
C (Profanity Filter): While not directly related to financial relevancy, ensuring the output is clean and professional is still important in maintaining the quality of responses.
D (Manual Review): Incorporating human oversight to catch and correct issues with the LLM's output ensures the final answers are aligned with financial content expectations.
Thus, increasing compute power does not help with ensuring the outputs are more relevant to financial news, making option B the correct answer.
NEW QUESTION # 18
A Generative Al Engineer is setting up a Databricks Vector Search that will lookup news articles by topic within 10 days of the date specified An example query might be "Tell me about monster truck news around January 5th 1992". They want to do this with the least amount of effort.
How can they set up their Vector Search index to support this use case?
Answer: D
Explanation:
The task is to set up a Databricks Vector Search index for news articles, supporting queries like "monster truck news around January 5th, 1992," with minimal effort. The index must filter by topic and a 10-day date range. Let's evaluate the options.
Option A: Split articles by 10-day blocks and return the block closest to the query Pre-splitting articles into 10-day blocks requires significant preprocessing and index management (e.g., one index per block). It's effort-intensive and inflexible for dynamic date ranges.
Databricks Reference: "Static partitioning increases setup complexity; metadata filtering is preferred" ("Databricks Vector Search Documentation").
Option B: Include metadata columns for article date and topic to support metadata filtering Adding date and topic as metadata in the Vector Search index allows dynamic filtering (e.g., date ± 5 days, topic = "monster truck") at query time. This leverages Databricks' built-in metadata filtering, minimizing setup effort.
Databricks Reference: "Vector Search supports metadata filtering on columns like date or category for precise retrieval with minimal preprocessing" ("Vector Search Guide," 2023).
Option C: Pass the query directly to the vector search index and return the best articles Passing the full query (e.g., "Tell me about monster truck news around January 5th, 1992") to Vector Search relies solely on embeddings, ignoring structured filtering for date and topic. This risks inaccurate results without explicit range logic.
Databricks Reference: "Pure vector similarity may not handle temporal or categorical constraints effectively" ("Building LLM Applications with Databricks").
Option D: Create separate indexes by topic and add a classifier model to appropriately pick the best index Separate indexes per topic plus a classifier model adds significant complexity (index creation, model training, maintenance), far exceeding "least effort." It's overkill for this use case.
Databricks Reference: "Multiple indexes increase overhead; single-index with metadata is simpler" ("Databricks Vector Search Documentation").
Conclusion: Option B is the simplest and most effective solution, using metadata filtering in a single Vector Search index to handle date ranges and topics, aligning with Databricks' emphasis on efficient, low-effort setups.
NEW QUESTION # 19
......
To lead a respectable life, our specialists made a rigorously study of professional knowledge about this Databricks-Generative-AI-Engineer-Associate exam. So do not splurge time on searching for the perfect practice materials, because our Databricks-Generative-AI-Engineer-Associate training materials are the best for you. We can assure you the proficiency of our Databricks-Generative-AI-Engineer-Associate Exam Prep. So this is a definitive choice, it means our Databricks-Generative-AI-Engineer-Associate practice quiz will help you reap the fruit of success.
Databricks-Generative-AI-Engineer-Associate Valid Dump: https://www.prep4surereview.com/Databricks-Generative-AI-Engineer-Associate-latest-braindumps.html