Do you want to find a fast way to step towards your dreams? We can help you by providing the latest and best useful CCAR-P pdf torrent to guarantee your success in Anthropic CCAR-P test certification. We keep our CCAR-P vce torrent the latest by checking the newest information about the updated version every day. Add the latest topics into the CCAR-P Dumps, and remove the useless questions, so that your time will be saved and study efficiency will be improved.
| Section | Objectives |
|---|---|
| Governance, Safety, and Risk | - Safety controls and fail-closed system design - Security, compliance, risk management, and governance |
| Stakeholder Engagement and Solution Lifecycle | - Solution lifecycle, handoff, adoption, and operational enablement - Stakeholder discovery and architectural trade-off communication |
| Evaluation and Optimization | - Model and architecture optimization - Evaluation design and acceptance criteria |
| Solution Design | - Claude platform and solution architecture - Model, architecture, context, and deployment strategy selection |
| Enterprise Integration and Production | - Cost, latency, reliability, and operational design - Enterprise integration architecture and production readiness |
The loss of personal information in the information society is indeed very serious, but CCAR-P guide materials can assure you that we will absolutely protect the privacy of every user. Our CCAR-P study braindumps users are all over the world, is a very international product, our CCAR-P Exam Questions are also very good in privacy protection. And we offer good sercives on our CCAR-P learning guide to make sure that every detail is perfect.
NEW QUESTION # 124
You are running a controlled experiment to compare two prompts and must complete the design steps before executing the experiment.
Which two steps must be completed BEFORE running the experiment with random assignment? (Select two.) Each correct answer presents part of the solution.
Answer: B,E
Explanation:
A controlled prompt experiment must begin with a falsifiable hypothesis and a predefined primary metric.
Option C prevents the team from examining results first and then selecting whichever metric makes the candidate look successful. The metric might measure task accuracy, rubric score, citation validity, escalation rate, latency, cost, or another criterion directly connected to the hypothesis.
Option A determines whether the experiment can detect a practically meaningful improvement. The minimum detectable effect expresses the smallest difference worth acting upon, while the power calculation determines the required sample size. Without this step, the experiment may be too small to detect a real improvement or unnecessarily large and expensive.
Random assignment should then distribute representative traffic between the control and candidate prompts while controlling model version, retrieval configuration, tool availability, and other confounding variables.
Options B and D occur after data collection. Option E follows the completed analysis and decision. The team should also define significance thresholds, stopping rules, guardrail metrics, exclusion criteria, and treatment of repeated observations before launch.
Study Guide references/topics: Prompt A/B testing; hypothesis definition; primary metrics; minimum detectable effect; statistical power; random assignment; decision sequencing.
NEW QUESTION # 125
A document analysis service processes legal filings averaging 80,000 tokens each. Each filing is queried by attorneys an average of 14 times during a case. The current architecture sends the full filing on every query.
The CFO has asked you to reduce per-query costs while preserving response quality. The security officer requires that filing contents not be stored outside Fabrikam's tenancy.
Which optimization approach should you recommend?
Answer: C
Explanation:
The 80,000-token filing is a large, stable prefix reused across fourteen requests, making prompt caching the strongest optimization. The first request creates the cache; subsequent identical-prefix requests use lower- priced cache reads while retaining the complete filing, preserving the evidence available to Claude. Anthropic documents cache reads at a fraction of standard input cost and confirms that caches are isolated by organization and, on supported platforms, by workspace. Cached representations remain in memory rather than persistent storage. Options A and C may omit context through summarization or retrieval and therefore require additional quality evaluation. Option D lowers unit cost but may reduce reasoning quality. The design must preserve prefix identity, choose an appropriate TTL, and verify the tenancy configuration.
Study Guide references/topics: Prompt caching ; cache isolation; stable prefixes; long-document analysis; cost optimization.
NEW QUESTION # 126
You are evaluating retrieval-strategy claims used by a peer team.
For each claim, select yes if the statement is generally accurate. Otherwise, select no.
Answer:
Explanation: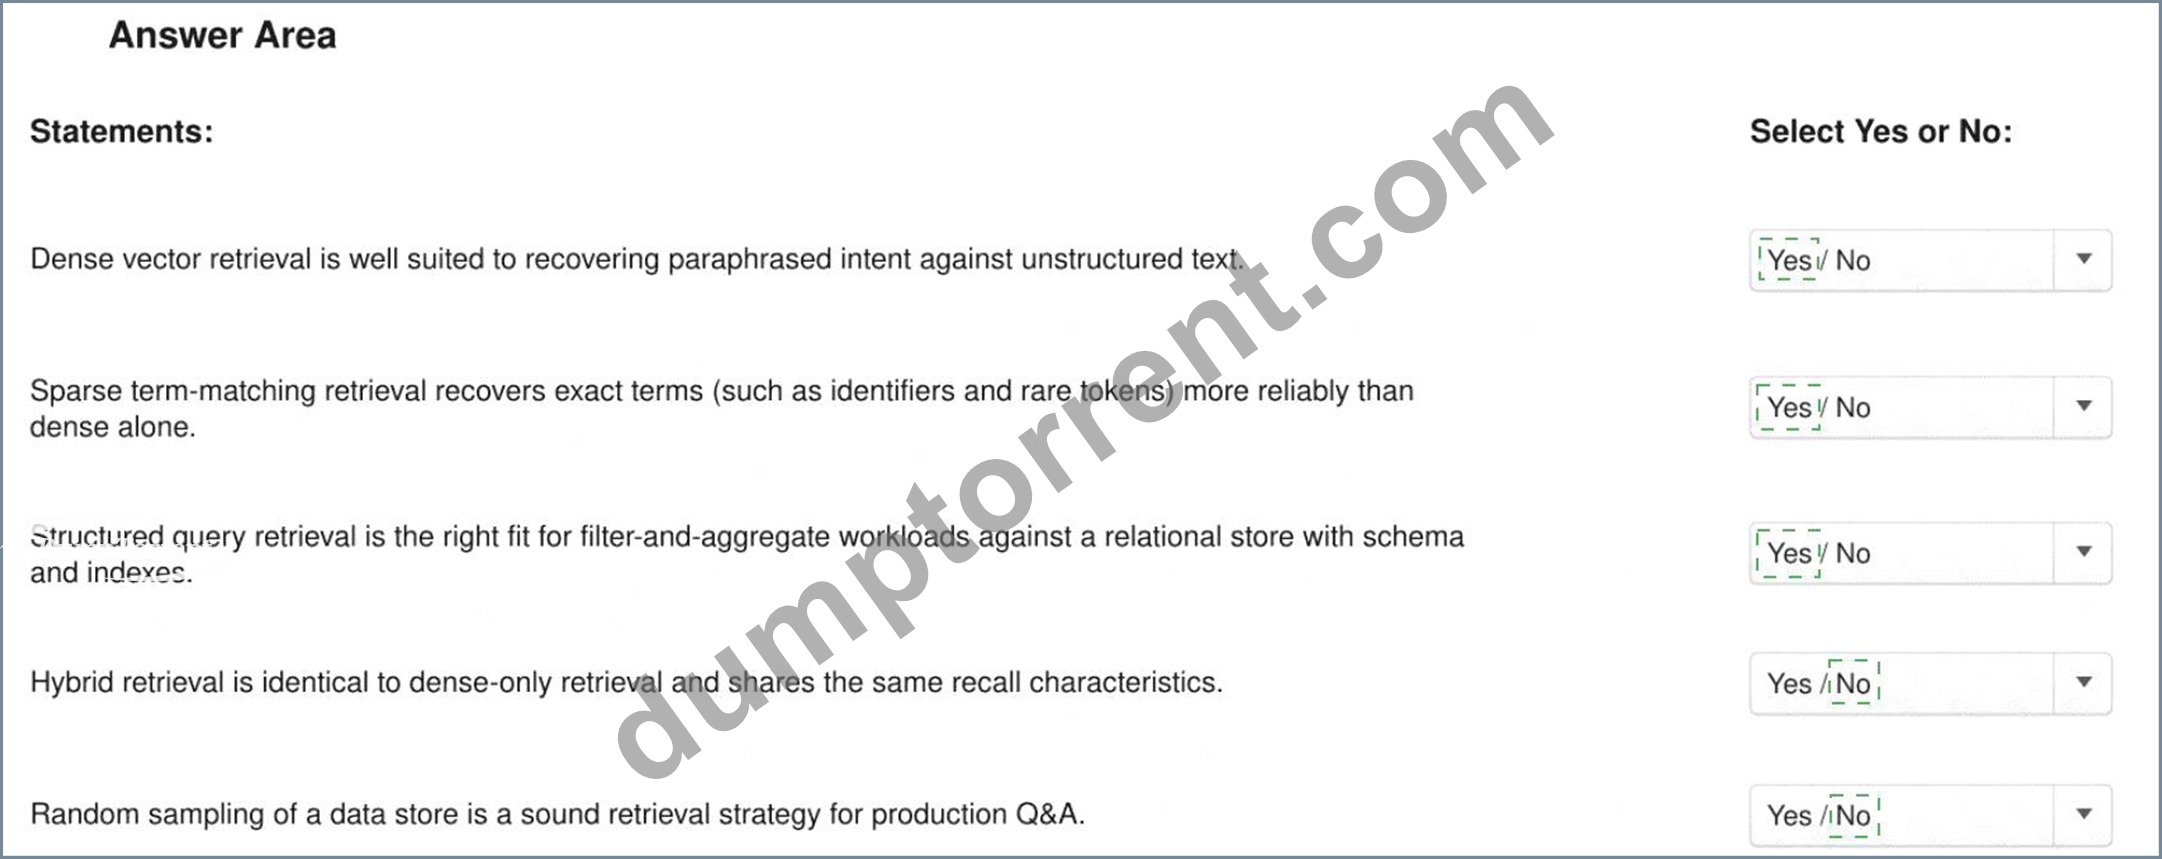
Explanation:
Yes, Yes, Yes, No, No
Dense vector retrieval represents semantic similarity, making it suitable for matching paraphrases and conceptually related language even when the query and source do not share identical words. Sparse lexical retrieval, including BM25-style matching, retains strong sensitivity to exact tokens and is therefore valuable for identifiers, product codes, technical names, and uncommon terminology.
Structured query retrieval is appropriate when the required operation depends on explicit fields, predicates, joins, counts, grouping, or aggregation over a relational schema. In that situation, generating or invoking a constrained database query is more precise than approximating the operation through semantic similarity.
Hybrid retrieval is not identical to dense retrieval. It combines semantic and lexical candidate sets, typically followed by rank fusion or reranking. Anthropic's contextual-retrieval guidance explains that semantic search captures meaning and paraphrases, while BM25 captures exact terminology; combining them improves coverage. Contextual Retrieval, Contextual Retrieval Cookbook Random sampling is not a relevance strategy. It provides no systematic relationship between the query and selected evidence, producing unstable coverage and preventable hallucination risk. Production Q & A requires deterministic or evaluated relevance mechanisms, access filters, suitable indexes, and measurable retrieval metrics such as recall at k.
Study Guide references/topics: Dense retrieval; sparse retrieval; structured queries; hybrid search; rank fusion; retrieval evaluation; production RAG design.
NEW QUESTION # 127
You are reviewing a peer's end-to-end design for a Claude-based platform expected to scale to thousands of concurrent users.
For each statement, indicate Yes if it reflects sound architectural practice. Otherwise, select No.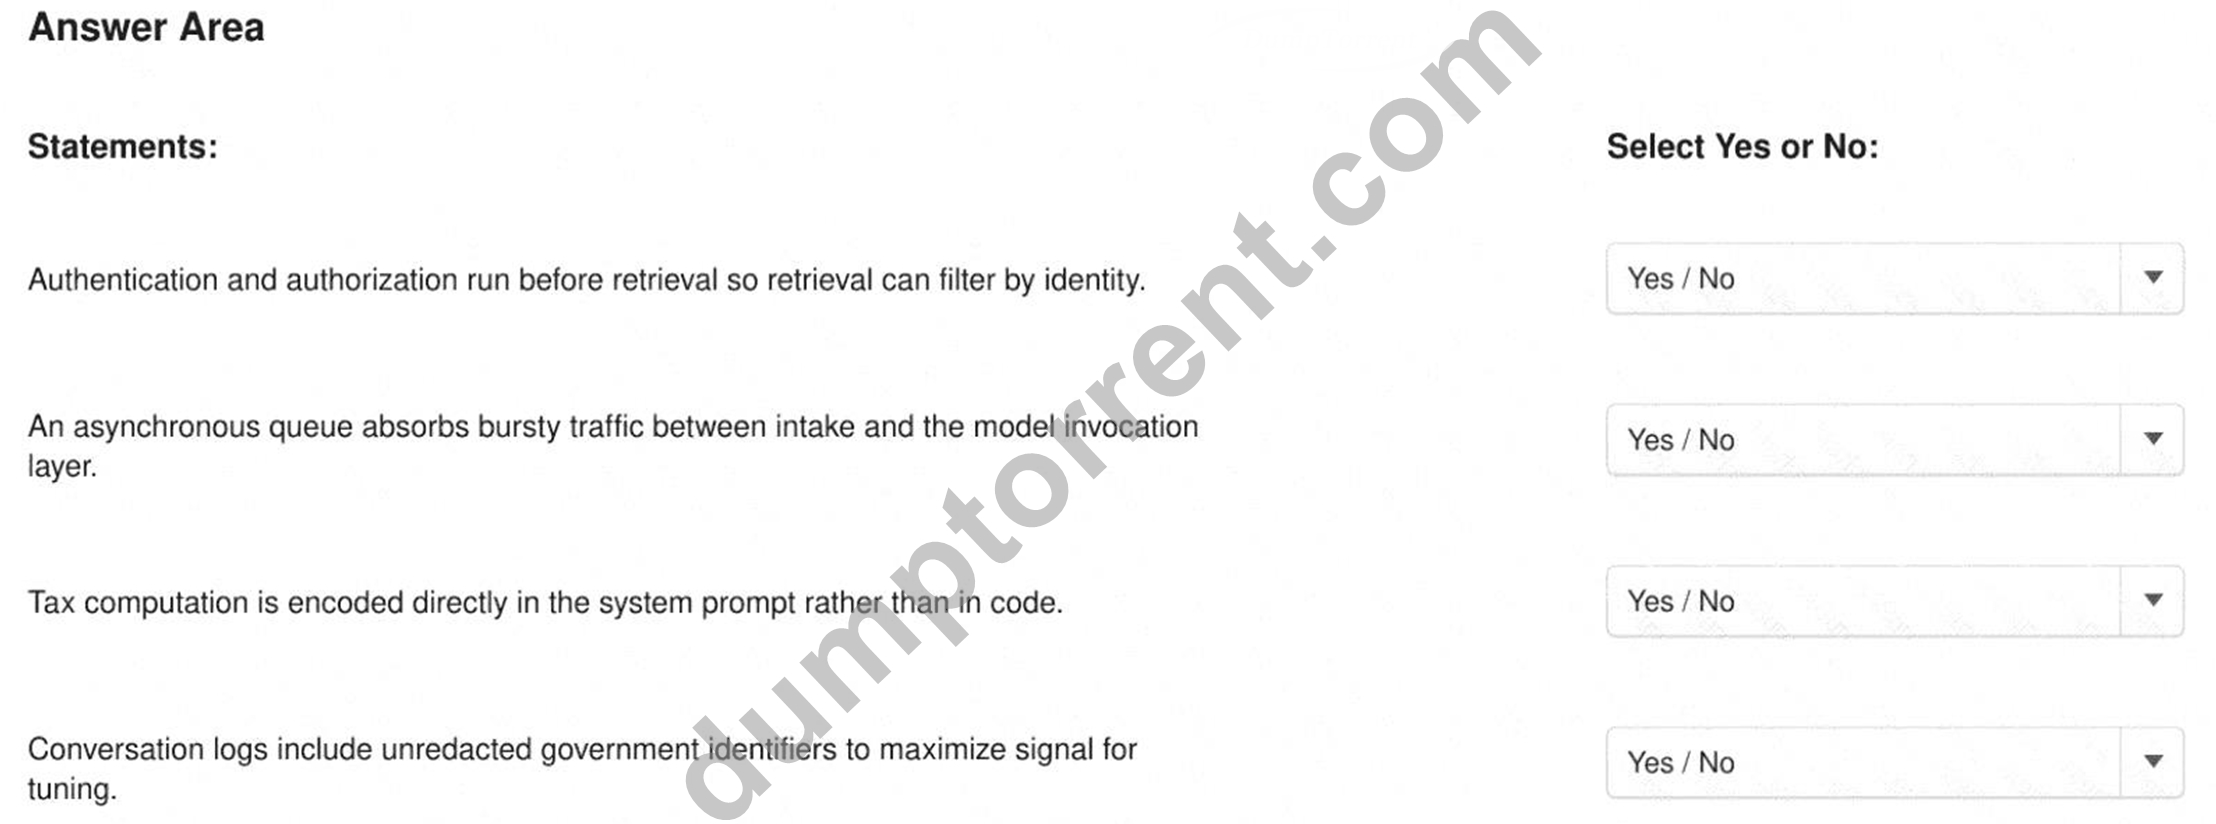
Answer:
Explanation:
Explanation:
Authentication and authorization run before retrieval so retrieval can filter by identity - Yes An asynchronous queue absorbs bursty traffic between intake and the model-invocation layer - Yes Tax computation is encoded directly in the system prompt rather than in code - No Conversation logs include unredacted government identifiers to maximize tuning signal - No Authentication and authorization must precede retrieval so unauthorized information never enters model context. An asynchronous queue is appropriate for burst absorption, backpressure, controlled concurrency, and retry management at scale. Deterministic tax computation should be implemented in validated code or a controlled calculation tool, not delegated to probabilistic prompt interpretation. Including unredacted government identifiers in conversation logs violates data-minimization principles and creates unnecessary privacy, security, and regulatory exposure. Sensitive fields should be removed, tokenized, or redacted before logging or model use unless specifically required and authorized. The resulting design separates deterministic computation, access control, scalable orchestration, and language reasoning into appropriate architectural layers.
NEW QUESTION # 128
You are assessing a Claude-based system whose dominant risk is silent quality drift on safety-relevant outputs after a model-version upgrade.
Which assessment activity most directly addresses this risk?
Answer: A
Explanation:
A stable adversarial regression set provides a controlled basis for detecting behavioral change between model versions. Version-attributed results show whether the proposed upgrade improves, preserves, or degrades performance on the same safety-relevant cases. The evaluation must run before promotion so a regression can block deployment rather than becoming a production incident. Randomly replacing the test inputs removes comparability and makes score changes difficult to attribute. Disabling evaluation or relying on complaints converts a preventable release-control failure into reactive incident handling. Anthropic characterizes regression evaluations as tests of whether an agent still handles tasks it previously completed and recommends maintaining them continuously to detect backsliding. Demystifying evals for AI agents
NEW QUESTION # 129
......
These formats save you from going through sleepless preparation nights and hectic CCAR-P test practice. DumpTorrent CCAR-P practice exams come in these two versions: desktop software and web-based test. A team of experts has approved this CCAR-P practice test after a thorough analysis of the interface and content. The Anthropic CCAR-P Mock Test has a built-in tracker which keeps a record of your progress in each take for you to easily analyze and improve your Anthropic CCAR-P preparation.
CCAR-P Valid Mock Test: https://www.dumptorrent.com/CCAR-P-braindumps-torrent.html