If you use our products, I believe it will be very easy for you to successfully pass your SPS-C01 exam. Of course, if you unluckily fail to pass your exam, don’t worry, because we have created a mechanism for economical compensation. You just need to give us your test documents and transcript, and then our SPS-C01 prep torrent will immediately provide you with a full refund, you will not lose money. More importantly, if you decide to buy our SPS-C01 exam torrent, we are willing to give you a discount, you will spend less money and time on preparing for your exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark Concepts | 15% | - Snowpark architecture and core concepts - Stored procedures and conditional logic - Transformations vs. Actions - Client-side vs. Server-side execution - Snowpark Sessions and connection management - Snowpark DataFrames and query plans |
| Topic 2: Snowpark API for Python | 30% | - Establishing connections and session management - Working with Semi-structured data - DataFrame creation and manipulation - User-Defined Functions (UDFs) and Stored Procedures - Reading and writing data |
| Topic 3: Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Filtering, Aggregating, and Joining DataFrames - Using built-in functions - Window functions - Persisting transformed data |
| Topic 4: Performance Optimization and Best Practices | 20% | - Caching strategies - Minimizing data transfer - Vectorized UDFs - Warehouse sizing for Snowpark - Query pushdown and optimization - Debugging and explain plans |
>> Pass4sure SPS-C01 Pass Guide <<
What do you think of using VCEDumps Snowflake SPS-C01 Exam Dumps? VCEDumps Snowflake SPS-C01 certification training dumps, it may be said, is the most excellent reference materials among all exam-related reference materials. Why? There are four reasons in the following. Firstly, VCEDumps exam dumps are researched by IT experts who used their experience for years and can figure out accurately the scope of the examinations. Secondly, VCEDumps exam dumps conclude all questions that can appear in the real exam. Thirdly, VCEDumps exam dumps ensures the candidate will pass their exam at the first attempt. If the candidate fails the exam, VCEDumps will give him FULL REFUND. Fourthly, VCEDumps exam dumps have two versions: PDF and SOFT version. With the two versions, the candidates can pass their exam with ease.
NEW QUESTION # 364
You have a Snowpark Python stored procedure that performs complex data transformations. This stored procedure needs to read data from a large table ('TRANSACTIONS) and write the transformed data to another table PROCESSED TRANSACTIONS'). You want to optimize the performance of this stored procedure by leveraging Snowpark's features for parallel processing. Which of the following approaches can significantly improve the performance of the stored procedure, assuming sufficient warehouse resources are available?
Answer: B
Explanation:
Using Snowpark DataFrame API along with vectorized UDFs leverages Snowflake's distributed processing capabilities for parallel execution, greatly enhancing performance. Reading the entire table into a Pandas DataFrame (Option B) limits parallelism and can lead to memory issues with large datasets. While SQL queries (Option C) work, they don't fully leverage Snowpark's optimized data transfer and processing. Option D refers to 'session.write_pandas' which isn't accurate in the context of writing transformed Snowpark data to Snowflake tables within the stored procedure. Using a temporary table and standard SQL queries, while functional, doesn't harness the full potential of Snowpark's distributed execution engine as effectively as using the DataFrame API directly (Option E).
NEW QUESTION # 365
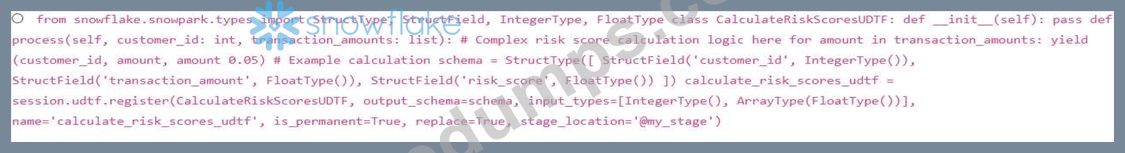
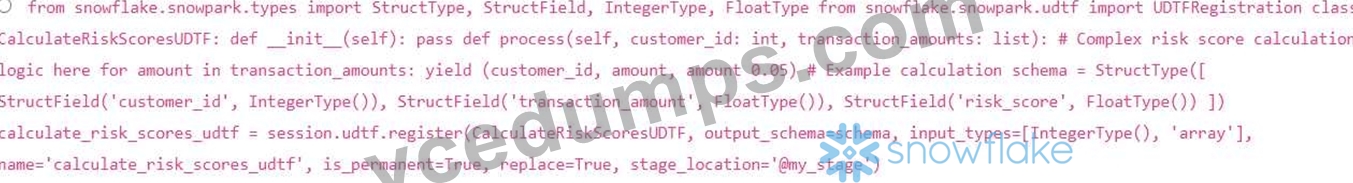
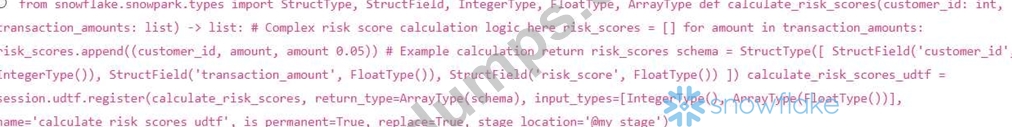
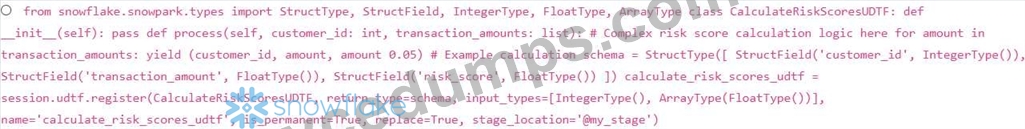
You have developed a Python function that performs complex data transformation on customer data'. You want to operationalize this function as a UDTF in Snowpark to process large datasets efficiently. The function takes a customer ID and a list of transaction amounts as input and returns a table with calculated risk scores for each transaction. Which of the following code snippets correctly defines and registers this UDTF in Snowpark, ensuring proper type handling and scalability?
Answer: C
Explanation:
Options B and C correctly defines the UDTF.Option B uses return_type and option C uses output_schema, both work. Option A is incorrect because a UDTF needs to be defined as a class with a 'process' method that yields rows, not as a function that returns a list. Option D uses an incorrect way to specify ArrayType ('array') . The other options are either syntactically incorrect or do not follow the correct UDTF definition pattern.
NEW QUESTION # 366
You have developed a Snowpark application that processes a large volume of customer interaction data'. The application uses a vectorized UDF to classify the sentiment of text-based interactions. Initial tests show the application is performing slowly. Which of the following strategies would be MOST effective for optimizing the performance of sentiment analysis using a vectorized UDF?
Answer: A
Explanation:
Optimizing the vectorized UDF code itself offers the most direct and significant performance gains for sentiment analysis. By streamlining computations, reducing memory allocations, and avoiding unnecessary function calls within the UDF's vectorized function, the processing time for each batch of data can be substantially reduced. Mini-batching (B) is already implicit with vectorization with pandas series/dataframe. Increaseing Number of cores allocated to the virtual warehouse can provide some help but it depends on other factor also. Other oprions may not have impact
NEW QUESTION # 367
You are developing a Snowpark application that processes large volumes of JSON data from an external stage. Initial testing on a MEDIUM warehouse results in significant query queuing. You suspect the issue is CPU bound due to complex JSON parsing and UDF execution within Snowpark. Considering only warehouse sizing options and assuming cost is a secondary concern to performance during peak processing hours, which strategy is MOST effective for optimizing performance? Consider the impact on concurrency.
Answer: A
Explanation:
Upgrading to a larger warehouse (X-LARGE or higher) provides significantly more CPU resources, which directly addresses the CPU-bound nature of complex JSON parsing and IJDF execution. Scaling out with smaller warehouses (option B) increases concurrency but doesn't necessarily alleviate the CPU bottleneck within individual queries. Materialized Views (option D) can help, but this question is focused on only warehouse sizing options. Option E will almost certainly make things worse. Upgrading to a LARGE could help, but the question asks for the most effective approach. Larger warehouse sizes generally deliver the best performance for intensive workloads.
NEW QUESTION # 368
You've written a Snowpark stored procedure in Python that utilizes a custom Python library named 'my utils.py' containing utility functions for data transformation. This library is not available in Anaconda'. You want to deploy the stored procedure and ensure that the custom library is accessible during execution. Which is the most appropriate way to operationalize your Snowpark stored procedure with the custom library?
Answer: C
Explanation:
Option A is the most appropriate. The 'imports' argument in 'session.sproc.register' is specifically designed for including custom modules and files that are not available through Anaconda. Uploading 'my_utils.py' to a stage and referencing it in the 'imports' argument makes the library available during stored procedure execution. Packaging into a wheel is used for libraries that are available through pypi but may require a specific version. Option C is bad practice, and options D and E are impossible.
NEW QUESTION # 369
......
The customizable mock tests make an image of a real-based Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam which is helpful for you to overcome the pressure of taking the final examination. Customers of VCEDumps can take multiple Snowflake SPS-C01 practice tests and improve their preparation to achieve the SPS-C01 Certification. You can even access your previously given tests from the history, which allows you to be careful while giving the mock test next time and prepare for Snowflake SPS-C01 certification in a better way.
Reliable SPS-C01 Test Online: https://www.vcedumps.com/SPS-C01-examcollection.html