What's more, part of that PracticeMaterial DP-750 dumps now are free: https://drive.google.com/open?id=1Bdvr_Hj4qyD27tgszOzs1_OGNFbQSrKq
Our Implementing Data Engineering Solutions Using Azure Databricks exam question can make you stand out in the competition. Why is that? The answer is that you get the DP-750 certificate. What certificate? Certificates are certifying that you have passed various qualifying examinations. Watch carefully you will find that more and more people are willing to invest time and energy on the DP-750 Exam, because the exam is not achieved overnight, so many people are trying to find a suitable way. Fortunately, you have found our DP-750 real exam materials, which is best for you.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
You will receive DP-750 exam materials immediately after your payment is successful, and then, you can use DP-750 test guide to learn. Everyone knows that time is very important and hopes to learn efficiently, especially for those who have taken a lot of detours and wasted a lot of time. Once they discover DP-750 study braindumps, they will definitely want to seize the time to learn. At the same time, regardless of which mode you use, DP-750 Test Guide will never limit your download times and the number of concurrent users. For the same information, you can use it as many times as you want, and even use together with your friends.
NEW QUESTION # 73
You have an Azure Databricks workspace named Workspace1 that is attached to a Unity Catalog metastore named metastore1 You need to register an Azure Storage account named account1 that has a hierarchical namespace enabled as an external location The external location must use a managed identity to authenticate to account1 and the solution must follow the principle of least privilege.
Which three actions should you perform in sequence' To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.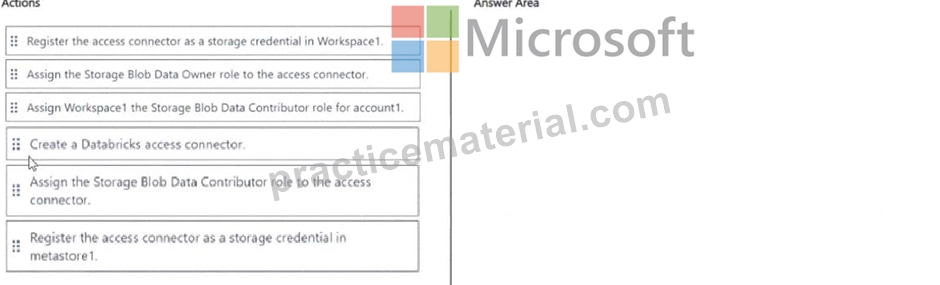
Answer:
Explanation: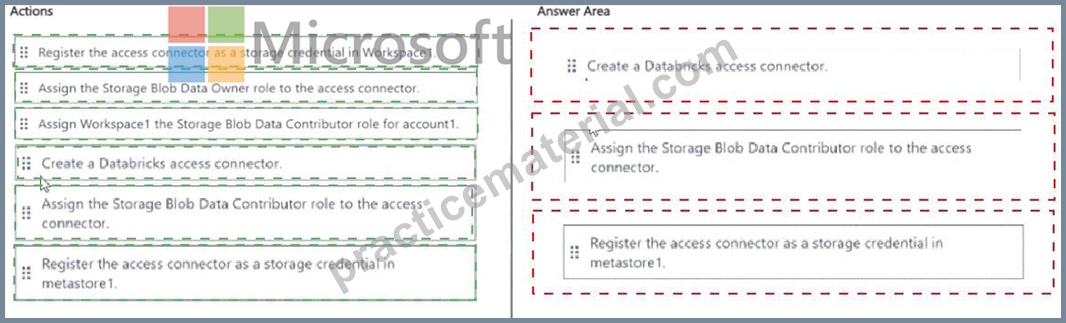
Explanation:
Registering an ADLS Gen2 account as an external location in Unity Catalog requires three steps in a specific order:
Step 1: Create a Databricks Access Connector. This Azure resource wraps a system-assigned or user-assigned managed identity. It is the credential-less authentication bridge between Databricks and Azure Storage - no SAS tokens or access keys are stored anywhere in the workspace.
Step 2: Create a Storage Credential in Unity Catalog that references the Access Connector. This object tells Unity Catalog 'use this identity when accessing storage.' The Storage Credential is the reusable authentication object.
Step 3: Create an External Location that maps a Unity Catalog path to the specific ADLS Gen2 container using the Storage Credential. This is the object that grants Databricks users access to files under that path, and it respects the principle of least privilege by scoping access to a specific container.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/storage-credentials
NEW QUESTION # 74
Which layer contains cleaned and conformed data in Databricks Lakehouse architecture?
Answer: A
Explanation:
Silver layer contains cleaned, validated, and enriched data ready for analytics. Bronze stores raw ingested data. Gold contains aggregated business-level data. Raw is not part of formal medallion architecture naming.
NEW QUESTION # 75
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.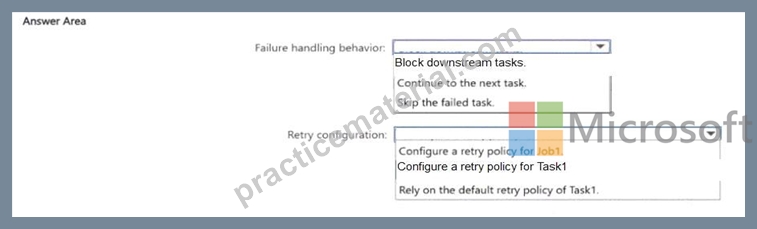
Answer:
Explanation: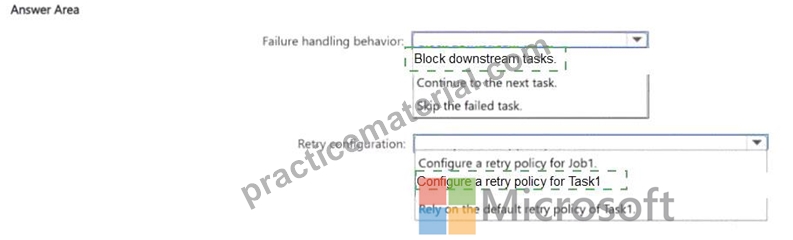
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to 'All succeeded' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2's 'Depends on' setting in the job configuration.
These two settings are independent and composable. Task1's retry policy gives it multiple chances to recover.
Task2's dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
NEW QUESTION # 76
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
* A catalog named Finance
* A schema named Purchases in the Finance catalog
* A table named Transactions in the Purchases schema
You need to ensure that a user named finance_user can query the Transactions table. The solution must follow the principle of least privilege.
Which permission should you grant to finance_user for each object? To answer, drag the appropriate permissions to the correct objects. Each permission may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.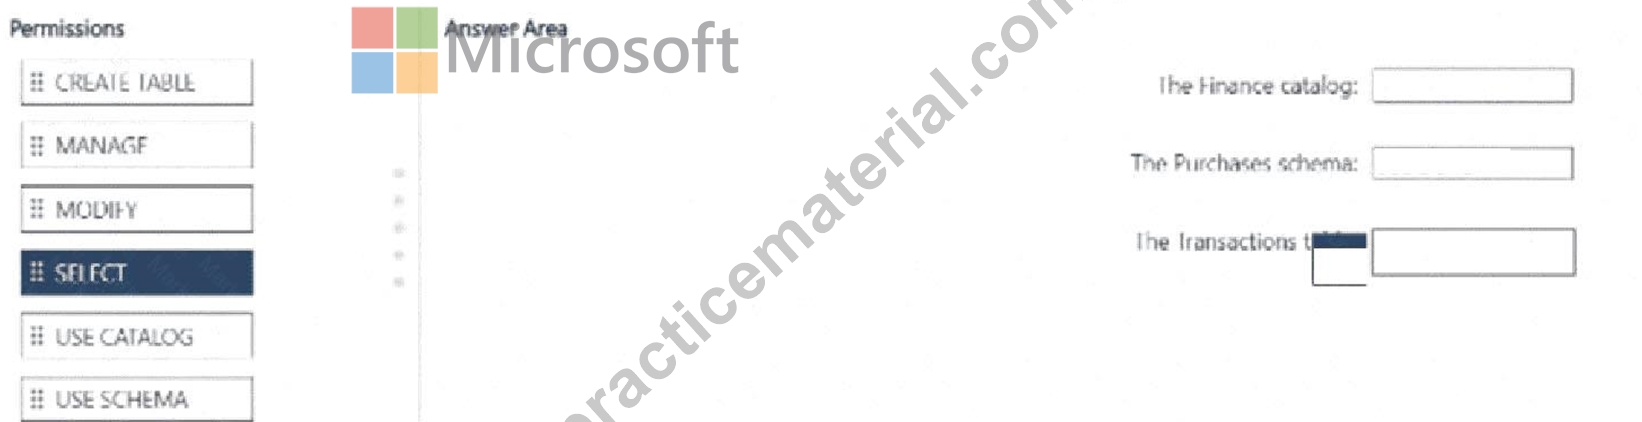
Answer:
Explanation: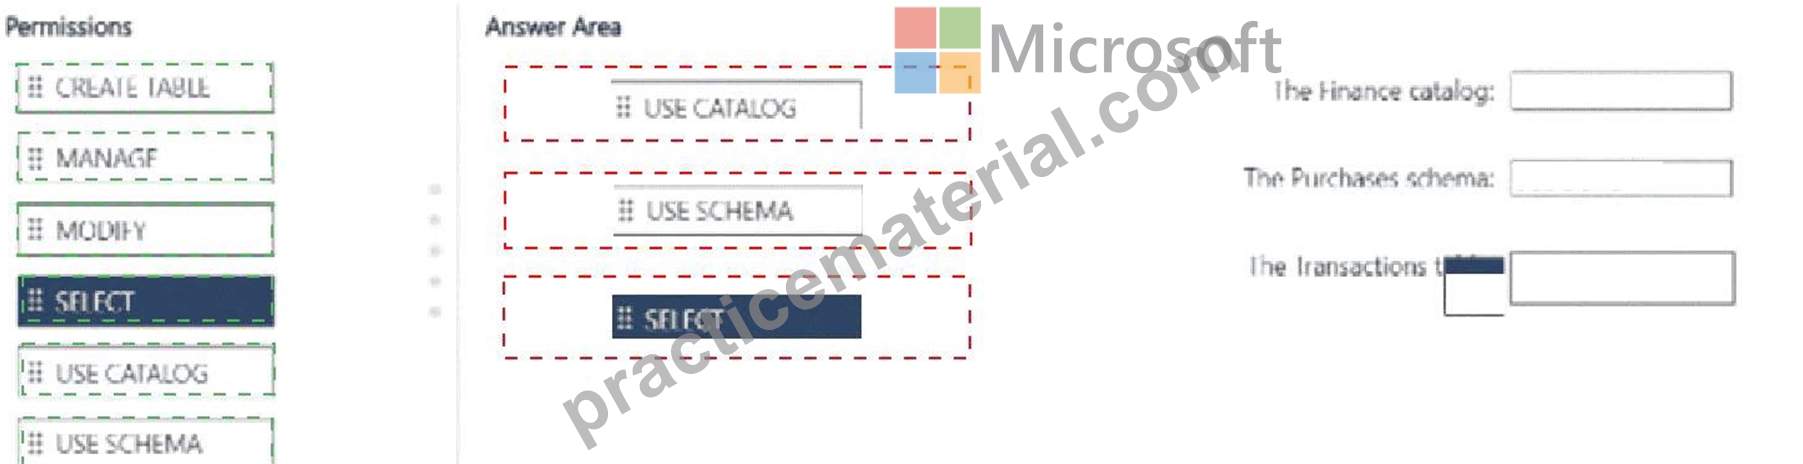
* The Finance catalog: USE CATALOG
* The Purchases schema: USE SCHEMA
* The Transactions table: SELECT
NEW QUESTION # 77
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
Answer: B
Explanation:
The best trigger type for this scenario is the Continuous trigger.
Immediate Processing: The Continuous trigger mode processes new records as soon as they arrive at the configured data sources. This matches your requirement to ingest and process records without waiting for an artificial time interval.
Native Serverless Support: When paired with serverless compute, Lakeflow Jobs efficiently manage resources by automatically scaling up or down according to the real-time stream volume.
Built-in Fault Tolerance: Continuous pipelines on Databricks automatically handle failures by retrying with an exponential backoff policy, keeping your automated ingestion operational 24/7 without manual intervention.
Reference:
https://docs.databricks.com/aws/en/jobs/continuous
NEW QUESTION # 78
......
In the learning process, many people are blind and inefficient for without valid DP-750 exam torrent and they often overlook some important knowledge points which may occupy a large proportion in the DP-750 exam, and such a situation eventually lead them to fail the exam. While we can provide absolutely high quality guarantee for our DP-750 practice materials, for all of our learning materials are finalized after being approved by industry experts. Without doubt, you will get what you expect to achieve, no matter your satisfied scores or according certification file
Dump DP-750 File: https://www.practicematerial.com/DP-750-exam-materials.html
P.S. Free 2026 Microsoft DP-750 dumps are available on Google Drive shared by PracticeMaterial: https://drive.google.com/open?id=1Bdvr_Hj4qyD27tgszOzs1_OGNFbQSrKq