At the same time, DP-750 study material also has a timekeeping function that allows you to be cautious and keep your own speed while you are practicing, so as to avoid the situation that you can't finish all the questions during the exam. With DP-750 Learning Materials, you only need to spend half your money to get several times better service than others. And you can get the DP-750 certification with little effort and money.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Topic 2: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Topic 3: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Topic 4: Prepare and process data | 30–35% | - Ingest and transform data
|
>> Reliable DP-750 Exam Test <<
We provide three versions of DP-750 study materials to the client and they include PDF version, PC version and APP online version. Different version boosts own advantages and using methods. The content of DP-750 exam torrent is the same but different version is suitable for different client. For example, the PC version of DP-750 study materials supports the computer with Windows system and its advantages includes that it simulates real operation exam environment and it can simulates the exam and you can attend time-limited exam on it. And whatever the version is the users can learn the DP-750 Guide Torrent at their own pleasures. The titles and the answers are the same and you can use the product on the computer or the cellphone or the laptop.
NEW QUESTION # 77
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a daily batch data process that requires complex and highly customized Python transformations. The solution must minimize additional complexity.
What should you include in the solution?
Answer: C
Explanation:
A Databricks notebook provides the flexibility required to implement complex, highly customized Python and PySpark transformations. Scheduling that notebook as a Lakeflow Jobs task supplies native daily orchestration, monitoring, retries, and compute management without introducing another service. Azure Data Factory data flows are oriented toward visually designed transformations and would add external orchestration complexity for logic already implemented most naturally in Python. A continuous job is inappropriate because the workload runs once per day rather than continuously. Spark Declarative Pipelines is effective for declarative batch and streaming ETL, but it is less direct when the core requirement emphasizes highly customized procedural Python transformations. A notebook task therefore provides the necessary programming freedom while keeping scheduling and operation inside Azure Databricks.
NEW QUESTION # 78
Drag and Drop Question
You have an Azure Databricks workspace named Workspace1 that is attached to a Unity Catalog metastore named metastore1.
You need to register an Azure Storage account named account1 that has a hierarchical namespace enabled as an external location. The external location must use a managed identity to authenticate to account1 and the solution must follow the principle of least privilege.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.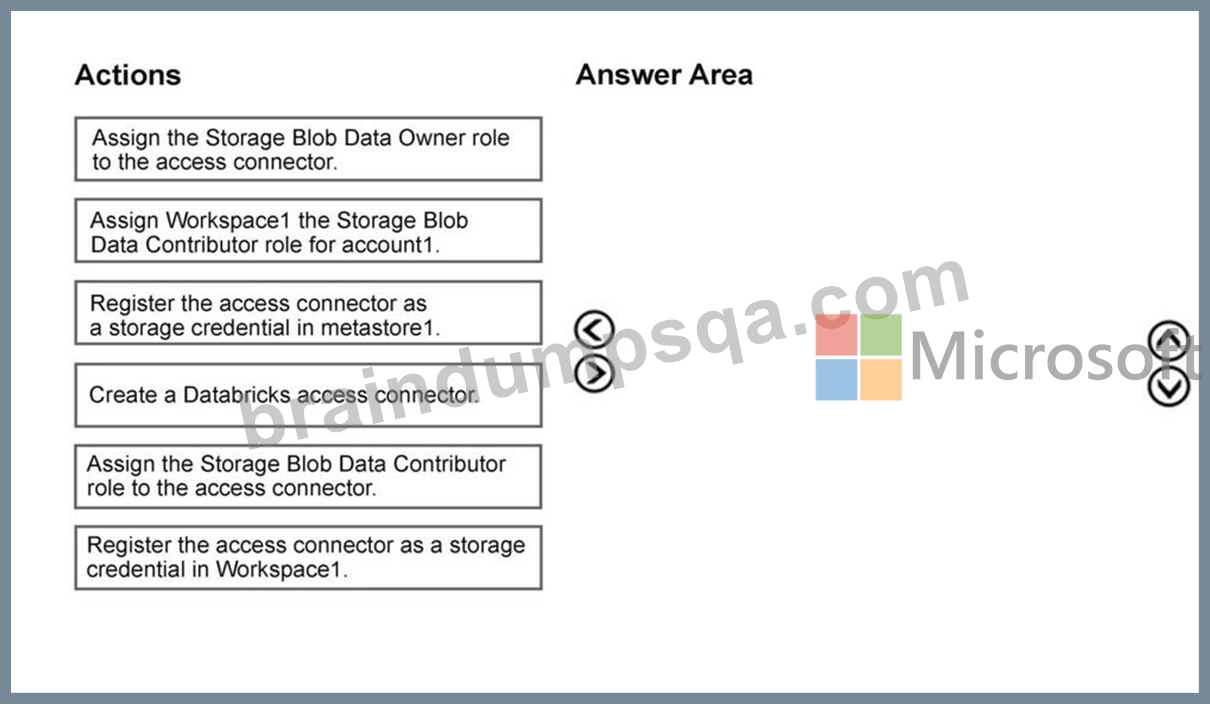
Answer:
Explanation: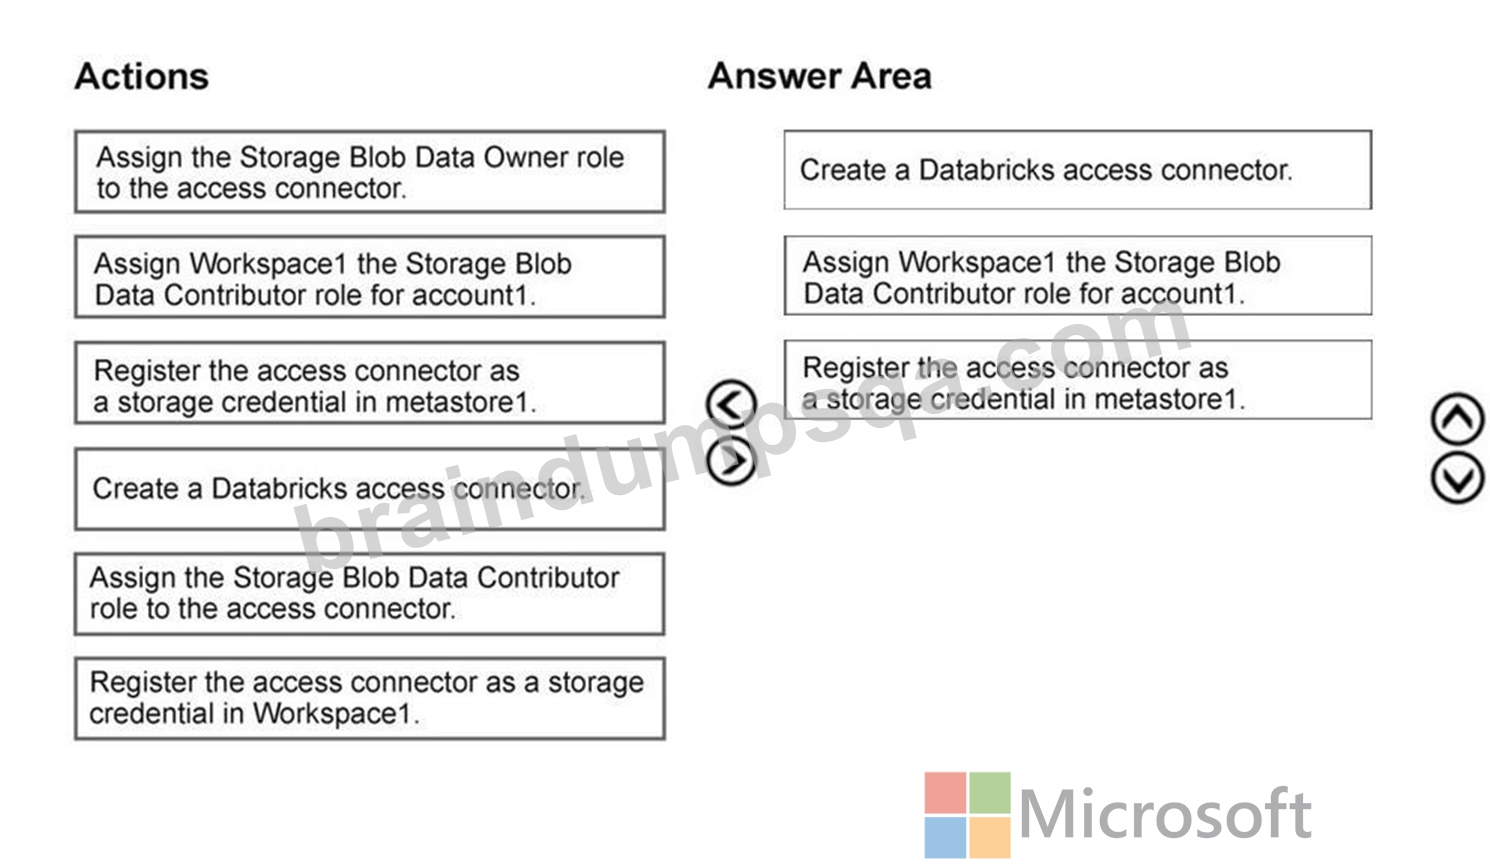
NEW QUESTION # 79
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to ensure that data lineage is captured and can be reviewed for tables accessed by Databricks notebooks and jobs. The solution must minimize administrative effort.
Which compute configuration should you use to capture the data lineage, and what should you use to review the data lineage? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.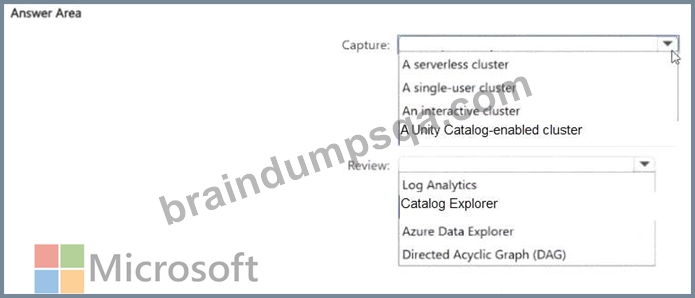
Answer:
Explanation: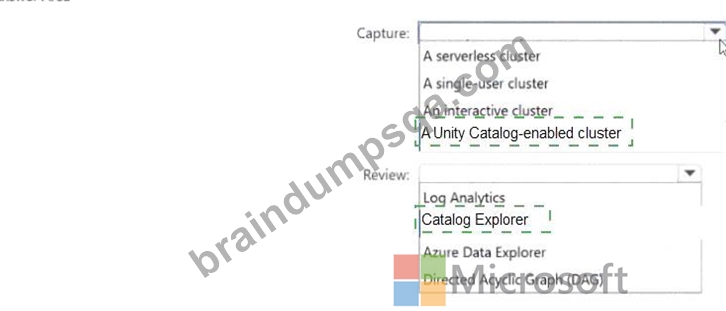
Explanation:
Data lineage in Unity Catalog is captured automatically - but only when jobs and notebooks run on clusters that are Unity Catalog-aware. Specifically, clusters must use 'Shared' or 'Single User' access mode. Clusters set to 'No Isolation Shared' or legacy 'High Concurrency' mode do not emit lineage events to the Unity Catalog lineage service.
No instrumentation, logging code, or external tools are required. The lineage service operates transparently, intercepting read and write operations at the Spark plan level and recording the table-to-table and column-to- column relationships.
To review captured lineage, open Catalog Explorer, navigate to the table, and select the Lineage tab. This shows the upstream sources that populate the table and the downstream consumers that read from it - all as an interactive graph, with no additional tooling needed. This built-in visibility is one of the core governance benefits Unity Catalog provides.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/data-lineage
NEW QUESTION # 80
Hotspot Question
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out-of-memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.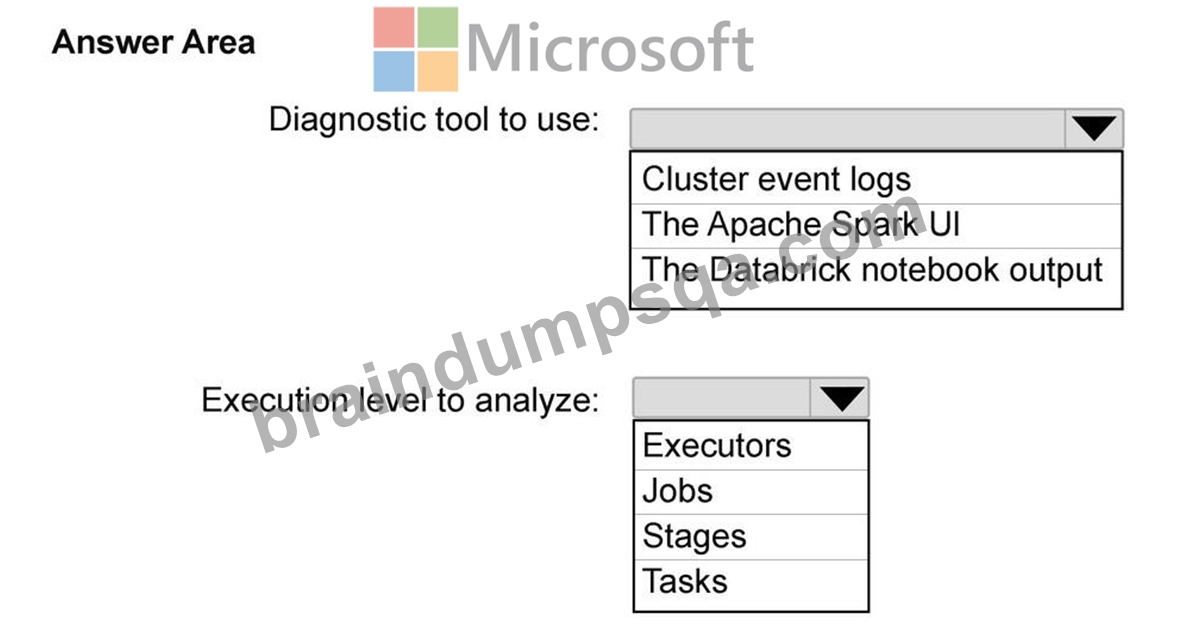
Answer:
Explanation: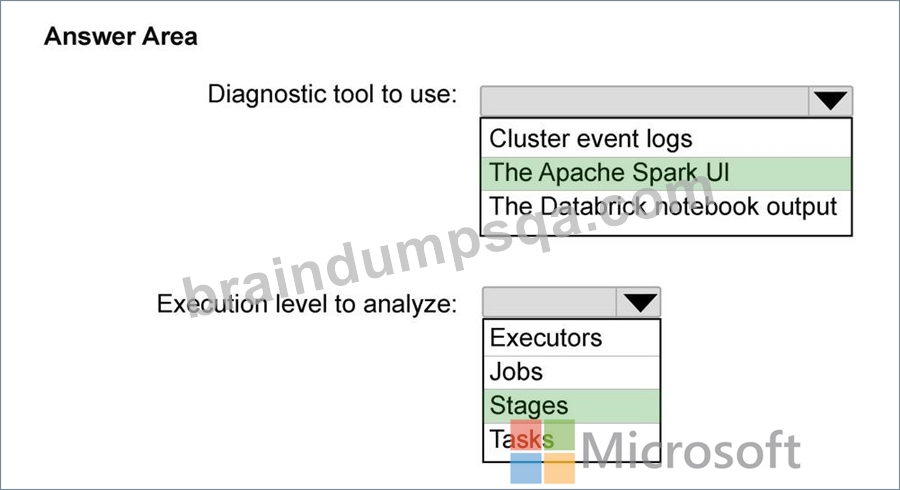
NEW QUESTION # 81
You have an Azure Databricks workspace named Workspace1 that contains a takehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a new native catalog in Unity Catalog. Does this meet the goal?
Answer: B
Explanation:
The correct answer is B - No.
A native catalog in Unity Catalog is a standard Databricks-managed catalog. Creating one provisions a metadata namespace inside Unity Catalog, but it has no connection whatsoever to DB1 or any external SQL Server database. There is no mechanism to point a native catalog at an external database - it simply doesn't serve that purpose.
The requirement is to expose an external SQL Server's schemas and tables inside Unity Catalog without copying the data. That requires a foreign catalog, which is created through Lakehouse Federation using a registered connection to the external database. A foreign catalog acts as a read-only, virtual mirror of the external database - queries run against the live external data in place.
Creating a native catalog and then trying to manually recreate DB1's structure inside it would involve copying all the data, violating the 'data is NOT copied' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
NEW QUESTION # 82
......
When you try our part of Microsoft certification DP-750 exam practice questions and answers, you can make a choice to our Braindumpsqa. We will be 100% providing you convenience and guarantee. Remember that making you 100% pass Microsoft Certification DP-750 Exam is Braindumpsqa.
DP-750 Reliable Test Vce: https://www.braindumpsqa.com/DP-750_braindumps.html