Itcertkr Databricks-Certified-Professional-Data-Engineer 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=19vZ3tlYcIoriIRW27UvfX8SphPX3aO0X
Databricks Databricks-Certified-Professional-Data-Engineer 덤프는 Databricks Databricks-Certified-Professional-Data-Engineer 시험의 모든 문제를 커버하고 있어 시험적중율이 아주 높습니다. Itcertkr는 Paypal과 몇년간의 파트너 관계를 유지하여 왔으므로 신뢰가 가는 안전한 지불방법을 제공해드립니다. Databricks Databricks-Certified-Professional-Data-Engineer시험탈락시 제품비용 전액환불조치로 고객님의 이익을 보장해드립니다.
| Section | Weight | Objectives |
|---|---|---|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
|
| Delta Lake | 20-25% | - Delta Lake operations
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Data Ingestion | 15-20% | - Batch ingestion methods
|
>> Databricks-Certified-Professional-Data-Engineer시험패스 인증덤프자료 <<
Itcertkr에는Databricks Databricks-Certified-Professional-Data-Engineer인증시험의 특별한 합습가이드가 있습니다. 여러분은 많은 시간과 돈을 들이지 않으셔도 많은 IT관련지식을 배우실수 있습니다.그리고 빠른 시일 내에 여러분의 IT지식을 인증 받으실 있습니다. Itcertkr인증자료들은 우리의 전문가들이 자기만의 지식과 몇 년간의 경험으로 준비중인 분들을 위하여 만들었습니다.
질문 # 169
An analytics team wants to run a short-term experiment in Databricks SQL on the customer transactions Delta table (about 20 billion records) created by the data engineering team. Which strategy should the data engineering team use to ensure minimal downtime and no impact on the ongoing ETL processes?
정답:A
설명:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "A shallow clone creates a copy of the metadata that references the source data files; it is fast and inexpensive." Exact extract: "A deep clone copies the data." Exact extract: "Clones provide a point-in-time snapshot for experimentation without impacting the source." A shallow clone of the production Delta table creates an instantaneous snapshot that references the same data files, so it introduces virtually no downtime or storage overhead and avoids interfering with the ongoing ETL. A deep clone would copy all data (very expensive and slow for 20B rows). CTAS rewrites data and is unnecessary; direct access to prod risks contention and accidental changes.
질문 # 170
A data pipeline uses Structured Streaming to ingest data from kafka to Delta Lake. Data is being stored in a bronze table, and includes the Kafka_generated timesamp, key, and value. Three months after the pipeline is deployed the data engineering team has noticed some latency issued during certain times of the day.
A senior data engineer updates the Delta Table's schema and ingestion logic to include the current timestamp (as recoded by Apache Spark) as well the Kafka topic and partition. The team plans to use the additional metadata fields to diagnose the transient processing delays:
Which limitation will the team face while diagnosing this problem?
정답:A
설명:
When adding new fields to a Delta table's schema, these fields will not be retrospectively applied to historical records that were ingested before the schema change. Consequently, while the team can use the new metadata fields to investigate transient processing delays moving forward, they will be unable to apply this diagnostic approach to past data that lacks these fields.
:
Databricks documentation on Delta Lake schema management: https://docs.databricks.com/delta/delta-batch.
html#schema-management
질문 # 171
Two of the most common data locations on Databricks are the DBFS root storage and external object storage mounted with dbutils.fs.mount().
Which of the following statements is correct?
정답:E
설명:
Explanation
DBFS is a file system protocol that allows users to interact with files stored in object storage using syntax and guarantees similar to Unix file systems1. DBFS is not a physical file system, but a layer over the object storage that provides a unified view of data across different data sources1. By default, the DBFS root is accessible to all users in the workspace, and the access to mounted data sources depends on the permissions of the storage account or container2. Mounted storage volumes do not need to have full public read and write permissions, but they do require a valid connection string or access key to be provided when mounting3. Both the DBFS root and mounted storage can be accessed when using %sh in a Databricks notebook, as long as the cluster has FUSE enabled4. The DBFS root does not store files in ephemeral block volumes attached to the driver, but in the object storage associated with the workspace1. Mounted directories will persist saved data to external storage between sessions, unless they are unmounted or deleted3. References: DBFS, Work with files on Azure Databricks, Mounting cloud object storage on Azure Databricks, Access DBFS with FUSE
질문 # 172
A data team ' s Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.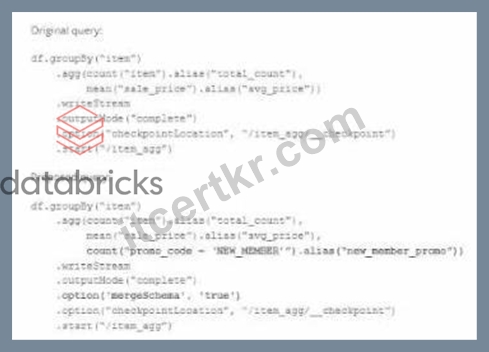
Which step must also be completed to put the proposed query into production?
정답:D
설명:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
:
Databricks documentation on Structured Streaming: https://docs.databricks.com/spark/latest/structured- streaming/index.html Databricks documentation on streaming checkpoints: https://docs.databricks.com/spark/latest/structured- streaming/production.html#checkpointing
질문 # 173
The business reporting team requires that data for their dashboards be updated every hour. The total processing time for the pipeline that extracts, transforms, and loads the data for their pipeline runs in 10 minutes. Assuming normal operating conditions, which configuration will meet their service-level agreement requirements with the lowest cost?
정답:C
설명:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "Job clusters are created for a job run and terminate when the job completes." Exact extract: "All-purpose (interactive) clusters are intended for interactive development and collaboration." An hourly batch that completes in ~10 minutes is best run on ephemeral job clusters so compute exists only during execution and auto-terminates afterward, minimizing cost while meeting the hourly SLA. Interactive clusters persist (incurring idle cost). Structured Streaming for an hourly refresh adds continuous compute cost with no benefit here. Event-driven triggers are unnecessary for a simple hourly SLA.
Reference:
질문 # 174
......
Itcertkr는Databricks Databricks-Certified-Professional-Data-Engineer인증시험을 아주 쉽게 패스할 수 있도록 도와드리는 사이트입니다. Itcertkr의 엘리트한 전문가가 끈임 없는 노력으로 최고의Databricks Databricks-Certified-Professional-Data-Engineer자료를 만들었습니다. 이 자료로 여러분은 100%Databricks의Databricks-Certified-Professional-Data-Engineer인증시험을 패스할 수 있으며, Itcertkr을 선택함으로 성공을 선택한 것입니다. Itcertkr가 제공하는 시험가이드로 효과적인 학습으로 많은 분들이 모두 인증시험을 패스하였습니다. 이건 모두 Itcertkr 인증시험덤프로 공부하였기 때문입니다. 그 중Databricks Databricks-Certified-Professional-Data-Engineer인증시험을 패스한 분들도 모두 Itcertkr인증시험덤프를 사용하였기 때문입니다.
Databricks-Certified-Professional-Data-Engineer최신 인증시험 기출문제: https://www.itcertkr.com/Databricks-Certified-Professional-Data-Engineer_exam.html
참고: Itcertkr에서 Google Drive로 공유하는 무료, 최신 Databricks-Certified-Professional-Data-Engineer 시험 문제집이 있습니다: https://drive.google.com/open?id=19vZ3tlYcIoriIRW27UvfX8SphPX3aO0X