学ぶことは遅すぎることはありません。あなたは引き続き勉強したい場合、DP-800認定試験資格証明書を取得する機会があります。そのほかに、多くの人がDP-800認定試験に合格しました後、成功し、幸せになりました。給料が高い仕事を見つけたからです。あなたは決してこの有難い機会をあきらめないで、早くDP-800学習材料を買いましょう!
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
最新のDP-800準備資料は、DP-800試験に最短時間で合格して、最も重要なテストの難易度をマスターし、学習効率を向上させたい場合に役立ちます。また、一生懸命勉強して、資格試験に合格し、DP-800証明書を取得することは、もはや夢ではありません。これらの条件で、あなたはインタビューから目立ち、あなたが待っていた仕事を得ることができます。ただし、リアルタイムの雇用プロセスでは、ユーザーも自分自身を豊かにすることを学び続ける必要があります。 DP-800の練習教材を学ぶには、勝利が近づいています。
質問 # 95
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.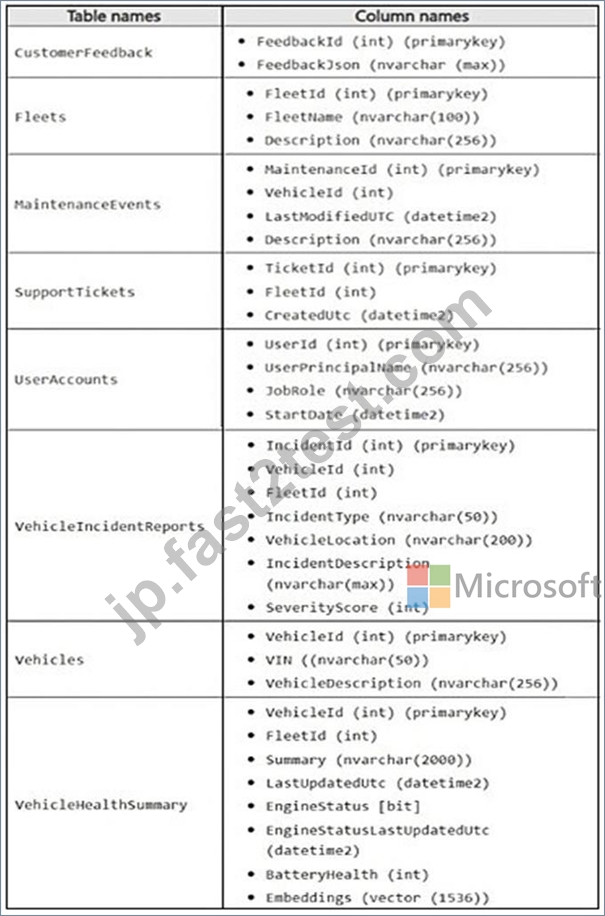
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.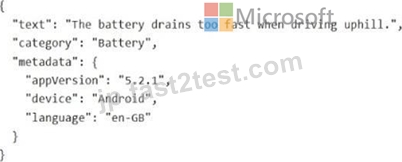
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.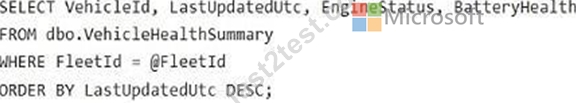
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to recommend a solution for the development team to retrieve the live metadata. The solution must meet the development requirements. What should you include in the recommendation?
正解:B
解説:
Scenario: Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
To retrieve live metadata from Azure SQL databases and use it with GitHub Copilot in Visual Studio Code (VS Code), you must use the SQL Server (mssql) extension. This extension provides the native capability to extract a database schema as a .dacpac file directly within the editor.
1. Export the Schema as a .dacpac File
You can extract the schema of your live Azure SQL database using the SQL Server (mssql) extension.
2. Load the .dacpac into GitHub Copilot Context
Once the .dacpac file is saved in your VS Code workspace, you can provide it as context to GitHub Copilot Chat using #-mentions or Drag & Drop.
Reference:
https://learn.microsoft.com/en-us/sql/tools/sql-database-projects/concepts/data-tier- applications/extract-dacpac-from-database
質問 # 96
You have an Azure SQL database named DB1 that contains two tables named knowledgebase and query_cache. knowledge_base contains support articles and embeddings. query_cache contains chat questions, responses, and embeddings DB1 supports an Al-enabled chat agent.
You need to design a solution that meets the following requirements:
* Serializes the retrieved rows from knowledee_base
* Extracts the answer field from the response
* Extracts the embeddings to store in query_cache
You will call the external large language model (LLM) by using the sp_irwoke_external_re standpoint stored procedure.
Which Transact-SGL commands should you use for each requirement? To answer, drag the appropriate commands to the correct requirements. Each command may be used once, mote than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
正解:
解説:
Explanation:
The correct mapping is:
* FOR JSON PATH
* JSON_VALUE
* JSON_QUERY
To serialize the retrieved rows from knowledge_base , the correct command is FOR JSON PATH .
Microsoft documents that FOR JSON formats query results as JSON, and PATH mode is the standard way to shape relational rows into JSON for downstream application or AI use.
To extract the answer field from the response , the correct command is JSON_VALUE because answer is a single scalar field . Microsoft states that JSON_VALUE is used to extract a scalar value from JSON text.
To extract the embeddings to store in query_cache , the correct command is JSON_QUERY because embeddings are returned as a JSON array , not a scalar. Microsoft states that JSON_QUERY extracts an object or array from JSON text, which is exactly the right behavior for an embeddings payload.
The unused options are not the best fit here:
* OPENJSON is mainly for shredding JSON into rows and columns.
* AI_GENERATE_CHUNKS is for chunking text, not extracting fields from a response payload.
* VECTOR_DISTANCE computes similarity between vectors and is unrelated to JSON extraction.
* FOR XML PATH produces XML, not JSON.
質問 # 97
You need to recommend a solution for the TransactionProcessing application that meets the security requirements.
What should you include in the recommendation?
正解:C
解説:
A). A service principal is the correct answer.
The critical requirements are that TransactionProcessing operates on-premises and must establish a passwordless connection to Azure SQL Database DB1.
A Microsoft Entra service principal provides an application identity that can authenticate to Azure SQL Database without relying on a hard-coded SQL username and password.
Technical implementation:
* Register TransactionProcessing as an application in Microsoft Entra ID and create its service principal.
* Configure certificate-based authentication instead of storing a client secret or SQL password in the connection string.
* Configure Microsoft Entra authentication for Azure SQL Database and create a database user mapped to the service principal.
* Grant the application only the required database permissions.
* Obtain a Microsoft Entra access token and use it to authenticate to DB1.
Microsoft documentation confirms that Azure SQL supports application authentication through service principals using certificates or client secrets.
Why the other options are incorrect:
* B. System-assigned managed identity: Requires an appropriately configured hosting resource. On- premises servers can support this through Azure Arc, but that configuration is not specified.
* C. Shared access key: Not a supported Azure SQL Database authentication mechanism.
* D. User-assigned managed identity: Requires a supported identity-assignment or federation configuration not described in the scenario.
DP-800 Official Study Guide Reference:
Main topic: Secure, optimize, and deploy database solutions.
Subtopic: Implement data security and compliance.
Specific examination objective: " Implement secure database access, including passwordless. "
質問 # 98
You have a GitHub Enterprise subscription.
Your team is developing an Azure SQL dataset solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
A mix of GitHub Copilot instructions is configured at different levels, including organization-wide, repository-wide, agent-specific, and personal.
Which instructions will take precedence over the others?
正解:A
解説:
In a GitHub Enterprise environment, personal instructions (user-level) generally have the highest precedence for individual interactions in VS Code.
Order of Precedence
When GitHub Copilot processes instructions, it follows a "specific-to-general" hierarchy. The most specific context (the individual user) typically overrides broader organizational settings.
1. Personal Instructions
Set via .github/copilot-instructions.md in your local home directory or VS Code settings.
Overrides all other layers for your specific session.
2. Agent-Specific / Extension Instructions
Specific instructions provided to a custom agent (like @workspace or a custom Chat participant).
3. Repository-wide Instructions
Stored in the .github/copilot-instructions.md file within the specific repository.
4. Organization-wide Policies
Set by Enterprise/Org admins. These usually act as "guardrails" (e.g., blocking suggestions) rather than stylistic instructions.
Reference:
https://aiddbot.com/vscode-and-github-copilot
質問 # 99
You have an Azure container app named app1-contoso-001 that hosts a Data API builder (DAB) container in front of an Azure SQL database.
You add an entity named Todo that uses a source named dbo.todos.
Which URL pattern should clients use to access the Todo REST endpoint?
正解:C
解説:
The correct answer is B because Data API builder exposes REST entities by default using the URL pattern:
https://{base_url}/api/{entity}
Microsoft's current DAB documentation states exactly that the default REST endpoint pattern is /api/{entity}
. For an entity named Todo , the REST route is therefore /api/Todo .
The other options are incorrect:
* A uses a GraphQL-style route and is not the REST endpoint.
* C uses /data-api/Todo , which is not the default REST path for a directly hosted DAB runtime.
* D adds an unnecessary /data-api prefix before /api/Todo .
Microsoft also shows examples such as:
GET https://localhost:5001/api/book
and documents collection reads as:
GET /api/{entity} .
So for the entity configuration:
* Entity name: Todo
* Source: dbo.todos
the REST endpoint path is:
/api/Todo
Therefore, among the supplied choices, Option B is the correct answer.
質問 # 100
......
Developing AI-Enabled Database Solutions試験の質問は、競争で際立ったものにすることができます。何故ですか?答えは、DP-800証明書を取得することです。どんな証明書?証明書は、さまざまな資格試験に合格したことを証明します。試験は一晩で行われず、多くの人が適切な方法を見つけようとしているため、DP-800試験に時間と労力を費やす人が増えていることがわかります。幸いなことに、DP-800の実際の試験材料が見つかりました。これはあなたに最適です。
DP-800問題トレーリング: https://jp.fast2test.com/DP-800-premium-file.html