Databricks Databricks-Certified-Data-Engineer-Professional PDF Questions - An Easy Way To Prepare For Exam

Prep4sures offers a complete Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) practice questions in PDF format. This Databricks Databricks-Certified-Data-Engineer-Professional test questions pdf file format is simple to use and can be accessed from any device, including a desktop, tablet, laptop, Mac, or smartphone. No matter where you are, you can learn on the go. The PDF version of the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam questions is also readily printable, allowing you to keep tangible copies of the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) questions with you at all times.
| Section | Weight | Objectives |
|---|
| Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance
- Secure data at rest and in transit
- Implement access control and permissions
|
| Debugging and Deploying | 10% | - Troubleshoot and debug pipelines
- Implement CI/CD and DevOps practices
- Deploy using Asset Bundles, CLI, and APIs
|
| Data Governance | 7% | - Use Unity Catalog for governance
- Manage data assets and metadata
- Enforce data policies and standards
|
| Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads
- Use Auto Loader and structured streaming
- Ingest data from diverse sources
|
| Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management
- Enforce data quality standards
- Apply data cleansing and validation rules
|
| Monitoring and Alerting | 10% | - Set up alerts and notifications
- Monitor pipeline performance and health
- Track data lineage and metrics
|
| Data Sharing and Federation | 5% | - Use Delta Sharing for secure data sharing
- Implement Lakehouse Federation
- Manage cross-platform data access
|
| Data Modelling | 6% | - Implement dimensional and relational models
- Optimize table design and partitioning
- Design Medallion Architecture
|
| Cost & Performance Optimisation | 13% | - Apply cost management best practices
- Improve query and pipeline performance
- Optimize compute and storage resources
|
| Developing Code for Data Processing using Python and SQL | 22% | - Use Databricks-specific libraries and APIs
- Write efficient and maintainable code
- Implement complex data processing logic
|
>> Databricks-Certified-Data-Engineer-Professional Reliable Test Answers <<
Exam Databricks-Certified-Data-Engineer-Professional Material, Valid Braindumps Databricks-Certified-Data-Engineer-Professional Book
Experts at Prep4sures have also prepared Databricks Databricks-Certified-Data-Engineer-Professional practice exam software for your self-assessment. This is especially handy for preparation and revision. You will be provided with an examination environment and you will be presented with actual exam Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions. This sort of preparation method enhances your knowledge which is crucial to excelling in the actual Databricks Databricks-Certified-Data-Engineer-Professional certification exam.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q209-Q214):
NEW QUESTION # 209
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
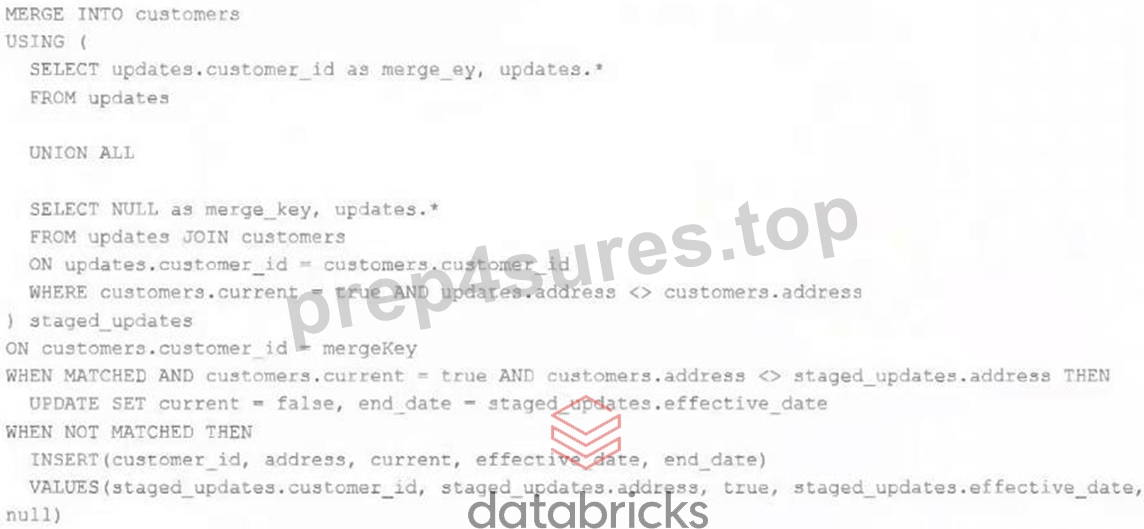
Which statement describes this implementation?
- A. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
- B. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
- C. The customers table is implemented as a Type 3 table; old values are maintained as a new column alongside the current value.
- D. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
- E. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
Answer: B
NEW QUESTION # 210
What statement is true regarding the retention of job run history?
- A. It is retained for 90 days or until the run-id is re-used through custom run configuration
- B. It is retained until you export or delete job run logs
- C. t is retained for 60 days, during which you can export notebook run results to HTML
- D. It is retained for 30 days, during which time you can deliver job run logs to DBFS or S3
- E. It is retained for 60 days, after which logs are archived
Answer: C
Explanation:
https://docs.databricks.com/en/workflows/jobs/monitor-job-runs.html
NEW QUESTION # 211
A data engineer needs to install the PyYAML Python package within an air-gapped Databricks environment. The workspace has no direct internet access to PyPI. The engineer has downloaded the .whl file locally and wants it available automatically on all new clusters. Which approach should the data engineer use?
- A. Set up a private PyPI repository and install via pip index URL.
- B. Add the .whl file to Databricks Git Repos and assume automatic installation.
- C. Upload the PyYAML .whl file to a Unity Catalog Volume, ensure it's allow-listed, and create a cluster-scoped init script that installs it from that path.
- D. Upload the PyYAML .whl file to the user home directory and create a cluster-scoped init script to install it.
Answer: C
Explanation:
For secure, air-gapped Databricks deployments, the recommended practice is to host dependency files such as .whl packages in Unity Catalog Volumes -- a managed storage layer governed by Unity Catalog.
Once stored in a volume, these files can be safely referenced from cluster-scoped init scripts, which automatically execute installation commands (e.g., pip install
/Volumes/catalog/schema/path/PyYAML.whl) during cluster startup.
This ensures consistent environment setup across clusters and compliance with data governance rules.
User directories (A) lack enterprise security controls; private repositories (C) are not viable in air- gapped setups; and Git repos (D) do not trigger package installation. Therefore, B is the correct and officially approved method.
NEW QUESTION # 212
A Delta Lake table representing metadata about content from user has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE Based on the above schema, which column is a good candidate for partitioning the Delta Table?
- A. Date
- B. Post_time
- C. latitude
- D. Post_id
- E. User_id
Answer: A
Explanation:
Partitioning a Delta Lake table improves query performance by organizing data into partitions based on the values of a column. In the given schema, the date column is a good candidate for partitioning for several reasons:
Time-Based Queries: If queries frequently filter or group by date, partitioning by the date column can significantly improve performance by limiting the amount of data scanned. Granularity: The date column likely has a granularity that leads to a reasonable number of partitions (not too many and not too few). This balance is important for optimizing both read and write performance.
Data Skew: Other columns like post_id or user_id might lead to uneven partition sizes (data skew), which can negatively impact performance.
Partitioning by post_time could also be considered, but typically date is preferred due to its more manageable granularity.
NEW QUESTION # 213
When monitoring a complex workload, being able to see the query plan is critical to understanding what the workload is doing. Where can the visualization of the query plan be found?
- A. In the Spark UI, under the SQL/DataFrame tab
- B. In the Spart UI, under the Jobs tab
- C. In the Query Profiler, under Query Source
- D. In the Query Profiler, under the Stages tab
Answer: A
Explanation:
The Spark UI provides detailed visibility into how queries are executed. The SQL/DataFrame tab displays the logical and physical query plans, allowing engineers to visualize execution details and understand how the workload is processed across stages and operators.
NEW QUESTION # 214
......
To lead a respectable life, our specialists made a rigorously study of professional knowledge about this Databricks-Certified-Data-Engineer-Professional exam. So do not splurge time on searching for the perfect practice materials, because our Databricks-Certified-Data-Engineer-Professional training materials are the best for you. We can assure you the proficiency of our Databricks-Certified-Data-Engineer-Professional Exam Prep. So this is a definitive choice, it means our Databricks-Certified-Data-Engineer-Professional practice quiz will help you reap the fruit of success.
Exam Databricks-Certified-Data-Engineer-Professional Material: https://www.prep4sures.top/Databricks-Certified-Data-Engineer-Professional-exam-dumps-torrent.html
- Pass Guaranteed Quiz Databricks - Databricks-Certified-Data-Engineer-Professional Authoritative Reliable Test Answers ▶ Copy URL ⏩ www.easy4engine.com ⏪ open and search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ to download for free 👠Databricks-Certified-Data-Engineer-Professional Brain Exam
- Databricks-Certified-Data-Engineer-Professional Reliable Real Exam 🕉 Demo Databricks-Certified-Data-Engineer-Professional Test 👧 Databricks-Certified-Data-Engineer-Professional Valid Test Practice 🩲 Immediately open { www.pdfvce.com } and search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 to obtain a free download 👾Latest Databricks-Certified-Data-Engineer-Professional Questions
- Authoritative Databricks-Certified-Data-Engineer-Professional Reliable Test Answers - Leader in Certification Exams Materials - Trusted Exam Databricks-Certified-Data-Engineer-Professional Material 🦚 Open website ▶ www.dumpsmaterials.com ◀ and search for “ Databricks-Certified-Data-Engineer-Professional ” for free download 🎠Latest Databricks-Certified-Data-Engineer-Professional Exam Preparation
- Interactive Databricks-Certified-Data-Engineer-Professional Questions 🟠 Latest Databricks-Certified-Data-Engineer-Professional Questions 💍 Interactive Databricks-Certified-Data-Engineer-Professional Questions ✳ Copy URL ➠ www.pdfvce.com 🠰 open and search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ to download for free 🧟New Databricks-Certified-Data-Engineer-Professional Exam Vce
- Latest Databricks-Certified-Data-Engineer-Professional Exam Preparation 😒 Databricks-Certified-Data-Engineer-Professional Brain Exam 🛃 Databricks-Certified-Data-Engineer-Professional Brain Exam 🕘 Download ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ for free by simply searching on ▛ www.vce4dumps.com ▟ 🏮New Databricks-Certified-Data-Engineer-Professional Test Preparation
- Latest Databricks-Certified-Data-Engineer-Professional Exam Preparation 🔁 Databricks-Certified-Data-Engineer-Professional Valid Test Practice 🛐 Latest Databricks-Certified-Data-Engineer-Professional Questions 🗽 ➡ www.pdfvce.com ️⬅️ is best website to obtain “ Databricks-Certified-Data-Engineer-Professional ” for free download 🏃Demo Databricks-Certified-Data-Engineer-Professional Test
- Databricks-Certified-Data-Engineer-Professional Brain Exam 🗺 Learning Databricks-Certified-Data-Engineer-Professional Mode 🎦 Latest Databricks-Certified-Data-Engineer-Professional Questions 👡 Download ➥ Databricks-Certified-Data-Engineer-Professional 🡄 for free by simply entering ▷ www.troytecdumps.com ◁ website 🚮Databricks-Certified-Data-Engineer-Professional Downloadable PDF
- Quiz 2026 Databricks Databricks-Certified-Data-Engineer-Professional: Fantastic Databricks Certified Data Engineer Professional Exam Reliable Test Answers 🧡 Open 【 www.pdfvce.com 】 enter ➠ Databricks-Certified-Data-Engineer-Professional 🠰 and obtain a free download 🥐Learning Databricks-Certified-Data-Engineer-Professional Mode
- Access Real www.practicevce.com Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions Easily in dumps PDF Form 🎩 Open ➤ www.practicevce.com ⮘ and search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ to download exam materials for free 📿Databricks-Certified-Data-Engineer-Professional Valid Test Practice
- Authoritative Databricks-Certified-Data-Engineer-Professional Reliable Test Answers - Leader in Certification Exams Materials - Trusted Exam Databricks-Certified-Data-Engineer-Professional Material 🥔 Search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ and easily obtain a free download on ▶ www.pdfvce.com ◀ 🕌Databricks-Certified-Data-Engineer-Professional Free Practice
- Databricks-Certified-Data-Engineer-Professional Reliable Test Answers | High Pass-Rate Exam Databricks-Certified-Data-Engineer-Professional Material: Databricks Certified Data Engineer Professional Exam 🌞 Open website ▛ www.easy4engine.com ▟ and search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 for free download 📗Demo Databricks-Certified-Data-Engineer-Professional Test
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, gifyu.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes