BTW, DOWNLOAD part of BraindumpsVCE AI-103 dumps from Cloud Storage: https://drive.google.com/open?id=19UEQFS8Ggq6gQWI2RrU1P96BxmLzaZ-o
It is a truism that an internationally recognized AI-103 certification can totally mean you have a good command of the knowledge in certain areas. If you are overwhelmed by workload heavily and cannot take a breath from it, why not choose our AI-103 preparation torrent? We are specialized in providing our customers with the most reliable and accurate exam materials and help them pass their exams by achieve their satisfied scores. With our AI-103 practice materials, your exam will be a piece of cake.
| Section | Weight | Objectives |
|---|---|---|
| Plan and manage Azure AI solutions | 25–30% | - Design Azure AI infrastructure
|
| Implement computer vision solutions | 10–15% | - Build multimodal solutions
|
| Implement information extraction and knowledge mining | 10–15% | - Extract structured data from documents
|
| Implement generative AI and agentic solutions | 30–35% | - Build generative AI applications
|
| Implement text and speech analysis solutions | 10–15% | - Implement natural language processing
|
You only need 20-30 hours to practice our software materials and then you can attend the exam. It costs you little time and energy. The AI-103 exam questions are easy to be mastered and simplified the content of important information. The AI-103 test guide conveys more important information with amount of answers and questions, thus the learning for the examinee is easy and highly efficient. So it is convenient for the learners to master the AI-103 Guide Torrent and pass the AI-103 exam in a short time.
NEW QUESTION # 12
You have a Microsoft Foundry project that contains a model deployment.
You have an application that calls the deployment by using the Azure OpenAl v1 API and DefaultAzureCredential.
The developers at your company receive HTTP 403 errors when they send inference requests, even after running az login.
You need to ensure that the developers can perform model inference. The solution must follow the principle of least privilege.
Which role-based access control (RBAC) role should you assign to the developers?
Answer: D
Explanation:
The correct role is Cognitive Services OpenAl User . The application is using DefaultAzureCredential, so az login only proves the developer's Microsoft Entra identity and enables token acquisition. It does not by itself grant authorization to the model deployment. Azure OpenAI and Microsoft Foundry separate authentication from authorization; Microsoft Entra ID provides token-based authentication, while Azure RBAC controls whether the signed-in principal can perform data-plane actions such as model inference. Microsoft's Foundry guidance states that Microsoft Entra ID supports granular RBAC and that data-plane operations include runtime usage such as chat completions and embedding generation.
For Azure OpenAI resources, the Cognitive Services OpenAI User role specifically allows users to make inference API calls with Microsoft Entra ID against deployed models, while preventing higher-privilege actions such as creating deployments, copying keys, fine-tuning, or managing the resource.
The other roles are not least privilege. Contributor grants broad management-plane permissions. Cognitive Services User is broader and less specific than the Azure OpenAI inference role. Cognitive Services Data Reader is read-oriented and does not provide the required model inference data action. Reference topics:
Microsoft Foundry authentication and authorization, Azure RBAC, Microsoft Entra ID keyless authentication, Azure OpenAI v1 API, and least-privilege model inference.
NEW QUESTION # 13
You are creating an enrichment pipeline that will use Azure Al Search. The knowledge store contains unstructured JSON data and the text from scanned PDF documents.
Which projection type should you use for each data type? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.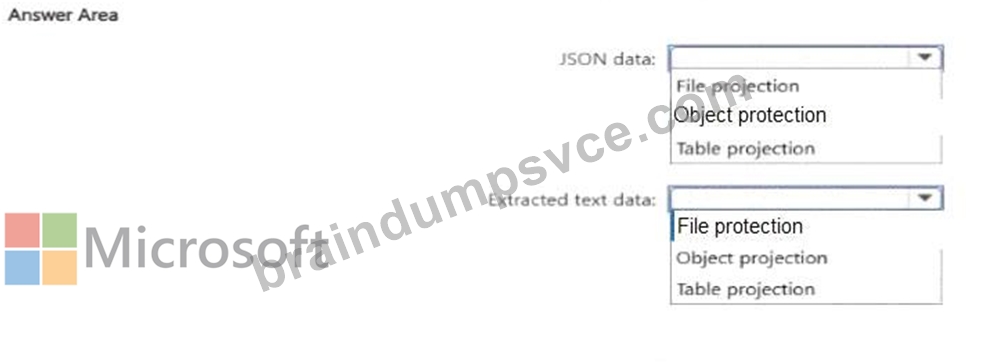
Answer:
Explanation: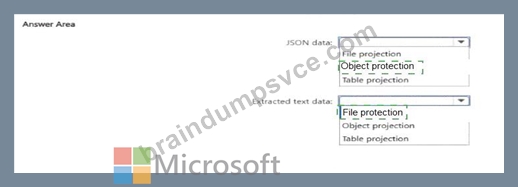
Explanation: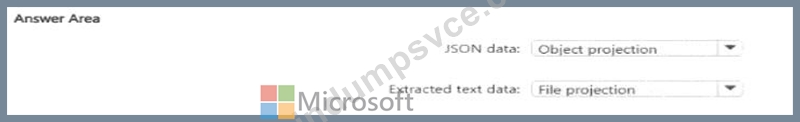
Use an object projection for the unstructured JSON data. Object projections store a JSON representation of an enrichment tree node in an Azure Blob Storage container. They preserve hierarchical fields and complex structures, making them appropriate when enriched document content must remain available as a complete JSON object rather than being decomposed into relational rows. Microsoft describes object projections as JSON representations that can be sourced from nodes in the enrichment tree.
For the scanned PDF content, use a file projection . During document cracking and OCR processing, scanned pages are represented through the /document/normalized_images/* collection. File projections write these binary normalized images to Blob Storage, preserving the page assets from which the text is extracted.
Microsoft specifies that file projections operate only on normalized images and contain binary data rather than JSON.
A table projection is intended for row-and-column structures used by analytical tools such as Power BI. It is not the appropriate choice for preserving hierarchical JSON or scanned-document image files.
Study Guide alignment: configure Azure AI Search enrichment pipelines, skillsets, knowledge stores, and table, object, and file projections .
NEW QUESTION # 14
You need to recommend a solution to support the planned changes and technical requirements for Agent1 to use the product information stored in storage1.
What should you include in the recommendation?
Answer: A
NEW QUESTION # 15
You have a Microsoft Foundry project that contains a support-ticket triage agent built by using the Foundry Agent Service.
The agent uses tool to classify the ticket type and sot the ticket priority.
Sometimes, the same support case continues across multiple sessions over several days.
You need to persist state by using a durable ID to ensure that the agent can automatically reuse the full interaction history. The solution must preserve previous user messages, tool calls and tool outputs across turns and sessions.
Which runtime component should you use?
Answer: C
Explanation:
To achieve state persistence and ensure that the agent automatically reuses the full multi-session interaction history (including previous user messages, tool calls, and tool outputs), you must include a conversation component.
References:
https://learn.microsoft.com/en-us/azure/foundry/agents/concepts/runtime-components
NEW QUESTION # 16
You have a Microsoft Foundry project that contains an agent.
The agent ingests scanned PDF vendor invoices that contain tables and embedded QR codes.
The agent must preserve the PDF layout in the extracted output to ensure that downstream processing can reference sections and tables.
You plan to call Azure Content Understanding in Foundry Tools.
You need to extract content and layout elements and detect QR codes without requiring a language model deployment.
Which built-in analyzer should you use?
Answer: C
Explanation:
The correct built-in analyzer is prebuilt-layout because the requirement is to preserve document layout while extracting content from scanned PDFs. Microsoft's Content Understanding prebuilt analyzer guidance states that prebuilt-layout extracts content and layout elements such as words, figures, paragraphs, and tables, identifies document structure including sections and formatting, and provides detailed layout information beyond basic text extraction. It also states that prebuilt-layout does not require a language model or embedding model, which directly satisfies the no language model deployment requirement.
QR codes are handled through barcode extraction. The analyzer configuration reference states that enableBarcode detects and extracts barcodes and QR codes, returns decoded values, and supports QR Code and Micro QR Code among other barcode types. This option is supported by document-based analyzers, making it compatible with layout-oriented document processing.
prebuilt-read is insufficient because it provides OCR and barcode extraction but foundational text extraction without layout analysis. prebuilt-documentSearch is optimized for RAG ingestion and semantic analysis, which is broader than required. prebuilt-documentFieldSchema proposes extraction schemas rather than extracting full document layout. Reference topics: Content Understanding prebuilt analyzers, layout analysis, OCR, barcode detection, QR code extraction, and document-based analyzers.
NEW QUESTION # 17
......
There is no doubt that we all dream of working for top companies around the globe. Some people make it through but some keep on thinking about how to break that glass. If you are among those who belong to the latter category, you should start the preparations for the Developing AI Apps and Agents on Azure (AI-103) certification exam to improve your knowledge, expertise and crack even the toughest interview easily.
AI-103 Valid Practice Materials: https://www.braindumpsvce.com/AI-103_exam-dumps-torrent.html
What's more, part of that BraindumpsVCE AI-103 dumps now are free: https://drive.google.com/open?id=19UEQFS8Ggq6gQWI2RrU1P96BxmLzaZ-o