With the arrival of experience economy and consumption, the experience marketing is well received in the market. If you are fully attracted by our CCAR-P training practice and plan to have a try before purchasing, we have free trials to help you understand our products better before you completely accept our CCAR-P study dumps. As long as you submit your email address and apply for our free trials, we will soon send the free demo of the CCAR-P training practice to your mailbox. If you are uncertain which one suit you best, you can ask for different kinds free trials of CCAR-P latest exam guide in the meantime. After deliberate consideration, you can pick one kind of study materials from our websites and prepare the exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Evaluation, Testing & Optimization | 16% | - System issue diagnosis - Cost and performance optimization - Production monitoring and optimization - A/B testing - Evaluation framework design - Evaluation metrics and datasets |
| Topic 2: Claude Models, Prompting & Context Engineering | 13% | - System prompts and prompt templates - Guardrails - Context window optimization - Claude model selection and trade-offs - Prompt reuse and context engineering strategies |
| Topic 3: Integration | 19% | - Enterprise system integration - Authentication and authorization analysis - RAG pipeline design
|
| Topic 4: Stakeholder Communication & Lifecycle Management | 14% | - Discovery and requirements gathering - Stakeholder management - Communicating architectural decisions - Solution lifecycle management - Architecture documentation - Service-level agreements |
| Topic 5: Developer Productivity & Operational Enablement | 7% | - Developer enablement - AI-assisted developer workflows - Debugging and operational issue resolution - Claude tooling configuration for teams |
| Topic 6: Solution Design & Architecture | 17% | - Multi-agent systems and orchestration - End-to-end architecture design - Decomposition techniques for complex problem solving - Translating business problems into Claude-based AI solutions - Alignment with business value, cost, performance, and SLAs - Architectural patterns
|
| Topic 7: Governance, Safety & Risk Management | 14% | - Human-in-the-loop validation - Ethical AI considerations - Regulatory and compliance requirements - AI safety and guardrails - Security and risk management |
>> Best CCAR-P Preparation Materials <<
There is no exaggeration that you can be confident about your coming exam just after studying with our CCAR-P preparation questions for 20 to 30 hours. Tens of thousands of our customers have benefited from our CCAR-P Exam Materials and passed their exams with ease. The data showed that our high pass rate is unbelievably 98% to 100%. Without doubt, your success is 100% guaranteed with our CCAR-P training guide.
NEW QUESTION # 67
You are classifying chunking strategies by the corpus type each is best suited to.
For each chunking strategy, select the appropriate corpus type: "Long Structured Documents,"
"Heterogeneous Short Records," or "Code or Hierarchical Specifications."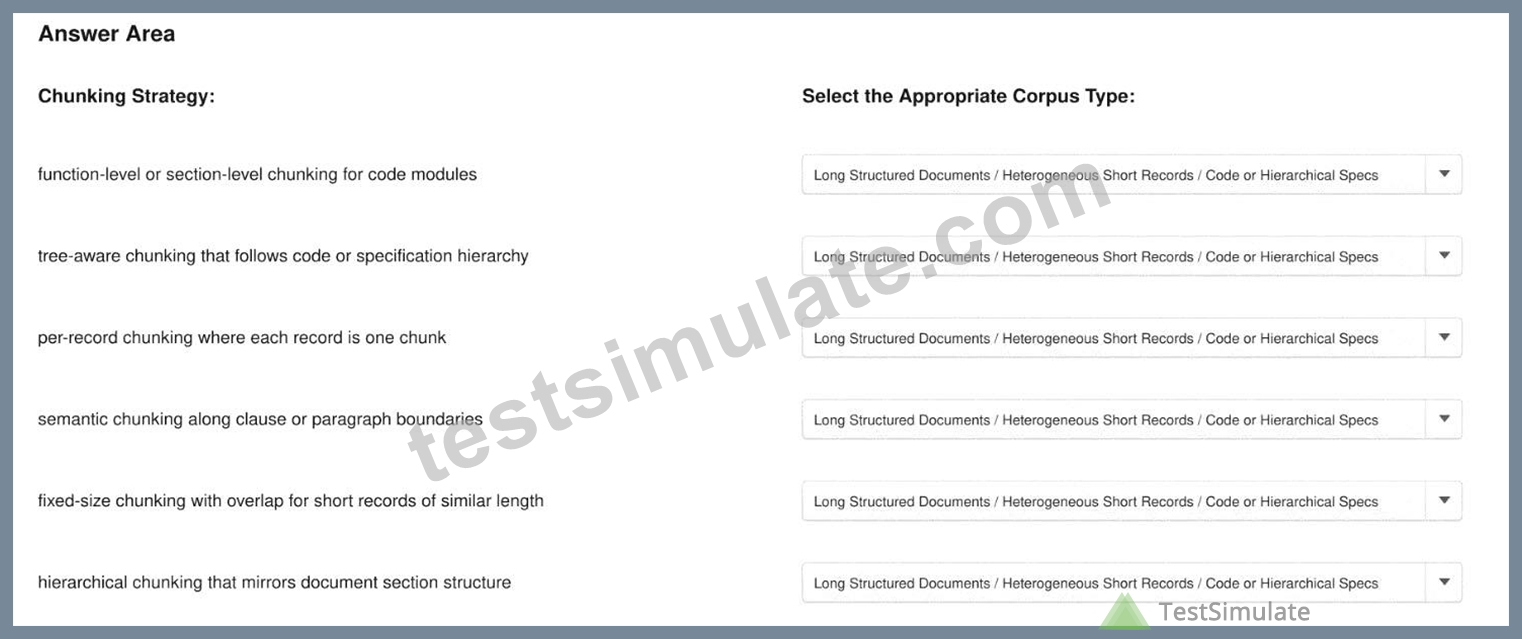
Answer:
Explanation: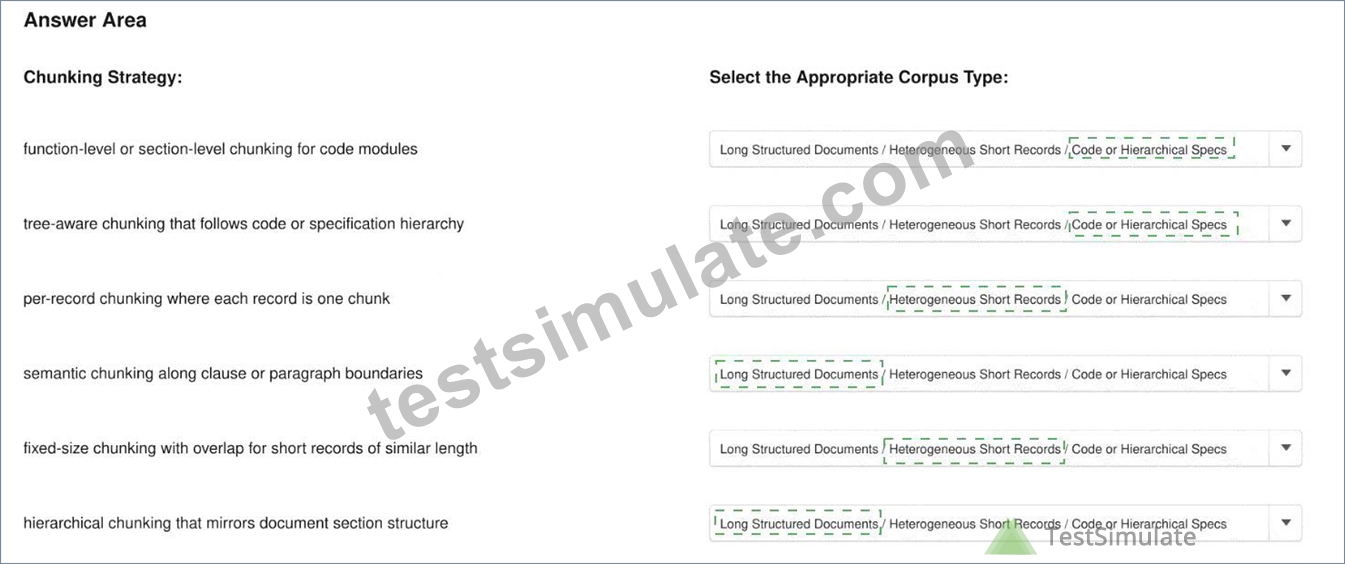
Explanation:
* Function-level or section-level chunking for code modules - Code or Hierarchical Specifications
* Tree-aware chunking that follows code or specification hierarchy - Code or Hierarchical Specifications
* Per-record chunking where each record is one chunk - Heterogeneous Short Records
* Semantic chunking along clause or paragraph boundaries - Long Structured Documents
* Fixed-size chunking with overlap for short records of similar length - Heterogeneous Short Records
* Hierarchical chunking that mirrors document section structure - Long Structured Documents Chunking must preserve the structural unit that carries meaning in the source corpus. Code and hierarchical specifications are best divided at function, module, class, or tree boundaries because arbitrary token cuts can separate definitions from their implementation or parent context. Heterogeneous short-record collections should generally preserve each record as an independent chunk. Fixed-size overlapping chunks are also effective when records have broadly similar lengths and lack meaningful internal hierarchy. Long structured documents benefit from semantic boundaries such as clauses and paragraphs, while hierarchical chunking preserves relationships among sections, subsections, and parent headings. Anthropic notes that chunk size, boundaries, and overlap materially affect retrieval performance; therefore, one universal chunking method is inappropriate. Anthropic Contextual Retrieval
NEW QUESTION # 68
A security team is evaluating two proposed controls. Control A adds an outbound tool allow-list with destination restrictions and per-call review. Control B scores responses against a stable adversarial evaluation set after each model-version change.
Which two risk categories are correctly matched to these controls? (Select two.)
Answer: B,E
Explanation:
Control A directly constrains the outbound action surface. An allow-list limits which tools and destinations may receive data, while per-call review introduces an approval boundary before information leaves the controlled environment. These measures therefore address data exfiltration through outbound tool calls, making Option C correct. Anthropic's security guidance recommends least privilege, narrowly scoped permissions, sandboxing, and limiting access to sensitive information and actions so that a compromised agent can cause minimal damage. Mitigate Jailbreaks and Prompt Injections Control B addresses model-version drift. Running a stable adversarial evaluation set after each version change creates a consistent comparison baseline and detects regressions that might otherwise remain invisible during routine testing. This correctly maps Control B to silent quality drift, making Option E correct. Anthropic's migration guidance repeatedly calls for workload reevaluation because instruction following, style, reasoning, and agent behavior can differ between versions. Model Migration Guide Control A may limit the consequences of successful prompt injection, but it does not prevent or directly detect adversarial instructions in retrieved content. Control B measures behavioral performance but does not impose outbound authorization controls. Each control must therefore be mapped to the risk it most directly mitigates.
Study Guide references/topics: Tool governance; least privilege; exfiltration controls; adversarial evaluations; model-change regression testing; defense in depth.
NEW QUESTION # 69
You are building an ethics-review checklist for deployments supported by artificial intelligence.
Which two checks belong on the list? (Select two.)
Each correct answer presents a complete solution.
Answer: C,D
Explanation:
An ethics review must examine unsupported generalizations, stereotyping, disparate treatment, and other conclusions about people that are not justified by the evidence. It must also preserve identifiable human accountability for consequential decisions; responsibility cannot be transferred to a probabilistic system.
Licensing is a legal and commercial-control question, while latency and throughput are operational requirements. Both remain important, but neither is the central ethical test presented here. Restricting review to low-confidence or threshold-triggering outputs is also inadequate because models can express harmful or biased conclusions with high confidence. Ethical review should cover representative populations, protected and intersectional groups, high-impact outcomes, override mechanisms, transparency, and channels for challenge or appeal.
Study Guide references/topics: Bias and unsupported generalization; human accountability; consequential decisions; ethical oversight.
NEW QUESTION # 70
You are defining transparency practices for a customer-facing assistant whose responses are materially shaped by AI.
Which transparency practice most directly supports responsible deployment?
Answer: B
Explanation:
Responsible deployment requires users to receive an accurate representation of the system with which they are interacting. Option C provides that transparency while also establishing a practical escalation path.
Disclosure should be proportionate to the material role AI plays, expressed in language appropriate to the audience, and aligned with organizational policy and applicable regulatory obligations.
A documented human-contact route is important when the assistant cannot resolve an issue, produces a disputed result, encounters a high-impact exception, or handles a matter requiring human authority. Anthropic' s Responsible Scaling Policy recognizes escalation to human reviewers as an appropriate safeguard for edge cases and situations requiring human judgment. Responsible Scaling Policy Options A and D intentionally conceal material AI involvement from affected users, weakening informed decision-making, auditability, and trust. Option B is also unsuitable because transparency does not require revealing proprietary prompts, confidential controls, or internal security mechanisms; however, it does require an honest explanation of AI involvement and the system's operational role.
The correct design combines disclosure, understandable limitations, human escalation, and records demonstrating that the organization's transparency requirements are consistently applied.
Study Guide references/topics: AI transparency; informed user interaction; human escalation; responsible deployment; disclosure policy; operational accountability.
NEW QUESTION # 71
You are designing a content moderation classifier that processes high volumes of user-generated comments under a tight per-message latency budget using well-defined classification labels.
Which model selection best aligns with the workload?
Answer: D
Explanation:
Haiku is the appropriate starting point because the workload is high-volume, latency-sensitive, and based on a stable closed set of moderation labels. These characteristics favor a fast, cost-efficient model capable of consistent classification without incurring the additional inference time and expense associated with deeper reasoning.
Anthropic's model-selection guidance requires architects to balance capability, speed, and cost rather than automatically selecting the most capable model. Its content-moderation guidance specifically identifies Haiku as a cost-effective option for processing moderation workloads at substantial scale. Choosing the Right Model
, Content Moderation
Opus is disproportionate to a routine closed-set classification problem. Sonnet may become justified if evaluation demonstrates that Haiku fails materially on complex policy distinctions, multilingual ambiguity, or adversarial edge cases, but it should not be selected merely because it is larger. Enabling extended thinking on every request would further increase latency and token consumption without evidence that the additional reasoning improves the defined success metrics. The correct architectural practice is to establish a representative moderation evaluation set, validate Haiku against accuracy and safety thresholds, and escalate only the cases that genuinely need deeper reasoning.
Study Guide references/topics: Model selection; capability-latency-cost trade-offs; classification workloads; evaluation-driven routing; moderation architecture.
NEW QUESTION # 72
......
TestSimulate is a leading platform that is committed to preparing the Anthropic CCAR-P certification exam candidates in a short time period. These Anthropic CCAR-P exam dumps are designed and verified by experienced and certified exam trainers. They put all their efforts to maintain the top standard of Anthropic CCAR-P Exam Questions all the time. latest real exam and exam questions offerred by TestSimulate, with free updates for 365 days.
Practice CCAR-P Engine: https://www.testsimulate.com/CCAR-P-study-materials.html