BTW, DOWNLOAD part of PassSureExam DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1o-spoZIOKVEFIRqeLhfJBnUpTD9ScH7z
Our Microsoft DP-750 Exam Dumps effect in helping candidates' certification exam. Original questions are also important. These would provide a forum where certification training can be carried on. Our dumps torrent is perfect and practice test is also the latest. After you purchase our product, we offer free update service for one year.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 2: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 3: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 4: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
Our DP-750 Test Braindumps are by no means limited to only one group of people. Whether you are trying this exam for the first time or have extensive experience in taking exams, our DP-750 latest exam torrent can satisfy you. This is due to the fact that our DP-750 test braindumps are humanized designed and express complex information in an easy-to-understand language. You will never have language barriers, and the learning process is very easy for you. What are you waiting for? If you are preparing to take the test, you can rely on our learning materials. You will also be the next beneficiary. After you get Microsoft certification, you can get boosted and high salary to enjoy a good life.
NEW QUESTION # 56
You need to ingest real-time IoT data into Delta Lake with exactly-once guarantees. Which approach should you use?
Answer: B
Explanation:
Structured Streaming with checkpointing ensures fault tolerance and exactly-once processing semantics in Databricks. It tracks processed offsets and recovers from failures automatically.
Batch ingestion cannot guarantee real-time processing. Copy activity is not designed for streaming workloads and manual ingestion is not scalable or reliable.
NEW QUESTION # 57
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table1 is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table1.
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: C
Explanation:
You should enable schema evolution to resolve this problem. In Lakeflow Spark Declarative Pipelines (SDP)-formerly known as Delta Live Tables (DLT)-schema evolution automatically updates the schema of your managed Delta tables when new columns are detected in the source data.
Prevents Pipeline Failures: By default, Delta Lake applies strict schema enforcement to prevent bad or mismatched data from corrupting your tables. When the source data layout changes (e.g., column creep), the pipeline will throw a runtime error and fail the write operation.
Automates Ingestion Flexibility: Activating schema evolution allows Delta Lake to automatically adapt by adding the new columns to the target managed table layout dynamically, eliminating manual intervention or explicit ALTER TABLE operations.
Reference:
https://learn.microsoft.com/en-us/azure/databricks/ldp/unity-catalog
NEW QUESTION # 58
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.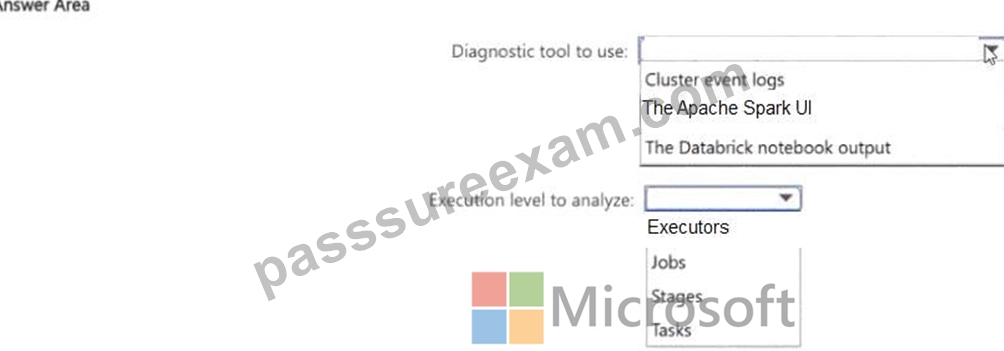
Answer:
Explanation:
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it ' s accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it ' s processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that
' s data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
NEW QUESTION # 59
What improves join performance for small lookup tables?
Answer: A
Explanation:
Broadcast joins send the small table to all worker nodes, avoiding expensive shuffling. This significantly improves performance. Shuffle and sort merge joins are heavier. Cartesian joins are inefficient and generally avoided.
NEW QUESTION # 60
You need to complete the PySpark code for the Spark Structured Streaming pipelines. The solution must meet the data ingestion and processing requirements.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.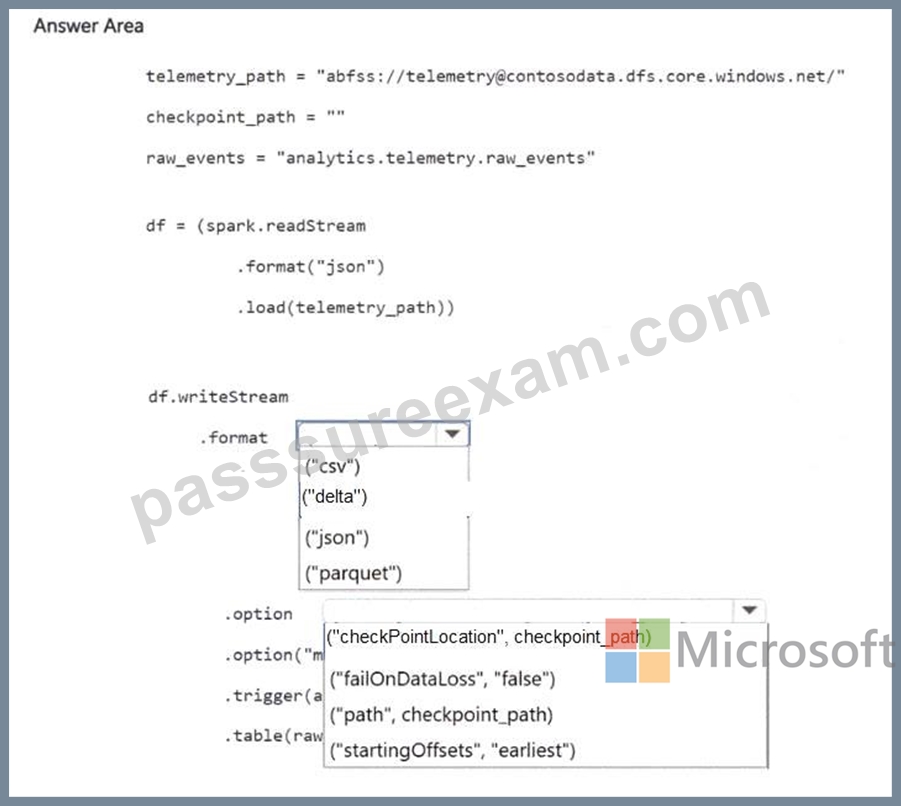
Answer:
Explanation: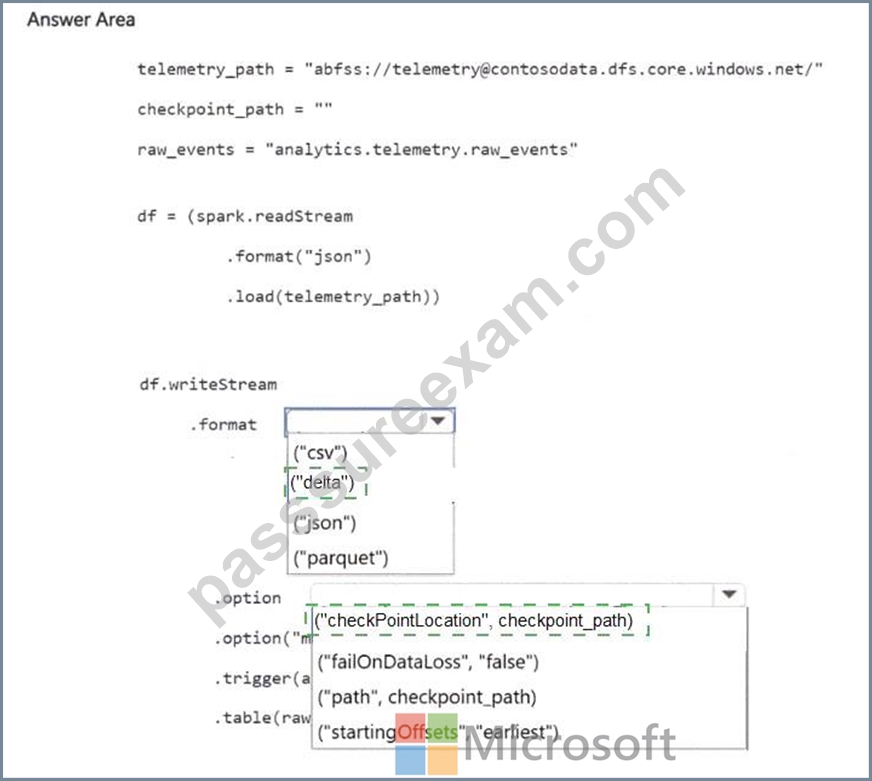
Explanation:
The solution requires spark.readStream with format('cloudFiles') for Auto Loader, paired with .writeStream using mergeSchema=true and a checkpointLocation.
Auto Loader's cloudFiles source incrementally processes new JSON files without rescanning the entire directory. The mergeSchema option handles schema drift - when sensors add new fields, the target Delta table schema expands automatically instead of throwing a parse error. This directly addresses Contoso's requirement to 'support schema drift.' The checkpointLocation is what gives the pipeline its resilience. Databricks writes the stream's committed offset and schema state to that path. If the cluster restarts, the engine reads the checkpoint and picks up exactly where it left off - no events are reprocessed, satisfying 'exactly-once semantics' and 'resume processing after failures without reprocessing the data.' Without a checkpoint, the stream would restart from the beginning on every cluster bounce, which is precisely the problem Contoso is trying to eliminate.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/schema
NEW QUESTION # 61
......
You will be feeling be counteracted the effect of tension for our Microsoft DP-750 practice dumps can relieve you of the anxious feelings. Our Implementing Data Engineering Solutions Using Azure Databricks practice materials are their masterpiece full of professional knowledge and sophistication to cope with the Microsoft DP-750 Exam. They have sublime devotion to their career just like you, and make progress ceaselessly.
DP-750 Valid Test Bootcamp: https://www.passsureexam.com/DP-750-pass4sure-exam-dumps.html
BONUS!!! Download part of PassSureExam DP-750 dumps for free: https://drive.google.com/open?id=1o-spoZIOKVEFIRqeLhfJBnUpTD9ScH7z