BTW, DOWNLOAD part of Itcertkey NCA-GENM dumps from Cloud Storage: https://drive.google.com/open?id=1OTRGFpWuJHz0MfrJzwrYrunfKjtv-Oby
We all harness talents with processional skills. Mastering the certificate of the NCA-GENM practice exam is essential for you. With all instability of the society, those knowledge and profession certificate mean a lot for you. So it is unquestionable the NCA-GENM learning questions of ours can do a big favor. And we have become the most popular exam braindumps provider in this career and supported by numerous of our loyal customers. You will be satisfied with our NCA-GENM study guide as well.
| Section | Weight | Objectives |
|---|---|---|
| Multimodal Data | 15% | - Characteristics of text, image, and audio data - Multimodal model architectures and integration - Data preprocessing, fusion, and representation |
| Software Development and Engineering | 15% | - Development workflows for generative AI applications - Best practices for building and maintaining systems - Libraries, frameworks, and tools for multimodal AI |
| Trustworthy AI | 5% | - Reliability, fairness, and safety in generative systems - Robustness and error mitigation - Ethical considerations and responsible use |
| Core Machine Learning and AI Knowledge | 20% | - Fundamental concepts of machine learning and deep learning - Generative AI principles and techniques - Neural network architectures relevant to multimodal systems |
| Data Analysis and Visualization | 10% | - Analyzing multimodal datasets and outputs - Visualization techniques for model behavior and results - Interpretation of generative AI outputs |
| Experimentation | 25% | - Metrics and validation strategies for generative models - Experiment design and methodology - Model training, fine-tuning, and evaluation |
| Performance Optimization | 10% | - Model efficiency and inference optimization - Scalability and deployment considerations - Hardware acceleration with NVIDIA platforms |
>> Test NCA-GENM Simulator Online <<
The NVIDIA Generative AI Multimodal (NCA-GENM) certification is one of the hottest career advancement credentials in the modern NVIDIA world. The NVIDIA NCA-GENM certification can help you to demonstrate your expertise and knowledge level. With only one badge of NCA-GENM Certification, successful candidates can advance their careers and increase their earning potential.
NEW QUESTION # 51
What is the purpose of the cuDNN library?
Answer: B
Explanation:
cuDNN (CUDA Deep Neural Network library) is NVIDIA's GPU-accelerated library providing highly optimized, low-level implementations of the primitive operations that underpin deep learning - convolutions, pooling, normalization, activation functions, and recurrent operations - tuned specifically for NVIDIA GPU architectures. Deep learning frameworks including PyTorch, TensorFlow, and JAX call into cuDNN under the hood rather than implementing these operations themselves, which is why upgrading a GPU driver/cuDNN version can materially change training and inference performance without any change to model code.
cuDNN's optimizations include algorithm auto-tuning (selecting the fastest available convolution algorithm for a given tensor shape and hardware), Tensor Core utilization for mixed-precision workloads, and kernel- level performance engineering that individual framework developers would find impractical to reimplement and maintain for every GPU generation.
The distractors point to different, specific NVIDIA-ecosystem or third-party tools: text-to-image generation via CLIP (A) is an application-level generative task, not a low-level compute library's function. GPU metrics monitoring via Prometheus (B) describes observability tooling (commonly paired with NVIDIA's DCGM exporter), a separate concern from computational optimization. GPU-accelerated data preparation (D) more closely describes RAPIDS libraries like cuDF, not cuDNN, which is specifically scoped to neural network primitive operations rather than general data preprocessing.
Reference: Performance Optimization domain - cuDNN, GPU-accelerated deep learning primitives.
NEW QUESTION # 52
You are developing a multimodal generative A1 model that takes both image and text inputs. The image branch uses a ResNet50 pre- trained on ImageNet, while the text branch uses a BERT model. To effectively combine the features, you need to align their representations. Which of the following techniques is MOST suitable for projecting the image and text features into a common embedding space?
Answer: B
Explanation:
Contrastive learning is highly effective for aligning representations from different modalities. By training the model to pull together embeddings of related image-text pairs while pushing apart embeddings of unrelated pairs, it learns a shared embedding space where semantically similar concepts are close to each other, regardless of their modality. While (B) is a possible approach, it doesn't explicitly enforce alignment based on semantic similarity. (A) is unlikely to produce good results due to differing feature spaces. (C) is computationally expensive. (D) is a dimensionality reduction technique, not primarily an alignment method.
NEW QUESTION # 53
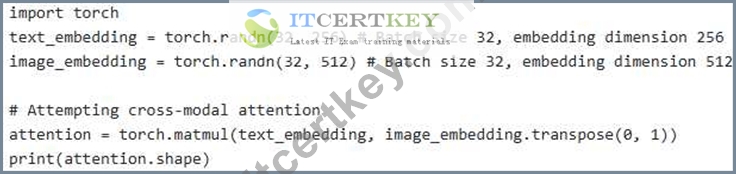
Consider this Python code snippet using PyTorch:
Answer: B
Explanation:
The shape of the 'attention' tensor is torch.Size([32, 32]). The matrix multiplication of (32, 256) with (512, 32) results in a (32, 32) tensor. The crucial issue here is the batch-wise attention calculation. The attention weights are being computed between all text embeddings and all image embeddings in the batch. During training, this leads to 'information leakage' because the model is learning relationships between samples that shouldn't be related (i.e., different text-image pairs in the batch are influencing each other). For proper cross-modal attention, you would typically want to compute the attention weights only between corresponding text and image embeddings within the same sample.
NEW QUESTION # 54
You are developing a generative A1 model to create music based on textual descriptions of mood and genre. You have a dataset of paired text descriptions and music tracks. When evaluating the generated music, you realize it's difficult to objectively quantify the quality of the music. Which of the following evaluation methods would provide the MOST comprehensive assessment of the generated music's quality and alignment with the text descriptions?
Answer: C
Explanation:
Human evaluation (C) is crucial for subjective aspects like music quality. Bit rate (A), file size (D), and RMS energy (E) are not related to music quality directly. While genre classification (B) can be a component, it doesn't capture the full scope of quality or mood alignment.
NEW QUESTION # 55
You have trained a multimodal model for visual question answering (VQA). During inference, the model often generates incorrect answers even though it seems to understand the question and the image content. Which of the following strategies could help improve the accuracy of the model's predictions? (Select all that apply)
Answer: A,D,E
Explanation:
Beam search can help explore more probable answer sequences, data augmentation can improve the model's robustness, and a loss function that penalizes incorrect answers more heavily can encourage the model to learn more accurate predictions. Increasing the learning rate might lead to instability, and reducing the dataset size is generally detrimental to performance.
NEW QUESTION # 56
......
This NVIDIA PDF file is a really convenient and manageable format. Furthermore, the NVIDIA NCA-GENM PDF is printable which enables you to study or revise questions on the go. This can be helpful since staring at a screen during long study hours can be tiring and the NCA-GENM PDF hardcopy format is much more comfortable. And this NVIDIA Generative AI Multimodal price is affordable.
Valid Test NCA-GENM Format: https://www.itcertkey.com/NCA-GENM_braindumps.html
BONUS!!! Download part of Itcertkey NCA-GENM dumps for free: https://drive.google.com/open?id=1OTRGFpWuJHz0MfrJzwrYrunfKjtv-Oby