The exam time is coming, while you are not prepared well for Databricks-Certified-Data-Engineer-Professional real test. Please do not be tense and worried, you can pass your Databricks-Certified-Data-Engineer-Professional actual exam very simply and easily with PrepAwayPDF Databricks-Certified-Data-Engineer-Professional free pdf dumps. With the help of Databricks Databricks-Certified-Data-Engineer-Professional free pdf practice, you can not only get high score in your actual test, but also can get more technology knowledge and be more professional.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring and Alerting | 10% | - Monitor pipeline performance and health - Track data lineage and metrics - Set up alerts and notifications |
| Data Governance | 7% | - Use Unity Catalog for governance - Enforce data policies and standards - Manage data assets and metadata |
| Cost & Performance Optimisation | 13% | - Improve query and pipeline performance - Optimize compute and storage resources - Apply cost management best practices |
| Data Sharing and Federation | 5% | - Use Delta Sharing for secure data sharing - Implement Lakehouse Federation - Manage cross-platform data access |
| Data Modelling | 6% | - Implement dimensional and relational models - Design Medallion Architecture - Optimize table design and partitioning |
| Data Transformation, Cleansing, and Quality | 10% | - Enforce data quality standards - Apply data cleansing and validation rules - Implement schema evolution and management |
| Debugging and Deploying | 10% | - Deploy using Asset Bundles, CLI, and APIs - Implement CI/CD and DevOps practices - Troubleshoot and debug pipelines |
| Developing Code for Data Processing using Python and SQL | 22% | - Write efficient and maintainable code - Use Databricks-specific libraries and APIs - Implement complex data processing logic |
| Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance - Implement access control and permissions - Secure data at rest and in transit |
| Data Ingestion & Acquisition | 7% | - Ingest data from diverse sources - Handle incremental and batch data loads - Use Auto Loader and structured streaming |
>> Exam Databricks-Certified-Data-Engineer-Professional Simulator <<
Our Databricks-Certified-Data-Engineer-Professional training materials have been honored as the panacea for the candidates for the exam since all of the contents in the Databricks-Certified-Data-Engineer-Professional guide materials are the essences of the exam. There are detailed explanations for some difficult questions in our Databricks-Certified-Data-Engineer-Professional exam practice. Consequently, with the help of our study materials, you can be confident that you will pass the exam and get the related certification as easy as rolling off a log. So what are you waiting for? Just take immediate action to buy our Databricks-Certified-Data-Engineer-Professional learning guide!
NEW QUESTION # 248
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from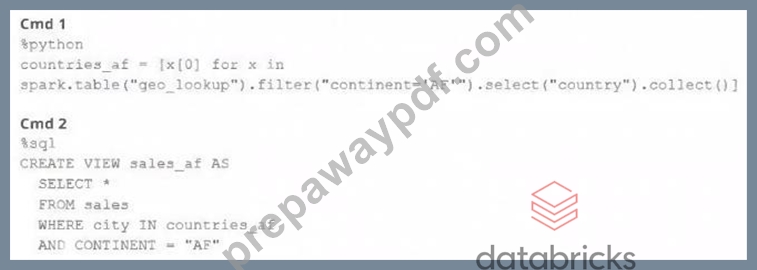
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
Answer: E
Explanation:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view.
Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter.
NEW QUESTION # 249
A data engineer has created a new cluster using shared access mode with default configurations.
The data engineer needs to allow the development team access to view the driver logs if needed.
What are the minimal cluster permissions that allow the development team to accomplish this?
Answer: D
Explanation:
The CAN VIEW permission on a cluster allows users to see cluster details, including driver and executor logs. This is the minimal permission required for the development team to access logs without granting them the ability to modify, restart, or attach notebooks to the cluster.
NEW QUESTION # 250
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id.
What should the data engineer do to ensure events are sequenced correctly?
Answer: C
Explanation:
When handling CDC data, sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built-in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration.
Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support, making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
NEW QUESTION # 251
A junior data engineer on your team has implemented the following code block.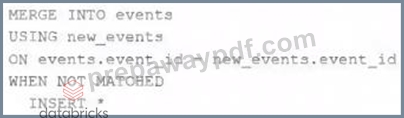
The view new_events contains a batch of records with the same schema as the events Delta table. The event_id field serves as a unique key for this table.
When this query is executed, what will happen with new records that have the same event_id as an existing record?
Answer: E
Explanation:
This is the correct answer because it describes what will happen with new records that have the same event_id as an existing record when the query is executed. The query uses the INSERT INTO command to append new records from the view new_events to the table events. However, the INSERT INTO command does not check for duplicate values in the primary key column (event_id) and does not perform any update or delete operations on existing records. Therefore, if there are new records that have the same event_id as an existing record, they will be ignored and not inserted into the table events.
NEW QUESTION # 252
A data company uses Databricks Unity Catalog and has multiple enterprise data sources, including PostgreSQL, Snowflake, and SQL Server. The central data platform team wants to configure Lakehouse Federation so analysts can query external tables directly in Databricks using Databricks SQL, without duplicating data. Which steps are necessary to configure Lakehouse Federation in a secure and governed manner?
Answer: C
Explanation:
Lakehouse Federation is configured by defining secure connections to external data sources and registering them as foreign catalogs in Unity Catalog. Access is then governed using Unity Catalog permissions at the catalog, schema, and table levels, enabling analysts to query external tables securely without data duplication.
NEW QUESTION # 253
......
If you want to get a desirable opposition and then achieve your career dream, you are a right place now. Our Databricks-Certified-Data-Engineer-Professional study tool can help you pass the exam. So, don't be hesitate, choose the Databricks-Certified-Data-Engineer-Professional test torrent and believe in us. Let's strive to our dreams together. Life is short for us, so we all should cherish our life. Our Databricks-Certified-Data-Engineer-Professional Guide Torrent can help you to save your valuable time and let you have enough time to do other things you want to do. Just buy our Databricks-Certified-Data-Engineer-Professional exam questions, then you will pass the Databricks-Certified-Data-Engineer-Professional exam easily.
Reliable Databricks-Certified-Data-Engineer-Professional Test Tips: https://www.prepawaypdf.com/Databricks/Databricks-Certified-Data-Engineer-Professional-practice-exam-dumps.html