Reliable Databricks-Certified-Data-Analyst-Associate Test Answers, Databricks-Certified-Data-Analyst-Associate Test Braindumps

BTW, DOWNLOAD part of RealValidExam Databricks-Certified-Data-Analyst-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1aG27H2IwI8n2JD_cdhcKpkIgtNYm4SqX
The Databricks-Certified-Data-Analyst-Associate PDF is the most convenient format to go through all exam questions easily. It is a compilation of actual Databricks Databricks-Certified-Data-Analyst-Associate exam questions and answers. The PDF is also printable so you can conveniently have a hard copy of Databricks Databricks-Certified-Data-Analyst-Associate Dumps with you on occasions when you have spare time for quick revision.
| Topic | Details |
|---|
| Topic 1 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
| Topic 2 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
| Topic 3 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
| Topic 4 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
| Topic 5 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
>> Reliable Databricks-Certified-Data-Analyst-Associate Test Answers <<
Databricks Databricks-Certified-Data-Analyst-Associate Test Braindumps & Databricks-Certified-Data-Analyst-Associate Instant Access
Constant improvements are the inner requirement for one person. As one person you can’t be satisfied with your present situation and must keep the pace of the times. You should constantly update your stocks of knowledge and practical skills. So you should attend the certificate exams such as the test Databricks-Certified-Data-Analyst-Associate Certification to improve yourself and buying our Databricks-Certified-Data-Analyst-Associate study materials is your optimal choice. Our Databricks-Certified-Data-Analyst-Associate study materials combine the real exam’s needs and the practicability of the knowledge.
Databricks Certified Data Analyst Associate Exam Sample Questions (Q18-Q23):
NEW QUESTION # 18
The stakeholders.customers table has 15 columns and 3,000 rows of data. The following command is run:
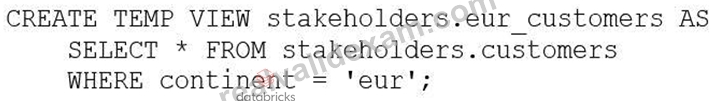
After running SELECT * FROM stakeholders.eur_customers, 15 rows are returned. After the command executes completely, the user logs out of Databricks.
After logging back in two days later, what is the status of the stakeholders.eur_customers view?
- A. The view has been converted into a table.
- B. The view is not available in the metastore, but the underlying data can be accessed with SELECT * FROM delta. `stakeholders.eur_customers`.
- C. The view remains available but attempting to SELECT from it results in an empty result set because data in views are automatically deleted after logging out.
- D. The view has been dropped.
- E. The view remains available and SELECT * FROM stakeholders.eur_customers will execute correctly.
Answer: E
Explanation:
In Databricks, a view is a saved SQL query definition that references existing tables or other views. Once created, a view remains persisted in the metastore (such as Unity Catalog or Hive Metastore) until it is explicitly dropped.
Key points:
* Views do not store data themselves but reference data from underlying tables.
* Logging out or being inactive does not delete or alter views.
* Unless a user or admin explicitly drops the view or the underlying data/table is deleted, the view continues to function as expected.
* Therefore, after logging back in-even days later-a user can still run SELECT * FROM stakeholders.
eur_customers, and it will return the same data (provided the underlying table hasn't changed).
Reference: Views - Databricks Documentation
NEW QUESTION # 19
A data analyst has created a Query in Databricks SQL, and now they want to create two data visualizations from that Query and add both of those data visualizations to the same Databricks SQL Dashboard.
Which of the following steps will they need to take when creating and adding both data visualizations to the Databricks SQL Dashboard?
- A. They will need to alter the Query to return two separate sets of results.
- B. They will need to create two separate dashboards.
- C. They will need to add two separate visualizations to the dashboard based on the same Query.
- D. They will need to decide on a single data visualization to add to the dashboard.
- E. They will need to copy the Query and create one data visualization per query.
Answer: C
Explanation:
A data analyst can create multiple visualizations from the same query in Databricks SQL by clicking the + button next to the Results tab and selecting Visualization. Each visualization can have a different type, name, and configuration. To add a visualization to a dashboard, the data analyst can click the vertical ellipsis button beneath the visualization, select + Add to Dashboard, and choose an existing or new dashboard. The data analyst can repeat this process for each visualization they want to add to the same dashboard. Reference: Visualization in Databricks SQL, Visualize queries and create a dashboard in Databricks SQL
NEW QUESTION # 20
A data analyst has created a Query in Databricks SQL, and now wants to create two data visualizations from that Query and add both of those data visualizations to the same Databricks SQL Dashboard.
Which step will the data analyst need to take when creating and adding both data visualizations to the Databricks SQL Dashboard?
- A. Copy the Query and create one data visualization per query.
- B. Alter the Query to return two separate sets of results.
- C. Add two separate visualizations to the dashboard based on the same Query.
- D. Decide on a single data visualization to add to the dashboard.
Answer: C
Explanation:
Databricks SQL allows you to create multiple visualizations from a single query result. These visualizations can be customized independently and each can be added to a dashboard. This feature is explicitly supported and recommended in Databricks' documentation on dashboards and visualization workflows, enabling flexible reporting without duplicating queries.
NEW QUESTION # 21
What describes the variance of a set of values?
- A. Variance is a measure of how far a single observed value is from a set ot va IN
- B. Variance is a measure of how far a set of values is spread out from the sets central value.
- C. Variance is a measure of central tendency of a set of values.
- D. Variance is a measure of how far an observed value is from the variable ' s maximum or minimum value.
Answer: B
Explanation:
Variance is a statistical measure that quantifies the dispersion or spread of a set of values around their mean (central value). It is calculated by taking the average of the squared differences between each value and the mean of the dataset. A higher variance indicates that the data points are more spread out from the mean, while a lower variance suggests that they are closer to the mean. This measure is fundamental in statistics to understand the degree of variability within a dataset.WikipediaWikipedia+1Investopedia+1 Reference: Variance - Wikipedia
NEW QUESTION # 22
A data scientist wants to tune a set of hyperparameters for a machine learning model. They have wrapped a Spark ML model in the objective function objective_function, and they have defined the search space search_space.
As a result, they have the following code block:
num_evals = 100
trials = SparkTrials()
best_hyperparam = fmin(
fn=objective_function,
space=search_space,
algo=tpe.suggest,
max_evals=num_evals,
trials=trials
)
Which of the following changes do they need to make to the above code block in order to accomplish the task?
- A. Reduce num_evals to be less than 10
- B. Change fmin() to fmax()
- C. Remove the trials=trials argument
- D. Change SparkTrials() to Trials()
- E. Remove the algo=tpe.suggest argument
Answer: D
Explanation:
Option A is correct. The model being tuned is a Spark ML model, which is already distributed. SparkTrials is intended to distribute independent single-machine trials across Spark workers. For distributed ML algorithms such as Spark MLlib/Spark ML, Hyperopt should run trials from the driver so each trial can access the full cluster resources. Therefore, SparkTrials() should be changed to Trials(). Official Databricks documentation explains that this setup works for distributed machine learning algorithms including Apache Spark MLlib, and the Databricks notebook guidance states that SparkTrials is incompatible for that distributed-training pattern because each trial must be evaluated on the driver node.
NEW QUESTION # 23
......
Our Databricks-Certified-Data-Analyst-Associate exam torrent is available in different versions. Whether you like to study on a computer or enjoy reading paper materials, our test prep can meet your needs. Our PDF version of the Databricks-Certified-Data-Analyst-Associate quiz guide is available for customers to print. You can print it out, so you can practice it repeatedly conveniently. Our Databricks-Certified-Data-Analyst-Associate test prep take full account of your problems and provide you with reliable services and help you learn and improve your ability and solve your problems effectively. Once you choose our Databricks-Certified-Data-Analyst-Associate Quiz guide, you have chosen the path to success. We are confident and able to help you realize your dream. A higher social status and higher wages will not be illusory. I will introduce you to the advantages of our Databricks-Certified-Data-Analyst-Associate exam torrent.
Databricks-Certified-Data-Analyst-Associate Test Braindumps: https://www.realvalidexam.com/Databricks-Certified-Data-Analyst-Associate-real-exam-dumps.html
- Databricks-Certified-Data-Analyst-Associate Dumps 🎣 Databricks-Certified-Data-Analyst-Associate Valid Exam Online 🦆 Databricks-Certified-Data-Analyst-Associate Latest Learning Material 🏎 Search for [ Databricks-Certified-Data-Analyst-Associate ] and download it for free immediately on ⮆ www.examcollectionpass.com ⮄ 🛄Test Databricks-Certified-Data-Analyst-Associate Cram
- Pdf Databricks-Certified-Data-Analyst-Associate Version 💙 Valid Databricks-Certified-Data-Analyst-Associate Test Materials 🙇 Premium Databricks-Certified-Data-Analyst-Associate Files 🍯 Simply search for ➤ Databricks-Certified-Data-Analyst-Associate ⮘ for free download on ➠ www.pdfvce.com 🠰 🦱Databricks-Certified-Data-Analyst-Associate Study Dumps
- Databricks-Certified-Data-Analyst-Associate Dumps 🪓 Pdf Databricks-Certified-Data-Analyst-Associate Version ✏ Vce Databricks-Certified-Data-Analyst-Associate Free 🍏 Open 「 www.practicevce.com 」 enter { Databricks-Certified-Data-Analyst-Associate } and obtain a free download 🎻Study Databricks-Certified-Data-Analyst-Associate Tool
- First-grade Reliable Databricks-Certified-Data-Analyst-Associate Test Answers - Pass Databricks-Certified-Data-Analyst-Associate Exam 🐉 [ www.pdfvce.com ] is best website to obtain ➽ Databricks-Certified-Data-Analyst-Associate 🢪 for free download 🍄Free Databricks-Certified-Data-Analyst-Associate Dumps
- Earn The Badge Of Databricks Databricks-Certified-Data-Analyst-Associate Certification Exam On The First Attempt 🐆 Immediately open 「 www.dumpsmaterials.com 」 and search for “ Databricks-Certified-Data-Analyst-Associate ” to obtain a free download 📐Free Databricks-Certified-Data-Analyst-Associate Dumps
- Latest Databricks-Certified-Data-Analyst-Associate Test Objectives 🚦 Test Databricks-Certified-Data-Analyst-Associate Cram 🥚 Databricks-Certified-Data-Analyst-Associate Detailed Study Plan 🛃 Search on ▛ www.pdfvce.com ▟ for ⮆ Databricks-Certified-Data-Analyst-Associate ⮄ to obtain exam materials for free download 🔲Testking Databricks-Certified-Data-Analyst-Associate Learning Materials
- First-grade Reliable Databricks-Certified-Data-Analyst-Associate Test Answers - Pass Databricks-Certified-Data-Analyst-Associate Exam 🧘 Search on ▛ www.practicevce.com ▟ for 【 Databricks-Certified-Data-Analyst-Associate 】 to obtain exam materials for free download 🎥Relevant Databricks-Certified-Data-Analyst-Associate Exam Dumps
- First-grade Reliable Databricks-Certified-Data-Analyst-Associate Test Answers - Pass Databricks-Certified-Data-Analyst-Associate Exam 😖 Go to website ➡ www.pdfvce.com ️⬅️ open and search for 【 Databricks-Certified-Data-Analyst-Associate 】 to download for free 🙈Study Databricks-Certified-Data-Analyst-Associate Tool
- Real Databricks Databricks-Certified-Data-Analyst-Associate PDF Questions [2026]-The Greatest Shortcut Towards Success 🙍 Immediately open ⮆ www.prepawayexam.com ⮄ and search for ➠ Databricks-Certified-Data-Analyst-Associate 🠰 to obtain a free download 👝Premium Databricks-Certified-Data-Analyst-Associate Files
- Databricks-Certified-Data-Analyst-Associate Valid Exam Online 🛀 Latest Databricks-Certified-Data-Analyst-Associate Test Objectives 🏌 Premium Databricks-Certified-Data-Analyst-Associate Files 🏪 Easily obtain free download of 《 Databricks-Certified-Data-Analyst-Associate 》 by searching on [ www.pdfvce.com ] 🕋Vce Databricks-Certified-Data-Analyst-Associate Free
- Databricks-Certified-Data-Analyst-Associate Latest Learning Material 🔴 Pdf Databricks-Certified-Data-Analyst-Associate Version 🥅 Latest Databricks-Certified-Data-Analyst-Associate Test Objectives 💝 Search for 【 Databricks-Certified-Data-Analyst-Associate 】 and download it for free on 《 www.examcollectionpass.com 》 website 🧒Reliable Databricks-Certified-Data-Analyst-Associate Test Topics
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, telegra.ph, www.stes.tyc.edu.tw, Disposable vapes
DOWNLOAD the newest RealValidExam Databricks-Certified-Data-Analyst-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1aG27H2IwI8n2JD_cdhcKpkIgtNYm4SqX