You get a specific amount of time per day to study, you have a job, need to go to the office daily, and take time to relax from the hectic work schedule. So, planning a long study schedule is not possible. Some people study while traveling to the office, some prefer to check the office breaks and some even take it to late-night study especially when they are left with little time to prepare Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional for certification exam. For this reason, we want to make your journey smooth by providing you with smart tips to make the most out of your Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional study material for the Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional certification programs and clear it in one go.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API - Implement testing and deployment pipelines |
| Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
| Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage - Leverage system tables and observability tools |
| Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Implement scalable Python/SQL code and project structures |
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
>> New Certified-Data-Engineer-Professional Test Preparation <<
These Databricks Certified-Data-Engineer-Professional exam questions are modeled after the Certified-Data-Engineer-Professional test. They will assist you in learning how to manage your time during the examination. Free4Dump enabled all users to regulate time during their Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional test. And it can be accomplished via practice, as practice makes perfect. Therefore, you must practice passing the Certified-Data-Engineer-Professional exam.
NEW QUESTION # 35
A junior data engineer has manually configured a series of jobs using the Databricks Jobs UI.
Upon reviewing their work, the engineer realizes that they are listed as the "Owner" for each job.
They attempt to transfer "Owner" privileges to the "DevOps" group, but cannot successfully accomplish this task.
Which statement explains what is preventing this privilege transfer?
Answer: E
Explanation:
A job cannot have more than one owner. A job cannot have a group as an owner.
NEW QUESTION # 36
A data engineer is analyzing transactional data in a PySpark DataFrame df containing customer_id, transaction_timestamp (precise to milliseconds), and amount_spent. The objective is to compute a cumulative sum of amount_spent per customer, strictly ordered by transaction_timestamp. The cumulative sum must include all transactions from the earliest timestamp up to and including the current row, respecting temporal ordering within each customer partition. Which PySpark code snippet most accurately constructs the appropriate window specification and applies the aggregation to yield the correct cumulative expenditure per customer?
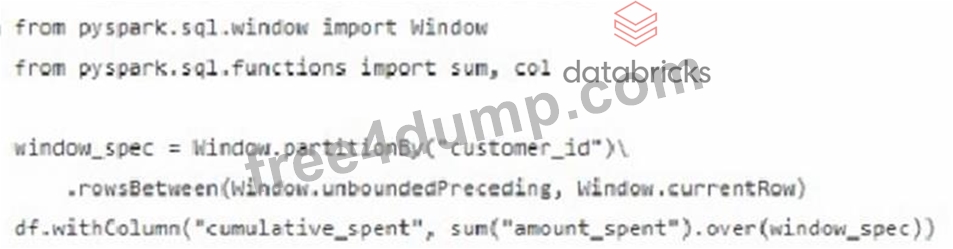
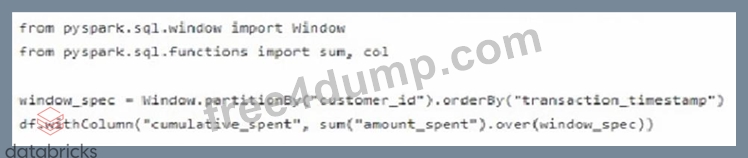
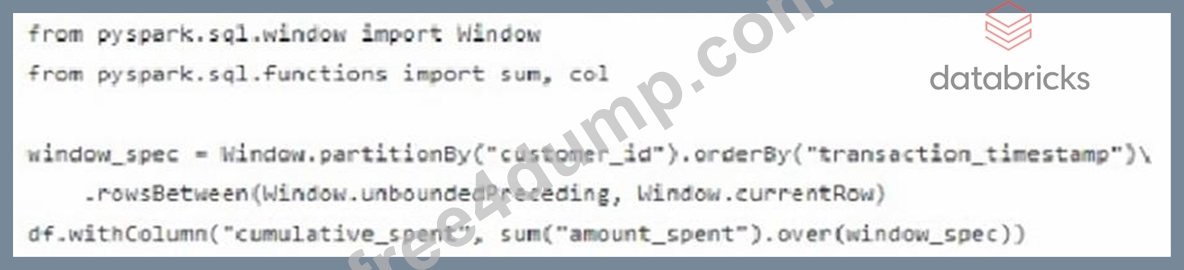
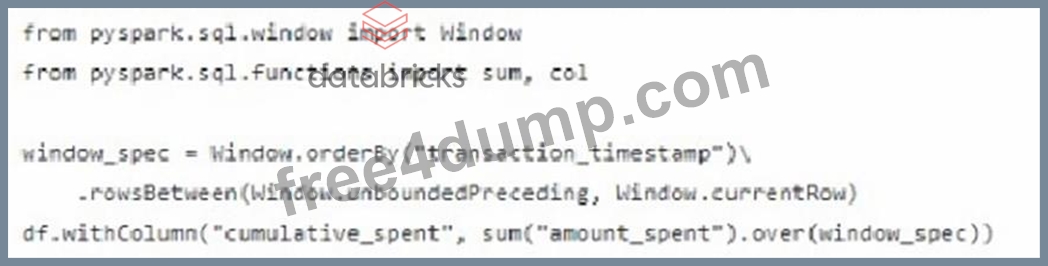
Answer: C
Explanation:
This window specification partitions the data by customer_id, orders transactions by transaction_timestamp, and defines the frame from the first transaction through the current one.
This guarantees that the cumulative sum is computed independently per customer and strictly follows the temporal order, including all prior transactions up to the current row.
NEW QUESTION # 37
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.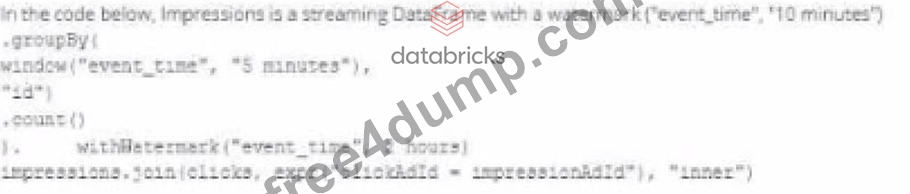
Which solution would improve the performance?




Answer: B
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
NEW QUESTION # 38
A data engineer is using Lakeflow Declarative Pipelines Expectations feature to track the data quality of their incoming sensor data. Periodically, sensors send bad readings that are out of range, and they are currently flagging those rows with a warning and writing them to the silver table along with the good data. They've been given a new requirement ?the bad rows need to be quarantined in a separate quarantine table and no longer included in the silver table.
This is the existing code for their silver table:
@dlt.table
@dlt.expect("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
What code will satisfy the requirements?
Answer: B
Explanation:
Lakeflow Declarative Pipelines (DLT) supports data quality enforcement using @dlt.expect,
@dlt.expect_or_drop, and @dlt.expect_all.
@dlt.expect applies a rule and records whether rows pass or fail the condition but does not drop failing rows. Instead, failing rows can be written to a quarantine table.
@dlt.expect_or_drop enforces that only rows passing the condition flow downstream, dropping bad records automatically.
In this case, the requirement is:
Good rows (reading < 120) go to the silver table.
Bad rows (reading >= 120) go to a quarantine table.
Bad rows should not be included in silver.
The correct implementation is Option A, where:
The silver table uses @dlt.expect to validate reading < 120. These rows flow normally.
The quarantine table applies an expectation for reading >= 120, ensuring bad records are captured separately.
Other options are incorrect:
Option B/D: These either use expect_or_drop incorrectly or apply wrong conditions, leading to dropped rows without quarantining properly.
Option C: Uses expect_or_drop for both tables, which would discard bad rows instead of persisting them into a quarantine table.
Thus, Option A meets the business requirement to split good and bad data streams while ensuring both are captured for auditing and processing.
NEW QUESTION # 39
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is named store_saies_summary and the schema is as follows:
The table daily_store_sales contains all the information needed to update store_sales_summary.
The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
If daily_store_sales is implemented as a Type 1 table and the total_sales column might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in the store_sales_summary table?
Answer: B
NEW QUESTION # 40
......
Our company boosts top-ranking expert team, professional personnel and specialized online customer service personnel. Our experts refer to the popular trend among the industry and the real exam papers and they research and produce the detailed information about the Certified-Data-Engineer-Professional exam study materials. They constantly use their industry experiences to provide the precise logic verification. The Certified-Data-Engineer-Professional prep material is compiled with the highest standard of technology accuracy and developed by the certified experts and the published authors only. And you will be bound to pass the Certified-Data-Engineer-Professional exam with them.
Exam Certified-Data-Engineer-Professional Practice: https://www.free4dump.com/Certified-Data-Engineer-Professional-braindumps-torrent.html