BONUS!!! Download part of RealExamFree Mule-Arch-201 dumps for free: https://drive.google.com/open?id=1xzWXG4-ukh86MOGr0vM8VBix-buomxlc
Are you still worried about the actuality and the accuracy of the Mule-Arch-201 exam cram? If you choose us, there is no necessary for you to worry about this problem, because we have the skilled specialists to compile as well check the Mule-Arch-201 Exam Cram, which can ensure the right answer and the accuracy. The pass rate is 98%, if you have any other questions about the Mule-Arch-201 dumps after buying, you can also contact the service stuff.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Monitoring and Analyzing Application Networks | 8% | - Operational visibility and optimization - Analytics and insight generation - Logging and alerting configuration - Monitoring strategies and tools |
| Topic 2: Meeting API Quality Goals | 8% | - Security and compliance standards - Maintainability and testability - Performance and latency requirements - Reliability and availability targets |
| Topic 3: Managing APIs | 12% | - API lifecycle management - Versioning and deprecation strategies - API policies and security enforcement - Rate limiting and throttling |
| Topic 4: Architecting and Deploying API Implementations | 11% | - CI/CD and DevOps integration - High availability and fault tolerance - Networking and security configuration - Runtime architecture and deployment options |
| Topic 5: Explaining Application Network Basics | 11% | - API-led connectivity principles - Benefits of modern API design - Core concepts of application networks |
| Topic 6: Designing and Sharing APIs | 11% | - API specification and documentation - API layering: Experience, Process, System APIs - Asset sharing and reuse via Anypoint Exchange - API design standards and best practices |
| Topic 7: Establishing Organizational and Platform Foundations | 17% | - Anypoint Platform architecture and components - Governance and organizational structure - Platform strategy and roadmap definition - Center for Enablement (C4E) operating model |
| Topic 8: Deploying API Implementations to CloudHub | 11% | - Deployment optimization and scaling - CloudHub architecture and capabilities - VPC and private space configuration - Worker sizing and resource planning |
| Topic 9: Applying Integration Patterns | 11% | - Common integration patterns and use cases - Event-driven and synchronous integration - Scalability and performance patterns - Error handling and reliability patterns |
>> Latest Salesforce Mule-Arch-201 Exam Vce <<
You can land your ideal job and advance your career with the Salesforce Mule-Arch-201 certification. Success in the Salesforce Mule-Arch-201 exam verifies your talent to perform crucial technical tasks. Preparation for this Salesforce Mule-Arch-201 exam is a tricky task. Make sure you choose the top-notch Salesforce Mule-Arch-201 Study Materials to get ready for this exam. For your smooth Mule-Arch-201 test preparation, RealExamFree provides updated Mule-Arch-201 practice material with a success guarantee.
NEW QUESTION # 74
When could the API data model of a System API reasonably mimic the data model exposed by the corresponding backend system, with minimal improvements over the backend system's data model?
Answer: B
Explanation:
Correct Answe r: When a pragmatic approach with only limited isolation from the backend system is deemed appropriate.
*****************************************
General guidance w.r.t choosing Data Models:
>> If an Enterprise Data Model is in use then the API data model of System APIs should make use of data types from that Enterprise Data Model and the corresponding API implementation should translate between these data types from the Enterprise Data Model and the native data model of the backend system.
>> If no Enterprise Data Model is in use then each System API should be assigned to a Bounded Context, the API data model of System APIs should make use of data types from the corresponding Bounded Context Data Model and the corresponding API implementation should translate between these data types from the Bounded Context Data Model and the native data model of the backend system. In this scenario, the data types in the Bounded Context Data Model are defined purely in terms of their business characteristics and are typically not related to the native data model of the backend system. In other words, the translation effort may be significant.
>> If no Enterprise Data Model is in use, and the definition of a clean Bounded Context Data Model is considered too much effort, then the API data model of System APIs should make use of data types that approximately mirror those from the backend system, same semantics and naming as backend system, lightly sanitized, expose all fields needed for the given System API's functionality, but not significantly more and making good use of REST conventions.
The latter approach, i.e., exposing in System APIs an API data model that basically mirrors that of the backend system, does not provide satisfactory isolation from backend systems through the System API tier on its own. In particular, it will typically not be possible to "swap out" a backend system without significantly changing all System APIs in front of that backend system and therefore the API implementations of all Process APIs that depend on those System APIs! This is so because it is not desirable to prolong the life of a previous backend system's data model in the form of the API data model of System APIs that now front a new backend system. The API data models of System APIs following this approach must therefore change when the backend system is replaced.
On the other hand:
>> It is a very pragmatic approach that adds comparatively little overhead over accessing the backend system directly
>> Isolates API clients from intricacies of the backend system outside the data model (protocol, authentication, connection pooling, network address, ...)
>> Allows the usual API policies to be applied to System APIs
>> Makes the API data model for interacting with the backend system explicit and visible, by exposing it in the RAML definitions of the System APIs
>> Further isolation from the backend system data model does occur in the API implementations of the Process API tier
NEW QUESTION # 75
Which two statements are true about the technology architecture of an Anypoint Virtual Private Cloud (VPC)?
Choose 2 answers
Answer: C,E
Explanation:
An Anypoint Virtual Private Cloud (VPC) provides a secure and private networking environment for MuleSoft applications, using specific architectural elements:
CIDR Blocks:
Anypoint VPCs utilize CIDR blocks to define IP ranges, allowing organizations to control and segment the VPC's IP address space.
Port 6091 for HTTP Requests:
By default, HTTP requests can be made to workers on port 6091 from the public internet, providing an accessible entry point unless additional restrictions are applied.
of Correct Answers (B, E):
CIDR blocks enable IP range management for VPCs, and port 6091 is the default public entry port, which is part of Anypoint VPC's default settings.
of Incorrect Options:
Option A (Ports 8081 and 8082) is incorrect; these are not default public ports for Anypoint VPC.
Option C (responsible for load balancing) is incorrect as load balancing requires a separate Dedicated Load Balancer (DLB).
Option D (round-robin load balancing) applies to DLBs, not directly to VPCs.
Reference
For more on VPC setup and networking, refer to MuleSoft documentation on VPC configurations and default port settings.
NEW QUESTION # 76
Refer to the exhibit.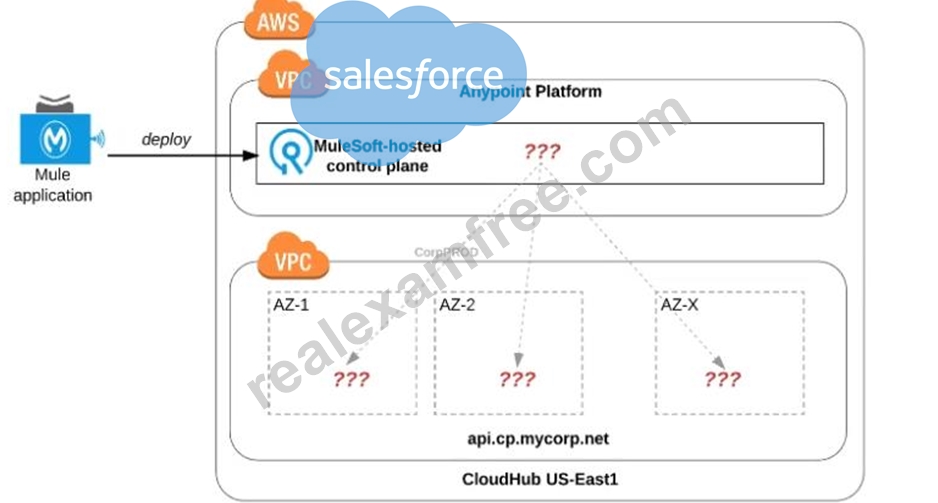
An organization uses one specific CloudHub (AWS) region for all CloudHub deployments.
How are CloudHub workers assigned to availability zones (AZs) when the organization's Mule applications are deployed to CloudHub in that region?
Answer: D
Explanation:
Correct Answe r: Workers are randomly distributed across available AZs within that region.
*****************************************
>> Currently, we only have control to choose which AWS Region to choose but there is no control at all using any configurations or deployment options to decide what Availability Zone (AZ) to assign to what worker.
>> There are NO fixed or implicit rules on platform too w.r.t assignment of AZ to workers based on environment or application.
>> They are completely assigned in random. However, cloudhub definitely ensures that HA is achieved by assigning the workers to more than on AZ so that all workers are not assigned to same AZ for same application.
Reference: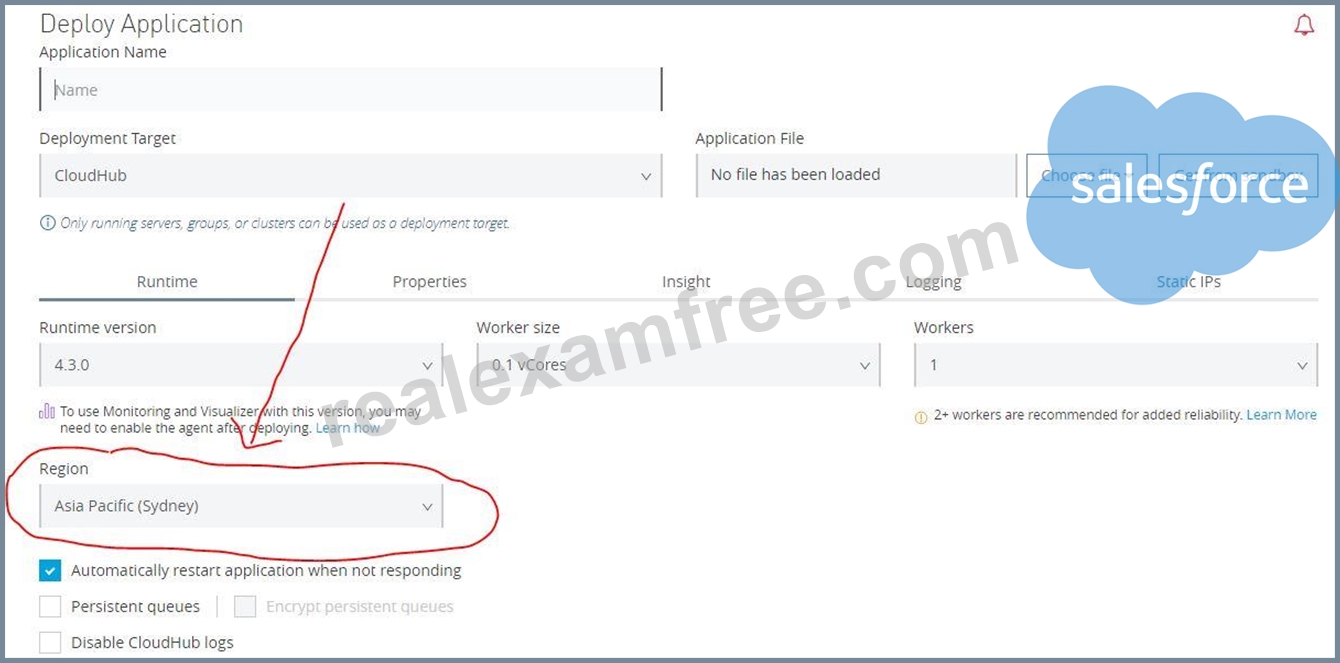
Bottom of Form
Top of Form
NEW QUESTION # 77
Refer to the exhibit.
What is the best way to decompose one end-to-end business process into a collaboration of Experience, Process, and System APIs?
A) Handle customizations for the end-user application at the Process API level rather than the Experience API level B) Allow System APIs to return data that is NOT currently required by the identified Process or Experience APIs C) Always use a tiered approach by creating exactly one API for each of the 3 layers (Experience, Process and System APIs) D) Use a Process API to orchestrate calls to multiple System APIs, but NOT to other Process APIs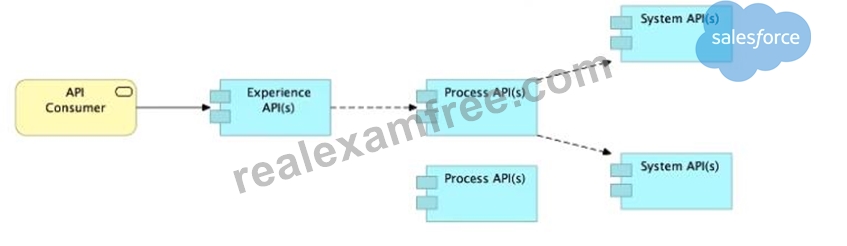
Answer: D
Explanation:
Correct Answe r: Allow System APIs to return data that is NOT currently required by the identified Process or Experience APIs.
*****************************************
>> All customizations for the end-user application should be handled in "Experience API" only. Not in Process API
>> We should use tiered approach but NOT always by creating exactly one API for each of the 3 layers. Experience APIs might be one but Process APIs and System APIs are often more than one. System APIs for sure will be more than one all the time as they are the smallest modular APIs built in front of end systems.
>> Process APIs can call System APIs as well as other Process APIs. There is no such anti-design pattern in API-Led connectivity saying Process APIs should not call other Process APIs.
So, the right answer in the given set of options that makes sense as per API-Led connectivity principles is to allow System APIs to return data that is NOT currently required by the identified Process or Experience APIs. This way, some future Process APIs can make use of that data from System APIs and we need NOT touch the System layer APIs again and again.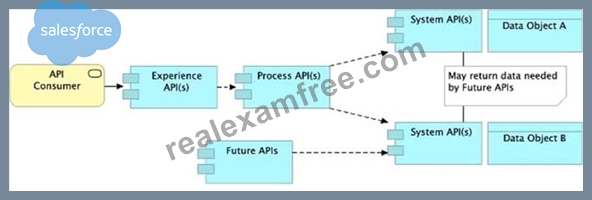
NEW QUESTION # 78
A customer wants to monitor and gain insights about the number of requests coming in a given time period as well as to measure key performance indicators (response times, CPU utilization, number of active APIs).
Which tool provides these data insights?
Answer: D
Explanation:
Understanding Anypoint Monitoring and Its Capabilities:
Anypoint Monitoring provides comprehensive visibility into Mule applications, offering metrics and analytics such as request counts, response times, CPU utilization, memory usage, and other key performance indicators (KPIs). This tool is designed to help teams monitor API usage, troubleshoot issues, and optimize application performance.
Evaluating the Options:
Option A (Correct Answer): Anypoint Monitoring is the ideal tool for this requirement. It provides real-time insights into metrics such as the number of requests, response times, CPU utilization, and active API usage.
Option B (API Manager): API Manager focuses on API lifecycle management, including applying policies, managing contracts, and setting access controls. It does not provide performance monitoring or KPI tracking.
Option C (Runtime Alerts): Runtime Alerts can notify users of specific conditions, like high CPU usage, but they do not provide a full suite of metrics or insights over a given time period.
Option D (Functional Monitoring): Functional Monitoring focuses on functional testing of APIs rather than performance and usage metrics. It does not provide continuous KPI tracking.
Conclusion:
Option A is the correct answer. Anypoint Monitoring is the most suitable tool to track the specified metrics, providing detailed insights into API requests, response times, CPU usage, and active API counts.
For further details, refer to MuleSoft's Anypoint Monitoring documentation on configuring dashboards and tracking performance metrics.
NEW QUESTION # 79
......
With a Mule-Arch-201 certification, you can not only get a good position in many companies, but also make your financial free come true. Besides, you can have more opportunities and challenge that will make your life endless possibility. We promise you that Mule-Arch-201 Actual Exam must be worth purchasing, and they can be your helper on your way to get success in gaining the Mule-Arch-201 certificate. Come and you will be a winner!
Latest Mule-Arch-201 Questions: https://www.realexamfree.com/Mule-Arch-201-real-exam-dumps.html
2026 Latest RealExamFree Mule-Arch-201 PDF Dumps and Mule-Arch-201 Exam Engine Free Share: https://drive.google.com/open?id=1xzWXG4-ukh86MOGr0vM8VBix-buomxlc