What we provide for you is the latest and comprehensive AI-103 exam dumps, the safest purchase guarantee and the immediate update of AI-103 exam software. Free demo download can make you be rest assured to buy; one-year free update of AI-103 Exam software after payment can assure you during your preparation for the exam. What's more, what make you be rest assured most is that we develop the exam software which will help more candidates get AI-103 exam certification.
| Section | Weight | Objectives |
|---|---|---|
| Plan and manage Azure AI solutions | 25–30% | - Design Azure AI infrastructure
|
| Implement information extraction and knowledge mining | 10–15% | - Build knowledge bases and search solutions
|
| Implement text and speech analysis solutions | 10–15% | - Implement speech capabilities
|
| Implement generative AI and agentic solutions | 30–35% | - Design and implement intelligent agents
|
| Implement computer vision solutions | 10–15% | - Implement image analysis and processing
|
Life is beset with all different obstacles that are not easily overcome. For instance, AI-103 exams may be insurmountable barriers for the majority of population. However, with the help of our exam test, exams are no longer problems for you. The reason why our AI-103 training materials outweigh other study prep can be attributed to three aspects, namely free renewal in one year, immediate download after payment and simulation for the software version. Now that using our AI-103 practice materials have become an irresistible trend, why don’t you accept AI-103 learning guide with pleasure?
NEW QUESTION # 30
You have a Microsoft Foundry project that processes procurement documents submitted by suppliers.
You need to implement two pipelines by using Azure Content Understanding in Foundry Tools. The solution must meet the following requirements:
* Include a pipeline named Pipeline1 that supports cost-effective, high-volume processing of standalone PDF invoices.
* Include a pipeline named Pipeline2 that supports cross-document validation by using multi-step reasoning and reference data.
How should you configure each pipeline? To answer, drag the appropriate configurations to the correct pipelines. Each configuration may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.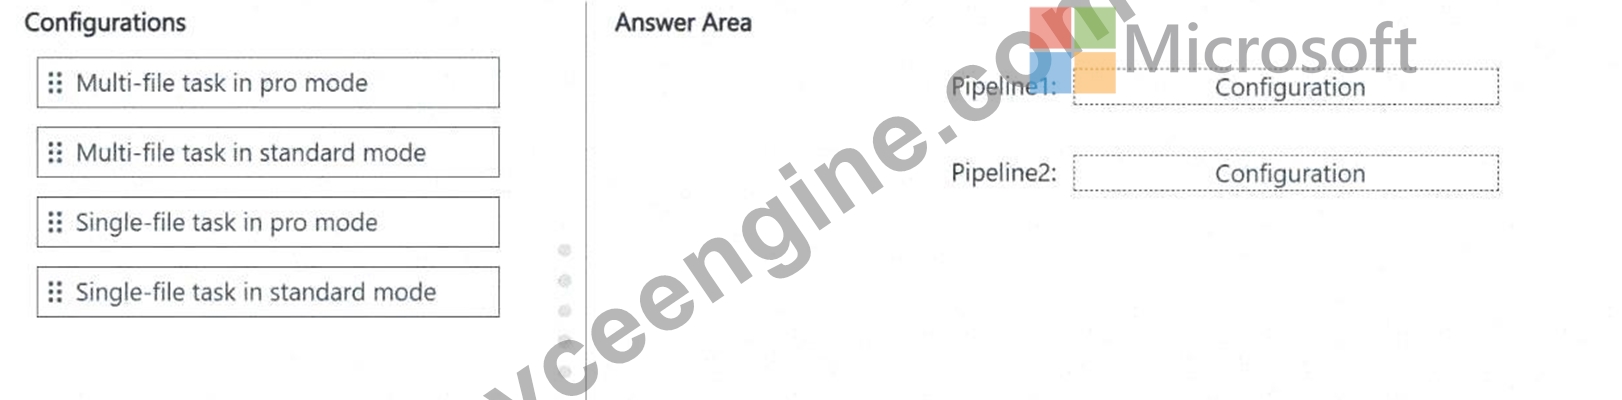
Answer:
Explanation: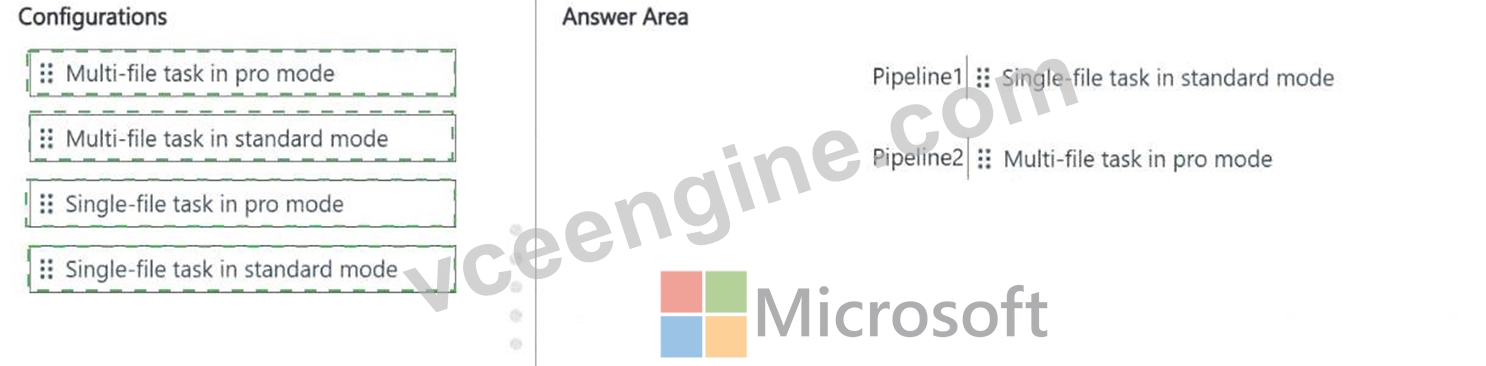
Explanation:
Pipeline1: Single-file task in standard mode
Pipeline2: Multi-file task in pro mode
Pipeline1 should use a single-file task in standard mode because the workload is high-volume processing of standalone PDF invoices. Azure Content Understanding standard mode is intended for individual files that require straightforward structured extraction, and Microsoft describes it as minimizing cost and latency for broad, data-centric processing scenarios. This makes it the best fit for cost-effective invoice extraction where each PDF can be processed independently.
Pipeline2 should use a multi-file task in pro mode because the requirement includes cross-document validation, multi-step reasoning, and reference data. Microsoft guidance states that pro mode is designed for advanced scenarios requiring multi-step reasoning and cross-file analysis, including processing multiple input files in a single request, validating or enriching data across documents, and using reference data to guide extraction and validation.
Single-file pro mode would add unnecessary capability for Pipeline1 and would not optimize for cost- effective high-volume standalone processing. Multi-file standard mode does not meet the pro-mode requirement for reference-data-based reasoning. Reference topics: Azure Content Understanding standard mode, pro mode, single-file tasks, multi-file tasks, field extraction, and procurement document validation.
NEW QUESTION # 31
You have a Microsoft Foundry project that contains an agent for a customer support chat app.
The agent uses a memory store and a memory search tool.
You need to ensure that the conversation history does NOT persist across separate sessions.
To what should you set the scope of the memory tool?
Answer: A
Explanation:
To ensure that conversation history does not persist across separate sessions, you must set the scope to session.
The session scope restricts data access to the current active chat instance. It automatically wipes or ignores previous data when a new session starts.
Incorrect:
[Not C]
user or {{$userId}} scope: Persists data across multiple sessions for that specific user. This would cause the exact issue you want to avoid by carrying historical context into new conversations.
References:
https://ai.gopubby.com/agents-with-memory-conceptual-undestanding-part-01-f6caedfcd96d?gi=a9aa95df15c6
NEW QUESTION # 32
You have a web app named App1 that sends requests to a multimodal chat model deployment in a Microsoft Foundry project. User messages can contain both text and images. Currently, App1 includes image URLs as plain text inside the message content, so the model cannot recognize them as images. You need to send the message as a structured array that includes both the text portion and the image reference.
Answer: B
Explanation:
A vision-enabled Chat Completions request must represent the user message as a multimodal content array.
One item contains the prompt with " type " : " text " , while another contains the image reference with " type ": " image_url " and an image_url.url property:
" content " : [
{ " type " : " text " , " text " : " Analyze this image. " },
{ " type " : " image_url " , " image_url " : { " url " : " < image-url > " }}
]
This structure explicitly identifies each modality, allowing the deployed model to route the text and image through the appropriate processing paths. A URL embedded in an ordinary string remains text and is not interpreted as visual input. Microsoft's documented Chat Completions schema shows the text and image objects inside the user message's content array.
Request metadata does not define model input, and a system message should contain behavioral instructions rather than the user's image attachment. Base64 images are supported, but the encoded value must be formatted as a data URL and supplied through the structured image item-not inserted into a plain content string.
Study Guide alignment: deploy and consume multimodal models, integrate generative workflows into applications, and design multimodal-understanding workflows .
NEW QUESTION # 33
You have a Microsoft Foundry project that contains a customer support agent grounded in internal documentation.
After a recent update, users report the following issues:
* Some answers are unsupported by retrieved documents.
* A small number of responses are flagged for policy violations.
You need to evaluate each issue.
Which observability signals should you use for each issue? To answer, drag the appropriate observability signals to the correct issues. Each observability signal may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.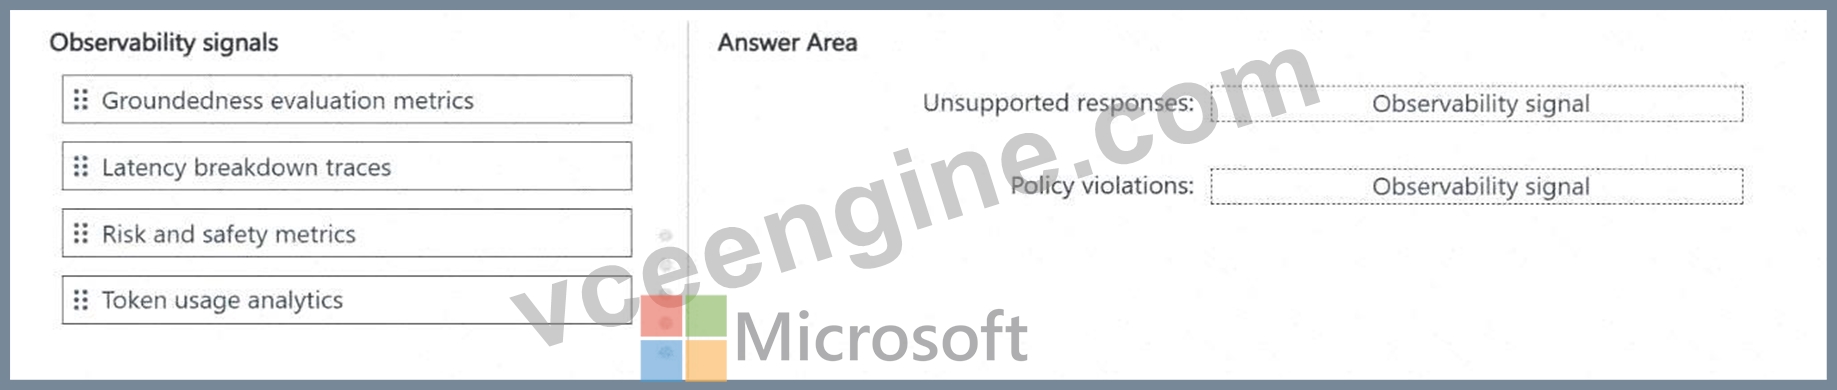
Answer:
Explanation: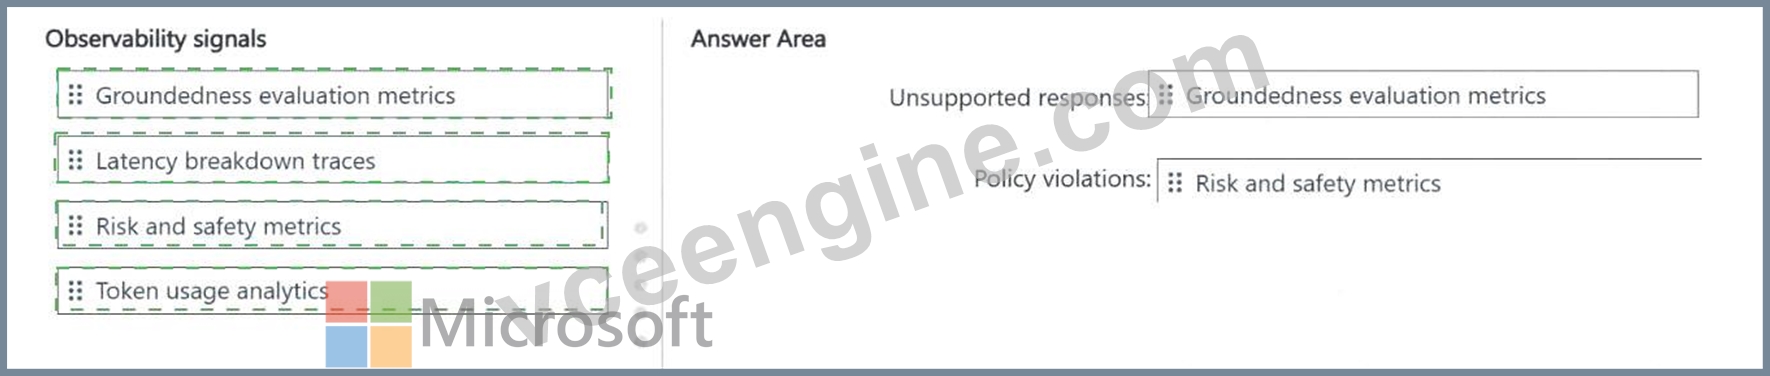
Explanation:
Unsupported responses: Groundedness evaluation metrics
Policy violations: Risk and safety metrics
For unsupported responses, use Groundedness evaluation metrics . In a Retrieval Augmented Generation scenario, the key question is whether the generated answer is supported by the retrieved context. Microsoft Foundry built-in evaluators define Groundedness as the RAG metric that measures how grounded a response is in retrieved context and returns a model-based score; Groundedness Pro evaluates whether the response is grounded in retrieved context by using Azure AI Content Safety. This directly matches answers that are unsupported by internal documentation.
For policy violations, use Risk and safety metrics . Microsoft Foundry risk and safety evaluators assess generated responses for safety risks such as hate and unfairness, sexual content, violence, self-harm, protected material, indirect attacks, code vulnerability, ungrounded attributes, prohibited actions, and sensitive data leakage. The guidance states that these evaluators assign risk and safety severity or pass/fail outcomes for AI responses and agent behavior.
Latency breakdown traces diagnose performance, not correctness or policy compliance. Token usage analytics diagnose cost and prompt/response size, not unsupported claims or safety violations. Reference topics:
Microsoft Foundry observability, RAG evaluators, groundedness, risk and safety evaluators, and agent quality evaluation.
NEW QUESTION # 34
Hotspot Question
You have a Python application named App1 that integrates with a Microsoft Foundry project named Project1.
You need to ensure that App1 meets the following requirements:
- Authenticates by using a Microsoft Entra managed identity
- Sends prompts to a deployed model by using the Azure OpenAI Responses API How should you complete the Python code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.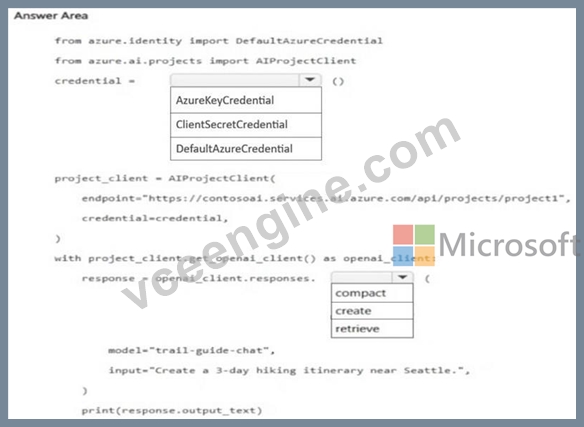
Answer:
Explanation: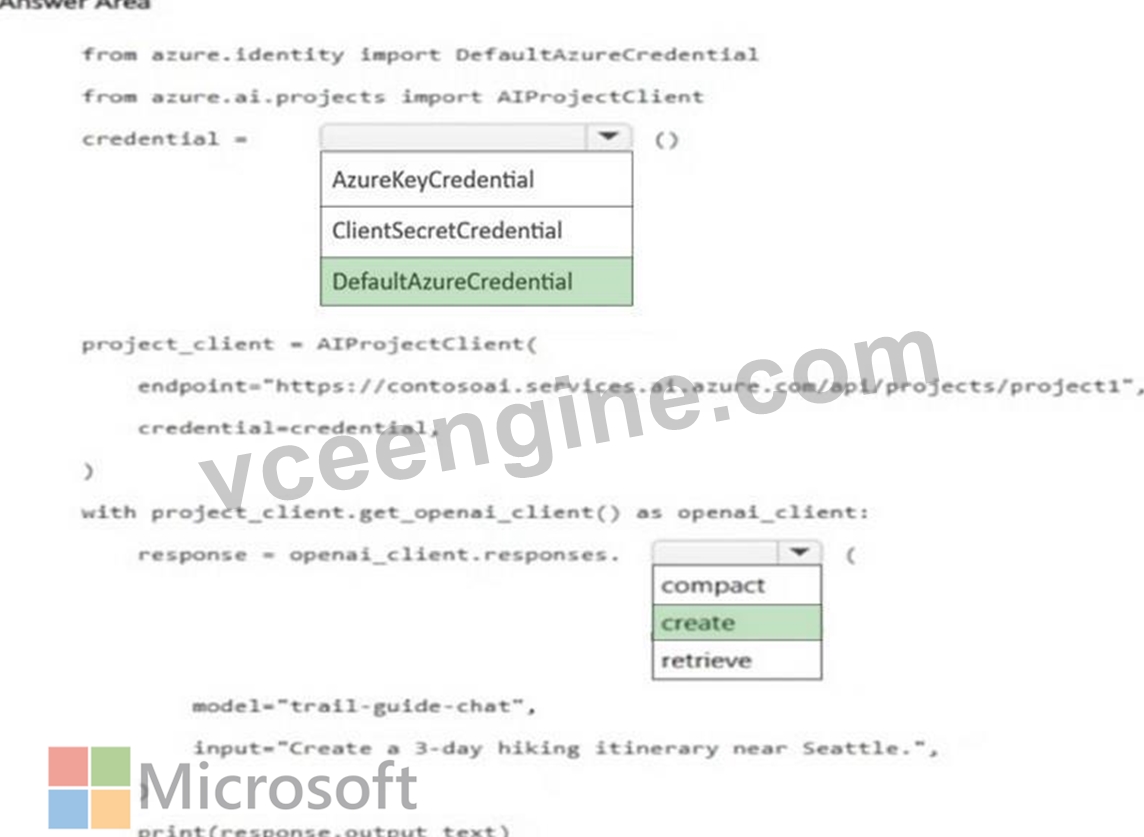
NEW QUESTION # 35
......
We also provide you with customizable desktop Central Finance in Developing AI Apps and Agents on Azure (AI-103) practice test software and web-based Microsoft AI-103 practice exam. You can adjust timings and Developing AI Apps and Agents on Azure (AI-103) questions number of our AI-103 practice exams according to your training needs. These Microsoft AI-103 Practice Tests simulate the real AI-103 exam pattern, track your progress, and help you overcome mistakes. Our AI-103 desktop software is compatible with Windows.
Valid AI-103 Exam Topics: https://www.vceengine.com/AI-103-vce-test-engine.html