Are you still staying up for the DP-750 exam day and night? If your answer is yes, then you may wish to try our DP-750 exam materials. We are professional not only on the content that contains the most accurate and useful information, but also on the after-sales services that provide the quickest and most efficient assistants. With our DP-750 practice torrent for 20 to 30 hours, we can claim that you are ready to take part in your DP-750 exam and will achieve your expected scores.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 2: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 4: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
There is no doubt that obtaining this DP-750 certification is recognition of their ability so that they can find a better job and gain the social status that they want. Most people are worried that it is not easy to obtain the certification of DP-750, so they dare not choose to start. We are willing to appease your troubles and comfort you. We are convinced that our DP-750 test material can help you solve your problems. Compared to other learning materials, our products are of higher quality and can give you access to the DP-750 certification that you have always dreamed of.
NEW QUESTION # 81
You have an Azure Databricks workspace that contains multiple all-purpose clusters. You discover that some clusters remain idle for long periods after users finish their work. You need to reduce compute costs without affecting active workloads. What should you do?
Answer: A
Explanation:
The correct answer is D - configure automatic termination.
The problem is specific: clusters sit idle after users finish working but nobody manually shuts them down.
Automatic termination solves this directly - once a cluster has been idle for the configured period (no running commands, no attached notebooks with active execution), it shuts itself down. You eliminate the idle cost without any manual intervention and without affecting any workload that is actually running.
Option A (convert to job clusters) would force users off interactive all-purpose clusters, disrupting their development workflow. Option B (spot instances) reduces the hourly rate while a cluster is running but does nothing about the idle-time problem - a cheaper idle cluster is still waste. Option C (enable autoscaling) reduces the number of workers during light load but keeps the cluster alive at the minimum node count. It saves some cost but doesn't fully eliminate idle spend the way auto-termination does.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#auto-termination
NEW QUESTION # 82
You need to configure resiliency for a job in Lakeflow Jobs named Job1 to meet the pipeline deployment and operation requirements.
What should you do?
Answer: D
Explanation:
Task-level retries allow the ingestion task to recover automatically from transient failures without rerunning unrelated tasks or restarting the complete workflow. Downstream tasks remain governed by their dependencies and start only after ingestion succeeds. This provides focused failure recovery and reduces unnecessary compute consumption. Disabling retries and relying on manual execution directly contradicts the requirement for resilient, automated pipeline operation. Setting the retry count to zero also prevents automatic retry behavior. Restarting the workflow from the first task whenever any task fails would repeat completed processing, increase costs, and potentially reingest data unnecessarily. Lakeflow Jobs supports individual retry policies for tasks, including the number of retries and delay between attempts, making option D the most controlled and operationally efficient configuration. Microsoft Learn
NEW QUESTION # 83
You have an Azure Databricks workspace.
You have a streaming table named sales_order that is populated by using a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
You need to create a new streaming table named sales_order_by_city that summarizes sales by city and calculates the total sales per city.
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.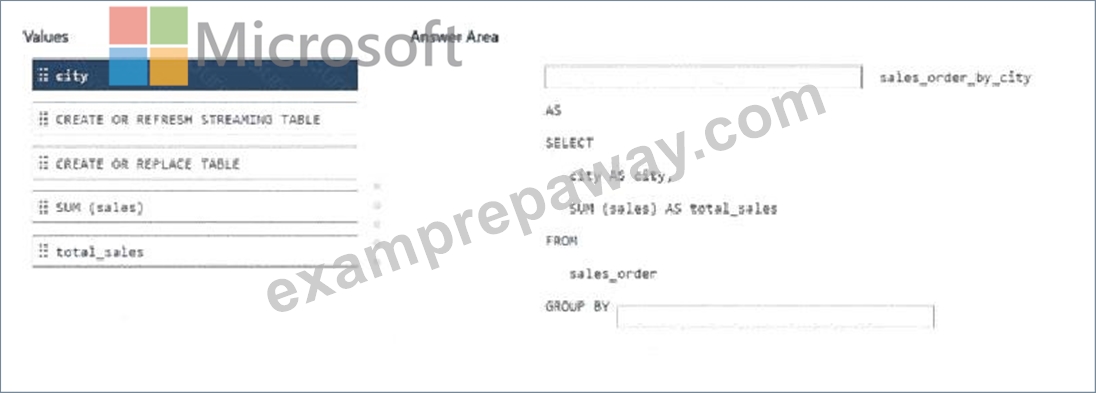
Answer:
Explanation: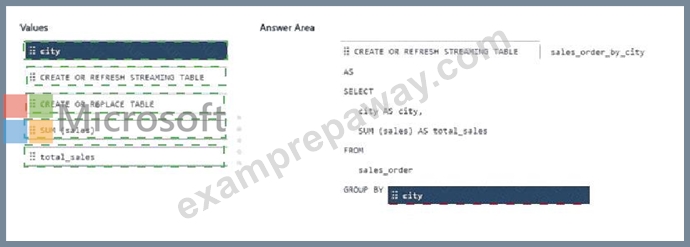
Explanation:
CREATE OR REFRESH STREAMING TABLE
city
CREATE OR REFRESH STREAMING TABLE defines a streaming table managed by Lakeflow Spark Declarative Pipelines. When the pipeline refreshes, Databricks incrementally processes newly available source data and maintains the resulting table. CREATE OR REPLACE TABLE would create a conventional table and does not provide the required streaming-table semantics. The query selects city AS city and calculates SUM(sales) AS total_sales. Because the aggregation must produce one result for each city, the GROUP BY expression must be city. Neither SUM(sales) nor total_sales belongs in the grouping clause: the former is the aggregate calculation, while the latter is only the alias assigned to its result. This produces continuously maintained city-level sales totals from the sales_order source table.
NEW QUESTION # 84
You have an Azure Databricks workspace that contains the objects shown in the following table.
Name | Type
Catalog1 | Catalog
Schema1 | Schema
Sales1 | Table
Notebook1 | Notebook
Space1 | AI/BI Genie space
Users often use the following words to refer to a sale: transaction, event, order, and invoice.
You need to create a knowledge store. The solution must ensure that when the users use any of the words in Space1, Genie queries the Sales1 table. Any other Genie spaces must remain unaffected.
To which object should you add the instructions?
Answer: D
Explanation:
The instructions must be added to Space1 because a Genie knowledge store is scoped to the individual Genie space, now called a Genie Agent. Adding synonyms and business-language instructions there teaches Space1 that "transaction," "event," "order," and "invoice" refer to sales information in Sales1. The configuration affects only that Genie space, satisfying the requirement that other spaces remain unchanged. Adding instructions to Sales1 or Schema1 would modify shared Unity Catalog metadata and could affect other consumers of those objects. Notebook1 is unrelated to the semantic instructions used by Genie when converting natural-language questions into SQL. Genie knowledge stores contain space-specific definitions, synonyms, join relationships, SQL expressions, and prompt-matching guidance without changing the underlying Unity Catalog objects. Microsoft Learn
NEW QUESTION # 85
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount != None)
Does this meet the goal?
Answer: B
Explanation:
The correct answer is B - No.
This is a common Python-to-PySpark trap. In pure Python, comparing a value to None with != works as expected. In PySpark, null comparisons follow SQL null semantics: any comparison involving NULL returns NULL (not True or False). So df.filter(df.order_amount != None) doesn't evaluate to True for non-null rows
- the comparison itself returns NULL for null values, and Spark interprets NULL in a filter as False, effectively dropping null rows. But the behaviour is undefined in edge cases and is not the documented approach.
More practically, Python's None and Spark's SQL NULL are different concepts. PySpark Column objects don't support Python's native equality/inequality semantics for null checking. The result is typically an empty DataFrame or incorrect filtering behaviour.
Always use .isNotNull() or .isNull() for null checks in PySpark column expressions. These methods are specifically designed for SQL-null-aware comparisons and produce correct, predictable results.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 86
......
In a year after your payment, we will inform you that when the DP-750 exam guide should be updated and send you the latest version. Our company has established a long-term partnership with those who have purchased our DP-750 exam questions. We have made all efforts to update our products in order to help you deal with any change, making you confidently take part in the DP-750 exam. Every day they are on duty to check for updates of DP-750 Study Materials for providing timely application. We also welcome the suggestions from our customers, as long as our clients propose rationally. We will adopt and consider it into the renovation of the DP-750 exam guide. Anyway, after your payment, you can enjoy the one-year free update service with our guarantee.
New DP-750 Exam Guide: https://www.examprepaway.com/Microsoft/braindumps.DP-750.ete.file.html