In the case of studying with outdated Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice questions, you will fail and lose your resources. TestkingPass made an DP-750 Questions for the students so that they don't get confused to prepare for DP-750 Certification Exam successfully in a short time. TestkingPass has designed the real DP-750 exam dumps after consulting many professionals and receiving positive feedback.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
>> DP-750 Trustworthy Exam Content <<
We have been focusing on perfecting the DP-750 exam dumps by the efforts of our company’s every worker no matter the professional expert or the 24 hours online services. We are so proud that we own the high pass rate to 99%. This data depend on the real number of our worthy customers who bought our DP-750 Study Guide and took part in the real DP-750 exam. Obviously, their performance is wonderful with the help of our outstanding DP-750 learning materials.
NEW QUESTION # 37
You have an Azure Databricks workspace named Workspace1 that is attached to a Unity Catalog metastore named metastore1 You need to register an Azure Storage account named account1 that has a hierarchical namespace enabled as an external location The external location must use a managed identity to authenticate to account1 and the solution must follow the principle of least privilege.
Which three actions should you perform in sequence' To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.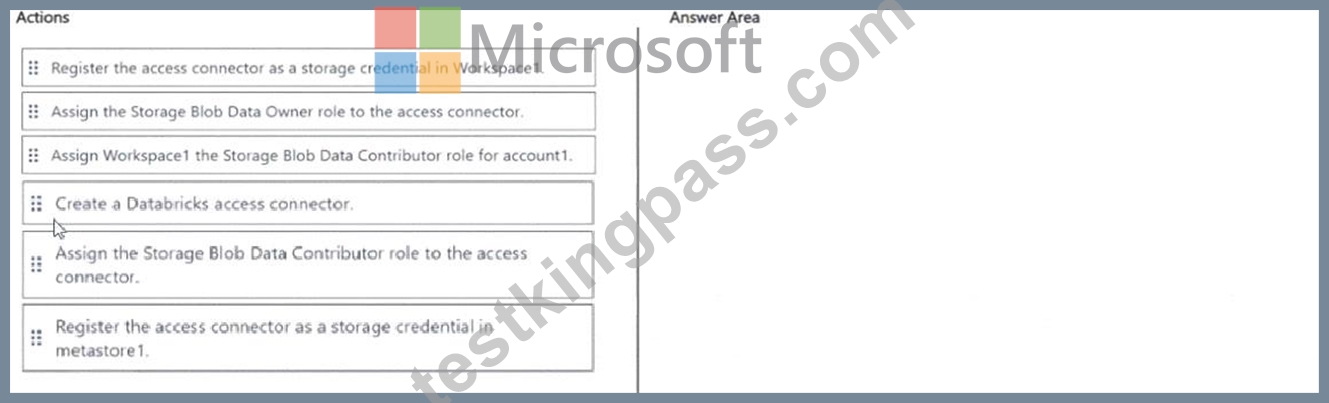
Answer:
Explanation: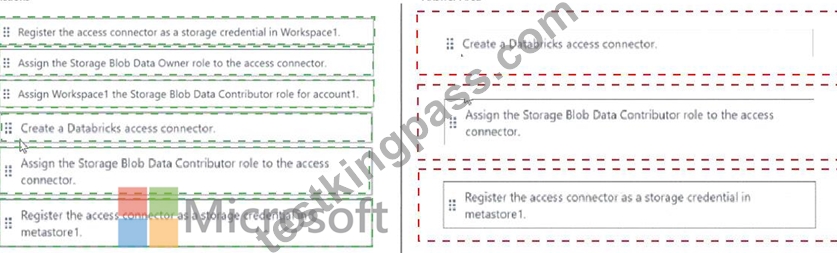
Explanation:
Registering an ADLS Gen2 account as an external location in Unity Catalog requires three steps in a specific order:
Step 1: Create a Databricks Access Connector. This Azure resource wraps a system-assigned or user-assigned managed identity. It is the credential-less authentication bridge between Databricks and Azure Storage - no SAS tokens or access keys are stored anywhere in the workspace.
Step 2: Create a Storage Credential in Unity Catalog that references the Access Connector. This object tells Unity Catalog 'use this identity when accessing storage.' The Storage Credential is the reusable authentication object.
Step 3: Create an External Location that maps a Unity Catalog path to the specific ADLS Gen2 container using the Storage Credential. This is the object that grants Databricks users access to files under that path, and it respects the principle of least privilege by scoping access to a specific container.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/storage-credentials
NEW QUESTION # 38
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job1 that processes data continuously and fails periodically due to transient errors.
You need to ensure that Job1 meets the following requirements:
- Resumes processing from the point that Job1 failed
- Minimizes how long it takes to restart Job1
- Minimizes the costs to restart Job1
What should you do?
Answer: B
Explanation:
You must use checkpointing.
Checkpointing is the native Apache Spark mechanism designed specifically to handle failures in Structured Streaming jobs. It saves the exact execution state and progress to cloud storage (like Azure Data Lake Storage), allowing the job to resume precisely where it left off without data loss.
Resumes from Failure Point: The checkpoint directory stores the stream offsets. When restarted, Spark reads these offsets to pick up exactly where it failed.
Minimizes Restart Time: By saving the state, Spark does not need to recompute historical streaming data or re-evaluate the entire stream architecture from scratch.
Minimizes Restart Costs: It prevents the reprocessing of duplicate data, saving valuable cluster compute time and reducing cloud infrastructure costs.
Reference:
https://www.linkedin.com/posts/shilpa-das-ln_what-is-checkpointing-in-spark-checkpointing- activity-7297113790393815041-AhPg
NEW QUESTION # 39
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
Answer: D
Explanation:
The best trigger type for this scenario is the Continuous trigger.
Immediate Processing: The Continuous trigger mode processes new records as soon as they arrive at the configured data sources. This matches your requirement to ingest and process records without waiting for an artificial time interval.
Native Serverless Support: When paired with serverless compute, Lakeflow Jobs efficiently manage resources by automatically scaling up or down according to the real-time stream volume.
Built-in Fault Tolerance: Continuous pipelines on Databricks automatically handle failures by retrying with an exponential backoff policy, keeping your automated ingestion operational 24/7 without manual intervention.
Reference:
https://docs.databricks.com/aws/en/jobs/continuous
NEW QUESTION # 40
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.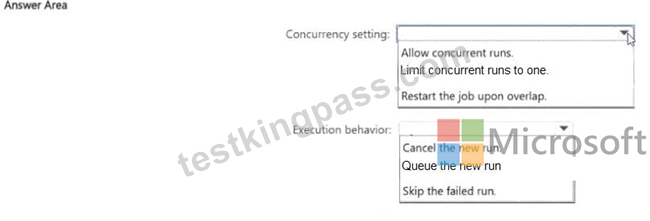
Answer:
Explanation: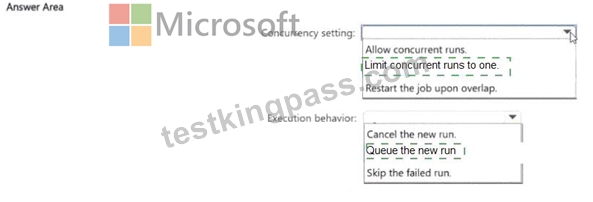
Explanation:
Two settings address the overlapping-run problem:
Concurrent Runs policy set to 'Skip' (or 'Allow only one concurrent run'). When a new scheduled trigger fires while the previous run is still in progress, the new run is skipped rather than starting alongside the ongoing one. This prevents two runs from writing to the same tables at the same time - which is the data corruption risk the question highlights.
Cron-based schedule for the hourly trigger. A cron expression defines the regular execution cadence.
Combined with the concurrency setting, the job runs hourly but never overlaps.
An alternative to 'Skip' is 'Wait' (queue the new run), which ensures every scheduled run eventually executes
- but for this scenario where overlapping is the primary concern, skipping the missed run is typically preferable to building up a queue of back-to-back executions.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#concurrent-runs
NEW QUESTION # 41
You have an Azure Databricks workspace.
You have a streaming table named sales_order that is populated by using a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
You need to create a new streaming table named sales_order_by_city that summarizes sales by city and calculates the total sales per city.
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.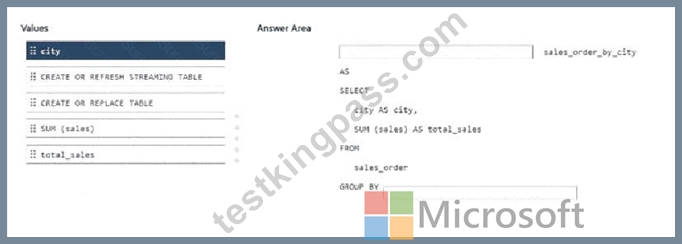
Answer:
Explanation: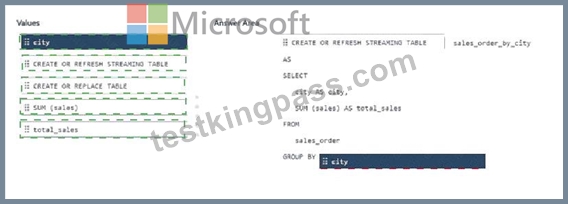
Explanation:
CREATE OR REFRESH STREAMING TABLE
city
CREATE OR REFRESH STREAMING TABLE defines a streaming table managed by Lakeflow Spark Declarative Pipelines. When the pipeline refreshes, Databricks incrementally processes newly available source data and maintains the resulting table. CREATE OR REPLACE TABLE would create a conventional table and does not provide the required streaming-table semantics. The query selects city AS city and calculates SUM(sales) AS total_sales. Because the aggregation must produce one result for each city, the GROUP BY expression must be city. Neither SUM(sales) nor total_sales belongs in the grouping clause: the former is the aggregate calculation, while the latter is only the alias assigned to its result. This produces continuously maintained city-level sales totals from the sales_order source table.
NEW QUESTION # 42
......
TestkingPass is famous for our company made these exam questions with accountability. We understand you can have more chances getting higher salary or acceptance instead of preparing for the DP-750 exam. Our DP-750 practice materials are made by our responsible company which means you can gain many other benefits as well. We offer free demos of our DP-750 Exam Questions for your reference, and send you the new updates of our DP-750 study guide if our experts make them freely. All we do and the promises made are in your perspective.
DP-750 Free Pdf Guide: https://www.testkingpass.com/DP-750-testking-dumps.html