Microsoftは成功の会社で、さまざまな認証と試験を提供します。我々の参考資料は実際の試験によって、弊社のAI-300資料をアップグレードしています。あなたの持っているすべての商品は一年の無料更新を得られています。あなたももっと多くの時間があってAI-300試験をよく準備します。
| Section | Objectives |
|---|---|
| Design and implement generative AI solutions | - RAG (Retrieval Augmented Generation) solutions
|
| Operationalizing machine learning solutions | - ML lifecycle management
|
| Implement secure and scalable AI systems | - Scalability and performance optimization
|
| Plan and design AI solutions using Azure AI services | - Requirements gathering and solution architecture
|
AI-300トレーニングガイドは、常にお客様に最高のサービスをお約束します。 AI-300試験材料の認定品質基準に一致するように慎重にテストおよび作成し、AI-300実践材料に関する特定の統計調査を実施しました。また、AI-300練習資料の運用システムは、さまざまな消費者グループに適応できます。事実は言葉よりも雄弁です。 99%の合格率は一般の人々の強力な信頼の証明であるため、長年の努力を通じて、AI-300試験準備は大いに有利なレビューを受けました。
質問 # 137
Hotspot Question
You create an Azure Machine Learning workspace and install the MLflow library.
You need to log different types of data by using the MLflow library.
Which method should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.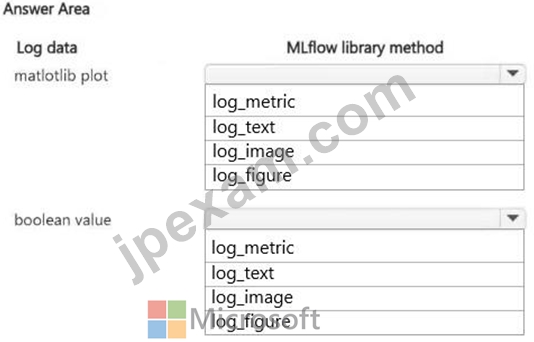
正解:
解説: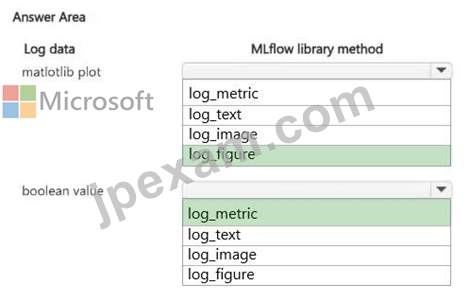
Explanation:
Box 1: log_figure
matlotlib plot
To log a Matplotlib plot data using the MLflow library, you should use the mlflow.log_figure() method.
Alternatively, if you save the Matplotlib plot as an image object (such as a PIL image) or a local image file first, you can use mlflow.log_image() or mlflow.log_artifact(). However, mlflow.log_figure() is specifically built to accept a Matplotlib figure object directly.
Box 2: log_metric
Boolean value
To log a boolean value data using the MLflow library in an Azure Machine Learning workspace, you should use the mlflow.log_param() method.
Alternatively, if you want to track it as a numerical metric over time, you can map the boolean to an integer (1 for True, 0 for False) and log it using mlflow.log_metric().
Depending on your precise objective for tracking the boolean data, choose from the two main use cases:
mlflow.log_param(key, value): Best for static configuration data, flags, or hyperparameter switches (e.g., is_training=True). Parameters accept string representations of boolean values.
mlflow.log_metric(key, value): Best if the boolean represents a status or binary occurrence that shifts or updates throughout execution. MLflow metrics exclusively accept numeric values, meaning you must cast the boolean into a 1 or 0.
Reference:
https://docs.azure.cn/en-us/machine-learning/how-to-log-view-metrics
質問 # 138
You need to recommend an experiment-tracking strategy that ensures consistent experiment results.
What should you recommend?
正解:D
解説:
MLflow is the industry-standard open-source platform for experiment tracking, and Azure Machine Learning has first-class native integration with it. When you use MLflow within an Azure ML job, parameters, metrics, and artifacts are automatically logged to the run history of the AML workspace, making every run reproducible and comparable. Option A (AML job output logs) only captures console output and lacks structured parameter and metric logging. Option C (Application Insights logs) is designed for application- level telemetry, not ML experiment metadata. Option D (Azure Monitor alerts) is a reactive notification tool, not a tracking system. MLflow ' s autologging capability means that for common frameworks such as scikit- learn, XGBoost, and PyTorch, parameters and metrics are captured without a single line of custom code, directly answering Fabrikam ' s requirement for consistent experiment tracking.
Microsoft Learn Reference Topic: Track ML experiments with MLflow - Azure Machine Learning MLflow integration
質問 # 139
An organization uses Microsoft Foundry to develop generative AI projects that access shared Azure resources such as storage accounts and vector databases.
The organization s security policy requires eliminating secret key-based authentication and enforcing least- privilege access.
You must configure identity and access so that:
Services authenticate without stored credentials.
Permissions are scoped appropriately across projects and shared resources.
You need to configure the appropriate identity or access mechanism for each requirement.
What should you configure in Microsoft Foundry to meet each requirement? To answer, move the appropriate configuration mechanisms to the correct requirements. You may use each configuration mechanism once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.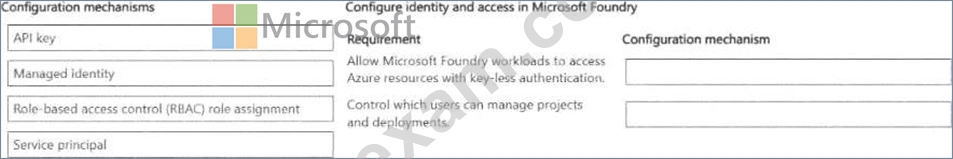
正解:
解説: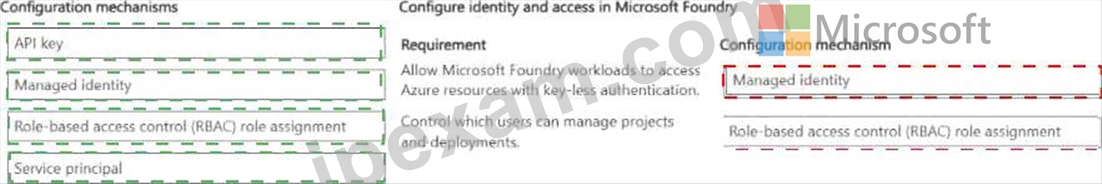
Explanation:
Managed Identity is Azure ' s solution for eliminating stored secrets and API keys from application configurations. When a Microsoft Foundry resource or its dependent compute has a system-assigned or user- assigned managed identity, it can authenticate to Azure services such as Storage, Key Vault, and Cognitive Services using Azure Entra ID tokens that are automatically issued and rotated by Azure. There are no keys to store, rotate, or accidentally expose in code or configuration files, directly satisfying the requirement to authenticate without stored credentials. Role-Based Access Control (RBAC) is the Azure governance mechanism for scoping permissions. By assigning specific built-in roles to the managed identity or to user and group principals at the correct scope - subscription, resource group, resource, or project level - the organization can enforce least-privilege access across different projects and shared resources.
Microsoft Learn Reference Topic: Configure managed identities and RBAC for Microsoft Azure AI Foundry resources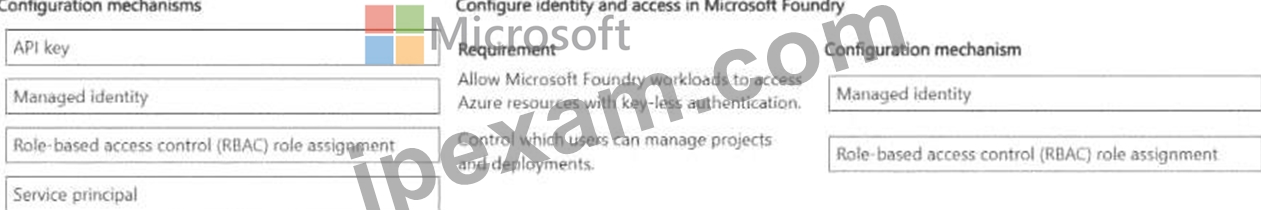
質問 # 140
Hotspot Question
You manage an Azure Machine Learning workspace. You create an experiment named experiment1 by using the Azure Machine Learning Python SDK v2 and MLflow.
You are reviewing the results of experiment1 by using the following code segment: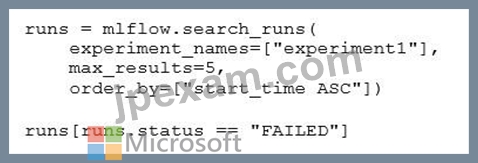
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.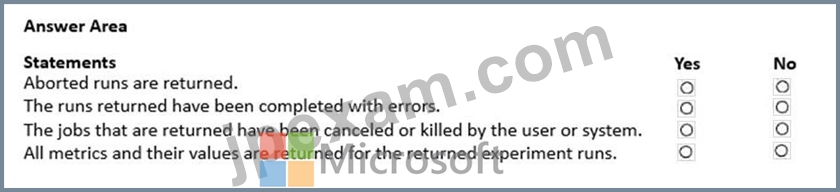
正解:
解説: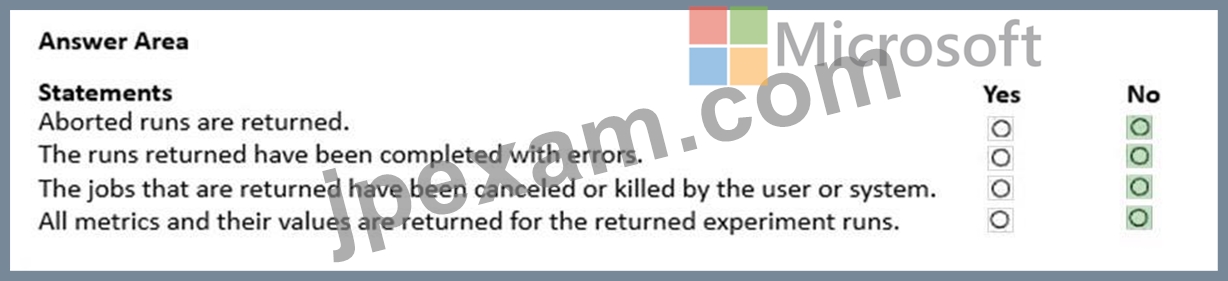
Explanation:
Box 1: No
Filter runs by status
You can also filter experiment by status. It becomes useful to find runs that are running, completed, canceled or failed.
Failed:The job/run has completed with errors.
KILLED: The job/run has been canceled or killed by the user/system.
The following example shows all the completed runs:
runs = mlflow.search_runs(experiment_ids=[ "1234-5678-90AB-CDEFG" ])
runs[runs.status == "FINISHED"]
Box 2: No
Ordering runs
By default, experiments are ordered descending by start_time, which is the time the experiment was queue in Azure Machine Learning.
However, here we have order_by=["start_time ASC"]. The five oldest experiments are returned.
Use the argument max_results from search_runs to limit the number of runs returned.
Box 3: No
Failed: The job/run has completed with errors.
KILLED: The job/run has been canceled or killed by the user/system.
Box 4: No
Getting metrics, parameters, artifacts and models
The method search_runs returns a Pandas Dataframe containing a limited amount of information by default. You can get Python objects if needed, which may be useful to get details about them.
Use the output_format parameter to control how output is returned:
runs = mlflow.search_runs(
experiment_ids=[ "1234-5678-90AB-CDEFG" ],
filter_string="params.num_boost_round='100'",
output_format="list",
)
Details can then be accessed from the info member. The following sample shows how to get the run_id:
last_run = runs[-1]
print("Last run ID:", last_run.info.run_id)
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-track-experiments-mlflow
質問 # 141
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to standardize how Fabrikam Inc. manages machine learning assets. Which action should you perform first?
正解:D
解説:
Scenario: To support the business goals, Fabrikam Inc. identifies these technical requirements:
Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
To centrally manage data assets, models, and environments across multiple Azure Machine Learning workspaces, you should Create a shared Azure Machine Learning workspace first.
The workspace serves as the top-level resource for your machine learning activities, providing a centralized place to view and manage the artifacts you create. While Registries are used to share assets (like models and environments) across existing workspaces, you must have a workspace as a prerequisite to create or use those assets in a project context.
Key Management Options
Azure provides several ways to organize and centralize your machine learning operations:
Shared Workspace: The primary container for managing data, compute, and experiments within a project team.
Registries: Used specifically for MLOps to decouple assets from specific workspaces, allowing them to be promoted through development, test, and production environments.
Hub Workspaces: A newer feature that groups multiple project workspaces under a single "hub" to share security settings, connections, and compute resources.
Reference:
https://docs.azure.cn/en-us/machine-learning/concept-workspace
質問 # 142
......
あなたはAI-300試験資料をよく勉強する限り、きっと短い時間で有難いAI-300認定試験資格証明書を取得できます。その後、あなたの生活もきっと大きく変わります。そして、いい友達ができ、いい生活を送ります。躊躇しないで、未来は本当に美しいです!AI-300試験資料有効であるかどうか分からない場合、Microsoftウエブサイトで、AI-300試験資料のデモを無料でダウンロードしてください。
AI-300受験記: https://www.jpexam.com/AI-300_exam.html