ちなみに、MogiExam Workday-Pro-Integrationsの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1wa-xETj1UoBpAfd3WBtPodD-cVpvW_Ql
初心者でも経験豊富な人でも、MogiExam学習教材は、長年にわたる試験概要の変化と業界の傾向に基づいて編集された専門家にとって最適な選択です。 Workday-Pro-Integrationsテストトレントは、学習の効率を向上させるのに役立つだけでなく、レビュー時間を最大数か月から1か月、さらには2週間または3週間に短縮するのにも役立ちます。 最大の改善を得る。 そして、Workday-Pro-Integrations試験問題により、Workday、あなたのWorkday Pro Integrations Certification Exam成功が保証されます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
| トピック 5 |
|
>> Workday-Pro-Integrations全真模擬試験 <<
社会に入った後の私達は最もの責任があって、学習の時間は少なくなりました。IT領域により良く発展したいなら、Workday Workday-Pro-Integrationsのような試験認定資格を取得するのは重要なことです。周知のようにWorkday Workday-Pro-Integrationsのような試験認定資格を手に入れると、会社の規則に沿う奨励があります。それで、速く我々MogiExamのWorkday Workday-Pro-Integrations試験問題集を入手しましょう。
質問 # 47
What is the purpose of a namespace in the context of a stylesheet?
正解:B
解説:
In the context of a stylesheet, particularly within Workday's Document Transformation system where XSLT (Extensible Stylesheet Language Transformations) is commonly used, a namespace serves a critical role in defining the scope and identity of elements and attributes. The correct answer, as aligned with Workday's integration practices and standard XSLT principles, is that a namespace "provides elements you can use in your code." Here's a detailed explanation:
* Definition and Purpose of a Namespace:
* A namespace in an XML-based stylesheet (like XSLT) is a mechanism to avoid naming conflicts by grouping elements and attributes under a unique identifier, typically a URI (Uniform Resource Identifier). This allows different vocabularies or schemas to coexist within the same document or transformation process without ambiguity.
* In XSLT, namespaces are declared in the stylesheet using the xmlns attribute (e.g., xmlns:xsl="
http://www.w3.org/1999/XSL/Transform" for XSLT itself). These declarations define the set of elements and functions available for use in the stylesheet, such as <xsl:template>, <xsl:value-of>, or <xsl:for-each>.
* For example, when transforming Workday data (which uses its own XML schema), a namespace might be defined to reference Workday-specific elements, enabling the stylesheet to correctly identify and manipulate those elements.
* Application in Workday Context:
* In Workday's Document Transformation integrations, namespaces are essential when processing XML data from Workday (e.g., Core Connector outputs) or external systems. The namespace ensures that the XSLT processor recognizes the correct elements from the source XML and applies the transformation rules appropriately.
* Without a namespace, the processor might misinterpret elements with the same name but different meanings (e.g., <name> in one schema vs. another). By providing a namespace, the stylesheet gains access to a specific vocabulary of elements and attributes, enabling precise coding of transformation logic.
* Why Other Options Are Incorrect:
* B. Indicates the start and end tag names to output: This is incorrect because namespaces do not dictate the structure (start and end tags) of the output. That is determined by the XSLT template rules and output instructions (e.g., <xsl:output> or literal result elements). Namespaces only define the identity of elements, not their placement or formatting in the output.
* C. Restricts the data the processor can access: While namespaces help distinguish between different sets of elements, they do not inherently restrict data access. Restrictions are more a function of security settings or XPath expressions within the stylesheet, not the namespace itself.
* D. Controls the filename of the transformed result: Namespaces have no bearing on the filename of the output. In Workday, the filename of a transformed result is typically managed by the Integration Attachment Service or delivery settings (e.g., SFTP or email configurations), not the stylesheet's namespace.
* Practical Example:
* Suppose you're transforming a Workday XML file containing employee data into a custom format. The stylesheet might include:
<xsl:stylesheet version="1.0" xmlns:xsl="http://www.w3.org/1999/XSL/Transform" xmlns:wd="http://www.
workday.com/ns">
<xsl:template match="wd:Employee">
<EmployeeName><xsl:value-of select="wd:Name"/></EmployeeName>
</xsl:template>
</xsl:stylesheet>
* Here, the wd namespace provides access to Workday-specific elements like <wd:Employee> and
<wd:Name>, which the XSLT processor can then use to extract and transform data.
Workday Pro Integrations Study Guide References:
* Workday Integration System Fundamentals: Explains XML and XSLT basics, including the role of namespaces in identifying elements within stylesheets.
* Document Transformation Module: Highlights how namespaces are used in XSLT to process Workday XML data, emphasizing their role in providing a vocabulary for transformation logic (e.g.,
"Understanding XSLT Namespaces").
* Core Connectors and Document Transformation Course Manual: Includes examples of XSLT stylesheets where namespaces are declared to handle Workday-specific schemas, reinforcing that they provide usable elements.
* Workday Community Documentation: Notes that namespaces are critical for ensuring compatibility between Workday's XML output and external system requirements in transformation scenarios.
質問 # 48
You are building an outbound EIB integration that uses a custom report to send worker data to a new Active Directory system. You must create a calculated field for the User ID, which the report will output. The User ID must follow the company's new standard format: the first three letters of the worker's first name, followed by the first three letters of their last name, with the entire string in lowercase.
Example: A worker named "Logan McNeil" must have a User ID of "logmcn".
Which combination of calculated fields should you use?
正解:D
解説:
This requirement is a classic calculated-field transformation for an outbound report-based integration. The first step is to use Substring Text to extract only the first three characters from the worker's first name and the first three characters from the worker's last name. After both substrings are produced, Concatenate Text joins those values into a single User ID string. Finally, Format Text is required to convert the combined result to lowercase so the output matches the Active Directory vendor standard. Evaluate Expression is not required because there is no conditional logic. Lookup Related Value is also inappropriate because the values are already available from worker name fields. Text Constant is not enough because the result must be dynamically built for each worker.
質問 # 49
When creating an XSLT file to transform the XML output of an EIB, you must have the XSL namespace.
What other namespace(s) do you need to process any part of the source XML file?
正解:A
解説:
When writing XSLT to transform an XML document, you must declare and reference all XML namespaces used in the source XML.
"To accurately access and transform nodes using XPath, every namespace in the source document must be declared in the XSLT stylesheet." This ensures that XPath expressions correctly match the fully qualified elements, especially when multiple namespaces are in use.
Why the others are incorrect:
* A (most commonly used) would be incomplete.
* C (ETV/XTT) are specific Workday terminologies but don't replace namespace declarations.
* D is incorrect; namespaces are required to avoid XPath resolution failures.
Reference:Workday XSLT Integration Training - "Namespace Requirements in XSLT for Workday XML Output"W3C XSLT and XPath Standards
質問 # 50
Refer to the following XML to answer the question below.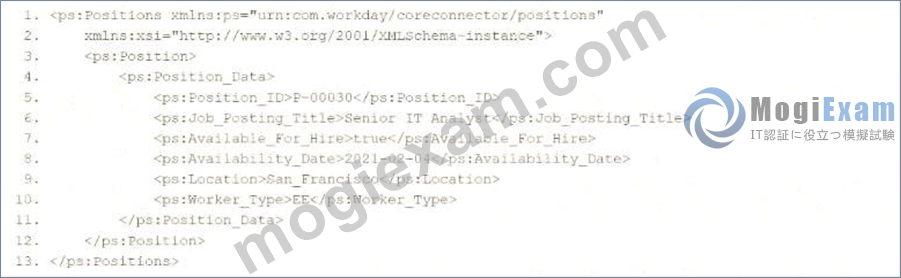
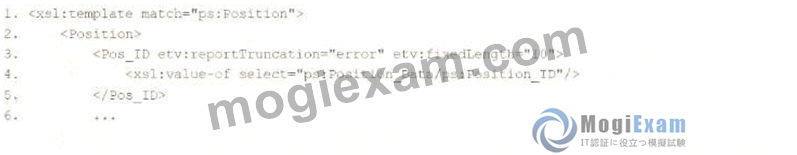
You need the integration file to format the ps:PositionJD field to 10 characters and report any truncated values as an error.
How will you start your template match on ps:Position to use Document Transformation (DT) to do the transformation using ETV with your truncation validation?
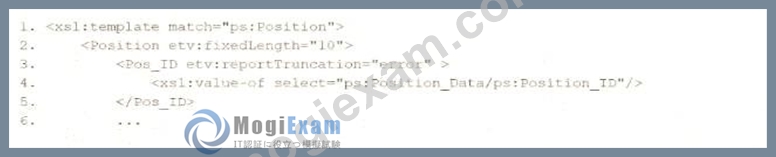
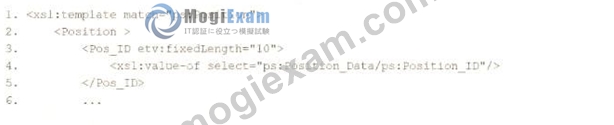
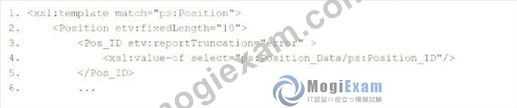
正解:D
解説:
In Workday integrations, Document Transformation (DT) using XSLT is employed to transform XML data, such as the output from a Core Connector or EIB, into a specific format for third-party systems. In this scenario, you need to transform the ps:Position_ID field within the ps:Position element to a fixed length of 10 characters and report any truncation as an error using Workday's Extension for Transformation and Validation (ETV) attributes. The template must match the ps:Position element and apply the specified formatting and validation rules.
Here's why option D is correct:
* Template Matching: The <xsl:template match="ps:Position"> correctly targets the ps:Position element in the XML, as shown in the provided snippet, ensuring the transformation applies to the appropriate node.
* ETV Attributes:
* etv:fixedLength="10" specifies that the Pos_ID field should be formatted to a fixed length of 10 characters. This ensures the output is truncated or padded (if needed) to meet the length requirement.
* etv:reportTruncation="error" instructs the transformation to raise an error if the ps:Position_ID value exceeds 10 characters and cannot be truncated without data loss, aligning with the requirement to report truncated values as errors.
* XPath Selection: The <xsl:value-of select="ps:Position_Data/ps:Position_ID"/> correctly extracts the ps:Position_ID value from the ps:Position_Data child element, as shown in the XML structure (<ps:
Position_ID>P-00030</ps:Position_ID>).
* Output Structure: The <Position><Pos_ID>...</Pos_ID></Position> structure ensures the transformed data is wrapped in meaningful tags for the target system, maintaining consistency with Workday integration practices.
Why not the other options?
* A.
xml
WrapCopy
<xsl:template match="ps:Position">
<Position>
<Pos_ID etv:fixedLength="10">
<xsl:value-of select="ps:Position_Data/ps:Position_ID"/>
</Pos_ID>
</Position>
</xsl:template>
This option includes etv:fixedLength="10" but omits etv:reportTruncation="error". Without the truncation reporting, it does not meet the requirement to report truncated values as errors, making it incorrect.
* B.
xml
WrapCopy
<xsl:template match="ps:Position">
<Position etv:fixedLength="10">
<Pos_ID etv:reportTruncation="error">
<xsl:value-of select="ps:Position_Data/ps:Position_ID"/>
</Pos_ID>
</Position>
</xsl:template>
This applies etv:fixedLength="10" to the Position element instead of Pos_ID, and etv:reportTruncation=" error" to Pos_ID. However, ETV attributes like fixedLength and reportTruncation should be applied to the specific field being formatted (Pos_ID), not the parent element (Position). This misplacement makes it incorrect.
* C.
xml
WrapCopy
<xsl:template match="ps:Position">
<Position etv:fixedLength="10">
<Pos_ID etv:reportTruncation="error">
<xsl:value-of select="ps:Position_Data/ps:Position_ID"/>
</Pos_ID>
</Position>
</xsl:template>
Similar to option B, this applies etv:fixedLength="10" to Position and etv:reportTruncation="error" to Pos_ID, which is incorrect for the same reason: ETV attributes must be applied to the specific field (Pos_ID) requiring formatting and validation, not the parent element.
To implement this in XSLT for a Workday integration:
* Use the template from option D to match ps:Position, apply etv:fixedLength="10" and etv:
reportTruncation="error" to the Pos_ID element, and extract the ps:Position_ID value using the correct XPath. This ensures the ps:Position_ID (e.g., "P-00030") is formatted to 10 characters and reports any truncation as an error, meeting the integration file requirements.
Workday Pro Integrations Study Guide: Section on "Document Transformation (DT) and ETV" - Details the use of ETV attributes like fixedLength and reportTruncation for formatting and validating data in XSLT transformations.
Workday Core Connector and EIB Guide: Chapter on "XML Transformations" - Explains how to use XSLT templates to transform position data, including ETV attributes for length and truncation validation.
Workday Integration System Fundamentals: Section on "ETV in Integrations" - Covers the application of ETV attributes to specific fields in XML for integration outputs, ensuring compliance with formatting and error-reporting requirements.
質問 # 51
Refer to the following XML to answer the question below.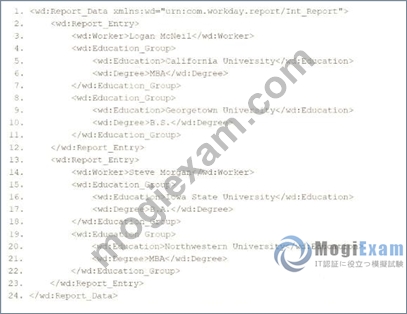
Within the template which matches on wd:Report_Entry, you would like to conditionally process the wd:
Education_Group elements by using an <xsl:apply-templates> element. What XPath syntax would be used for the select to iterate over only the wd:Education_Group elements where the Degree is an MBA?
正解:B
解説:
In Workday integrations, XSLT is used to transform XML data, such as the output from a web service- enabled report or EIB, into a desired format for third-party systems. In this scenario, you need to write XSLT to process wd:Education_Group elements within a template matching wd:Report_Entry, using an <xsl:apply- templates> element to iterate only over wd:Education_Group elements where the wd:Degree is "MBA." The correct XPath syntax for the select attribute is critical to ensure accurate filtering.
Here's why option A is correct:
* XPath Syntax Explanation: In XPath, square brackets [ ] are used to specify predicates or conditions to filter elements. The condition wd:Degree='MBA' checks if the wd:Degree child element has the value
"MBA." When applied to wd:Education_Group, the expression wd:Education_Group[wd:
Degree='MBA'] selects only those wd:Education_Group elements that contain a wd:Degree child element with the value "MBA."
* Context in XSLT: Within an <xsl:apply-templates> element in a template matching wd:Report_Entry, the select attribute uses XPath to specify which nodes to process. This syntax ensures that the template only applies to wd:Education_Group elements where the degree is "MBA," aligning with the requirement to conditionally process only those specific education groups.
* XML Structure Alignment: Based on the provided XML snippet, wd:Education_Group contains wd:
Education and wd:Degree child elements (e.g., <wd:Degree>MBA</wd:Degree>). The XPath wd:
Education_Group[wd:Degree='MBA'] correctly navigates to wd:Education_Group and filters based on the wd:Degree value, matching the structure and requirement.
Why not the other options?
* B. wd:Education_Group/wd:Degree='MBA': This is not a valid XPath expression for a predicate. It attempts to navigate to wd:Degree as a child but does not use square brackets [ ] to create a filtering condition. This would be interpreted as selecting wd:Degree elements under wd:Education_Group, but it wouldn't filter based on the value "MBA" correctly within an <xsl:apply-templates> context.
* C. wd:Report_Entry/wd:Education_Group/wd:Degree='MBA' 1:Degree='MBA': This is syntactically incorrect and unclear. It includes a malformed condition (1:Degree='MBA') and does not use proper XPath predicate syntax. It fails to filter wd:Education_Group elements based on wd:Degree='MBA' and is not valid for use in select.
* D. wd:Report_Entry/wd:Education_Group[wd:Degree='MBA' 1:Degree='MBA']: This is also syntactically incorrect due to the inclusion of 1:Degree='MBA' within the predicate. The 1: prefix is not valid XPath syntax and introduces an error. The correct predicate should only be wd:Degree='MBA' to filter the wd:Education_Group elements.
To implement this in XSLT:
* Within your template matching wd:Report_Entry, you would write an <xsl:apply-templates> element with the select attribute set to wd:Education_Group[wd:Degree='MBA']. This ensures that only wd:
Education_Group elements with a wd:Degree value of "MBA" are processed by the corresponding templates, effectively filtering out other degrees (e.g., B.S., B.A.) in the transformation.
This approach ensures the XSLT transformation aligns with Workday's XML structure and integration requirements for processing education data in a report output.
Workday Pro Integrations Study Guide: Section on "XSLT Transformations for Workday Integrations" - Details the use of XPath in XSLT for filtering XML elements, including predicates for conditional processing based on child element values.
Workday EIB and Web Services Guide: Chapter on "XML and XSLT for Report Data" - Explains the structure of Workday XML (e.g., wd:Education_Group, wd:Degree) and how to use XPath to navigate and filter data.
Workday Reporting and Analytics Guide: Section on "Web Service-Enabled Reports" - Covers integrating report outputs with XSLT for transformations, including examples of filtering elements based on specific values like degree types.
質問 # 52
......
MogiExamのWorkday Workday-Pro-Integrations認定試験の問題集について知っていますか?なぜWorkday-Pro-Integrations練習問題集を使った人達は口をきわめてほめたたえますか?本当に効果があるかどうかを試したいですか?では、MogiExamのサイトを訪問してWorkday Workday-Pro-Integrations認定試験の対策問題集をダウンロードしてください。Workday Workday-Pro-Integrations認証試験に関連する各問題集はデモ版を提供されていますから、先ず体験して、もしよければ、あなたが愛用する版を購入することができます。Workday Workday-Pro-Integrations試験練習問題集を購入して後、また一年間の無料更新サービスを得ることもできます。一年以内に、あなたが持っている資料を更新したい限り、MogiExamは最新バージョンの問題集を捧げます。この勉強資料があれば、楽にWorkday Workday-Pro-Integrations認定試験に合格することができます。
Workday-Pro-Integrations関連資料: https://www.mogiexam.com/Workday-Pro-Integrations-exam.html
さらに、MogiExam Workday-Pro-Integrationsダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1wa-xETj1UoBpAfd3WBtPodD-cVpvW_Ql