Certified-Data-Engineer-Professional Training Pdf Material & Certified-Data-Engineer-Professional Latest Study Material & Certified-Data-Engineer-Professional Test Practice Vce

No need to go after substandard Certified-Data-Engineer-Professional brain dumps for exam preparation that has no credibility. They just make you confused and waste your precious time and money. Compare our content with other competitors like Pass4sure's dumps, you will find a clear difference in Certified-Data-Engineer-Professional material. Most of the content there does not correspond with the latest syllabus content. It also does not provide you the best quality. Likewise the exam collection's brain dumps are not sufficient to address all exam preparation needs.
| Section | Objectives |
|---|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 3. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Create pipeline components using control flow operators such as if/else and foreach
- 6. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 7. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 8. Explain the advantages and disadvantages of streaming tables compared to materialized views
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 3. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 4. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Monitoring and Alerting | - Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
>> Certified-Data-Engineer-Professional Valid Exam Pdf <<
Valid Certified-Data-Engineer-Professional Test Discount, Best Certified-Data-Engineer-Professional Preparation Materials
If you choose our Certified-Data-Engineer-Professional exam review questions, you can share fast download. As we sell electronic files, there is no need to ship. After payment you can receive Certified-Data-Engineer-Professional exam review questions you purchase soon so that you can study before. If you are urgent to pass exam our exam materials will be suitable for you. Mostly you just need to remember the questions and answers of our Databricks Certified-Data-Engineer-Professional Exam Review questions and you will clear exams. If you master all key knowledge points, you get a wonderful score.
Databricks Certified Data Engineer Professional Sample Questions (Q241-Q246):
NEW QUESTION # 241
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
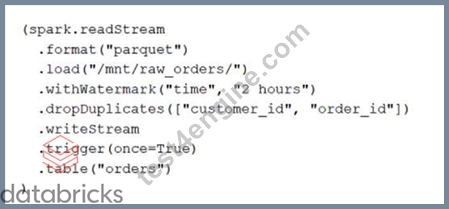
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system.
If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
- A. The orders table will not contain duplicates, but records arriving more than 2 hours late will be ignored and missing from the table.
- B. Duplicate records enqueued more than 2 hours apart may be retained and the orders table may contain duplicate records with the same customer_id and order_id.
- C. Duplicate records arriving more than 2 hours apart will be dropped, but duplicates that arrive in the same batch may both be written to the orders table.
- D. All records will be held in the state store for 2 hours before being deduplicated and committed to the orders table.
- E. The orders table will contain only the most recent 2 hours of records and no duplicates will be present.
Answer: B
NEW QUESTION # 242
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats. After converting a subset of data to Delta Lake, they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join, whereas queries on legacy formats used Sort Merge Joins. The queries reading Delta Lake data also scanned less data. Which reason could be attributed to the difference in query performance?
- A. Shuffle Hash Joins are always more efficient than Sort Merge Joins.
- B. The queries against the ORC tables leveraged the dynamic data skipping optimization but not the dynamic file pruning optimization.
- C. The queries against the Delta Lake tables were able to leverage the dynamic file pruning optimization.
- D. Delta Lake enables data skipping and file pruning using a vectorized Parquet reader.
Answer: D
Explanation:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage, data skipping, and file pruning. According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters, a process called data skipping and file pruning. Additionally, Delta uses a vectorized Parquet reader, which reduces I/O and CPU overhead. Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
NEW QUESTION # 243
An upstream system has been configured to pass the date for a given batch of data to the Databricks Jobs API as a parameter. The notebook to be scheduled will use this parameter to load data with the following code:
df = spark.read.format("parquet").load(f"/mnt/source/(date)")
Which code block should be used to create the date Python variable used in the above code block?
- A. import sys
date = sys.argv[1] - B. input_dict = input()
date= input_dict["date"] - C. date = spark.conf.get("date")
- D. dbutils.widgets.text("date", "null")
date = dbutils.widgets.get("date") - E. date = dbutils.notebooks.getParam("date")
Answer: D
Explanation:
The code block that should be used to create the date Python variable used in the above code block is:
dbutils.widgets.text("date", "null") date = dbutils.widgets.get("date") This code block uses the dbutils.widgets API to create and get a text widget named "date" that can accept a string value as a parameter. The default value of the widget is "null", which means that if no parameter is passed, the date variable will be "null". However, if a parameter is passed through the Databricks Jobs API, the date variable will be assigned the value of the parameter.
For example, if the parameter is "2021-11-01", the date variable will be "2021-11-01". This way, the notebook can use the date variable to load data from the specified path.
NEW QUESTION # 244
A platform team is creating a standardized template for Databricks Asset Bundles to support CI/CD. The template must specify defaults for artifacts, workspace root paths, and a run identity, while allowing a "dev" target to be the default and override specific paths. How should the team use databricks.yml to satisfy these requirements?
- A. Use roots, modules, profiles, actor, and targets; where profiles contain workspace and artifacts defaults and actor sets run identity.
- B. Use bundle, artifacts, workspace, run_as, and targets at the top level; set one target with default:true and override workspace paths or artifacts under that target.
- C. Use project, packages, environment, identity, and stages; set dev as default stage and override workspace under environment.
- D. Use deployment, builds, context, identity, and environments; set dev as default environment and override paths under builds.
Answer: B
Explanation:
In Databricks Asset Bundles, the databricks.yml file defines all top-level configuration keys, including bundle, artifacts, workspace, run_as, and targets. The targets section defines specific deployment contexts (for example, dev, test, prod). Setting default: true for a target marks it as the default environment. Overrides for workspace paths and artifact configurations can be defined inside each target while keeping defaults at the top level.
NEW QUESTION # 245
A data engineer is implementing a job to download multiple PDF files from a third-party provided REST API endpoint by specifying different report types. The REST API is time-consuming and encounters intermittent errors, so the engineer wants to track each download activity to know when it fails and to retry partially, while providing scalable throughput. The engineer needs to download ten report types, and the list can be changed over time. How should the data engineer achieve this?
- A. Define a list variable within a Notebook to loop through the report types to download them, and print the download results. Execute it as a Notebook tasks.
- B. Use a Delta Lake table to track each report download status as 10 rows, and use it as a source table to execute the download function as a Pandas UDF.
- C. Use a foreach task with a list of report types as its inputs.
- D. Define ten Notebook tasks to clearly track which report download failed.
Answer: C
Explanation:
A foreach task allows the job to dynamically iterate over a configurable list of report types, execute downloads in parallel, and track the success or failure of each item independently. This enables scalable throughput, partial retries for failed downloads, and easy updates when the list of report types changes, without hardcoding tasks or introducing unnecessary complexity.
NEW QUESTION # 246
......
If you want to pass the exam in the shortest time, our study materials can help you achieve this dream. Certified-Data-Engineer-Professional learning quiz according to your specific circumstances, for you to develop a suitable schedule and learning materials, so that you can prepare in the shortest possible time to pass the exam needs everything. If you use our Certified-Data-Engineer-Professional training prep, you only need to spend twenty to thirty hours to practice our Certified-Data-Engineer-Professional study materials and you are ready to take the exam.
Valid Certified-Data-Engineer-Professional Test Discount: https://www.test4engine.com/Certified-Data-Engineer-Professional_exam-latest-braindumps.html
- Certified-Data-Engineer-Professional Dump Collection 🏐 New Certified-Data-Engineer-Professional Braindumps Files 🚎 Certified-Data-Engineer-Professional Dump Check ✋ Enter [ www.prep4sures.top ] and search for ➽ Certified-Data-Engineer-Professional 🢪 to download for free 👽Certified-Data-Engineer-Professional Dump Check
- Databricks Certified-Data-Engineer-Professional Exam Questions Preparation Material By Pdfvce 🤦 Go to website ☀ www.pdfvce.com ️☀️ open and search for ➥ Certified-Data-Engineer-Professional 🡄 to download for free 🚶Certified-Data-Engineer-Professional Latest Exam Simulator
- Reliable Databricks Certified-Data-Engineer-Professional Valid Exam Pdf With Interarctive Test Engine - Trustable Valid Certified-Data-Engineer-Professional Test Discount 🚲 Open website ⏩ www.prepawayexam.com ⏪ and search for { Certified-Data-Engineer-Professional } for free download 🍲New Certified-Data-Engineer-Professional Braindumps Files
- Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Useful Valid Exam Pdf 🐖 Search on ( www.pdfvce.com ) for 「 Certified-Data-Engineer-Professional 」 to obtain exam materials for free download 🤮Reliable Certified-Data-Engineer-Professional Real Exam
- Valid free Certified-Data-Engineer-Professional exam dumps collection - Databricks Certified-Data-Engineer-Professional exam tests 🍻 Easily obtain free download of ➤ Certified-Data-Engineer-Professional ⮘ by searching on ( www.testkingpass.com ) 💌Certified-Data-Engineer-Professional Downloadable PDF
- Certified-Data-Engineer-Professional Boot Camp 🗓 Free Certified-Data-Engineer-Professional Learning Cram ✍ Certified-Data-Engineer-Professional Reliable Exam Blueprint 🏐 Open website ( www.pdfvce.com ) and search for ⮆ Certified-Data-Engineer-Professional ⮄ for free download 🦀Free Certified-Data-Engineer-Professional Learning Cram
- Certified-Data-Engineer-Professional Test Discount Voucher 📂 Certified-Data-Engineer-Professional Exam Prep 👈 Free Certified-Data-Engineer-Professional Learning Cram 🎌 Copy URL [ www.prepawaypdf.com ] open and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download for free 🔯Certified-Data-Engineer-Professional Test Dumps
- First-grade Certified-Data-Engineer-Professional Valid Exam Pdf – Find Shortcut to Pass Certified-Data-Engineer-Professional Exam 🐣 Search for 《 Certified-Data-Engineer-Professional 》 on ⏩ www.pdfvce.com ⏪ immediately to obtain a free download 😁Certified-Data-Engineer-Professional Dump Collection
- Valid Certified-Data-Engineer-Professional Test Sample ⏮ Certified-Data-Engineer-Professional Reliable Exam Blueprint 🟡 Test Certified-Data-Engineer-Professional Duration ☑ Copy URL ➽ www.easy4engine.com 🢪 open and search for ▶ Certified-Data-Engineer-Professional ◀ to download for free ⭕Certified-Data-Engineer-Professional Test Dumps
- 2026 100% Free Certified-Data-Engineer-Professional –Reliable 100% Free Valid Exam Pdf | Valid Certified-Data-Engineer-Professional Test Discount 🏞 Search for ➠ Certified-Data-Engineer-Professional 🠰 and download it for free on ▛ www.pdfvce.com ▟ website 🍸Certified-Data-Engineer-Professional Exam Prep
- Databricks Certified-Data-Engineer-Professional Exam Questions Preparation Material By www.pdfdumps.com 😜 Open ▷ www.pdfdumps.com ◁ and search for { Certified-Data-Engineer-Professional } to download exam materials for free 🍬New Certified-Data-Engineer-Professional Braindumps Files
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, semasocial.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes