As a market leader, our company is able to attract quality staffs, it actively seeks out those who are energetic, persistent, and professional to various DP-750 certificate and good communicator. And we strongly believe that the key of our company's success is its people, skills, knowledge and experience. Over 50% of the account executives and directors have been with the Group for more than ten years. The successful selection, development and DP-750 training of personnel are critical to our company's ability to provide a high pass rate of DP-750 exam questions for you to pass the DP-750 exam.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
>> DP-750 Exam Questions Pdf <<
We always aim at improving our users’ experiences. You can download the PDF version demo before you buy our DP-750 test guide, and briefly have a look at the content and understand the DP-750 exam meanwhile. After you know about our DP-750 actual questions, you can decide to buy it or not. The process is quiet simple, all you need to do is visit our website and download the free demo. That would save lots of your time, and you’ll be more likely to satisfy with our DP-750 Test Guide.
NEW QUESTION # 70
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a Lakeflow Connect pipeline and connect it to DB1.
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
NEW QUESTION # 71
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.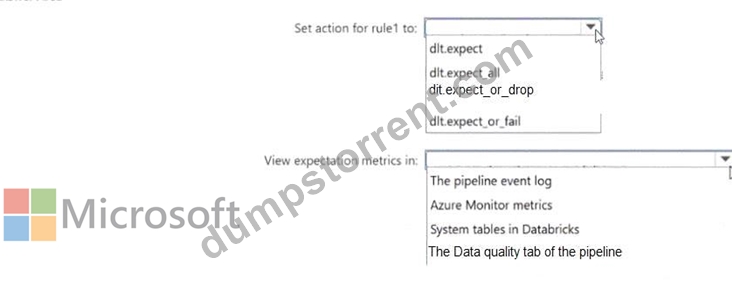
Answer:
Explanation: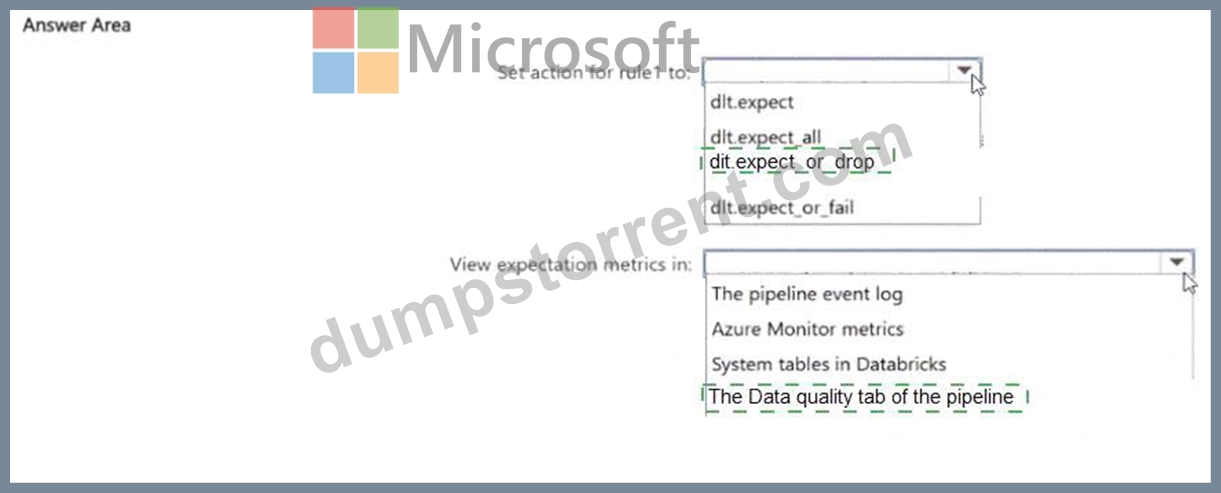
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 72
Which feature provides end-to-end tracking of data movement in Databricks?
Answer: A
Explanation:
Unity Catalog provides data lineage tracking across ingestion, transformation, and consumption layers. It helps visualize dependencies and compliance auditing. Spark logs are low-level and not structured for lineage. Query history is partial only.
NEW QUESTION # 73
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table! is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table!
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: D
Explanation:
The correct answer is C - Enable schema evolution.
When new columns are added to the source data, a pipeline without schema evolution treats the unexpected columns as a schema mismatch and fails the write. Schema evolution, when enabled in an SDP pipeline, automatically adds those new columns to the target Delta table on the next pipeline run. The pipeline continues without intervention, and no historical data is lost.
Option A (disable schema enforcement) is the wrong lever - it removes all schema validation, which could allow corrupt or mistyped data into Table1. Schema evolution is a targeted, safer response.
Option B (row filters to exclude records with new columns) would silently discard valid records just because they carry extra fields - that's data loss. Option D (separate table per schema version) creates an explosion of tables as schemas evolve and makes downstream analytics significantly more complex. Schema evolution is the clean, built-in solution.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/schema-evolution
NEW QUESTION # 74
You have an Azure Databricks workspace and a remote Git repository named Repo1. Repo1 contains two branches named main and Branch1.
You are on a development team that works in Repo1.
You commit changes to Branch1 and must merge the changes into main.
Before completing the merge, you need to meet the following requirements:
* Ensure that Branch1 includes the changes committed to main since Branch1 was created.
* Ensure that merge conflicts are detected and resolved.
What should you do first?
Answer: A
Explanation:
The latest remote changes from main must first be retrieved so that the development environment has the current main-branch state. After pulling those updates, main can be merged into Branch1, and any conflicts can be detected and resolved before Branch1 is proposed for integration into main. Immediately merging a stale local copy of main into Branch1 could omit commits added remotely after Branch1 was created. Pulling Branch1 only synchronizes the feature branch and does not retrieve the required main-branch changes.
Creating a pull request before updating and testing Branch1 would defer conflict discovery until later in the integration process. Pulling the latest main changes is therefore the correct first operation in the sequence.
Microsoft Learn
NEW QUESTION # 75
......
We would like to provide our customers with different kinds of DP-750 practice guide to learn, and help them accumulate knowledge and enhance their ability. Besides, we guarantee that the DP-750 exam questions of all our users can be answered by professional personal in the shortest time with our DP-750 Study Dumps. One more to mention, we can help you make full use of your sporadic time to absorb knowledge and information.
Exam DP-750 Voucher: https://www.dumpstorrent.com/DP-750-exam-dumps-torrent.html