P.S. Kostenlose und neue SPS-C01 Prüfungsfragen sind auf Google Drive freigegeben von ZertSoft verfügbar: https://drive.google.com/open?id=12i193qFW2TWktVcV9f4APGE9U9S4uk2d
Wenn Sie die ZertSoft Website klicken, wundern Sie sich vielleicht, dass viele Leute jedentag ZertSoft besuchen. Das ist ganz normal. Wir bieten den Kandidaten zahlreiche Schulungsunterlagen, mit denen sie die Snowflake SPS-C01 Prüfung bestehen können. Das heißt, dass die Schulungsunterlagen wirklich wirksam sind. Wenn Sie die Snowflake SPS-C01 Fragenkatalog kaufen wollen, verpassen Sie ZertSoft nicht. Und Sie werden sicher mit unseren Produkten zufrieden.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and DataFrame Operations | 35% | - Filtering, Aggregating, and Joining DataFrames - Using built-in functions - Complex data pipelines - Persisting transformed data - Window functions |
| Performance Optimization and Best Practices | 20% | - Vectorized UDFs - Warehouse sizing for Snowpark - Minimizing data transfer - Query pushdown and optimization - Debugging and explain plans - Caching strategies |
| Snowpark API for Python | 30% | - User-Defined Functions (UDFs) and Stored Procedures - DataFrame creation and manipulation - Working with Semi-structured data - Establishing connections and session management - Reading and writing data |
| Snowpark Concepts | 15% | - Client-side vs. Server-side execution - Snowpark architecture and core concepts - Snowpark DataFrames and query plans - Transformations vs. Actions - Snowpark Sessions and connection management - Stored procedures and conditional logic |
Jedem, der die Prüfungsunterlagen und Software zu Snowflake SPS-C01 (Snowflake Certified SnowPro Specialty - Snowpark) von ZertSoft nutzt und die Snowflake Zertifizierungsprüfungen nicht beim ersten Mal erfolgreich besteht, versprechen wir, die Kosten für das Prüfungsmaterial 100% zu erstatten.
342. Frage
You are developing a Snowpark stored procedure to process PDF files stored in a Snowflake stage. You need to extract text from these PDF files and store the extracted text in a Snowflake table. Due to security requirements, you cannot use any external packages that require internet access. Which of the following approaches can you use to accomplish this task securely and efficiently? (Select all that apply)
Antwort: C,D
Begründung:
Options B and C are correct. Option B: Java UDFs allow you to leverage existing Java libraries (like PDFBox, which can be included in the UDF's JAR file) to parse PDFs securely within the Snowflake environment. Option C: Using and a pure-Python PDF parsing library (which doesn't require external network access) is another viable approach. The entire library's code must be embedded within the stored procedure. Option A is incorrect because Snowflake does not have built-in PDF parsing functions. Option D is not ideal as you are trying to avoid any external dependencies and internet access. Option E, although workable, adds an external preprocessing step which isn't the most efficient way.
343. Frage
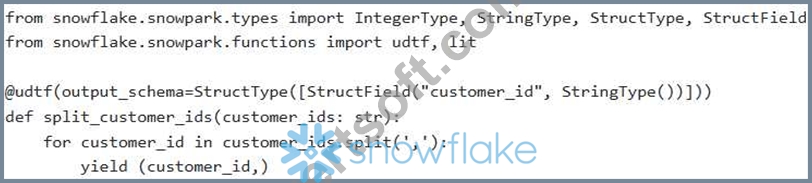
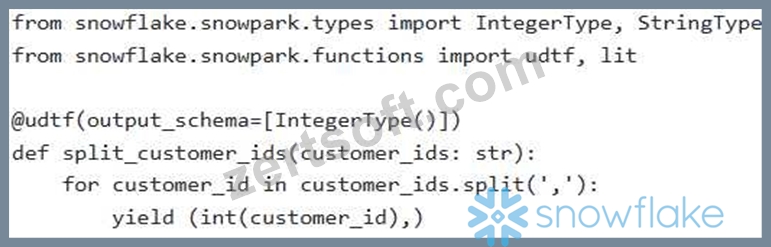
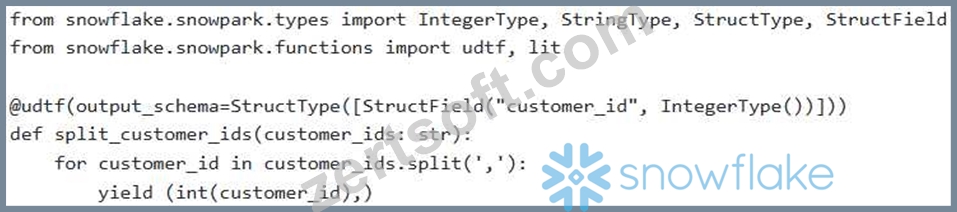
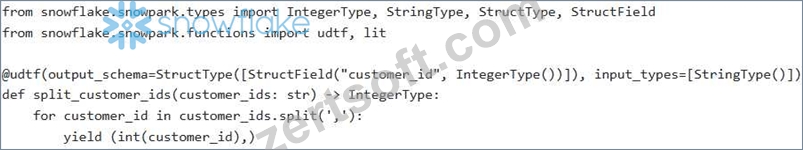
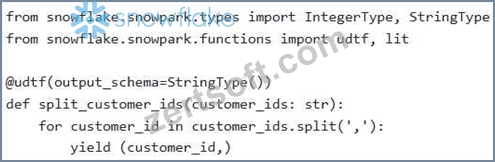
You are tasked with creating a UDTF using Snowpark Python that splits a comma-separated string of customer IDs into individual rows. The input is a string (VARCHAR) and the output should be a table with a single column named 'customer_id' of type INTEGER. Which of the following code snippets CORRECTLY defines and registers the UDTF, ensuring proper data type handling? Assume is a valid Snowpark Session object.
Antwort: C
Begründung:
Option B correctly defines the UDTF. It uses 'StructType' and to define the output schema with a column named 'customer_id' of type "Integer Type'. The code also correctly converts the customer ID to an integer before yielding it. Option A defines the output schema as 'StringType' , which is incorrect. Option C does not correctly define a column name. Option D uses 'StringType' for the column, which violates the requirements. Option E adds and a return annotation which are valid, but the structure of the annotation is still not correct for a UDTF.
344. Frage
Consider the following Snowpark Python code snippet designed to perform a join operation between two large tables: 'transactions' and 'customers'. The 'transactions' table contains billions of rows and the 'customers' table contains millions of rows. You are experiencing performance bottlenecks during the join operation. The 'transactions' table has a 'customer id' column that references the 'customers' table's primary key 'id'. Which optimization techniques would be MOST effective in improving the join performance within a Snowpark- optimized warehouse?
Antwort: E
Begründung:
Broadcasting the smaller table (customers) to all nodes allows for a more efficient join by avoiding the need to shuffle large amounts of data. Snowflake automatically handles index management and optimization; explicitly defining indexes is not necessary. While repartitioning can sometimes improve join performance, in this scenario broadcasting the smaller table is generally more effective. Increasing the warehouse size might help, but it's less targeted than broadcasting. 'how='broadcastr is not a valid parameter in Snowpark's 'join()' function.
345. Frage
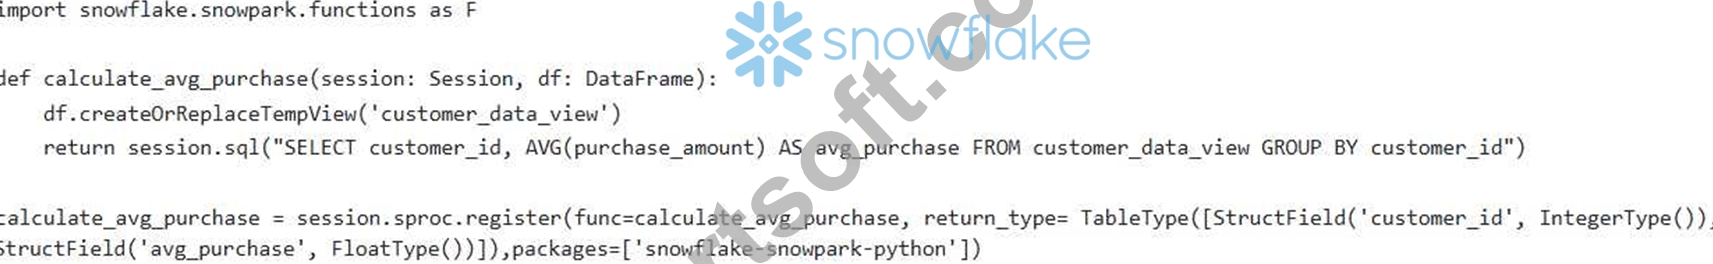
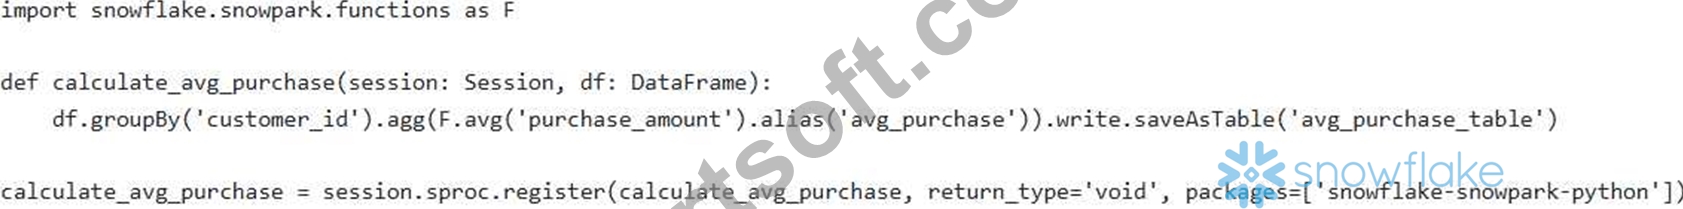
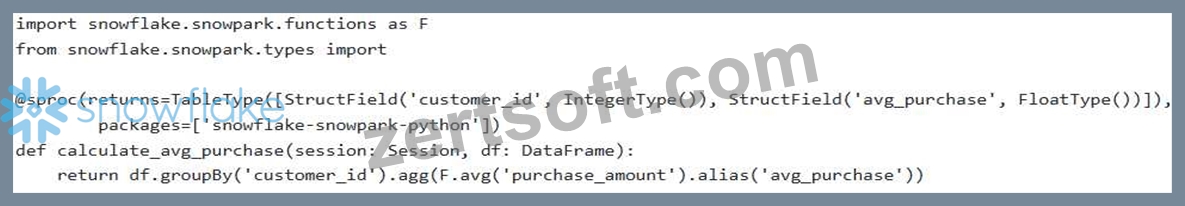
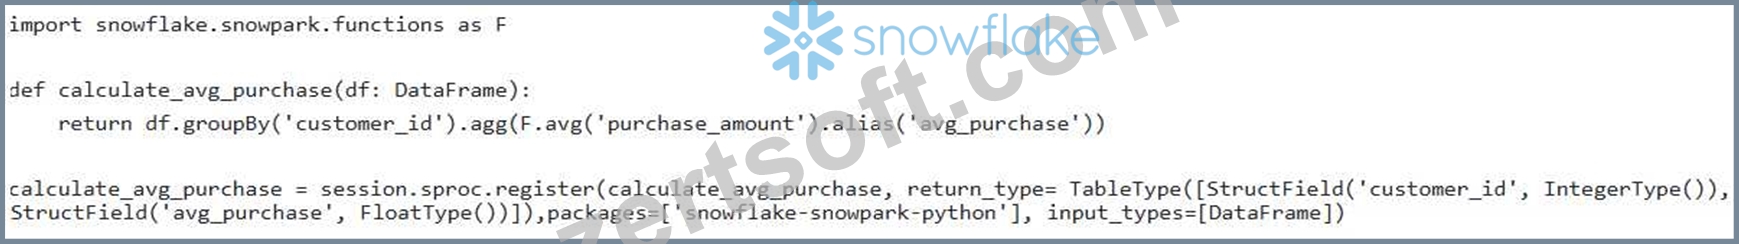
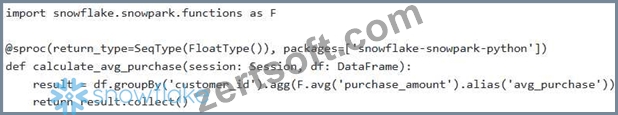
You have a Snowpark DataFrame named and want to create a stored procedure that calculates the average purchase amount for each customer. The stored procedure should accept the DataFrame as input, perform the aggregation, and return a new DataFrame with the results. Which of the following code snippets BEST demonstrates how to correctly define and deploy this stored procedure?
Antwort: D
Begründung:
Option E is the most correct. It correctly registers the stored procedure using 'session.sproc.register' with the correct return type annotation for a DataFrame (using TableType and StructFields) and explicitly declares the input type to be DataFrame using 'input_types' parameter in registration. Option A uses the '@sproc' decorator which is the older API (still valid, but less explicit). Option B uses session.sql which is not appropriate for creating DataFrame based stored procedures. Option C is not correct because the return type SeqType(FloatType()) expects a sequence of float types instead of a DataFrame structure. Option D writes the result to a table, which is not the defined requirement to return a DataFrame.
346. Frage
You are working with a Snowpark DataFrame that contains product information including 'product_name' and 'description'. You need to create a new column named 'search_terms' that contains the first three words from the 'description' column, converted to lowercase. If the description has fewer than three words, the 'search_terms' column should contain all the words available. The words should be separated by a space. What is the MOST efficient way to achieve this using Snowpark?





Antwort: A
Begründung:
Using a UDF (Option C) is a valid approach, but generally less efficient than leveraging built-in functions or existing Snowflake functions, especially for large datasets, because it involves serialization and deserialization between Python and Snowflake. Option A is not dynamic and will error on strings with fewer than three words. Option D will only correctly return the words if there are exactly three, otherwise it won 't match. E will just return the lowercased string and Snowflake UDF defined in SQL. Snowflake UDFs overhead, and are preferable for performance It is also less efficient than a UDF/Stored proc as it involves calling the Regex. Option is incorrect. Option B (UDF) is the most efficient, assuming GET FIRST THREE_WORDS is a are optimized for execution within the Snowflake environment, minimizing data transfer compared to Python UDFs in Snowpark.
347. Frage
......
Ea ist Traum der Angestellten, sich in der IT-Branche engagieren zu können, die Snowflake SPS-C01 Zertifizierungsprüfung zu bestehen. Wenn Sie Ihren Traum verwirklichen wollen, brauchen Sie nur fachliche Ausbildung zu wählen. ZertSoft ist eine fachliche Website, die Schulungsunterlagen zur Snowflake SPS-C01 Zertifizierung bietet. Wählen Sie ZertSoft. Und wir versprechen, dass Sie den Erfolg erlangen und Ihren Traum verwirklichen , egal welches hohes Ziel Sie anstreben, können.
SPS-C01 Testfagen: https://www.zertsoft.com/SPS-C01-pruefungsfragen.html
P.S. Kostenlose und neue SPS-C01 Prüfungsfragen sind auf Google Drive freigegeben von ZertSoft verfügbar: https://drive.google.com/open?id=12i193qFW2TWktVcV9f4APGE9U9S4uk2d