順便提一下,可以從雲存儲中下載Testpdf Professional-Machine-Learning-Engineer考試題庫的完整版:https://drive.google.com/open?id=1kiZdLIPUHF_mKlWLuCrb1grQlRpxHHhx
在談到Professional-Machine-Learning-Engineer考試認證,很難忽視的是可靠性,Testpdf的Professional-Machine-Learning-Engineer考試培訓資料是特別設計,以最大限度的提高你的工作效率,本站在全球範圍內執行這項考試通過率最大化。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Scale prototypes into AI models | 18% | - Design and run experiments - Optimize model performance and generalization - Work with foundation models and generative AI techniques - Select appropriate model architectures and frameworks |
| Topic 2: Collaborate to manage data and models | 16% | - Organize and prepare enterprise data
- Address data privacy, compliance, and governance |
| Topic 3: Architect low-code AI solutions | 12% | - Identify use cases for low-code/no-code AI tools - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder - Apply responsible AI principles to low-code designs |
| Topic 4: Train and deploy models | 20% | - Configure training jobs and environments - Implement generative AI deployment patterns - Deploy models for online, batch, and streaming prediction - Use Vertex AI deployment features and infrastructure |
| Topic 5: Automate and orchestrate ML pipelines | 18% | - Use Vertex AI Pipelines, TFX, and other orchestration tools - Design end-to-end ML workflows - Automate retraining and model updates - Implement CI/CD for ML systems |
| Topic 6: Monitor and optimize AI solutions | 16% | - Monitor data quality and pipeline health - Optimize cost, latency, and resource usage - Monitor model performance, fairness, and drift - Troubleshoot and maintain production systems |
>> 免費下載Professional-Machine-Learning-Engineer考題 <<
現在許多公司正要求員工接受減薪,然而雇員可能抱怨幾年前增加的不足百分之四或五的薪水,持有當前的 IT 認證不能保證您不面對減薪。但擁有特別的認證包括 GAQM、EMC、ISC證書,就會使員工具有獲得被付高薪的資格。而 Testpdf 為你提供的 Google Professional-Machine-Learning-Engineer 練習題和答案能使你順利通過考試。Google Professional-Machine-Learning-Engineer 考古題是考試之前的模擬考試時很有必要的,也是很有效的。如果你選擇了它,你可以100%通過 Professional-Machine-Learning-Engineer 考試。
問題 #42
You recently trained an XGBoost model on tabular data. You plan to expose the model for internal use as an HTTP microservice. After deployment, you expect a small number of incoming requests. You want to productionize the model with the least amount of effort and latency. What should you do?
答案:A
問題 #43
You are training a Resnet model on Al Platform using TPUs to visually categorize types of defects in automobile engines. You capture the training profile using the Cloud TPU profiler plugin and observe that it is highly input-bound. You want to reduce the bottleneck and speed up your model training process. Which modifications should you make to the tf .data dataset?
Choose 2 answers
答案:B,E
解題說明:
The tf.data dataset is a TensorFlow API that provides a way to create and manipulate data pipelines for machine learning. The tf.data dataset allows you to apply various transformations to the data, such as reading, shuffling, batching, prefetching, and interleaving. These transformations can affect the performance and efficiency of the model training process1 One of the common performance issues in model training is input-bound, which means that the model is waiting for the input data to be ready and is not fully utilizing the computational resources. Input-bound can be caused by slow data loading, insufficient parallelism, or large data size. Input-bound can be detected by using the Cloud TPU profiler plugin, which is a tool that helps you analyze the performance of your model on Cloud TPUs. The Cloud TPU profiler plugin can show you the percentage of time that the TPU cores are idle, which indicates input-bound2 To reduce the input-bound bottleneck and speed up the model training process, you can make some modifications to the tf.data dataset. Two of the modifications that can help are:
* Use the interleave option for reading data. The interleave option allows you to read data from multiple files in parallel and interleave their records. This can improve the data loading speed and reduce the idle time of the TPU cores. The interleave option can be applied by using the tf.data.Dataset.interleave method, which takes a function that returns a dataset for each input element, and a number of parallel calls3
* Set the prefetch option equal to the training batch size. The prefetch option allows you to prefetch the next batch of data while the current batch is being processed by the model. This can reduce the latency
* between batches and improve the throughput of the model training. The prefetch option can be applied by using the tf.data.Dataset.prefetch method, which takes a buffer size argument. The buffer size should be equal to the training batch size, which is the number of examples per batch4 The other options are not effective or counterproductive. Reducing the value of the repeat parameter will reduce the number of epochs, which is the number of times the model sees the entire dataset. This can affect the model's accuracy and convergence. Increasing the buffer size for the shuffle option will increase the randomness of the data, but also increase the memory usage and the data loading time. Decreasing the batch size argument in your transformation will reduce the number of examples per batch, which can affect the model's stability and performance.
References: 1: tf.data: Build TensorFlow input pipelines 2: Cloud TPU Tools in TensorBoard 3: tf.data.Dataset.interleave 4: tf.data.Dataset.prefetch : [Better performance with the tf.data API]
問題 #44
You need to use TensorFlow to train an image classification model. Your dataset is located in a Cloud Storage directory and contains millions of labeled images Before training the model, you need to prepare the dat a. You want the data preprocessing and model training workflow to be as efficient scalable, and low maintenance as possible. What should you do?
答案:C
解題說明:
TFRecord is a binary file format that stores your data as a sequence of binary strings1. TFRecord files are efficient, scalable, and easy to process1. Sharding is a technique that splits a large file into smaller files, which can improve parallelism and performance2. Dataflow is a service that allows you to create and run data processing pipelines on Google Cloud3. Dataflow can create sharded TFRecord files from your images in a Cloud Storage directory4.
tf.data.TFRecordDataset is a class that allows you to read and parse TFRecord files in TensorFlow. You can use this class to create a tf.data.Dataset object that represents your input data for training. tf.data.Dataset is a high-level API that provides various methods to transform, batch, shuffle, and prefetch your data.
Vertex AI Training is a service that allows you to train your custom models on Google Cloud using various hardware accelerators, such as GPUs. Vertex AI Training supports TensorFlow models and can read data from Cloud Storage. You can use Vertex AI Training to train your image classification model by using a V100 GPU, which is a powerful and fast GPU for deep learning.
Reference:
TFRecord and tf.Example | TensorFlow Core
Sharding | TensorFlow Core
Dataflow | Google Cloud
Creating sharded TFRecord files | Google Cloud
[tf.data.TFRecordDataset | TensorFlow Core v2.6.0]
[tf.data: Build TensorFlow input pipelines | TensorFlow Core]
[Vertex AI Training | Google Cloud]
[NVIDIA Tesla V100 GPU | NVIDIA]
問題 #45
You are building a model to predict daily temperatures. You split the data randomly and then transformed the training and test datasets. Temperature data for model training is uploaded hourly. During testing, your model performed with 97% accuracy; however, after deploying to production, the model's accuracy dropped to 66%. How can you make your production model more accurate?
答案:D
解題說明:
If you do time series prediction, you can't borrow information from the future to predict the future.
If you do, you are artificially increasing your accuracy.
問題 #46
You developed a Vertex Al pipeline that trains a classification model on data stored in a large BigQuery table. The pipeline has four steps, where each step is created by a Python function that uses the KubeFlow v2 API The components have the following names: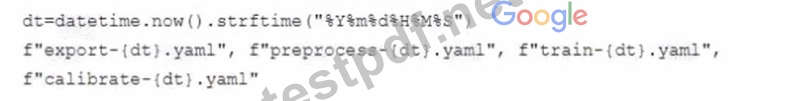
You launch your Vertex Al pipeline as the following: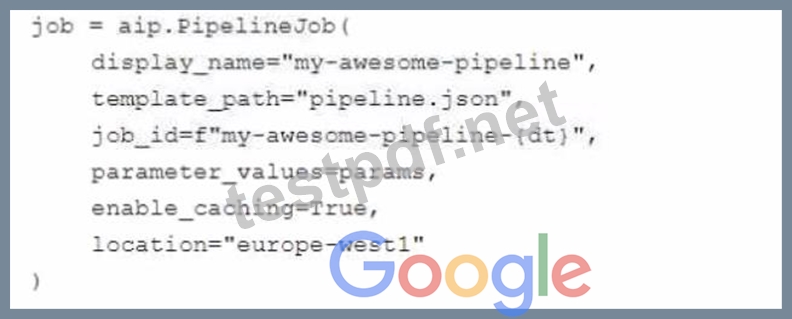
You perform many model iterations by adjusting the code and parameters of the training step. You observe high costs associated with the development, particularly the data export and preprocessing steps. You need to reduce model development costs. What should you do?




答案:B
問題 #47
......
如果你想參加Professional-Machine-Learning-Engineer認證考試,那麼是使用Professional-Machine-Learning-Engineer考試資料是很有必要的。如果你正在漫無目的地到處尋找參考資料,那麼趕快停止吧。如果你不知道應該用什麼資料,那麼試一下Testpdf的Professional-Machine-Learning-Engineer考古題吧。這個考古題的命中率很高,可以保證你一次就取得成功。與別的考試資料相比,這個考古題更能準確地劃出考試試題的範圍。這樣的話,可以讓你提高學習效率,更加充分地準備Professional-Machine-Learning-Engineer考試。
Professional-Machine-Learning-Engineer考題寶典: https://www.testpdf.net/Professional-Machine-Learning-Engineer.html
順便提一下,可以從雲存儲中下載Testpdf Professional-Machine-Learning-Engineer考試題庫的完整版:https://drive.google.com/open?id=1kiZdLIPUHF_mKlWLuCrb1grQlRpxHHhx